Scraping AliExpress collects the price, stock, variants, rating, and reviews that price monitoring and competitor tracking need. Most of it isn’t in the HTML, because the page loads it afterward from a signed internal API.
In my tests, a plain request returned HTTP 200 and no price, so a pipeline would log a success with an empty row. From one IP address, the signed API started to block calls within a dozen requests.
This guide shows you how to get that data, detect a failure that looks like a success, and use Bright Data’s AliExpress Scraper API at scale.
TL;DR
- The
window.runParamsobject that older tutorials parse is empty. Price, stock, and SKU data load frommtop.aliexpress.pdp.pc.query, which needs an MD5 signature. - Detect blocks by markers, not status codes. Blocked requests returned HTTP 200, a
bxpunishheader, and a body marker such asrgv587_flag. - A correct signature didn’t prevent blocks. Two runs of 60 calls from one IP address, with no delay, got data from 7 and 15.
- At scale, scrape the public
/item/product pages. Bright Data’s AliExpress Scraper API extracts structured data, and the Browser API lets your script read each page’s full API response.
What happens when you scrape AliExpress with an HTTP client
Start with one HTTP request, sent without a browser or a proxy. If it times out, your network can’t reach AliExpress directly, and a proxy or one of the managed methods below sends the request from a network that can.
Everything below uses 3 packages. The Scraper API script in a later section reads your Bright Data API key from an environment variable:
pip install curl_cffi playwright requests
export BRIGHTDATA_API_KEY="your-api-key"    # PowerShell: $env:BRIGHTDATA_API_KEY="your-api-key"
Fetch one product page with curl_cffi and read the <title>, the window.runParams object that older tutorials parse, and the bootstrap object that the page passes to its own JavaScript. These 3 values show whether a plain HTTP client is enough:
import re
from curl_cffi import requests as cffi

# any product URL that still exists works
ITEM = "https://www.aliexpress.com/item/1005001398867186.html"

# no User-Agent of your own: curl_cffi sends one that matches the browser it impersonates
r = cffi.get(ITEM, impersonate="chrome", timeout=30)
html = r.text

print("status      ", r.status_code)
print("bytes       ", len(html))
print("title       ", repr(re.search(r"<title>(.*?)</title>", html, re.S).group(1)))
print("runParams   ", repr(re.search(r"window\.runParams\s*=\s*(\{.*?\});", html, re.S).group(1)))
print("isCSR       ", re.search(r"isCSR\s*=\s*(\w+)", html).group(1))
print("crawler flag", re.search(r'"crawler":(\w+)', html).group(1))
The fetch succeeds:
status       200
bytes        77226
title        ''
runParams    '{\n                    }'
isCSR        true
crawler flag false
The page is an HTML shell, with no price, stock, SKU, rating, or reviews. Before any JavaScript runs, the shell already has the Open Graph tags. og:title contains the real product name while <title> is blank, and og:image, og:url, and og:type (set to product) are there too. og:description contains only a generic AliExpress slogan, and the page has no JSON-LD, so neither source gives you product data.
A browser that loads the same URL in the same hour renders the price, rating, and variants:
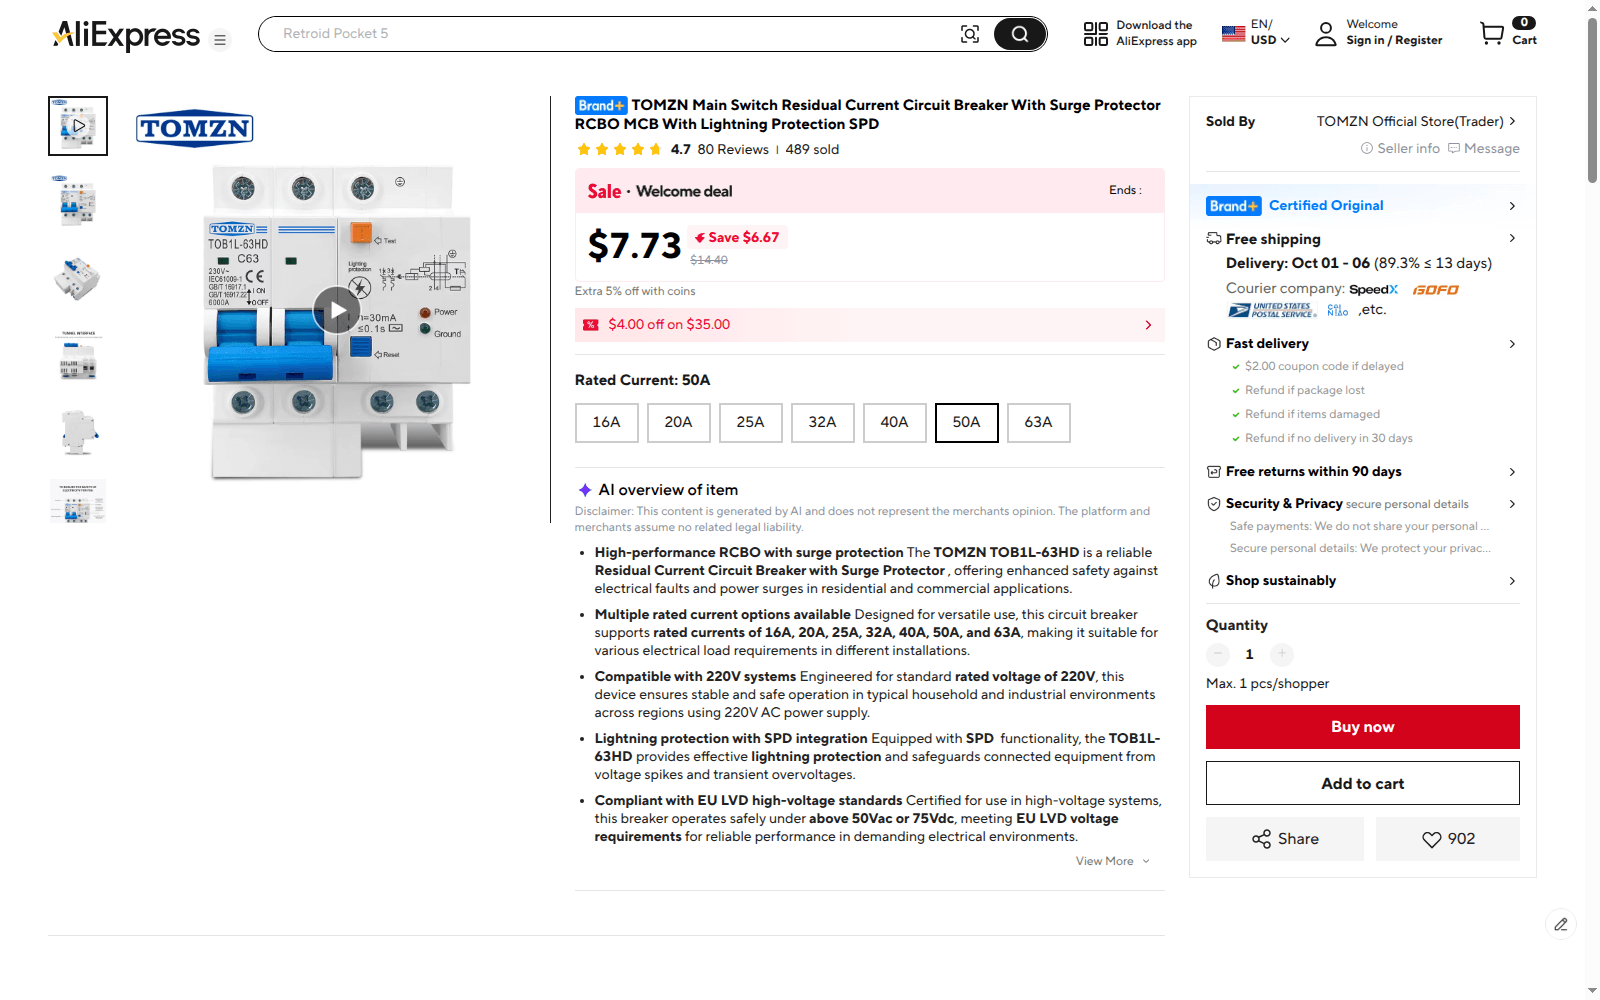
Rendered through Bright Data’s Browser API with geolocation targeting set to the US. AliExpress’s internal API returns the same $14.40 list price and 4.7 rating for this product. The sale price comes from a temporary promotion and changes over time.
Searching the page source for that list price finds nothing:
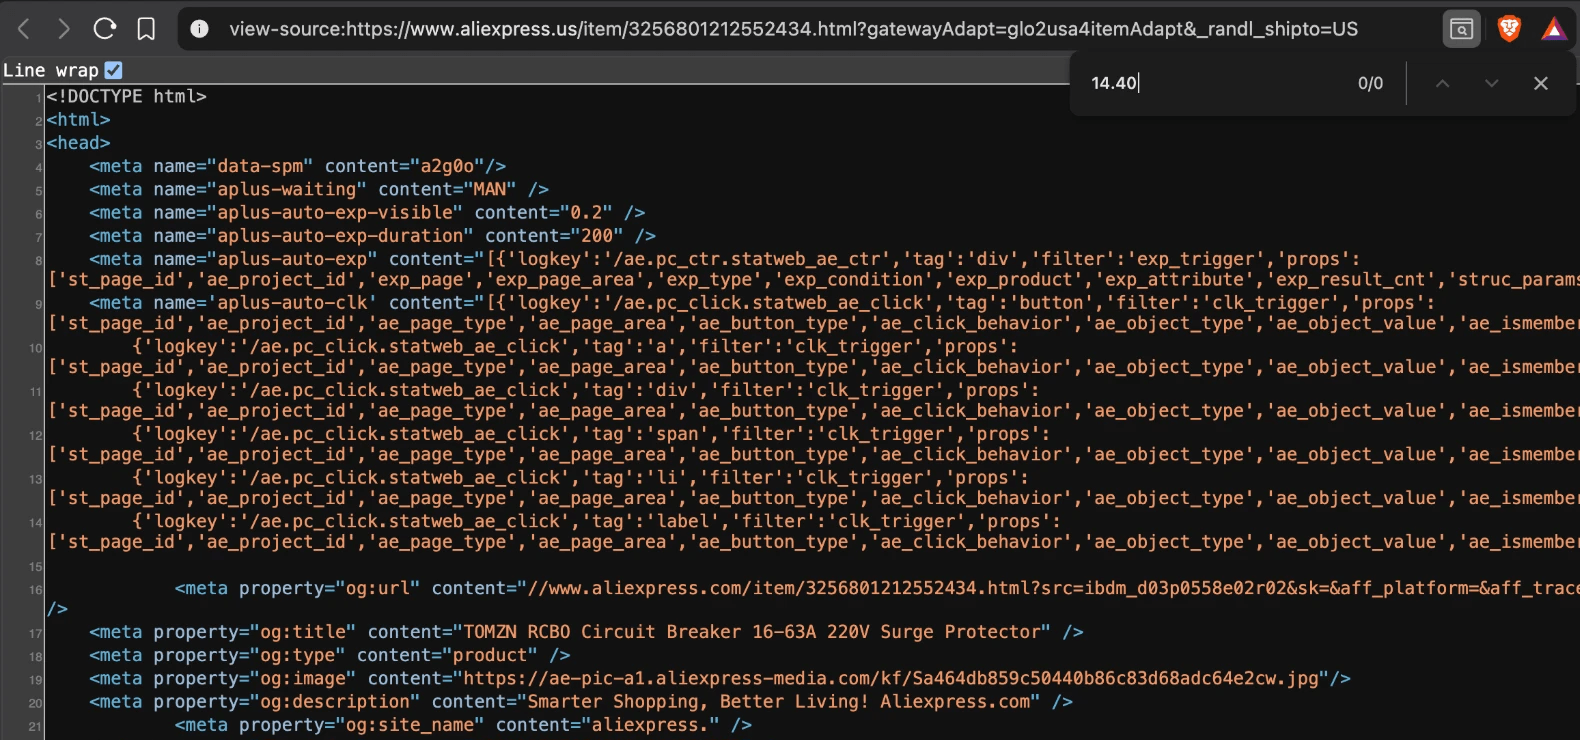
Captured on the US storefront, which serves the same 77 KB shell.
The catalog fields are cheap to collect. A single GET request with no unblocking returns the catalog fields, so you can map product IDs to titles and main images without rendering. Price and assortment pipelines need price, stock, and variant data, which comes from AliExpress’s internal API gateway. Plan those 2 jobs separately.
Let curl_cffi choose the User-Agent. impersonate="chrome" is an alias rather than a version. In the library’s source, curl_cffi 0.16.1 maps the alias to chrome150 through a DEFAULT_CHROME constant, and that constant changes whenever a new profile is released. If you don’t set the header, the library also sends the matching Chrome/150 User-Agent.
If you pass your own User-Agent, it replaces the library’s User-Agent, so a hardcoded Chrome/141 string is sent with a Chrome 150 TLS handshake. The mismatch raises no error, so you can deploy it without noticing. Either omit the header and let the library pair the User-Agent with the handshake, or pin the profile to a version and match the string to it. Engineers who build TLS clients report that a mismatched identity is easier to detect than a consistent one, and that the User-Agent becomes outdated long before the TLS handshake does.
The isCSR flag shows how the page renders. Its value is true because AliExpress moved the product detail page to client-side rendering (CSR). window.runParams is an unused empty object that regex-based extractors still match. A parser that reads it raises no error and returns nothing.
Every client I tried got HTTP 200 and the same 77 KB shell. I sent 20 consecutive requests to that URL from one residential IP address without a proxy, and all of them returned HTTP 200. The requests ran in a single session at one request every 0.4 seconds, with no User-Agent rotation. I also fetched the same URL as python-requests/2.32.5, as curl/8.7.1, and as 3 TLS impersonation profiles.
Sending the Googlebot User-Agent switches "crawler" from false to true in the bootstrap object. The response differs by 1 byte. The flag didn’t add a server-rendered payload, so spoofing Googlebot changes one boolean value and nothing else.
On a client-rendered marketplace, check the data before you log a fetch as a success. The status code only shows that the HTTP request succeeded. On this target, the request succeeded even when the data was missing.
The block that returns HTTP 200
AliExpress does block requests, but the HTTP status line doesn’t show the block.
The site’s own robots.txt names an internal endpoint in a Googlebot-specific rule, and that endpoint may return the product data. Call it directly and read the response headers before the body:
from curl_cffi import requests as cffi

PID = "1005001398867186"
url = f"https://www.aliexpress.com/aeglodetailweb/api/msite/item?productId={PID}"
r = cffi.get(url, impersonate="chrome", timeout=30,
             headers={"Accept": "application/json",
                      "Referer": f"https://www.aliexpress.com/item/{PID}.html"})

print("status", r.status_code, "bytes", len(r.text))
for k in ("server", "x-rule-name", "bxpunish", "set-cookie"):
    print(f"  {k:12s} {str(r.headers.get(k))[:70]}")
print("body marker:", "rgv587_flag" in r.text, "| x5secdata:", "x5secdata" in r.text)
The response comes from Alibaba’s Baxia anti-bot system, and it has a success status code:
status 200 bytes 2399
  server       Tengine/AServer-Ingress
  x-rule-name  AE_GLOBAL_UNLOGIN
  bxpunish     1
  set-cookie   x5secdata=xffEdBbOh5ArPGTjyI_40B3_06C7jiK2nBFPGlpVzkk2x66w14DH6V
body marker: True | x5secdata: True
The body is a script that redirects to a _____tmd_____/punish URL through window.location and sets window._config_ = {"action":"captcha", ...}. It ends with <!--rgv587_flag:sm-->, Alibaba’s block marker. The x-rule-name header names the rule that matched, AE_GLOBAL_UNLOGIN, which appears to be the rule for unauthenticated global traffic. The same header also came back on normal, unblocked responses, so it doesn’t mark a block on its own.
Status-code checks accept this blocked response. raise_for_status() doesn’t raise, and a status_code == 200 check returns true. If a dashboard counts HTTP 2xx responses as successes, it reports a healthy pipeline while the rows are empty.
So detect blocks by the response headers and body, not by the status code. Alibaba’s error strings can change without notice, but a dedicated response header and a marker string in the body are cheap to check and cheap to extend:
BLOCK_MARKERS = ("rgv587_flag", "x5secdata", "_____tmd_____", "FAIL_SYS_USER_VALIDATE")

def is_blocked(resp, min_bytes=1024):
    """True when Baxia responded instead of the application."""
    if resp.headers.get("bxpunish"):
        return True
    body = resp.text
    if len(body) < min_bytes:          # treat a near-empty 200 as a block too
        return True
    return any(m in body[:4096] for m in BLOCK_MARKERS)
In my runs, those checks detected every block that the status code didn’t show. Run the same checks before your parser, and add them before you write any selectors. Without them, you learn about a block on this target only when your parser finds no data.
Log the reason for each failed request. On this target, a block page, an empty shell, and a price in the wrong currency each need a different fix, and one overall success rate hides all 3. Split the reasons by exit country too, because a wrong-currency price still looks like a success.
Signing product API calls yourself
The product fields do exist as JSON. If you load one page in a browser and record its XHR traffic, you can see that those fields come from an API gateway the page calls.
A page load makes calls to Alibaba’s MTOP gateway at acs.aliexpress.com/h5/<api>/<version>/, each with jsv, appKey, a millisecond timestamp t, and a 32-character sign. mtop.aliexpress.pdp.pc.query returns price, stock, SKU, store, and rating. Review text comes from a second signed call, mtop.aliexpress.review.pc.list, on the same gateway, so collecting reviews needs a second request per product. Reading the inline bootstrap script shows that the page can call more than one product API:
Page variant (viewName) |
Prefetched API |
|---|---|
newDetail |
mtop.aliexpress.pdp.pc.query |
choiceDetail |
mtop.aliexpress.itemdetail.pc.asyncPCDetail |
h5Detail |
mtop.aliexpress.itemdetail.msite |
All 6 product pages I sampled had viewName = 'newDetail'. The other 2 APIs, the mobile mtop.aliexpress.itemdetail.msite and mtop.aliexpress.itemdetail.pc.asyncPCDetail, weren’t easier to access. Both returned FAIL_SYS_USER_VALIDATE with bxpunish: 1 on the first request, sent with the same payload the desktop API accepts.
Read viewName on each fetch to see when a listing starts rendering as a different page variant. A scraper hardcoded to one API name would miss that change. The page’s bootstrap script sets a 15,000 ms prefetch timeout and aborts its own XHR at 10,000 ms, so use 10,000 ms as the upper bound for your own timeouts.
In the browser’s Network panel, filtered to pdp.pc.query, the page’s own request contains every value your signing code needs:
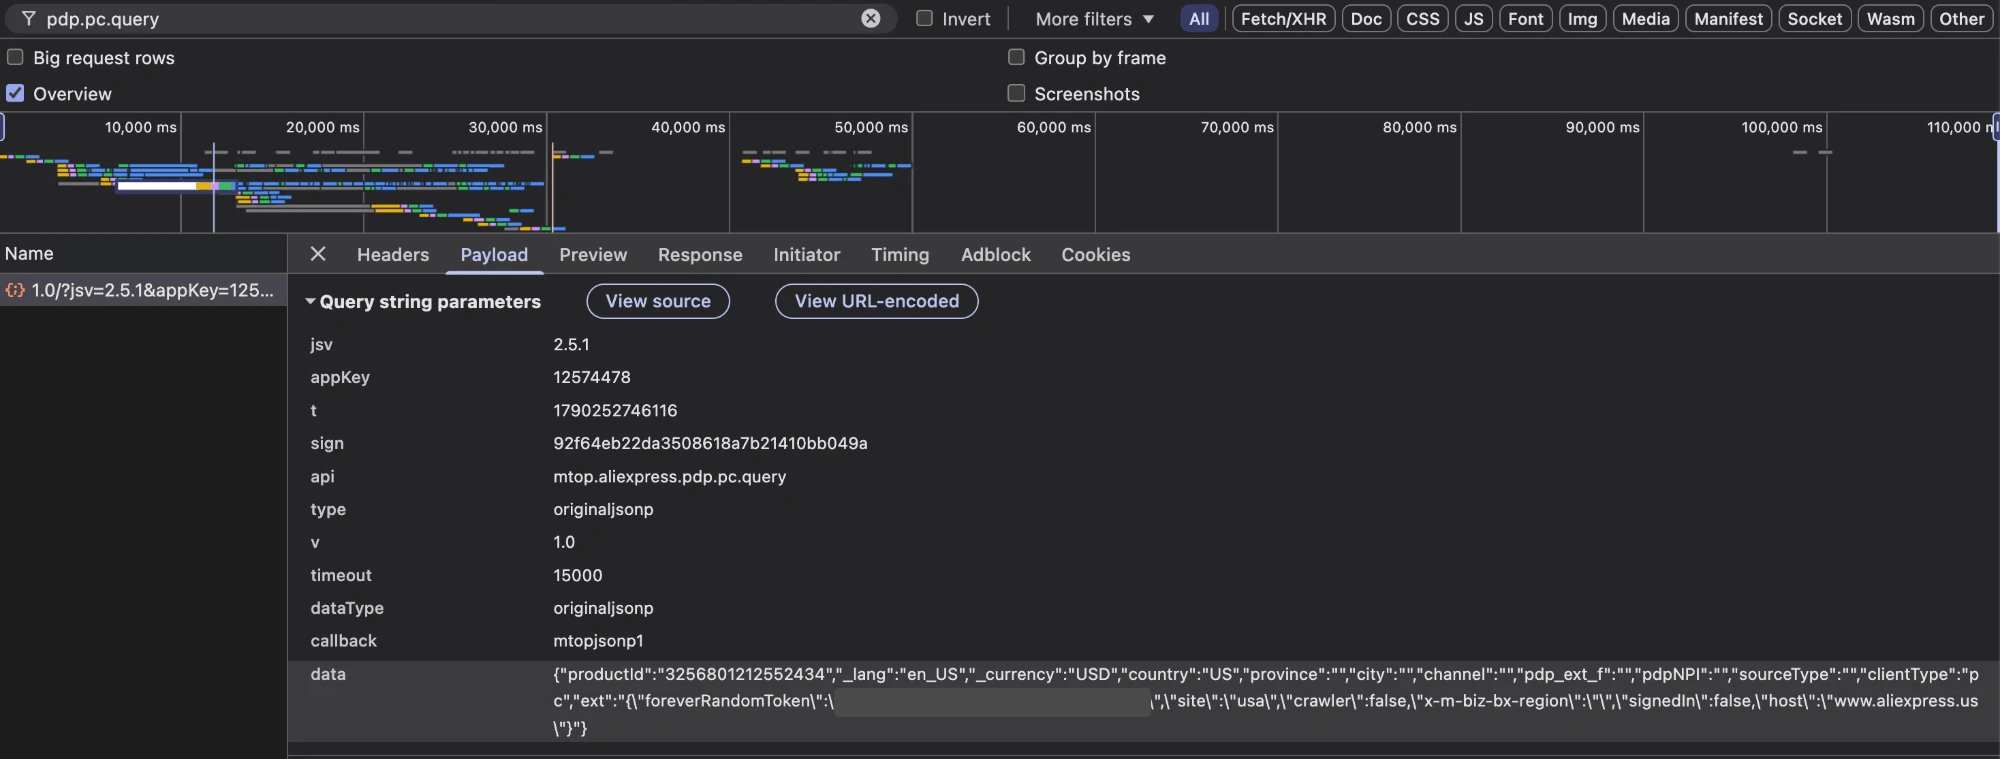
The page’s own call, captured on the US storefront, where this listing’s ID is 3256801212552434. The page sends originaljsonp and adds a timeout and an ext block. The signing code below sends jsonp and omits both, and the gateway accepted that shorter request. One token value is redacted.
The sign value uses the Alibaba H5 signing scheme, which is short enough to reimplement in one function. The scheme joins the session token, the timestamp, the app key, and the exact request body with ampersands, and then hashes the result with MD5:
import hashlib, json, time
from curl_cffi import requests as cffi

APP_KEY, API, VER = "12574478", "mtop.aliexpress.pdp.pc.query", "1.0"
GATEWAY = f"https://acs.aliexpress.com/h5/{API}/{VER}/"

def sign(token, t, data):
    return hashlib.md5(f"{token}&{t}&{APP_KEY}&{data}".encode()).hexdigest()

def pdp(session, product_id, token=""):
    data = json.dumps({"productId": product_id, "_lang": "en_US", "_currency": "USD",
                       "country": "US", "province": "", "city": "", "channel": "",
                       "pdp_ext_f": "{}", "sourceType": "", "clientType": "pc"},
                      separators=(",", ":"))
    t = str(int(time.time() * 1000))
    params = {"jsv": "2.5.1", "appKey": APP_KEY, "t": t, "sign": sign(token, t, data),
              "api": API, "v": VER, "type": "jsonp", "dataType": "jsonp",
              "callback": "mtopjsonp1", "data": data}
    return session.get(GATEWAY, params=params, impersonate="chrome", timeout=30,
                       headers={"Referer": "https://www.aliexpress.com/"})

s = cffi.Session()
first = pdp(s, "1005001398867186")                       # unsigned, returns the token cookie
token = s.cookies.get("_m_h5_tk", "").split("_")[0]
second = pdp(s, "1005001398867186", token)               # signed with that token
print("call 1:", len(first.text), "bytes |", first.text[:60])
print("call 2:", len(second.text), "bytes")
The first call returns the token, and the second call returns the product:
call 1: 151 bytes | mtopjsonp1({"api":"mtop.aliexpress.pdp.pc.query","data":{},"ret
call 2: 103748 bytes
Call 1 returns FAIL_SYS_TOKEN_EMPTY and a Set-Cookie header with _m_h5_tk. Call 2 is signed with the first part of that cookie’s value and returns JSONP, a function call wrapped around one JSON object. If you remove the mtopjsonp1(...) wrapper, you get the full product record, including the title, originalPrice $14.40, salePriceString $6.84, 59,924 units of inventory, rating 4.7, seller ID 200422816, and categoryPath 13/5/141914.
You need only a small part of that payload. The response has 27 top-level modules, and 8 of them contain the fields a price or assortment pipeline would store. Serialized as compact JSON, those 8 modules are 16,494 bytes, which is 15.9% of the whole result object. The largest module is SHIPPING at 34,071 bytes, and the second largest is GLOBAL_DATA at 23,783 bytes.
Signing needs one MD5 hash, one cookie, and one retry. If you’ve reimplemented the H5 signing scheme for another Alibaba site, expect a few hours of work. So how long does your signing code keep working?
How many signed API calls succeed from one IP address
Running the signed call in a loop answers that question quickly. The test uses 10 product IDs, one token, one residential IP address, and no delay between calls. The script counts each ret code the gateway returns:
# continues the session from the signing code: pdp(), s and token are defined there
from collections import Counter
import re

# ten product IDs, replace any that were removed
IDS = ["3256812884305776", "1005007712136541", "1005002754717958", "1005002495501001",
       "2255799968025159", "1005008121783683", "3256809736486496", "1005008175462016",
       "1005012238762416", "3256812840307416"]

outcomes, first_fail = Counter(), None
for i in range(1, 61):
    r = pdp(s, IDS[i % len(IDS)], token)
    ret = re.search(r'"ret":\["([^"]+)"', r.text).group(1).split("::")[0]
    key = ret + (" +bxpunish" if r.headers.get("bxpunish") else "")
    outcomes[key] += 1
    if key != "SUCCESS" and first_fail is None:
        first_fail = i
print(dict(outcomes), "| first non-SUCCESS at", first_fail)
The loop stopped getting data after the 7th call:
{'SUCCESS': 7, 'FAIL_SYS_USER_VALIDATE +bxpunish': 53} | first non-SUCCESS at 8Each blocked response’s ret array also contained RGV587_ERROR::SM.
The block repeated, but the success count changed. A second run from the same IP address sent 6.2 requests per second, recorded the status code and response length of each call, got 15 successes in 60, and was first blocked at request 12. It returned HTTP 200 for all 60 calls, and all 45 of its blocked responses were exactly 543 bytes. So base your capacity plan on the block, not on either success count.
A new session didn’t remove the block. Each of 3 new sessions in a row started from an empty cookie jar and was blocked before the client could get a token. A request sent after a 60-second wait, again from an empty cookie jar, was blocked as well. So an automatic retry adds traffic without adding data, and proxy engineers warn that retry logic like this spends budget without any visible error.
This test used no delay between calls. Next, test the variables a production scraper adds, such as a long backoff, a new token for each batch, a deliberately slow request rate, and the ext block that the page’s own request signs. That block contains a crawler flag and an x-m-biz-bx-region key.
The signature stayed correct from request 7 to request 60, so more reverse engineering is unlikely to increase the success counts of 7 and 15 in 60 requests. The tests exclude the session as the cause. No test changed the IP address and the fingerprint separately, so the block could depend on either one. Anti-bot systems can also link one fingerprint across many IP addresses, so practitioners change the IP address, fingerprint, and cookies together.
Three checks show that the client isn’t the cause. On the tls.peet.ws fingerprint echo, the signing code on curl_cffi 0.16.1 matched a real Chromium 152 on that machine, with the same JA4 fingerprint, t13d1516h2_8daaf6152771_806a8c22fdea, and the same HTTP/2 fingerprint. Five fingerprints from curl_cffi and the Rust libraries rnet and wreq produced 100 blocked responses and no token, even though wreq ships newer Chrome profiles than curl_cffi 0.16.1. Patchright, nodriver, and Camoufox each succeeded 0 times in 8 attempts from that IP address, while Bright Data’s Browser API, on a different exit IP, returned the product in the same minute.
That IP address was already blocked when those 3 tools ran, so all 3 failed the same way on it. The zeros show the IP address’s reputation, and they don’t rank the tools.
The first check, TrackMe’s fingerprint echo at tls.peet.ws, returns every fingerprint from a single request:
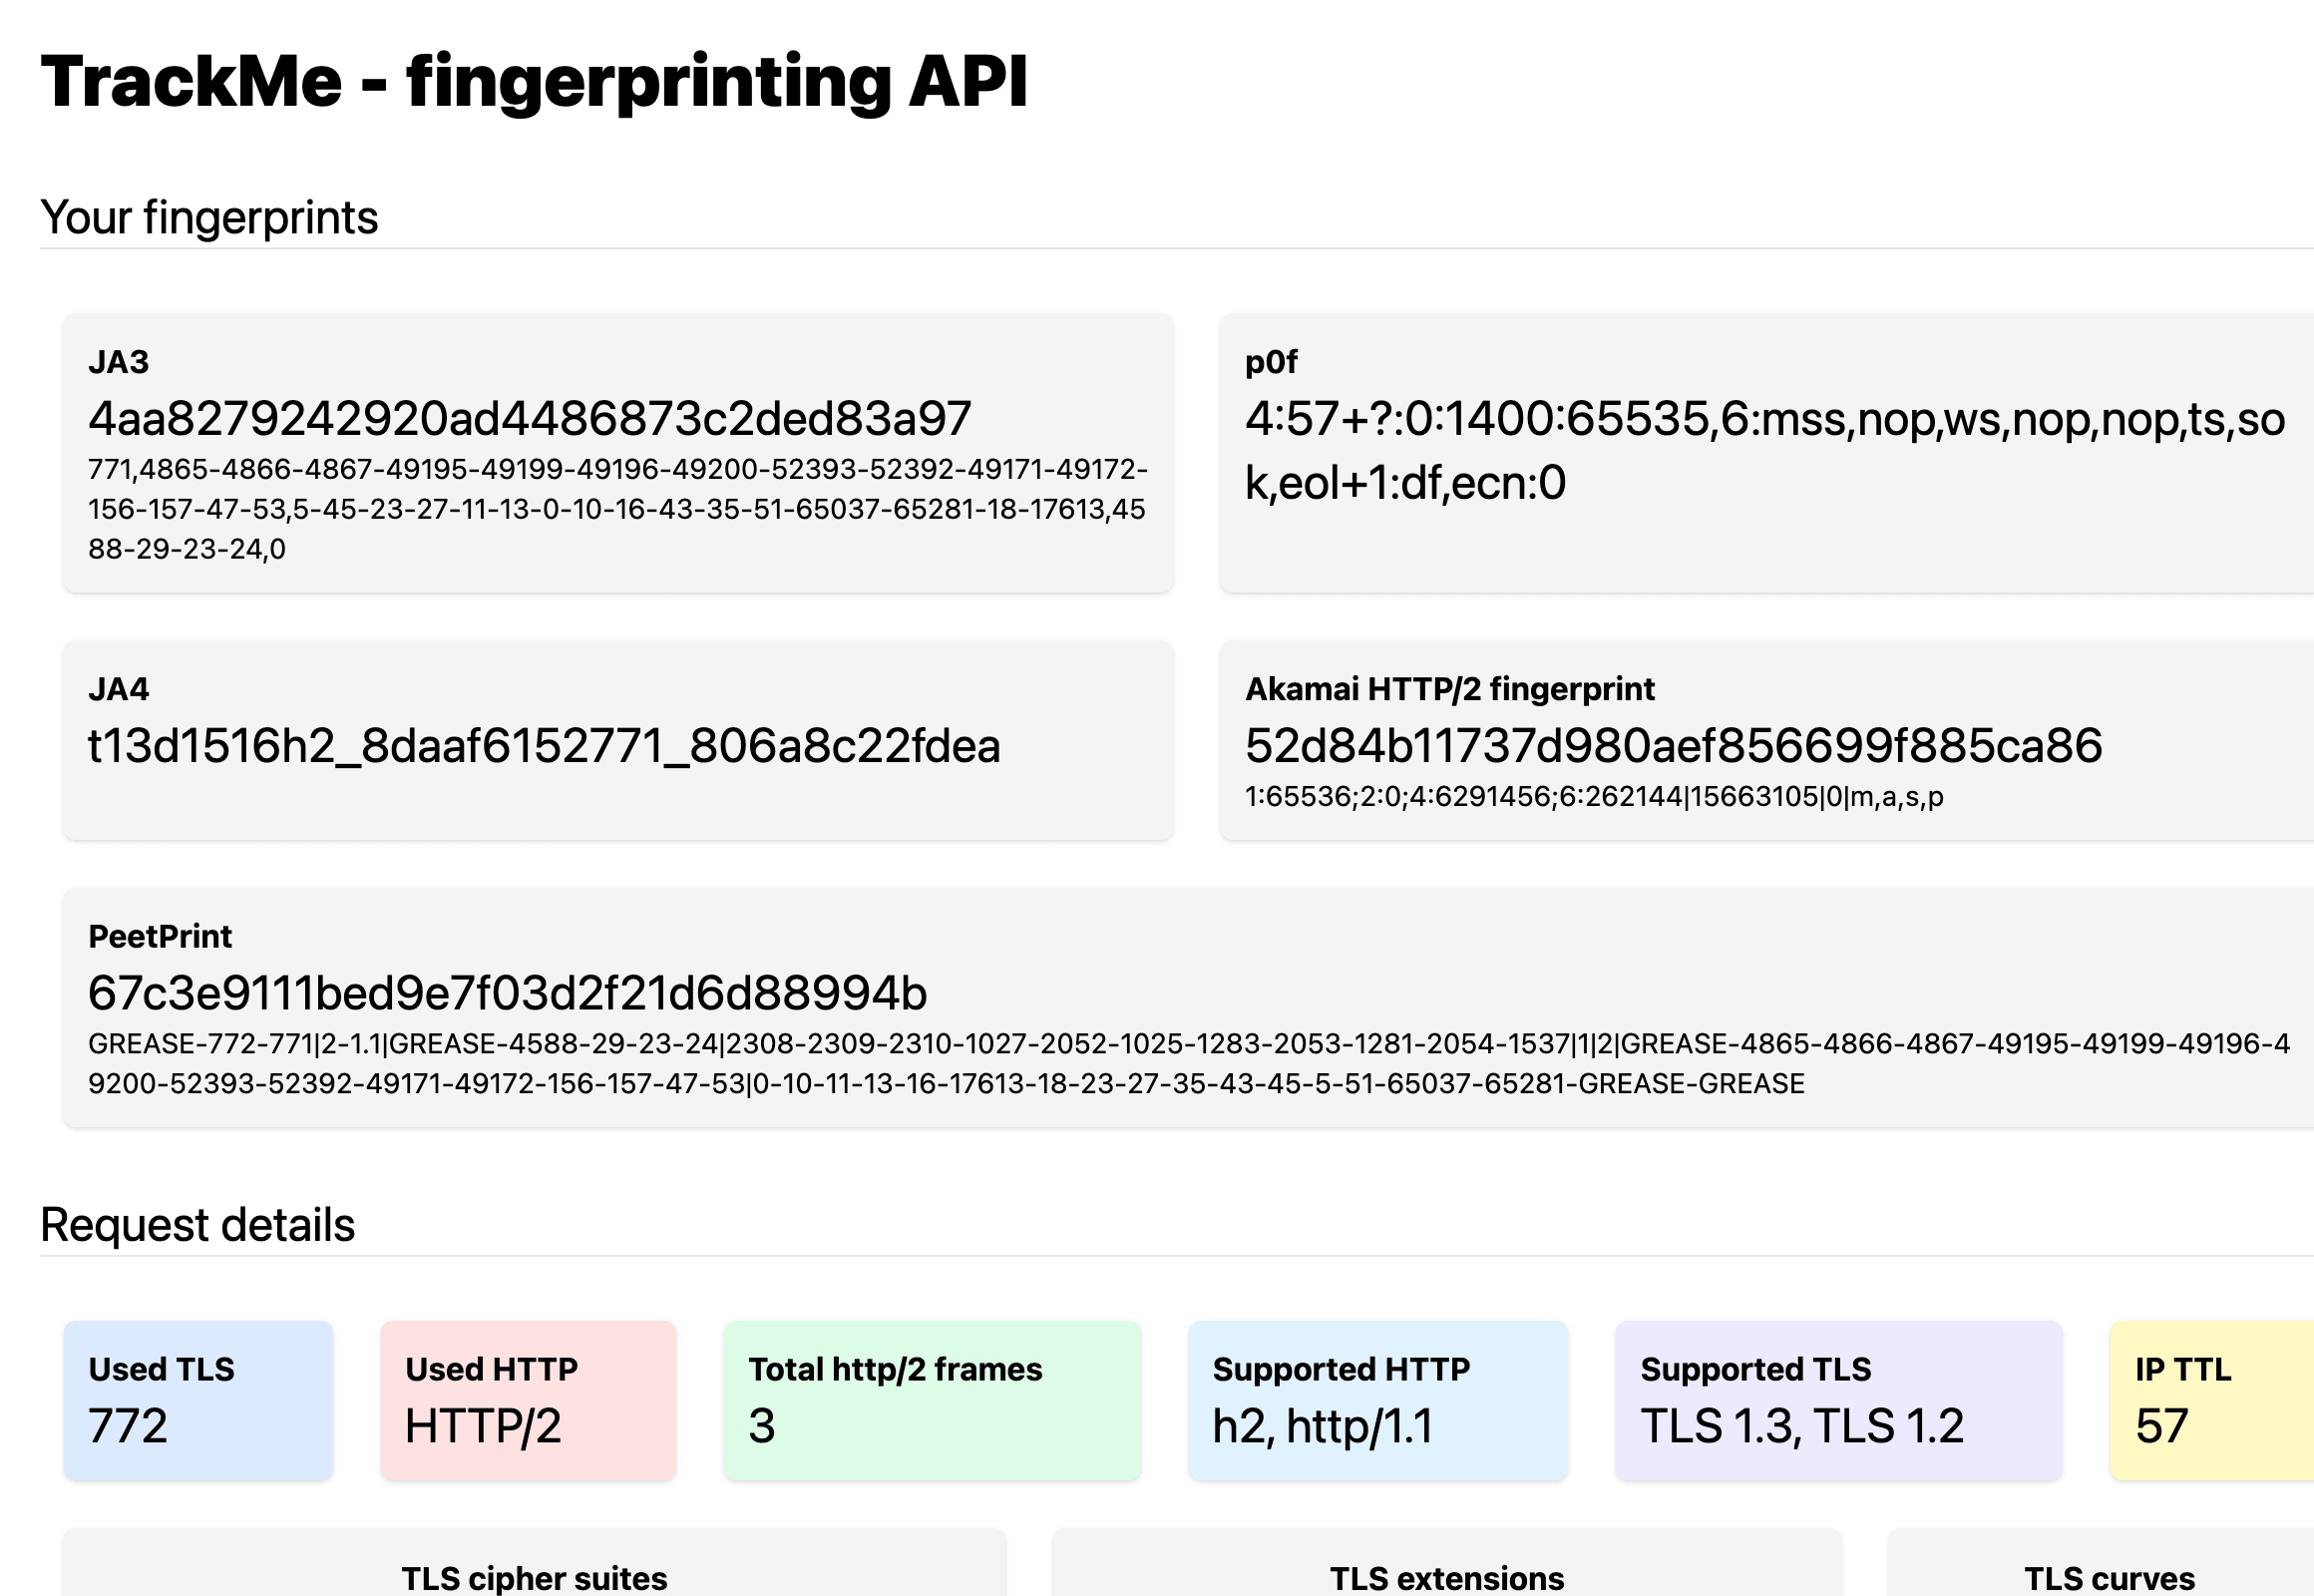
Check that a profile reproduces both the JA4 and the HTTP/2 fingerprint of the browser it’s named after.
A newer profile wasn’t a better match here. The wreq Chrome 152 profile sent a ClientHello with 17 extensions, and Chrome 152 itself sent 16. The version number in a profile’s name doesn’t guarantee the fingerprint it sends, so check each profile against a fingerprint echo before you trust it. Here, curl_cffi’s default profile matched the real browser exactly.
Reverse engineering a signed endpoint tells you what the data looks like, but not how much of it you can collect. In these tests, neither a better signature nor a better browser increased that amount.
Letting the page sign product API calls for you
A second way to get the product payload uses browser automation instead of API calls from your own code. The page already makes the signed call. Attach a response handler and read the responses the page receives. Through the Browser API, the page’s requests also go through Bright Data’s proxy network.
Reading the page’s own response removes the token, the timestamp, the MD5 signature, and the cookie jar from your code:
import json, re
from playwright.sync_api import sync_playwright

WSS = "wss://brd-customer-<id>-zone-<zone>:<password>@brd.superproxy.io:9222"

def capture_pdp(product_id):
    """Read the response to the call the page already makes."""
    bodies = []

    def keep(response):
        if "mtop.aliexpress.pdp.pc.query" not in response.url:
            return
        try:
            bodies.append(response.text())
        except Exception:
            pass                      # redirects and closed pages have no readable body

    with sync_playwright() as pw:
        browser = pw.chromium.connect_over_cdp(WSS, timeout=150_000)
        ctx = browser.contexts[0] if browser.contexts else browser.new_context()
        page = ctx.new_page()
        page.on("response", keep)
        try:
            page.goto(f"https://www.aliexpress.com/item/{product_id}.html",
                      wait_until="domcontentloaded", timeout=150_000)
            page.wait_for_timeout(13_000)
        except Exception:
            pass                      # keep whatever keep() collected before navigation ended
        browser.close()

    for body in sorted((b for b in bodies if isinstance(b, str)), key=len, reverse=True):
        m = re.match(r"\s*mtopjsonp\d*\((.*)\)\s*$", body, re.S)
        try:
            result = json.loads(m.group(1) if m else body).get("data", {}).get("result")
        except (ValueError, AttributeError):
            continue                  # skip a body that is not JSON, such as an HTML page
        if isinstance(result, dict) and len(result) > 10:
            return result
    return None

result = capture_pdp("1005001398867186")
if result:
    print(len(result["PRICE"]["skuIdStrPriceInfoMap"]), "SKUs priced")
WSS connects to a Browser API zone, and its 3 placeholders come from that zone’s Access details:
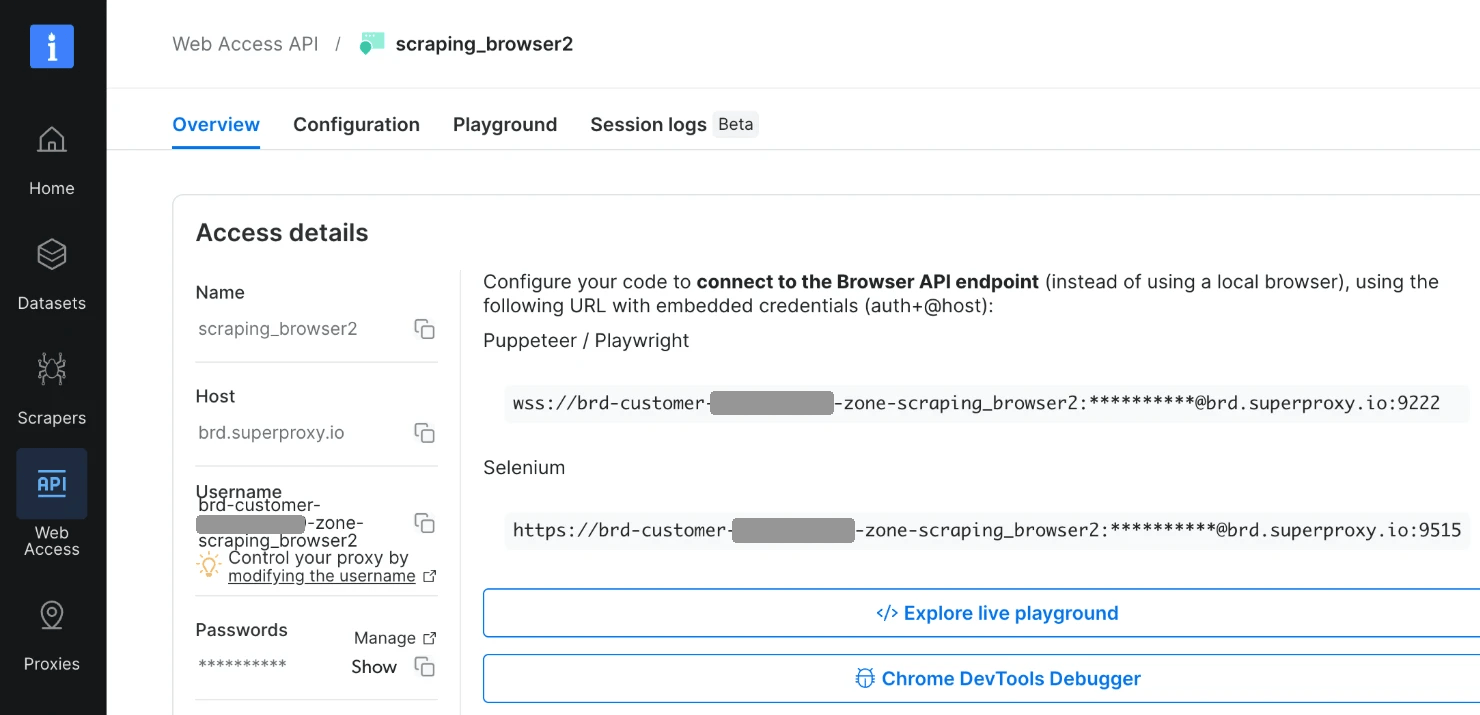
The Puppeteer / Playwright line is the value WSS expects, and your account ID, zone name, and password fill its 3 placeholders. The account ID is redacted here, and the Control Panel masks the password.
Keep every response, not just the first. The page calls that endpoint more than once per load. Log the size of every response body that keep() collects to see which one contains the product:
3256812884305776  sizes=[151, 170539]          141 SKUs priced
1005007712136541  sizes=[151, 244023]           75 SKUs priced
1005002754717958  sizes=[151, 105852, 106046]   20 SKUs priced
1005002495501001  sizes=[151,  96065]           18 SKUs priced
2255799968025159  sizes=[151,  93982]           15 SKUs priced
1005008121783683  sizes=[151,  63780]            6 SKUs priced
The 151-byte response sets the token cookie. The large response body after it contains the product record, including the SKU price map. When a load has more than one large response, capture_pdp returns the largest.
What the AliExpress robots.txt files allow
Read the robots.txt files before you choose a method. If a directive is new to you, our guide to robots.txt for web scraping explains it. The files on the API host and the main host have different rules:
$ curl -s https://acs.aliexpress.com/robots.txt
User-agent: *
Disallow: /

$ curl -s https://www.aliexpress.com/robots.txt | grep -E '/item'
Disallow: */aeglodetailweb/api/msite/item?productId*
Disallow: /items/*
Disallow: /item-img/*
Disallow: /item-img/*
The MTOP gateway is completely disallowed. On the main host, every rule mentioning item applies to something else (/items/*, /item-img/*, and the Googlebot rule on the aeglodetailweb endpoint). No rule applies to /item/1005001398867186.html, while all of /search/* is disallowed. Use Bright Data’s residential proxies, or one of the methods below, for the paths that robots.txt allows.
Also check the main host’s sitemaps and agent manifest files. The .com robots.txt listed item sitemaps, and the first sitemap file contained 31,999 /item/ URLs, so the sitemaps are a direct source of product IDs. In testing, the 6 agent manifest paths (/llms.txt and /ai.txt, plus agent.json, ai-plugin.json, mcp.json, and acp.json under /.well-known/) redirected with a 302 to /p/error/404.html.
www.aliexpress.us/robots.txt had the same rules as the .com file, without the sitemap lines. Because the site redirects visitors between the 2 hosts by region, those rules apply on both hosts. m.aliexpress.com publishes a longer file with its own AdsBot rule, so check the host you’re calling.
One AliExpress host publishes an exception, the only signed API path that any of these files allows. recom-acs.aliexpress.com serves Disallow: / followed by Allow: /h5/mtop.relationrecommend.aliexpressseorecommend.recommend/*. Called with a deliberately incomplete payload, that endpoint returned FAIL_SYS_BIZPARAM_MISSED without a bxpunish header, while the disallowed endpoints returned FAIL_SYS_USER_VALIDATE with that header. So robots.txt and the anti-bot system both allowed the same endpoint.
The product page is the opposite of the gateway. AliExpress serves it to the public, robots.txt doesn’t disallow it, and each of the 3 Bright Data products accessed it in testing. A Web Unlocker render, the gateway response, and a Scraper API record all had the same $6.84 sale price in US-locale tests.
Scrape the pages the site makes public, and let your infrastructure handle IP addresses and fingerprints. That approach is less likely to break after a redesign or a signature change, while a signing routine copied from the site’s JavaScript bundle has to be redone after either.
3 methods to scrape AliExpress at scale
Bright Data’s Browser API, Web Unlocker, and Scraper API each provide the product data in a different form. Our comparison of Web Unlocker and the Browser API explains how they differ in general. Searching the Control Panel’s Scrapers Library for AliExpress shows the scrapers available for this domain:
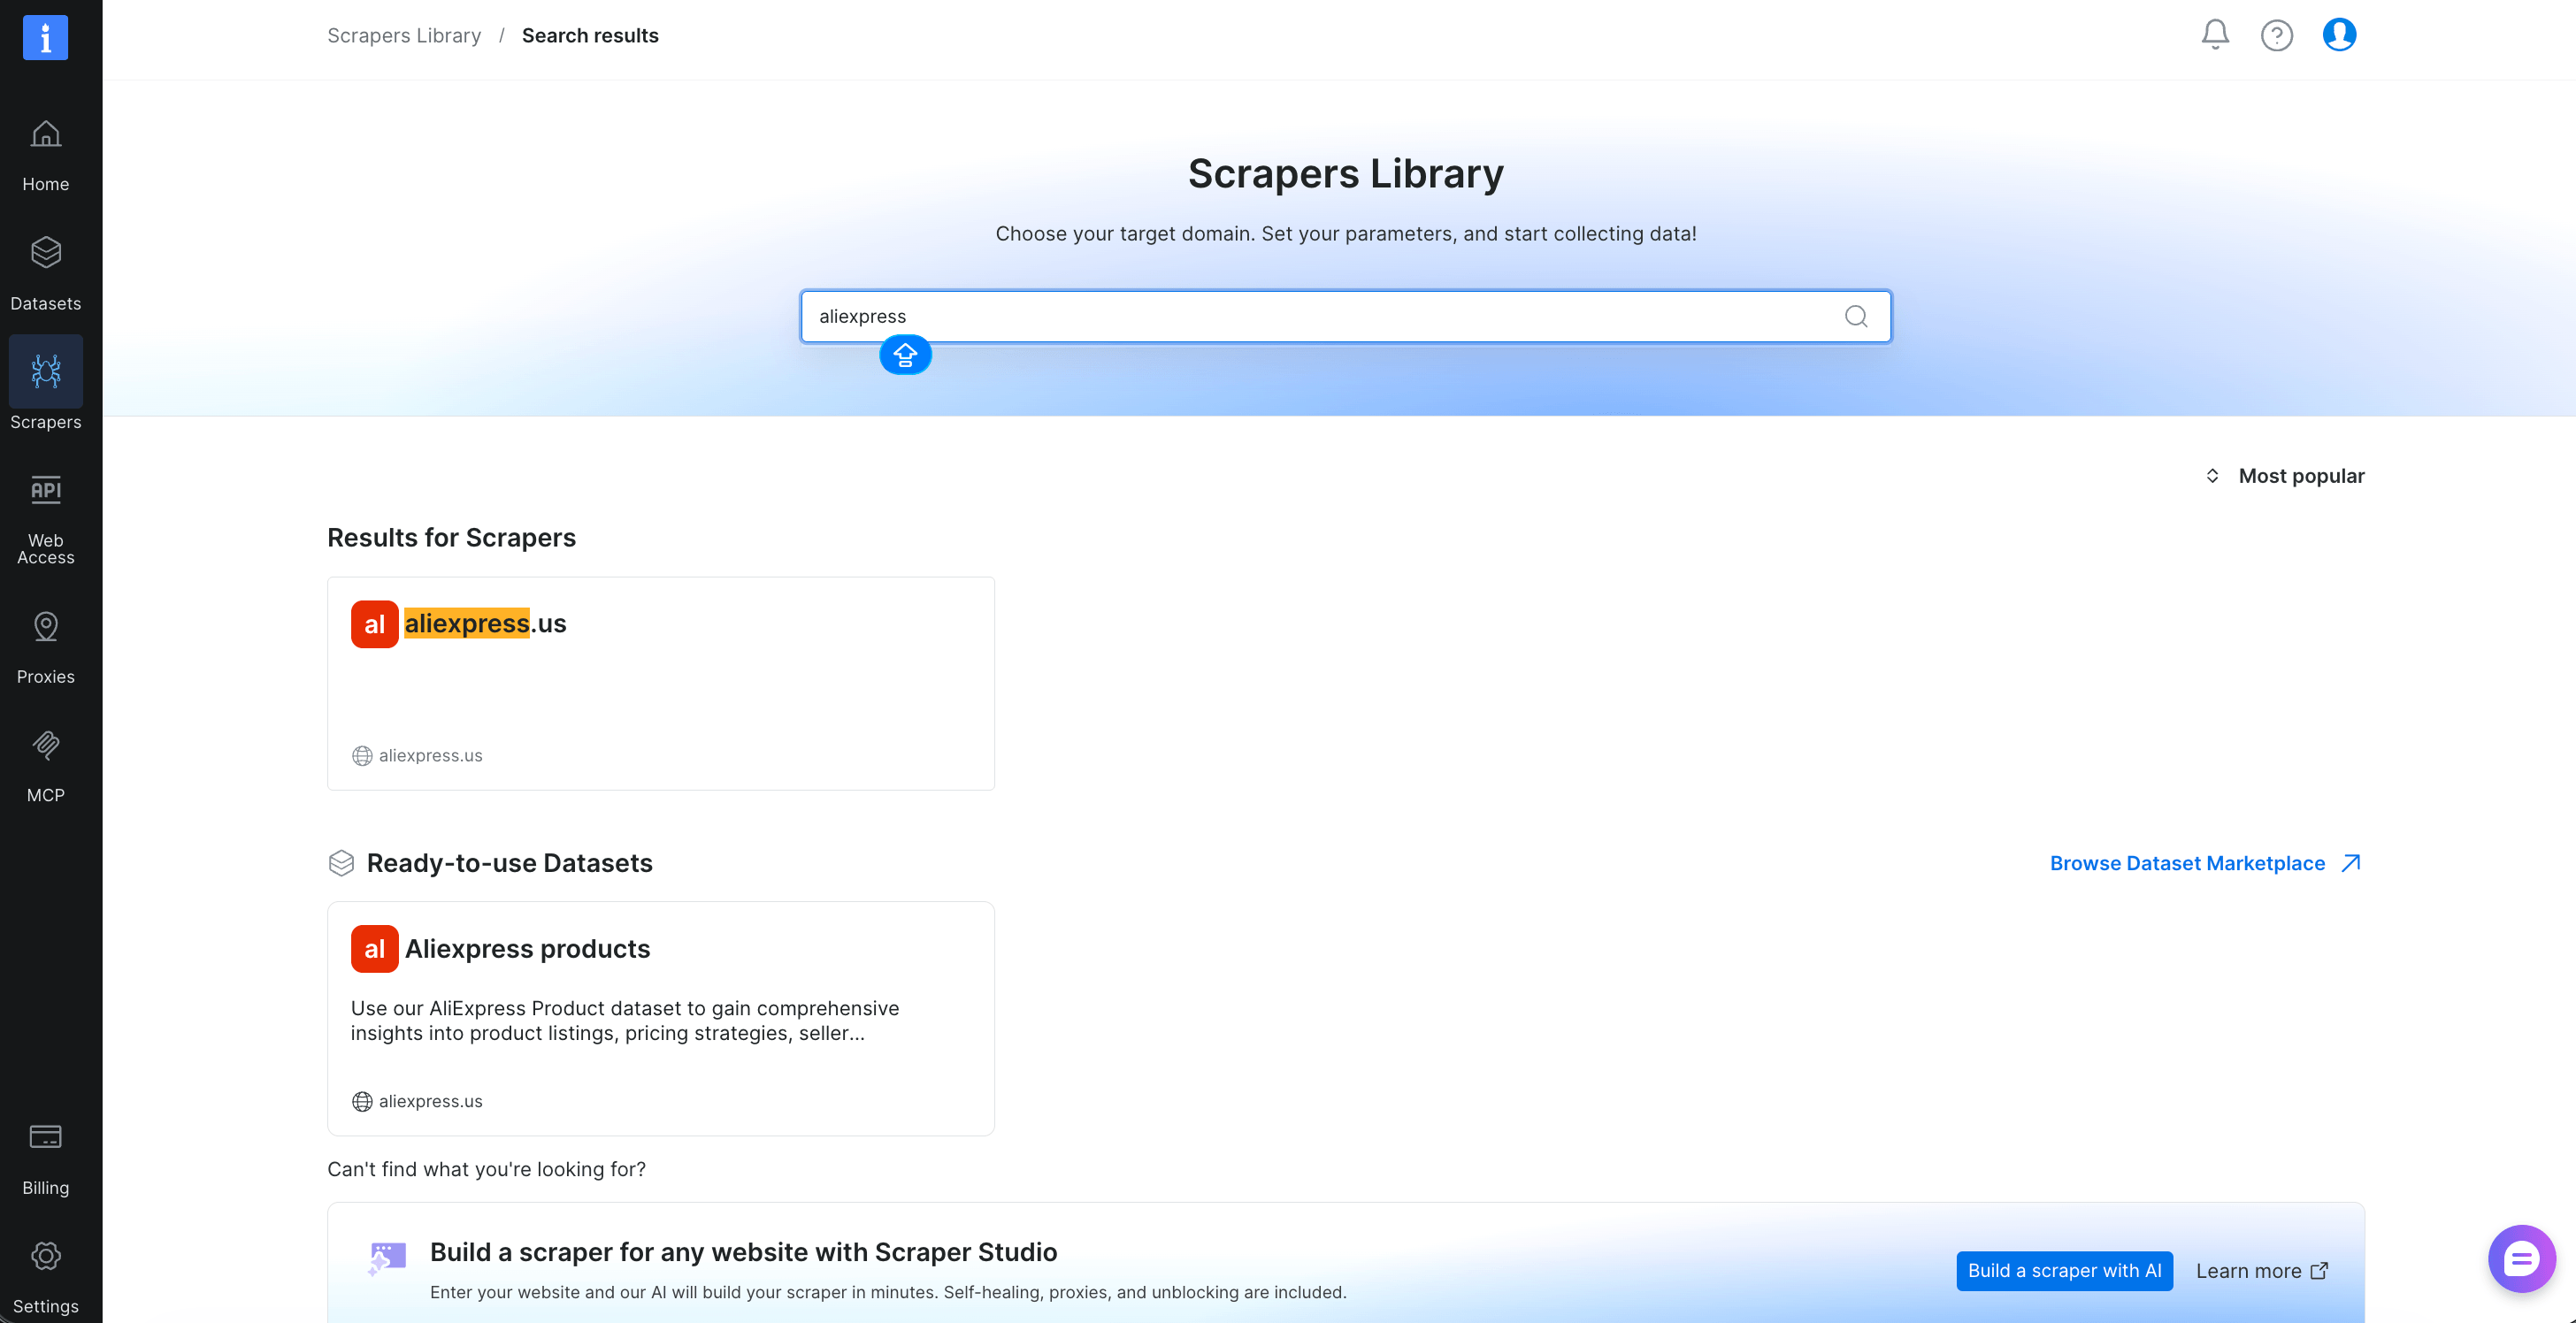
One search returns the domain’s scrapers and a ready-to-use AliExpress dataset.
Browser API runs your script in a managed cloud browser with built-in unblocking and lets your script read the network responses the page receives. When I connected Playwright over CDP and loaded the product page, the page showed the title and a buy box with its price, and my script could read all 171 responses from that single load. The Browser API also supports geolocation targeting, so the buy box shows prices in the currency of the exit country you choose. For US prices, append -country-us to the zone username.
Browser API pricing is per GB of traffic, so page weight lets you estimate a run’s cost before you start. Across 3 loads, the transferred bytes in CDP’s Network.loadingFinished events averaged 3.03 MB per product page, with a range of 2.68 MB to 3.47 MB. Playwright’s networkidle waits for 500 ms with no requests, but this page kept sending requests in the background. So capture_pdp waits for domcontentloaded and then for a fixed time.
Web Unlocker handles the unblocking, renders the page, and returns one document. Its raw output for the product page was 344,355 bytes, compared with the 77,226-byte shell, so the JavaScript ran. Its markdown output for this page was 21 KB to 24 KB of text that an LLM or a regex can read directly. The brightdata scrape command in the Bright Data CLI uses markdown output by default.
Web Unlocker pricing is per request, and you pay only for successful ones. Set country on each request to select the storefront.
AliExpress Scraper API returns structured data. You send product URLs and receive records with the fields already extracted, such as the title, list and sale price, availability, specifications, seller, rating, reviews, and image URLs. The AliExpress Image Scraper API specializes in image data. Scraper API pricing is per delivered record, so you pay only for results.
| Product | Pricing unit | What you receive | Use it when |
|---|---|---|---|
| Browser API | GB of traffic | A browser session and the page’s network responses | You want the page’s own API responses, such as each variant’s price |
| Web Unlocker | Successful request | Rendered HTML or markdown you parse | You already maintain a parser, or you send pages to an LLM |
| Scraper API | Delivered record | Structured product records | You want records, not pages |
Running your own browser is the fourth option, so I measured it too. The 3 stealth browsers (Patchright, nodriver, and Camoufox) are open source and averaged 14.1 to 15.9 seconds per load. That time is a minimum, because none of the 24 loads reached the product data, and a successful load would also spend time parsing it.
On an already-blocked IP address, all 3 stealth browsers returned the page’s header and footer but no product data. Each Bright Data product has built-in proxies, and a browser you run yourself can use Bright Data’s AliExpress Proxies.
Running the Scraper API at scale
The Scraper API accepts URLs on one endpoint and returns records on another. Its Control Panel page shows both scraper modes beside a ready-to-run request:
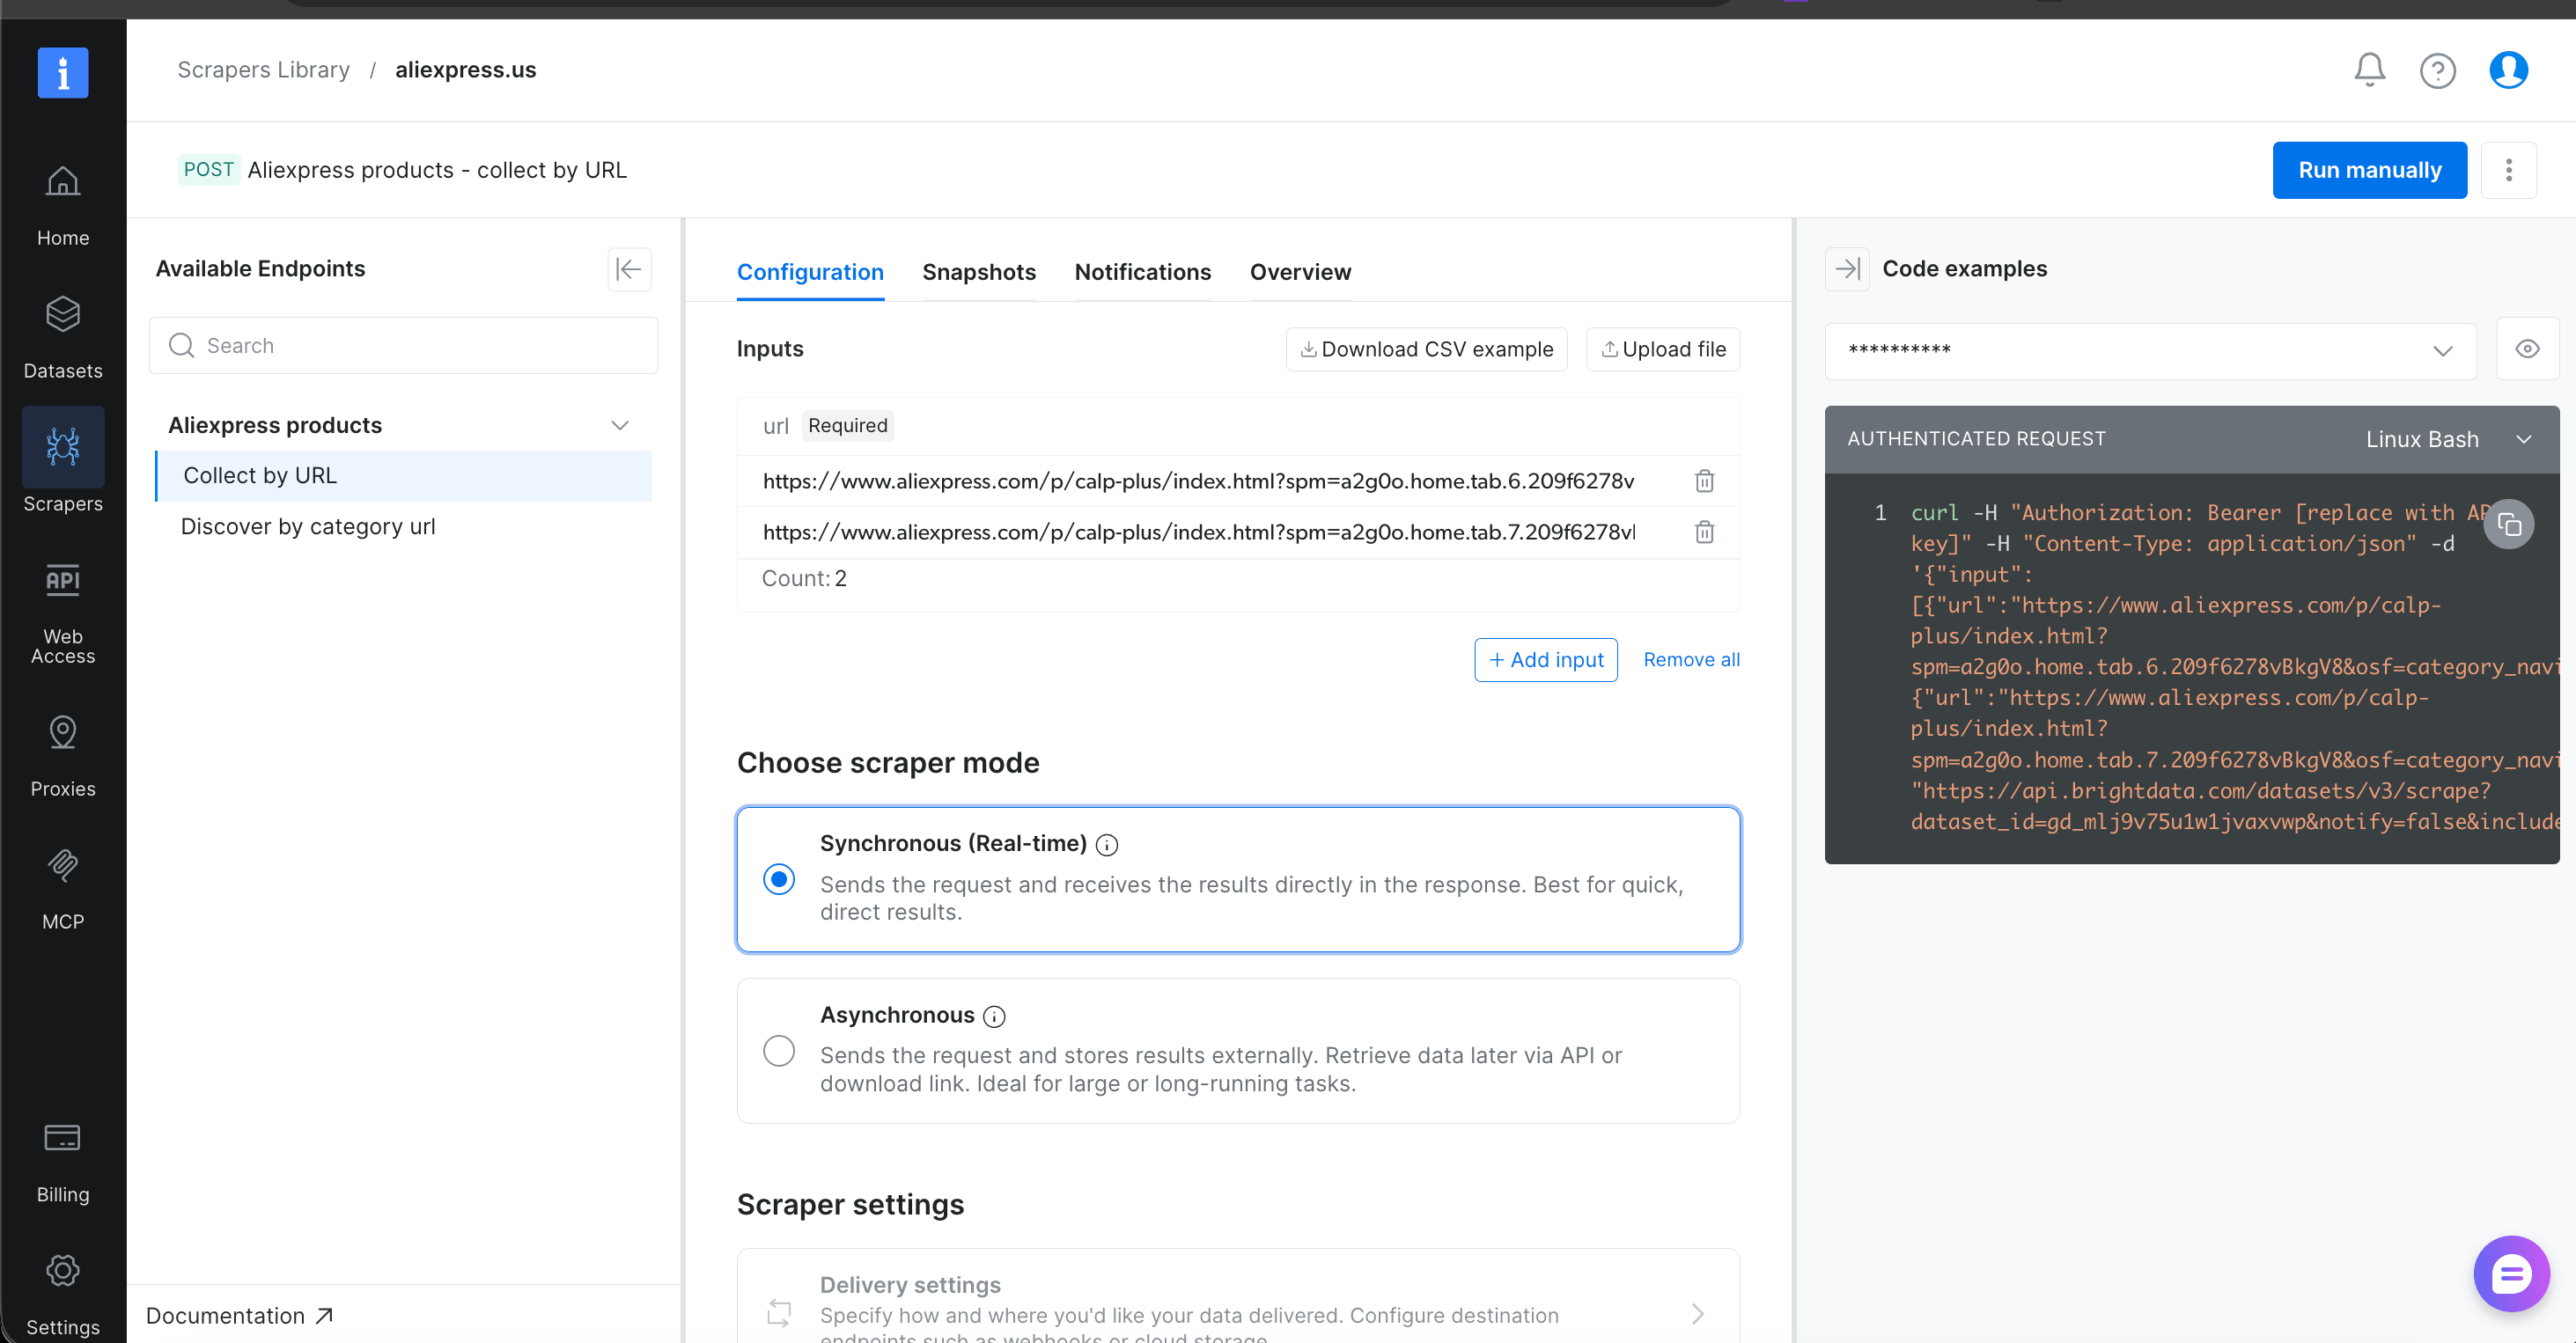
The left panel lists the domain’s 2 endpoints, Collect by URL and Discover by category URL. The dataset_id in the code example on the right is the same value the script below uses.
Synchronous mode returns a snapshot_id when a collection takes a long time, and the collection continues in the background. For a full catalog, trigger an asynchronous collection in chunks and save progress after each one, so that if your process crashes, the run resumes and you don’t pay for the same URLs twice:
import json, os, time, requests

API = "https://api.brightdata.com/datasets/v3"
DATASET = "gd_mlj9v75u1w1jvaxvwp"          # AliExpress products
TOKEN = os.environ["BRIGHTDATA_API_KEY"]   # API key from your account settings
CHUNK = 40                                 # larger triggers ran faster per input
H = {"Authorization": f"Bearer {TOKEN}", "Content-Type": "application/json"}

def _await(snapshot, timeout=3600, poll=20):
    deadline = time.time() + timeout
    while time.time() < deadline:
        p = requests.get(f"{API}/progress/{snapshot}", headers=H, timeout=60).json()
        if p.get("status") in ("ready", "failed"):
            return p
        time.sleep(poll)
    raise TimeoutError(snapshot)

def _save(state, state_path):
    with open(state_path, "w") as fh:
        json.dump(state, fh)

def run(urls, state_path="run_state.json", out_path="rows.jsonl"):
    state = {"done": {}, "dead": []}
    if os.path.exists(state_path):
        with open(state_path) as fh:
            state = json.load(fh)

    for n in range(0, len(urls), CHUNK):
        key = str(n // CHUNK)
        done = state["done"].get(key, {})
        if done.get("records") is not None:     # finished means downloaded, not triggered
            continue
        batch, t0 = urls[n:n + CHUNK], time.time()
        snapshot = done.get("snapshot")         # triggered before a crash: reuse that snapshot
        if not snapshot:
            r = requests.post(f"{API}/trigger?dataset_id={DATASET}&include_errors=true",
                              headers=H, json={"input": [{"url": u} for u in batch]},
                              timeout=120)
            r.raise_for_status()
            snapshot = r.json()["snapshot_id"]
            state["done"][key] = {"snapshot": snapshot}
            _save(state, state_path)            # record the trigger BEFORE the wait

        print(f"chunk {key}: collecting {len(batch)} URLs")
        progress = _await(snapshot)
        rows = requests.get(f"{API}/snapshot/{snapshot}?format=json",
                            headers=H, timeout=600).json()
        with open(out_path, "a") as fh:
            for row in rows:
                if row.get("error_code") == "dead_page":   # listing removed on AliExpress
                    state["dead"].append(row["input"]["url"])
                elif not row.get("error"):
                    fh.write(json.dumps(row) + "\n")
        state["done"][key].update(records=progress.get("records"), errors=progress.get("errors"))
        _save(state, state_path)
        print(f"chunk {key}: collected at {(time.time() - t0) / len(batch):.1f}s per input")

    return state

run(["https://www.aliexpress.com/item/1005001398867186.html"])   # pass your full URL list
include_errors=true adds the errors report to the results, so every URL in your list has a status.
Each line in rows.jsonl is one product record. This script prints a few fields from the first record:
import json

with open("rows.jsonl") as fh:
    row = json.loads(fh.readline())
for key in ("item_id", "title", "brand", "price", "sale_price",
            "availability", "star_rating", "review_count"):
    print(f"{key:13s}", row[key])
print("variants     ", [o["option_name"] for o in row["variants"][0]["variant_options"]])
The output shows the circuit breaker from the first section:
item_id       1005001398867186
title         TOMZN Main Switch Residual Current Circuit Breaker With Surge Protector RCBO MCB With Lightning Protection SPD
brand         TOMZN
price         $14.40
sale_price    $8.40
availability  in_stock
star_rating   4.7
review_count  80
variants      ['16A', '20A', '25A', '32A', '40A', '50A', '63A']
The list price, the 4.7 rating from 80 reviews, and the 7 rated-current variants match the rendered page in the first section. The sale price comes from a temporary promotion, so it differs between captures.
Keep every chunk full. In these runs, a 40-URL trigger finished 2.8 times faster per URL than a 20-URL one. Fill the last chunk with URLs from your next run so it runs at full size. For hundreds of thousands of URLs, let Bright Data deliver each snapshot to your cloud storage or to a webhook, so results arrive without polling.
Running run() again with the same state file finished in 0.08 seconds, sent no triggers, and wrote no duplicate rows. The script also handles a chunk that was triggered before the process crashed during the wait. It skips a chunk only if its records were already downloaded. Otherwise, it reuses the saved snapshot, so a crash during the wait doesn’t lose a collected snapshot.
Measure how often prices change, then match your collection schedule to that rate. In one check, I captured 12 products twice, 25 minutes apart, and none of their prices changed. That sample can’t show a price-change rate, so use the method, not the result. Two snapshots of your own products, taken at the interval you’re considering, will answer the question for your catalog.
Discovery, the scraper’s discover-by-category endpoint, lists products from a seed URL. With the wholesale search page /w/wholesale-ergonomic-chair.html as the seed, a type=discover_new&discover_by=category_url request returned product URLs on the first run. Use /w/wholesale-<keyword>.html as your seed URL pattern, limit every discovery run with limit_per_input while you calibrate, and pass the returned URLs directly to the collection run.
If you collect product IDs from other places, such as the item sitemaps or a product page’s SEO links, a single GET request without rendering shows whether each ID still has a product page. Product pages returned 77.2 to 77.4 KB with a populated og:title, while 3 IDs collected from those SEO links returned 75.26 KB with every og: field empty. That 2 KB difference is visible in the raw response, so drop the IDs with empty og: fields before you queue a collection.
2 checks that keep price data comparable
The data needs the same validation as the HTTP responses. Each of these 2 checks is cheap to add and helps you catch prices that aren’t comparable before they reach a dashboard.
The discount varied with the exit country, not just the currency. I fetched one product ID through Web Unlocker in markdown format from 6 exit countries, and each country returned a different promotion:
| Exit country | Currency | Sale price | List price | Discount |
|---|---|---|---|---|
| United States | USD | $6.84 | $14.40 | 52.5% |
| United Kingdom | GBP | £9.83 | £11.16 | 11.9% |
| Germany | EUR | 11,69€ | 13,29€ | 12.0% |
| Brazil | BRL | R$62,25 | R$68,30 | 8.9% |
| Australia | AUD | AU$18.59 | AU$19.42 | 4.3% |
| Canada | CAD | C$19.86 | C$20.70 | 4.1% |
Even the percentages aren’t directly comparable, and each page shows why. The US buy box labels its price Ends :, so the US row is a limited-time deal captured at one moment. The UK page says Price includes VAT while the US page says Tax excluded. The German page states 30-day lowest price before the discount, the EU reference-price rule that tends to make German discounts look smaller.
Because of those 3 differences, set one exit country for each price series, store it in the row, and compare a series only with itself. Web Unlocker sets it with the country parameter, and the Browser API sets it with a -country-<code> suffix on the zone username. If you need the promotions themselves rather than a price pipeline, the AliExpress Promotions Tracker monitors competitor promotions for you.
The UK pound sign is the fullwidth one. The UK storefront uses £, U+FFE1 FULLWIDTH POUND SIGN, so a currency regex written with £ (U+00A3) matches nothing. The German and Brazilian storefronts use a comma as the decimal separator in the price field. Parse the currency from the storefront setting you requested and keep the number parsing separate from the symbol.
Every variant’s price and the full category path
Bright Data’s Browser API captures the SKU price map from an AliExpress product page, and Web Unlocker returns the category breadcrumb from its footer. Reviews also have a dedicated scraper, the AliExpress Reviews Scraper, whose records include the product ID and URL.
The page’s own response contains the SKU price map. The captures logged with capture_pdp included prices for 141, 75, 20, 18, 15, and 6 SKUs. For one product, the price map had 6 distinct prices, from 2.56 to 10.96. The map is in the PRICE module, next to the preselected SKU and the region field:
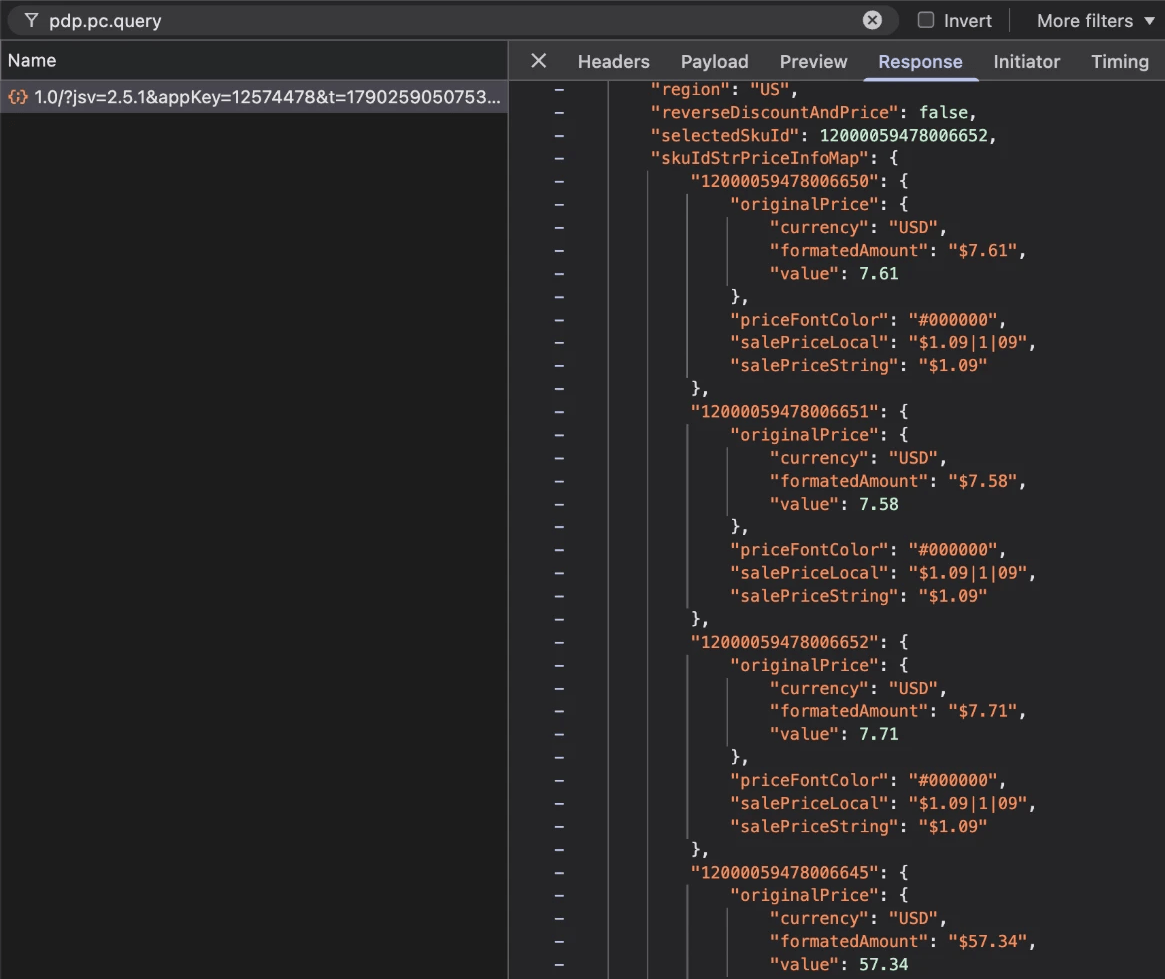
This capture comes from a multipack listing. The page preselects a 1-pack at $1.09, and the fourth entry is a 10-pack listed at $57.34, so the map contains each variant’s own price.
To get each variant’s price, run capture_pdp through the Browser API, read PRICE.skuIdStrPriceInfoMap, and store it with item_id as the key. Read the map from the region whose prices you need, because it can vary by region too. For the circuit breaker from the first section, the map had different variant prices in a US session and a single price for all 7 variants in another region.
Web Unlocker markdown contains the category path. The rendered page lists the product’s categories as a breadcrumb in the footer, and the gateway’s GLOBAL_DATA.globalData has the same path in its categoryPath field, 13/5/141914. The parser below reads the product page as Web Unlocker markdown, the format brightdata scrape returns by default:
import re

CRUMB   = re.compile(r"^This product belongs to\s.*$", re.M)
CAT_URL = re.compile(r"/category/(\d+)/([a-z0-9-]+)\.html")

def categories_from_markdown(md):
    """Category IDs and URLs from the product page footer."""
    line = CRUMB.search(md)
    if not line:
        return []
    return [{"category_id": cid,
             "url": f"https://www.aliexpress.com/category/{cid}/{slug}.html"}
            for cid, slug in CAT_URL.findall(line.group(0))]

with open("page.md", encoding="utf-8") as fh:    # brightdata scrape <product URL> -o page.md
    print(categories_from_markdown(fh.read()))
The \s at the end of the first pattern is essential, because the footer puts U+00A0, a non-breaking space, immediately after to. The same pattern written with a literal space finds no match. With \s, the parser returns the category path:
[{'category_id': '13',     'url': '.../category/13/home-improvement.html'},
 {'category_id': '5',      'url': '.../category/5/electrical-equipments-supplies.html'},
 {'category_id': '141914', 'url': '.../category/141914/circuit-breakers.html'}]
Getting the category path needs one Web Unlocker request per product. Run the parser on the products whose taxonomy you need, and store the result with item_id as the key. The footer wording can change without notice, so check the CRUMB pattern first if the parser returns an empty list.
Scraper Studio handles a custom field list. When you describe the data you need, its AI generates a ready-to-run scraper with proxies and unblocking built in, and you can add or change output fields later. For price monitoring specifically, the AliExpress Price Scraper API collects AliExpress pricing data so you can track how prices change.
Detecting page and schema changes
Every failure seen on this target was silent, so monitor the page itself. The page’s bootstrap script contains a build version, cosmos_prefetch_mtop version 20240605.195626.856, and when that version changes, the prefetch config can change with it. A fingerprint detects that change directly. Without one, your own scraper would only show it as null values.
The 2 fingerprints below check 3 stages (the HTML shell, the rendered page, and the delivered row), and neither depends on parsing product fields:
import hashlib, re

def shell_fingerprint(html):
    """From an unrendered GET. Detects a bootstrap or prefetch-config change."""
    view = re.search(r"viewName\s*=\s*'([^']+)'", html)
    api  = re.search(r"api:\s*'(mtop\.[^']+)'", html)
    ver  = re.search(r"cosmos_prefetch_mtop version ([\d.]+)", html)
    return {"viewName": view.group(1) if view else None,
            "prefetch_api": api.group(1) if api else None,
            "gop_version": ver.group(1) if ver else None}

def row_fingerprint(row):
    """From a delivered row. Confirms the field set your pipeline expects."""
    keys = sorted(k for k in row if k not in ("input", "timestamp"))
    return {"fields_sha1": hashlib.sha1(",".join(keys).encode()).hexdigest()[:12]}
On real captures, both fingerprints returned stable values:
shell   unrendered GET : viewName=newDetail  api=mtop.aliexpress.pdp.pc.query  gop=20240605.195626.856
shell   rendered DOM   : viewName=newDetail  api=mtop.aliexpress.pdp.pc.query  gop=20240605.195626.856
row     1005012408061151 : fields_sha1=154f2f84da5f
row     1005001398867186 : fields_sha1=154f2f84da5f
row     1005011666876666 : fields_sha1=154f2f84da5f
A third fingerprint of the captured payload looks useful, but it can cause false positives. Hashing the module set seems like the same idea, but the module count varied with the listing and the time of capture, not only with a new deployment. The captured payloads had 28, 27, and 28 modules, and the PRICE key set differed between 2 of them.
The count changed within one product too. The same product ID returned 27 modules and then 26 on 2 captures minutes apart, so even a per-product history needs a threshold rather than an equality check. Base your alerts on the shell and row fingerprints, because their values stayed the same in every capture.
When to buy the AliExpress dataset instead
The 3 methods all start from URLs you already have. If your question is about the whole market, start with the ready-to-use dataset:
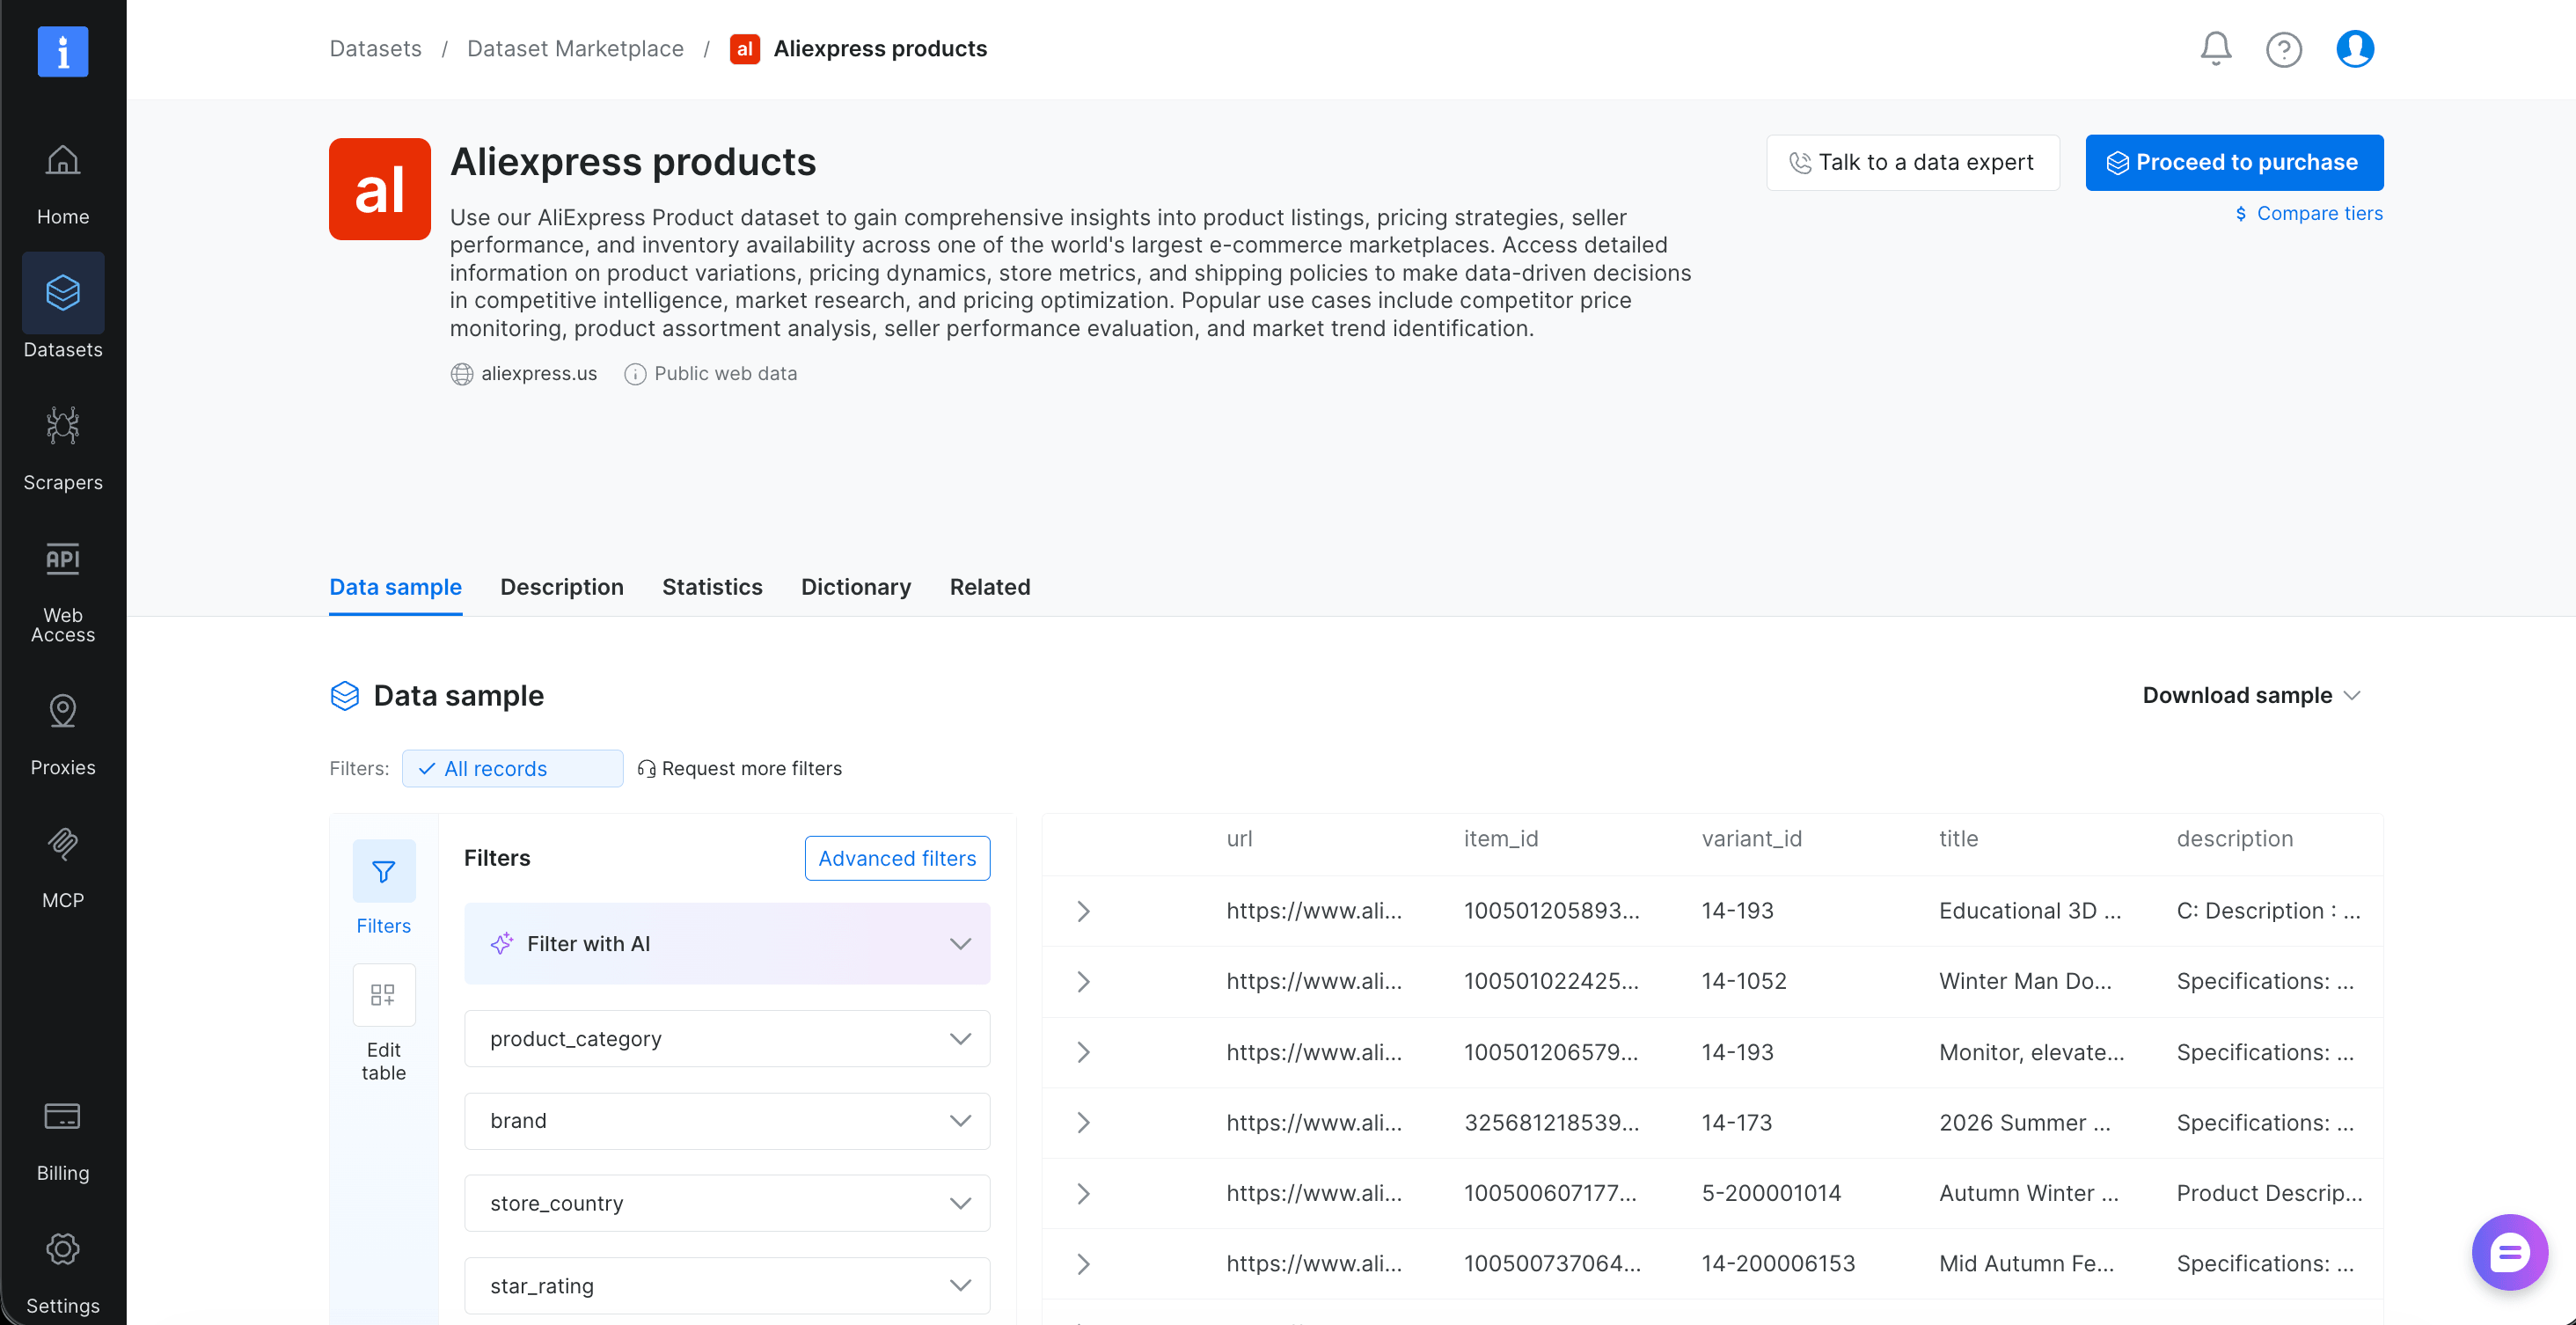
The filter panel lets you select records before you pay for them.
The AliExpress dataset reduces selection work and collection time. You filter the dataset to the records you need, in the marketplace or through the Filter Dataset API, and pay only for your filtered snapshot. Those records already exist, so there’s no collection run to wait for. You can buy it once or on a refresh schedule you choose, and current prices are on the datasets pricing page.
Estimate the delivery size before you order it. Records in the dataset sample average 12.75 KB as delivered JSON, so plan for about 1.3 GB per 100,000 records. The dataset also delivers in Parquet, and the same sample converted to Parquet was almost 8 times smaller. That size difference can determine whether you query the file in place or stage it first.
Use the dataset for market-wide assortment and coverage questions, and use the Scraper API for the specific listings you track. The dataset refreshes on the schedule you choose, and a Scraper API collection returns each listing at the moment you run it.
Final thoughts
AliExpress’s signing scheme fits in one function, but in testing, the gateway blocked calls from one IP address within the first dozen requests, even with a correct signature. Because a block can return a success status code, base every check on the bxpunish header and on a field that every product has, such as the price. The site’s robots.txt doesn’t disallow the public /item/ path, so that’s the path to scrape at scale.
Bright Data’s AliExpress Scraper API returns structured records for those product pages, the Browser API captures each variant’s price, and the AliExpress dataset suits whole-market questions. Start on the free tier, which includes 5,000 requests a month with no credit card required. Test it with 40 URLs from your catalog, and check the records against the fields your pipeline needs.
FAQ
Does AliExpress have an API for product data?
Yes, for sellers, affiliates, and approved dropshippers. On the AliExpress Open Platform, a seller authorizes an app for their own store through OAuth 2.0, and the affiliate API covers the promotional catalog. None of them covers the whole marketplace, so market-level pricing data needs ecommerce data collection.
How do I get an AliExpress product URL or ID?
Product URLs follow the pattern /item/<item_id>.html, and discovery starts from /w/wholesale-<keyword>.html. IDs depend on the host. One product has the ID 1005001398867186 on .com and 3256801212552434 on .us. Key each product by its final URL after the regional redirect, so it doesn’t appear under 2 IDs.
Is scraping AliExpress product data free?
Yes, at small scale. Bright Data’s free tier includes 5,000 requests a month with no credit card required, and it covers the Scraper API, Web Unlocker, and the Browser API, so you can test them on your own URLs first. Playwright and curl_cffi are open source. At production scale, you pay mostly for IP addresses, because 2 runs of 60 signed API calls from one IP address got data 7 and 15 times.
What does an AliExpress scraper API cost?
Bright Data’s AliExpress Scraper API is priced per delivered record, and Web Unlocker is priced per successful request, so you pay only for results. The Browser API is priced by traffic, so page weight predicts its cost. A product page weighed about 3 MB in testing. Current prices are on Bright Data’s pricing page.
Why does my AliExpress scraper return empty fields?
Because the initial HTML has no prices or stock. window.runParams is an empty object and <title> is blank, so selector-based extractors match nothing and raise no error. The page’s JavaScript loads the fields later from mtop.aliexpress.pdp.pc.query. Either execute the JavaScript or call that API directly.
How do I avoid getting blocked scraping AliExpress?
Send requests through Bright Data’s Scraper API or Web Unlocker, which have built-in proxies and AliExpress CAPTCHA solving. In testing, neither a new cookie jar nor a 60-second wait removed a block from one IP address. Blocked requests also returned HTTP 200, so check for the bxpunish header, not the status code.
Why do AliExpress prices change?
Because promotions are temporary and vary by country. In one test across 6 exit countries, one product’s discount ranged from 52.5% down to 4.1% off the list price, and the countries differed in whether prices included tax. Set one exit country for each price series and store it in the row.
Is there an AliExpress MCP server?
Yes. Bright Data’s MCP Server lets an AI agent fetch AliExpress product pages through its scrape_as_markdown and scrape_batch tools, which handle unblocking and return markdown. In a test call, scrape_as_markdown returned the product’s price, rating, variants, and category path. The AliExpress MCP page explains setup.


Technical Writer
 5 years experience
Satyam Tripathi helps SaaS and data startups turn complex tech into actionable content, boosting developer adoption and user understanding.