Yahoo Finance offers free quotes, price history, financial statements, and analyst estimates, but no official API. Its quote pages contain that data as JSON inside the HTML, so a Python pipeline can read it without a browser.
Code from many older tutorials failed in 2 ways. With its default User-Agent, Python’s requests library got 429 Too Many Requests on its first request. When a request succeeded, the old selectors matched nothing or the S&P 500’s price instead of the stock’s.
This guide shows you how to scrape Yahoo Finance from that JSON, avoid the 429, and move to a server.
TL;DR
- Yahoo’s 429 on the first request depends on the client, not the request rate. Impersonating Chrome, curl_cffi requested 503 S&P 500 quote pages without a 429.
- A single request returns a ticker’s full price history. With period1=0, MSFT’s historical data tab returned every daily bar since 1986.
- Validate every page, even when it returns 200. FB, Meta’s old symbol, returned a ProShares ETF, and Vodafone’s London price was in pence.
- Move to a server by swapping the fetch function. Bright Data’s Web Unlocker API adds IP rotation and automatic retries. Or Bright Data’s Yahoo Finance Scraper API returns structured records.
Where Yahoo Finance keeps its data
The numbers on a quote page are embedded as JSON inside its HTML. Yahoo renders the pages on the server with SvelteKit, a JavaScript framework, and calls its own JSON APIs during rendering. SvelteKit inlines each response into the HTML, so the browser can reuse it without fetching it again. Each response is in its own script tag, which has a data-sveltekit-fetched attribute and the source API URL in data-url.
A tag from the MSFT summary tab looks like this, with its JSON body shortened:
<script type="application/json" data-sveltekit-fetched
data-url="https://query1.finance.yahoo.com/v1/finance/quoteType/MSFT?formatted=true&enablePrivateCompany=true&overnightPrice=true&lang=en-US&region=US"
data-hash="1ibomen" data-ttl="1800">
{"status":200,"statusText":"","headers":{"cache-control":"public, max-age=1800, stale-while-revalidate=1800"},"body":"{\"quoteType\":{\"result\":[{\"symbol\":\"MSFT\",\"quoteType\":\"EQUITY\",\"exchange\":\"NMS\",\"longName\":\"Microsoft Corporation\"}],\"error\":null}}"}
</script>The body field contains the API response as a JSON string. Parsing a tag needs 2 json.loads() calls. The first call parses the wrapper, and the second call parses the body string. Each tab of a quote page embeds a different set of API responses:
| Tab | Embedded API response | What you can read from it |
|---|---|---|
/quote/MSFT/ |
v10/finance/quoteSummary and v7/finance/spark |
Price, market cap, P/E, dividend, 52-week range, analyst price targets, up to 24 hours of 5-minute closes |
/quote/MSFT/history/ |
v8/finance/chart |
Daily, weekly, or monthly prices, adjusted close, splits, dividends |
/quote/MSFT/financials/, balance-sheet/, cash-flow/ |
ws/fundamentals-timeseries |
Annual and trailing 12-month line items |
/quote/MSFT/analysis/ |
v10/finance/quoteSummary with earningsTrend |
EPS and revenue estimates, analyst counts, earnings surprises |
/quote/MSFT/key-statistics/ |
ws/fundamentals-timeseries |
Quarterly market cap, enterprise value, and valuation ratios |
/quote/MSFT/profile/ |
v10/finance/quoteSummary with assetProfile |
Key executives, employee count, sector, SEC filings |
/quote/MSFT/holders/ |
v10/finance/quoteSummary with ownership modules |
Institutional, fund, and insider holders |
/quote/MSFT/options/ |
v7/finance/options |
The options chain for the nearest expiration, plus the list of expiration dates |
Yahoo’s API hosts, query1.finance.yahoo.com and query2.finance.yahoo.com, serve the same JSON, and the open-source yfinance library calls them directly. On those hosts, the quote, quoteSummary, and options endpoints returned 401 when a request had no crumb. A crumb is a token that Yahoo issues with each session cookie and expects as a crumb= query parameter.
The old CSV download returned 401 User is not logged in. On both API hosts, robots.txt disallows every path (Disallow: /). The responses embedded in the quote page need no cookie, no crumb, and no API-host access:
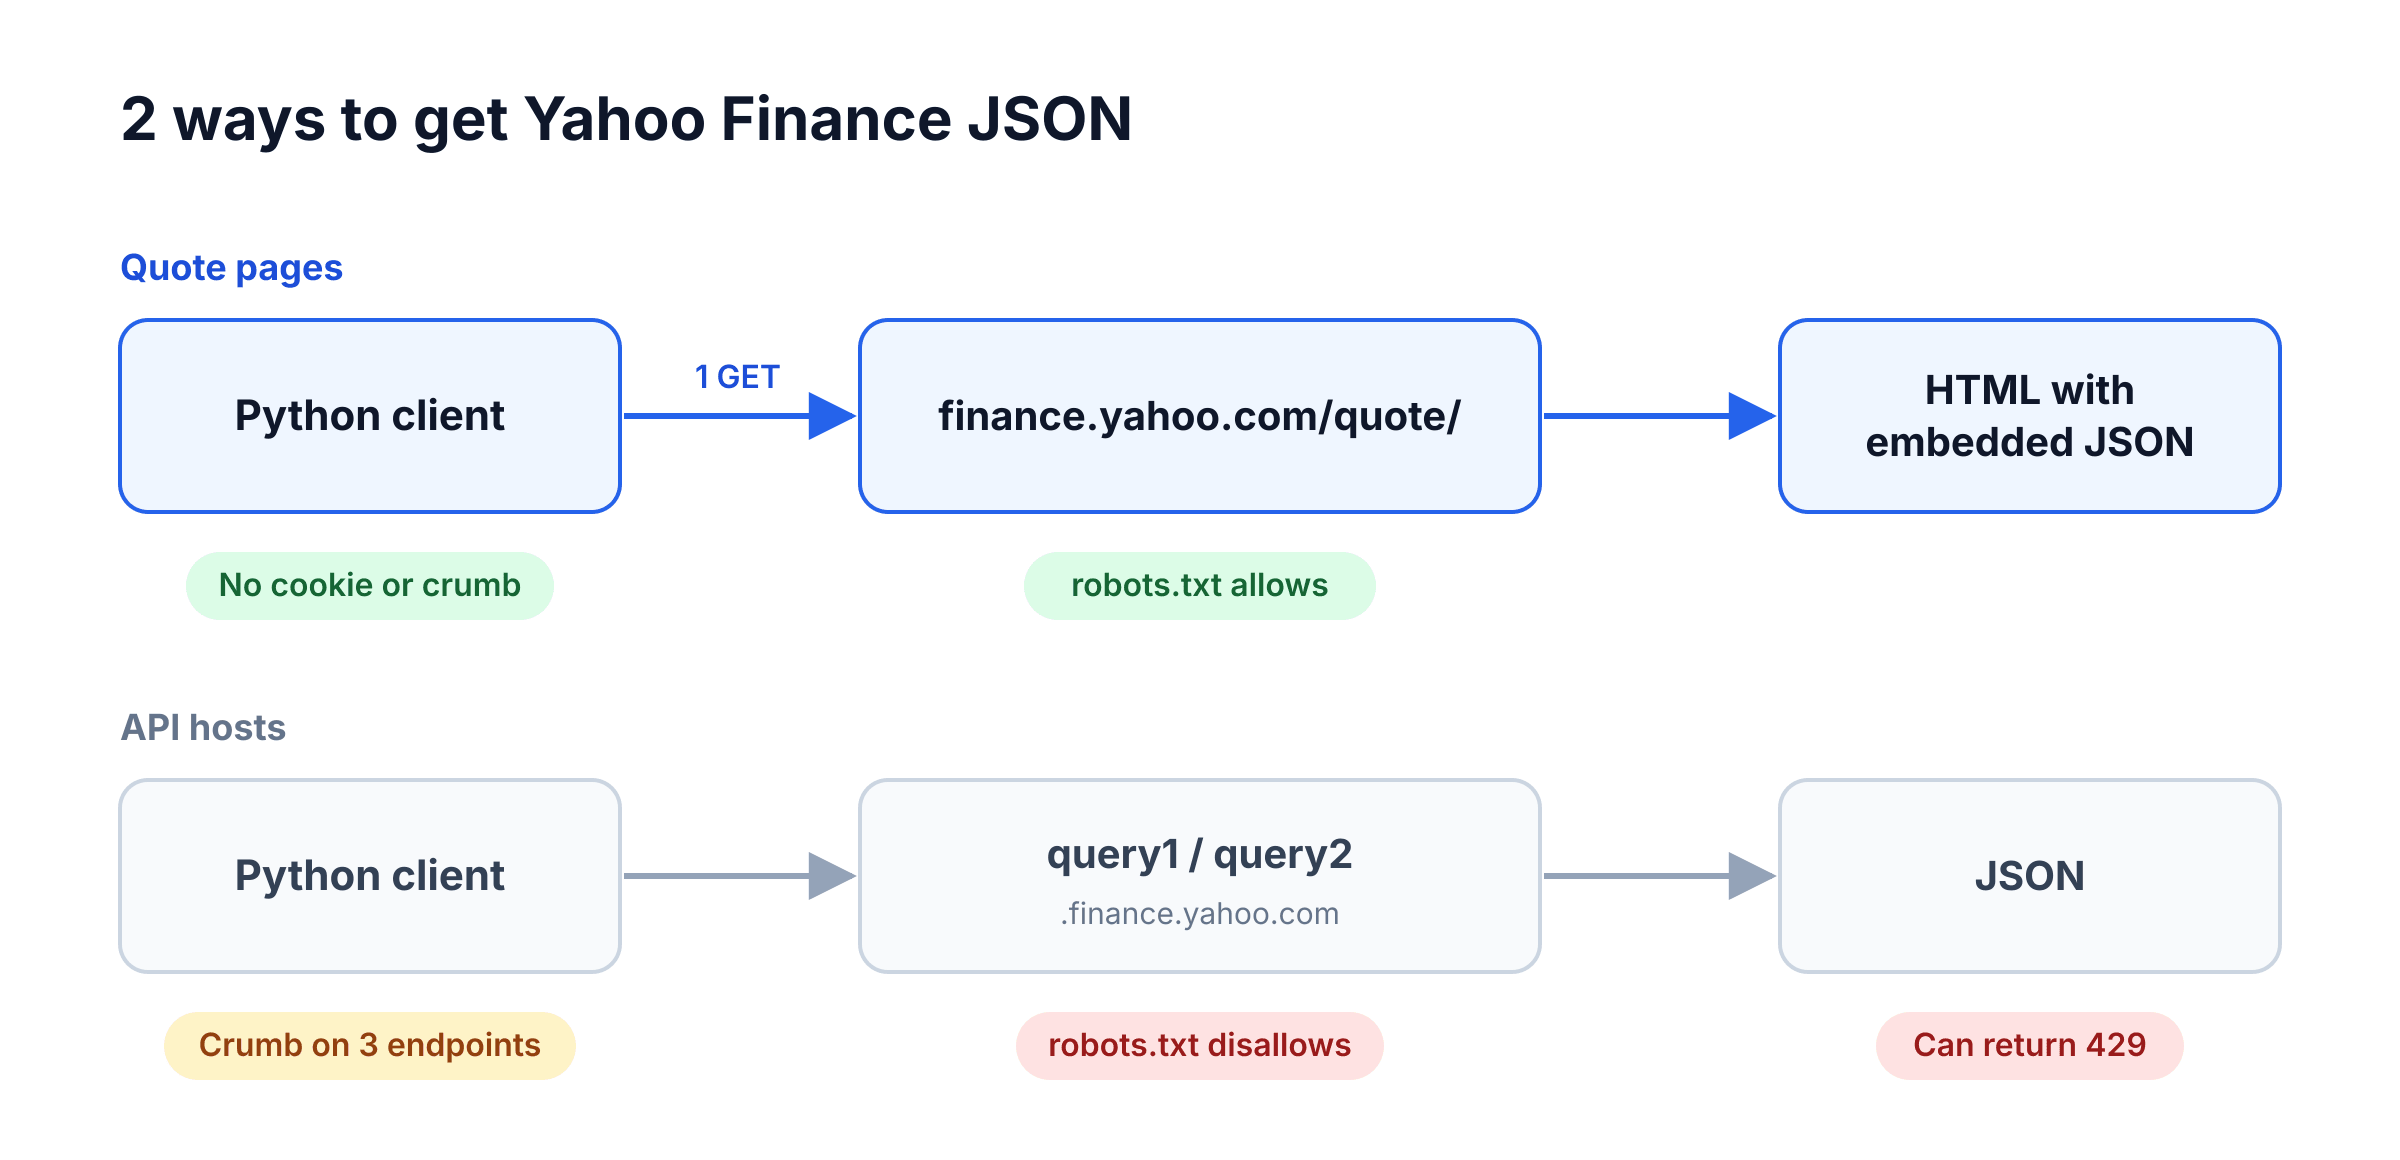
The scripts read only the quote pages, so they never call the API hosts.
Many older tutorials read prices with CSS selectors that no longer work. On the MSFT page, [data-symbol="MSFT"][data-field="regularMarketPrice"] and #quote-summary [data-test="PREV_CLOSE-value"] matched 0 elements. The less specific fin-streamer[data-field="regularMarketPrice"] selector matched 9, and the first match contained the S&P 500’s price from the page’s market summary.
Other tutorials automate a browser. The embedded JSON makes a browser unnecessary for quotes, daily history, annual statements, and estimates, because 1 HTTP request per tab returns the same data.
If you use a browser, read the raw HTML response, because SvelteKit’s client-side code removes each script tag after reading it. In 2 of 4 test page loads, page.content() returned the page without the tags. In 1 of those, the scraper read the page as soon as DOMContentLoaded fired.
Why Yahoo Finance can return 429 on the first request
Yahoo’s responses depended on the client’s User-Agent and TLS handshake, so a client can get a 429 on its first request. The server: ATS header in the responses identifies Apache Traffic Server. With its default settings, Python’s requests library got a 429 on its first request. The 429 responses had 2 forms:
- With the default
python-requests/2.34.2User-Agent, every TLS stack in the table below got a 23-byteEdge: Too Many Requestsresponse. Python’s requests library got the same response onfinance.yahoo.com. - On the API hosts, some browser User-Agents over Python’s TLS stack got a 19-byte
Too Many Requestsresponse.
The table shows how query1, the API host yfinance uses, responded to chart requests sent from 1 residential connection at least 1.5 seconds apart. The curl_cffi library, a Python HTTP client, can impersonate a browser’s TLS handshake. Each row pairs a TLS stack with a User-Agent header:
| TLS stack | User-Agent header | Got 429 |
|---|---|---|
| Python requests (OpenSSL) | python-requests/2.34.2, the default |
5 of 5 |
| Python requests (OpenSSL) | Chrome 140 on macOS | 26 of 26 |
| Python requests (OpenSSL) | Firefox 147 on Windows | 16 of 17 |
| Python requests (OpenSSL) | Safari 26 on macOS | 8 of 11 |
| Python requests (OpenSSL) | Chrome 150 on macOS | 3 of 6 |
| Python requests (OpenSSL) | Chrome 150 on Windows | 0 of 11 |
| Python requests (OpenSSL) | Mozilla/5.0 alone |
0 of 11 |
| curl_cffi (Chrome, Firefox, or Safari handshake) | Chrome 140 or 150, Firefox 147, Safari 26, or Mozilla/5.0 |
0 of 80 |
| curl_cffi (same 3 handshakes) | python-requests/2.34.2 |
15 of 15 |
Why does the TLS handshake matter?
Yahoo’s response depended on the TLS stack, even when the User-Agent was the same. In a controlled test, requests and curl_cffi sent the same User-Agent (Chrome 140 on macOS) and Accept header over HTTP/1.1 from the same IP address. Only the HTTP client and its TLS stack changed. Through Python’s requests library, 0 of 8 requests succeeded, and through curl_cffi’s Chrome TLS stack, 8 of 8 did.
The 2 stacks already differ before any header is sent. A JA4 fingerprint, a common form of TLS fingerprinting, summarizes the ClientHello, the first message a client sends in a TLS handshake. Python’s OpenSSL handshake produced t13d1812h1_85036bcba153_b26ce05bbdd6, and curl_cffi’s chrome target produced t13d1516h2_8daaf6152771_806a8c22fdea, which matches Chrome’s cipher suites. Request https://tls.peet.ws/api/all from your own client to see what it sends.
Each result depended on the combination of TLS stack and User-Agent. The Mozilla/5.0 string alone succeeded 11 of 11 times over Python’s TLS. Chrome 140 on macOS failed 26 of 26 times, and Firefox 147 failed 16 of 17 times. So a realistic browser User-Agent can make Python’s requests library fail more often.
With a browser’s TLS handshake from curl_cffi, the browser User-Agents in the table succeeded on 80 of 80 requests. In a smaller test, finance.yahoo.com itself accepted the Chrome 140 string over Python’s TLS and blocked the default python-requests string. The scraper code uses curl_cffi on finance.yahoo.com too, so the User-Agent and the TLS handshake both match Chrome.
If you send a browser’s User-Agent, send a browser’s TLS handshake with it.
Does the request rate matter?
Not for the 429s on first requests, which depend on the client. At 8 threads, curl_cffi requested all 503 S&P 500 quote pages, then 501 historical data pages, without a 429. That’s the volume of a daily S&P 500 refresh. If a 429 appears at higher volume, the scraper code backs off and retries.
A rate-limiting snippet posted in yfinance’s issue tracker limits traffic to 60 requests a minute, 360 requests an hour, and 8,000 requests a day. Those figures come from the rate-limit page of Yahoo’s DSP Traffic API. Yahoo DSP is a demand-side platform for buying ads, so the snippet uses another product’s limits.
The yfinance library also got 429 errors from Yahoo, which it raised as YFRateLimitError('Too Many Requests. Rate limited. Try after a while.'). After an issue thread about 429 errors received more than 140 comments, yfinance’s maintainers adopted the same fix: a browser’s TLS handshake. Version 0.2.58 (2025) moved the library to curl_cffi, and version 1.7.0 creates its default session with impersonate="chrome".
Does the code work from a cloud server?
Yes, on 3 GitHub Actions runners with Microsoft Azure IP addresses. On each runner, curl_cffi’s first request returned a quote page for each of 20 symbols, from US stocks and ETFs to crypto and foreign listings. In a second run, each runner requested all 503 S&P 500 quote pages without a 429.
The scripts returned the same history, statements, and estimates as they did from home. On the runners, Python’s requests library with its default User-Agent got the same 23-byte 429 response, while yfinance fetched MSFT’s full daily history.
Reported cloud failures involved older clients and shared IP ranges, so test the scripts from your own server before you schedule a job. In 2025, before yfinance moved to curl_cffi, its maintainers removed their GitHub Actions test job after it failed to fetch data from Yahoo. Another developer traced 401 “Invalid Crumb” responses to the shared free-tier IP range of Render, a cloud platform. The same calls worked from a residential IP.
Extract the embedded JSON from a quote page
You need Python 3.11 or later and 5 packages. The code was tested on Python 3.11, 3.13, and 3.14 with curl_cffi 0.16.3, beautifulsoup4 4.15.0, lxml 6.1.3, pandas 3.0.6, and requests 2.34.2. Install them with pip:
pip install curl_cffi beautifulsoup4 lxml pandas requestsFor Python scraping basics, see our guide to web scraping with Python. The core module fetches a single tab, checks that Yahoo returned a quote page, and returns the embedded responses keyed by their API URL. Save it as yahoo_embedded.py, because the scripts that read Yahoo’s pages depend on it:
import json
import random
import threading
import time
from urllib.parse import quote

from bs4 import BeautifulSoup
from curl_cffi import requests

QUOTE_URL = "https://finance.yahoo.com/quote"
_local = threading.local()


class SymbolNotFound(Exception):
    """Yahoo returned its lookup page or a soft 404 instead of a quote page."""


def page_url(symbol: str, tab: str = "") -> str:
    return (
        f"{QUOTE_URL}/{quote(symbol.upper(), safe='')}/{tab}"  # ^GSPC becomes %5EGSPC
    )


def embedded(html: str) -> dict[str, dict]:
    """Map the API URLs the page was rendered from to their JSON bodies."""
    soup = BeautifulSoup(html, "lxml")
    found = {}
    for tag in soup.select('script[type="application/json"][data-sveltekit-fetched]'):
        try:
            wrapper = json.loads(tag.string)
            found[tag["data-url"]] = json.loads(wrapper["body"])
        except (TypeError, KeyError, ValueError):
            continue  # an embedded response whose body isn't JSON
    return found


def pick(found: dict[str, dict], path: str) -> dict:
    """Return the first embedded response whose URL contains `path`."""
    for url, body in found.items():
        if path in url:
            return body
    raise LookupError(f"no embedded response for {path}")


def is_quote_page(html: str, symbol: str) -> bool:
    """True for a quote page, False otherwise, SymbolNotFound for an unknown symbol."""
    found = embedded(html)
    if any("/v1/finance/lookup" in url for url in found):
        raise SymbolNotFound(symbol)
    for url, body in found.items():
        if "/v1/finance/quoteType/" in url:
            result = (body.get("quoteType") or {}).get("result") or [{}]
            if not result[0].get("exchange"):
                # A soft 404, as for BRK.B (Yahoo spells it BRK-B)
                raise SymbolNotFound(symbol)
            return True
    return False


def _session() -> requests.Session:
    # One Chrome-impersonating session per thread, as curl_cffi recommends.
    if not hasattr(_local, "session"):
        _local.session = requests.Session(impersonate="chrome")
    return _local.session


def fetch_page(
    symbol: str, tab: str = "", params: dict | None = None, attempts: int = 4
) -> str:
    """Return the HTML of a quote page, for example tab="history/"."""
    for attempt in range(attempts):
        if attempt:
            time.sleep(2**attempt + random.random())  # back off before each retry
        try:
            response = _session().get(
                page_url(symbol, tab), params=params, timeout=30, allow_redirects=False
            )
        except requests.RequestException:
            continue  # timeout or dropped connection
        if response.is_redirect:
            location = response.headers.get("location", "")
            if "/lookup" in location:
                raise SymbolNotFound(symbol)
            # For example, a tab that doesn't exist
            raise LookupError(f"{symbol} {tab}: Yahoo redirected to {location}")
        if response.status_code == 200 and is_quote_page(response.text, symbol):
            return response.text
        if 400 <= response.status_code < 500 and response.status_code != 429:
            response.raise_for_status()
    # Every attempt timed out or got a 429, a 5xx, or a page without quote data
    raise RuntimeError(f"{symbol} {tab}: no quote data after {attempts} attempts")


if __name__ == "__main__":
    from urllib.parse import urlsplit

    found = embedded(fetch_page("MSFT"))
    print(len(found), "embedded responses")
    for url in found:
        if url.startswith("https://"):
            print(urlsplit(url).netloc, urlsplit(url).path)
The module handles 3 edge cases:
allow_redirects=Falsestops the client at a redirect instead of following it. A 302 to/lookup/means an unknown symbol, so the module raisesSymbolNotFound. It doesn’t fetch the lookup page, which robots.txt disallows. Any other redirect, such as a tab that an ETF doesn’t have, raisesLookupErroron the first attempt.is_quote_page()checks for thequoteTyperesponse, because a 200 status alone doesn’t prove that the page has data. All 11 MSFT tabs embedded it, includingnews/. AquoteTypewithout an exchange means a soft 404, a page with status 200 but no quote data. Yahoo returned that kind of page forBRK.B, because it spells the symbolBRK-B.quote(symbol.upper(), safe='')uppercases the symbol and percent-encodes index symbols such as^GSPC, because^isn’t a valid URL character until it’s encoded.
For MSFT, the module lists the Yahoo APIs the page calls:
23 embedded responses
query1.finance.yahoo.com /ws/obi-integration/v1/premiumTiersMeta
query1.finance.yahoo.com /v1/finance/quoteType/MSFT
query1.finance.yahoo.com /v7/finance/spark
query1.finance.yahoo.com /v6/finance/quote/marketSummary
query1.finance.yahoo.com /v7/finance/quote
query1.finance.yahoo.com /v7/finance/quote
query1.finance.yahoo.com /v6/finance/recommendationsbysymbol/MSFT
query1.finance.yahoo.com /v6/finance/markettime
query1.finance.yahoo.com /v7/finance/spark
query1.finance.yahoo.com /v10/finance/quoteSummary/MSFT
query1.finance.yahoo.com /v1/finance/trending/US
query1.finance.yahoo.com /v7/finance/quote
query1.finance.yahoo.com /v1/finance/screener/predefined/saved
The summary tab’s statistics come from v10/finance/quoteSummary, which contained about 223 KB of JSON across 17 modules for MSFT. The listing shows the 13 absolute API URLs, and the other 10 responses came from Yahoo’s own /xhr/ endpoints. Most of the 23 provide data for page widgets such as trending tickers and market summaries. The count varies: from US cloud runners, the same page embedded 26 responses, and the extra ones included price-insights.
Parse price, valuation, and rating fields
Many numbers inside quoteSummary are {"raw": 516.17, "fmt": "516.17"} pairs, so a helper keeps the raw value. This function returns 20 quote fields. Save it as quote_summary.py, because the estimates and batch scripts reuse it:
import json

from yahoo_embedded import embedded, fetch_page, pick


def raw(module: dict, key: str):
    """Many numbers are {"raw": 516.17, "fmt": "516.17"} pairs. Keep the raw value."""
    value = module.get(key)
    return value.get("raw") if isinstance(value, dict) else value


def quote_summary(symbol: str, fetch=fetch_page) -> dict:
    found = embedded(fetch(symbol))
    result = pick(found, "/v10/finance/quoteSummary/")["quoteSummary"]["result"][0]
    price = result.get("price", {})
    detail = result.get("summaryDetail", {})
    stats = result.get("defaultKeyStatistics", {})
    analysts = result.get("financialData", {})
    return {
        "symbol": price.get("symbol"),
        "name": price.get("longName") or price.get("shortName"),
        "quote_type": price.get("quoteType"),
        "currency": price.get("currency"),
        "price": raw(price, "regularMarketPrice"),
        "change_pct": raw(price, "regularMarketChangePercent"),
        "market_time": raw(price, "regularMarketTime"),
        "market_state": price.get("marketState"),
        "delay_minutes": price.get("exchangeDataDelayedBy"),
        "market_cap": raw(price, "marketCap"),
        "trailing_pe": raw(detail, "trailingPE"),
        "forward_pe": raw(detail, "forwardPE"),
        "dividend_yield": raw(detail, "dividendYield"),
        "beta": raw(detail, "beta"),
        "week52_low": raw(detail, "fiftyTwoWeekLow"),
        "week52_high": raw(detail, "fiftyTwoWeekHigh"),
        "eps_ttm": raw(stats, "trailingEps"),
        "target_mean": raw(analysts, "targetMeanPrice"),
        "recommendation": analysts.get("recommendationKey"),
        "reporting_currency": analysts.get("financialCurrency"),
    }


if __name__ == "__main__":
    print(json.dumps(quote_summary("MSFT"), indent=2))
For MSFT, the function printed raw values for all 20 fields after a market close:
{
  "symbol": "MSFT",
  "name": "Microsoft Corporation",
  "quote_type": "EQUITY",
  "currency": "USD",
  "price": 516.17,
  "change_pct": 0.0366316,
  "market_time": 1790366401,
  "market_state": "CLOSED",
  "delay_minutes": 0,
  "market_cap": 3832843862016,
  "trailing_pe": 28.739979,
  "forward_pe": 21.801512,
  "dividend_yield": 0.0076,
  "beta": 1.108,
  "week52_low": 349.2,
  "week52_high": 553.72,
  "eps_ttm": 17.96,
  "target_mean": 577.26135,
  "recommendation": "strong_buy",
  "reporting_currency": "USD"
}
The summary tab showed the same numbers formatted, such as a 3.833T market cap, a 28.74 P/E, and a 0.76% dividend yield:
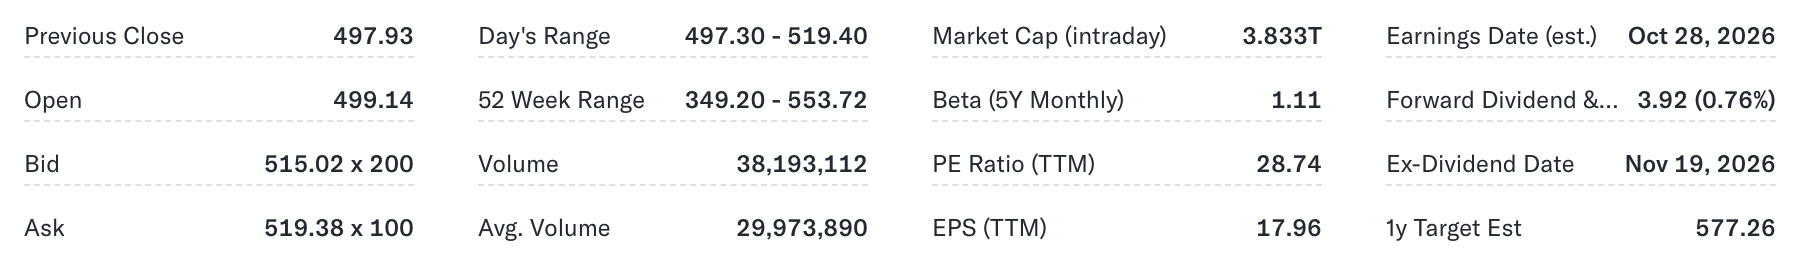
The JSON contains the raw values instead, such as 3832843862016 for the 3.833T market cap.
In the raw values, percentages are fractions, so a change_pct of 0.0366316 is a 3.66% move, and a dividend_yield of 0.0076 is 0.76%. The function reads every module with .get() because the embedded modules differ by asset type. SPY, ^GSPC, BTC-USD, and EURUSD=X all returned prices without the financialData module, so their analyst fields were None. SPY included fundProfile and topHoldings instead.
Download the full price history in 1 request
The historical data tab (history/) passes the period1, period2, and frequency parameters from its own URL to the chart request it embeds. Both period parameters are Unix timestamps, so a period1 of 0 asks for every bar since January 1, 1970. The date picker then starts on that date, and frequency=1d shows daily rows:
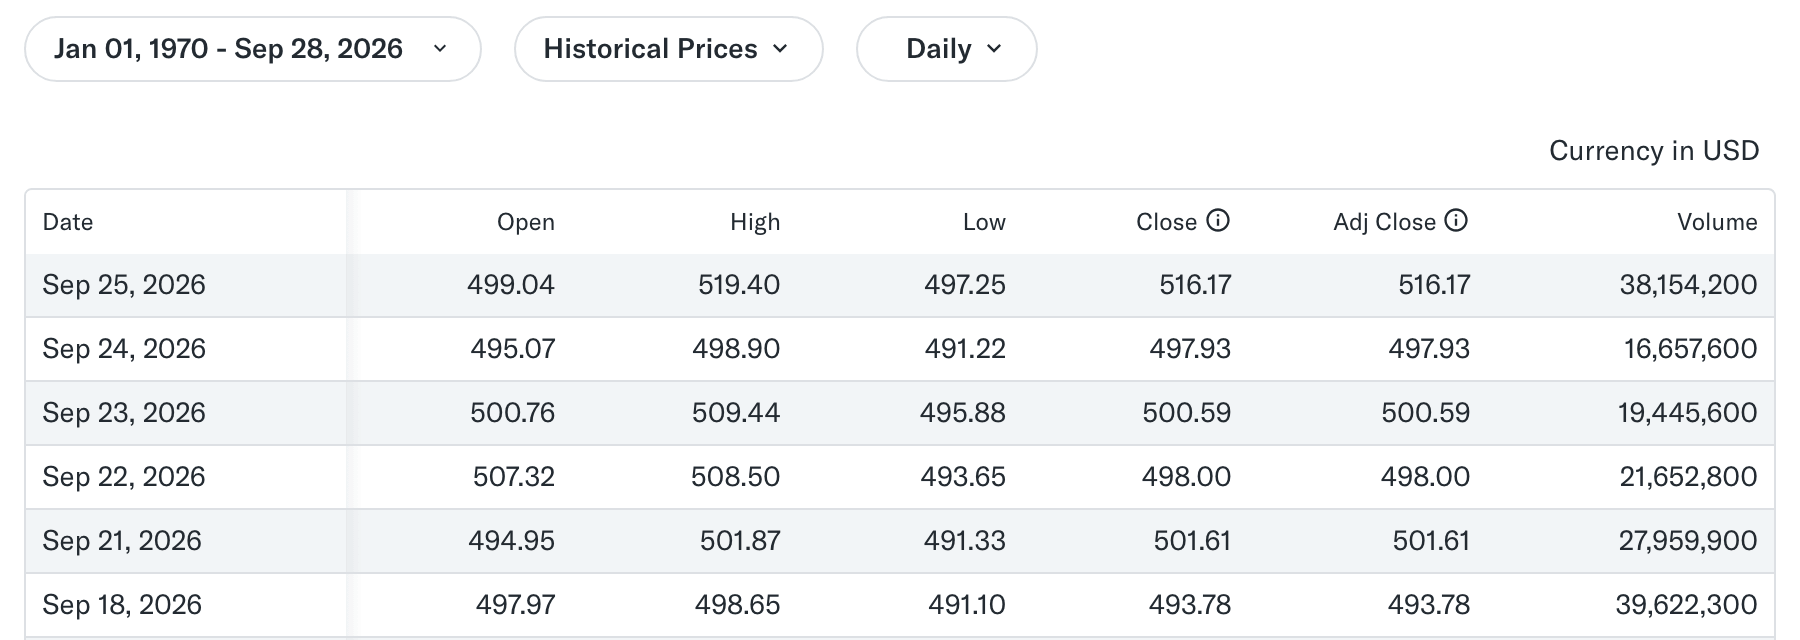
The table’s newest row matches the last row that price_history() prints below.
The price_history() function converts the embedded chart response into a DataFrame indexed by dates in the exchange’s time zone. Save it as price_history.py:
import time

import pandas as pd

from yahoo_embedded import embedded, fetch_page, pick


def price_history(
    symbol: str, frequency: str = "1d", fetch=fetch_page
) -> tuple[pd.DataFrame, dict]:
    """Every bar since 1970 at 1d, 1wk or 1mo, plus split and dividend events."""
    params = {"period1": 0, "period2": int(time.time()), "frequency": frequency}
    found = embedded(fetch(symbol, "history/", params))
    result = pick(found, "/v8/finance/chart/")["chart"]["result"][0]
    bars, meta = result["indicators"]["quote"][0], result["meta"]
    utc = pd.to_datetime(result["timestamp"], unit="s", utc=True)
    index = utc.tz_convert(meta["exchangeTimezoneName"]).tz_localize(None).normalize()
    frame = pd.DataFrame(
        {
            "open": bars["open"],
            "high": bars["high"],
            "low": bars["low"],
            "close": bars["close"],
            "adj_close": result["indicators"]["adjclose"][0]["adjclose"],
            "volume": bars["volume"],
        },
        index=index,
    )
    if frequency != "1d" and result["timestamp"][-1] == meta.get("regularMarketTime"):
        frame = frame.iloc[:-1]  # Yahoo appends the latest session as an extra bar
    return frame.dropna(how="all"), result.get("events", {})


if __name__ == "__main__":
    history, events = price_history("MSFT")
    print(history.tail(3).round(2).to_string())
    print(
        f"{len(history):,} daily bars from {history.index[0]:%Y-%m-%d} "
        f"to {history.index[-1]:%Y-%m-%d}"
    )
    splits = sorted(
        pd.Timestamp(s["date"], unit="s").date()
        for s in events.get("splits", {}).values()
    )
    if splits:
        print(f"{len(splits)} splits, the last one on {splits[-1]}")
A single request returned MSFT’s full history:
              open    high     low   close  adj_close    volume
2026-09-23  500.76  509.44  495.88  500.59     500.59  19445600
2026-09-24  495.07  498.90  491.22  497.93     497.93  16657600
2026-09-25  499.04  519.40  497.25  516.17     516.17  38154200
10,213 daily bars from 1986-03-13 to 2026-09-25
9 splits, the last one on 2003-02-18
Through the API host, yfinance returned the same 10,213 bars for that range. Handle these 5 details in a history pipeline:
- In the tests, history started no earlier than 1970. Yahoo’s help page on historical data says prices usually don’t start earlier than that. Coca-Cola has traded since 1919, but its full history started on 1970-01-02. A negative
period1returned 404. frequencysupports1d,1wk, and1mo. At1wkand1mo, Yahoo appended the last session as an extra bar, and the function drops it. With that bar removed, the final weekly or monthly bar can exclude the last trading session, so take recent closes from daily bars.- Intraday values such as
1h,5m, and1mreturned daily bars instead. The summary tab embeds up to 24 hours of 5-minute closes from/v7/finance/spark. It also embeds a second spark response for the market summary, so pick the response whosesymbolsparameter matches your ticker. The quote pages contain only those 24 hours of intraday data, because longer intraday history comes from the API hosts, which robots.txt disallows. - Yahoo adjusts
closefor splits andadj_closefor splits and dividends. Old bars change after every new split or dividend, so store the split and dividend events with each download. - The page size grows with the date range. With the full date range, MSFT’s historical data tab was 4.9 MB of HTML, and the summary tab was about 1.1 MB. For a daily refresh, set
period1to a recent timestamp, and download the full range again after each new split or dividend.
Fetch financial statements and analyst estimates
Statements and estimates are on different tabs, so each gets its own function.
Get annual financial statements
Financial statements come from the fundamentals-timeseries response on the financials, balance sheet, and cash flow tabs. On MSFT’s financials tab, that response contained 96 annual series and 96 trailing 12-month series. statement() keeps the annual series and pivots them into a table with 1 column per fiscal year. Save it as statements.py:
import pandas as pd

from yahoo_embedded import embedded, fetch_page, pick


def statement(symbol: str, tab: str = "financials/", fetch=fetch_page) -> pd.DataFrame:
    """Annual line items from the financials/, balance-sheet/ or cash-flow/ tab."""
    found = embedded(fetch(symbol, tab))
    series = pick(found, "/fundamentals-timeseries/")["timeseries"]["result"]
    rows = []
    for item in series:
        name = item["meta"]["type"][0]  # for example "annualTotalRevenue"
        if not name.startswith("annual"):
            continue  # skip non-annual series, such as trailing 12 months
        for point in item.get(name) or []:
            if point:
                rows.append(
                    {
                        "line_item": name.removeprefix("annual"),
                        "fiscal_year_end": point["asOfDate"],
                        "value": point["reportedValue"]["raw"],
                    }
                )
    table = pd.DataFrame(rows).pivot(
        index="line_item", columns="fiscal_year_end", values="value"
    )
    return table.sort_index(axis=1)


if __name__ == "__main__":
    income = statement("MSFT")
    billions = (
        income.loc[["TotalRevenue", "GrossProfit", "OperatingIncome", "NetIncome"]].T
        / 1e9
    )
    billions["DilutedEPS"] = income.loc["DilutedEPS"]
    print(billions.round(2).to_string())
    print(f"{len(income)} line items")
The script printed 4 fiscal years of the income statement, in billions of dollars except for EPS:
line_item        TotalRevenue  GrossProfit  OperatingIncome  NetIncome  DilutedEPS
fiscal_year_end
2023-06-30             211.92       146.05            88.52      72.36        9.68
2024-06-30             245.12       171.01           109.43      88.14       11.80
2025-06-30             281.72       193.89           128.53     101.83       13.64
2026-06-30             331.84       225.46           155.24     133.75       17.95
47 line items
On the financials tab, Yahoo shows the same figures in thousands, so the 331.84B revenue in the output appears as 331,839,000:
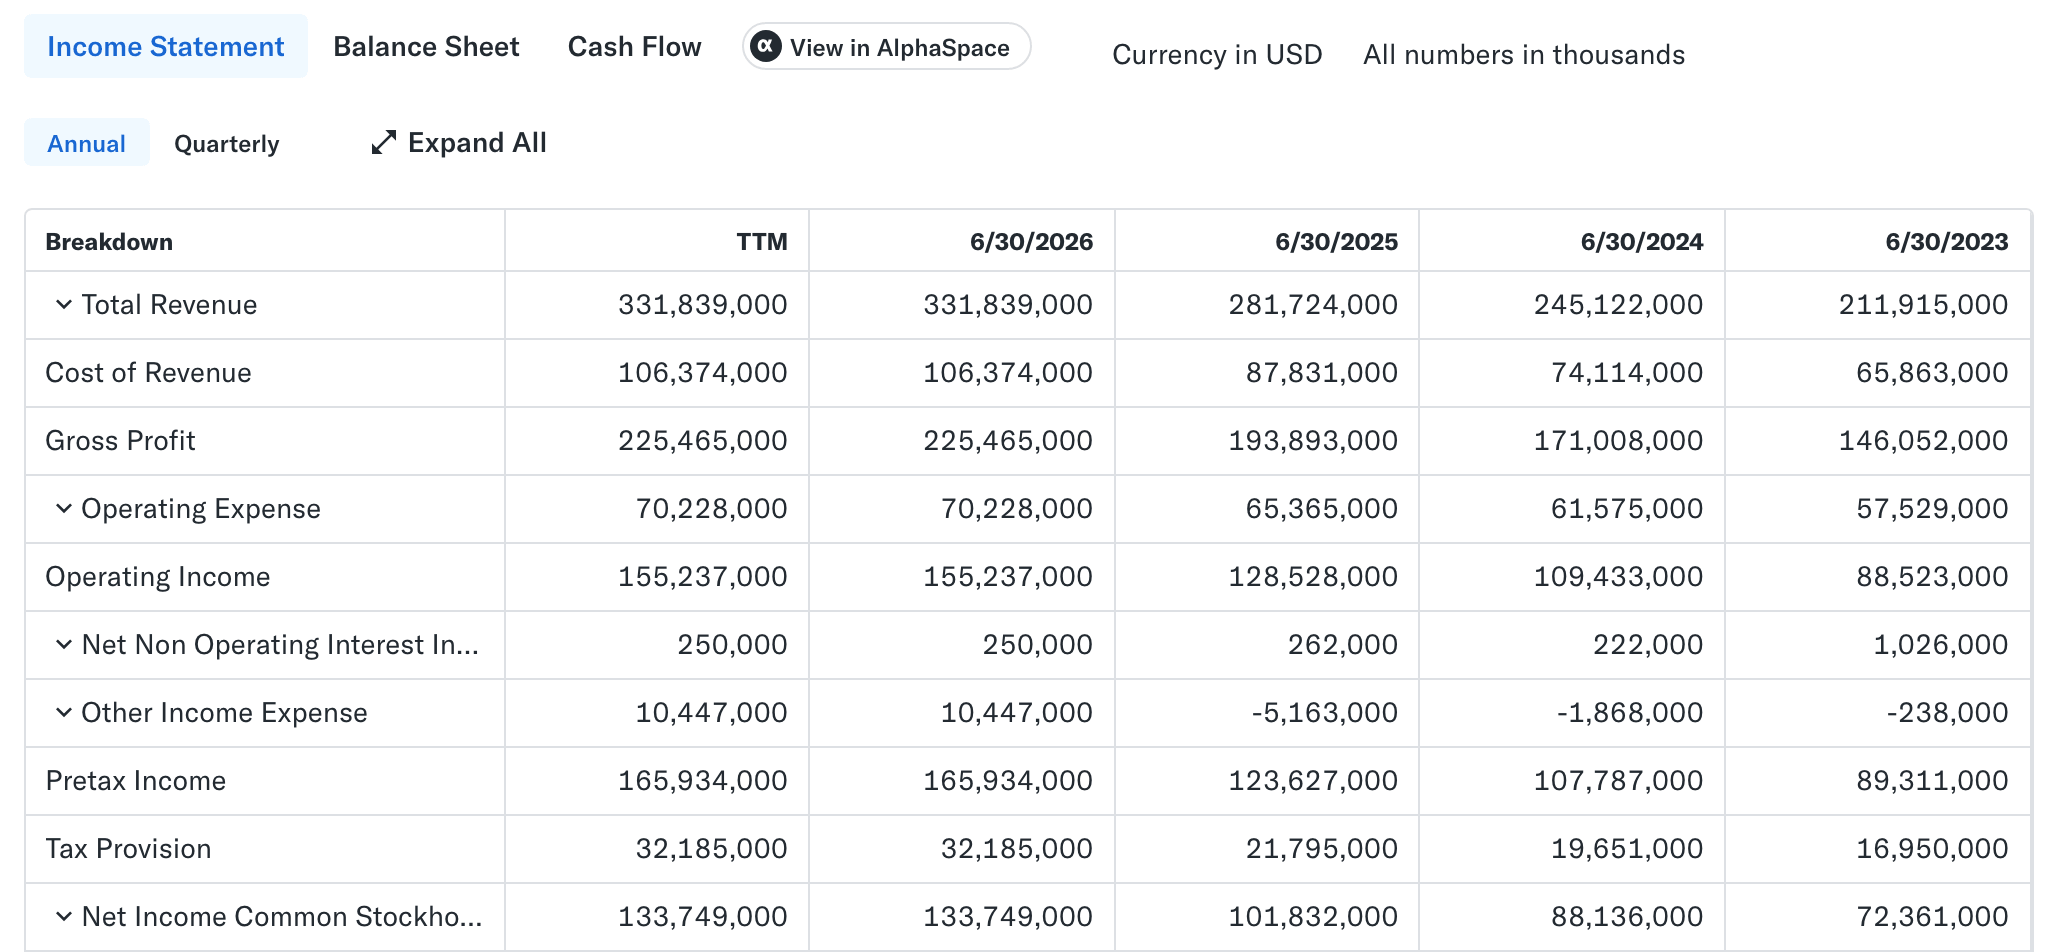
The Income Statement, Balance Sheet, and Cash Flow views are the financials/, balance-sheet/, and cash-flow/ tabs that statement() reads.
For MSFT, 47 of the 96 annual series had values. The empty series were line items such as insurance claims, preferred dividends, and excise taxes. For those 4 years, the function returned 79 line items from balance-sheet/ and 59 line items from cash-flow/. Quarterly statements load only after you select the Quarterly toggle, and no tested URL parameter changed that.
Skip the incomeStatementHistory and balanceSheetHistory modules in quoteSummary. Their income rows had actual values only for total revenue and net income, in both the annual and quarterly versions. The balance-sheet rows had only dates. Other income fields contained 0 as a placeholder, so a parser that trusts them would store a gross profit of 0.
Get analyst estimates
The analysis tab embeds earningsTrend, which contains consensus EPS and revenue for the current quarter, the next quarter, the current year, and the next year. estimates() flattens it into 1 row per period. Save it as estimates.py:
import pandas as pd

from quote_summary import raw
from yahoo_embedded import embedded, fetch_page, pick


def estimates(symbol: str, fetch=fetch_page) -> pd.DataFrame:
    """Consensus EPS and revenue for the current and next quarter and year."""
    found = embedded(fetch(symbol, "analysis/"))
    result = pick(found, "/v10/finance/quoteSummary/")["quoteSummary"]["result"][0]
    rows = []
    for period in result["earningsTrend"]["trend"]:
        eps, revenue = period["earningsEstimate"], period["revenueEstimate"]
        revenue_avg = raw(revenue, "avg")
        rows.append(
            {
                "period": period["period"],  # 0q, +1q, 0y, +1y
                "ends": period["endDate"],
                "eps_avg": raw(eps, "avg"),
                "eps_low": raw(eps, "low"),
                "eps_high": raw(eps, "high"),
                "eps_analysts": raw(eps, "numberOfAnalysts"),
                "revenue_avg_bn": None if revenue_avg is None else revenue_avg / 1e9,
                "revenue_analysts": raw(revenue, "numberOfAnalysts"),
            }
        )
    return pd.DataFrame(rows).set_index("period")


if __name__ == "__main__":
    print(estimates("MSFT").round(2).to_string())
For MSFT, each estimate came from 25 to 51 analysts:
              ends  eps_avg  eps_low  eps_high  eps_analysts  revenue_avg_bn  revenue_analysts
period
0q      2026-09-30     4.72     4.43      4.83            25           90.66                38
+1q     2026-12-31     4.82     4.72      5.02            25           95.49                37
0y      2027-06-30    19.76    19.21     20.70            33          391.04                50
+1y     2028-06-30    23.68    22.08     26.00            32          467.27                51
On the analysis tab, the Earnings Estimate table shows the same EPS figures. Its Current Qtr., Next Qtr., Current Year, and Next Year columns match the 0q, +1q, 0y, and +1y rows:
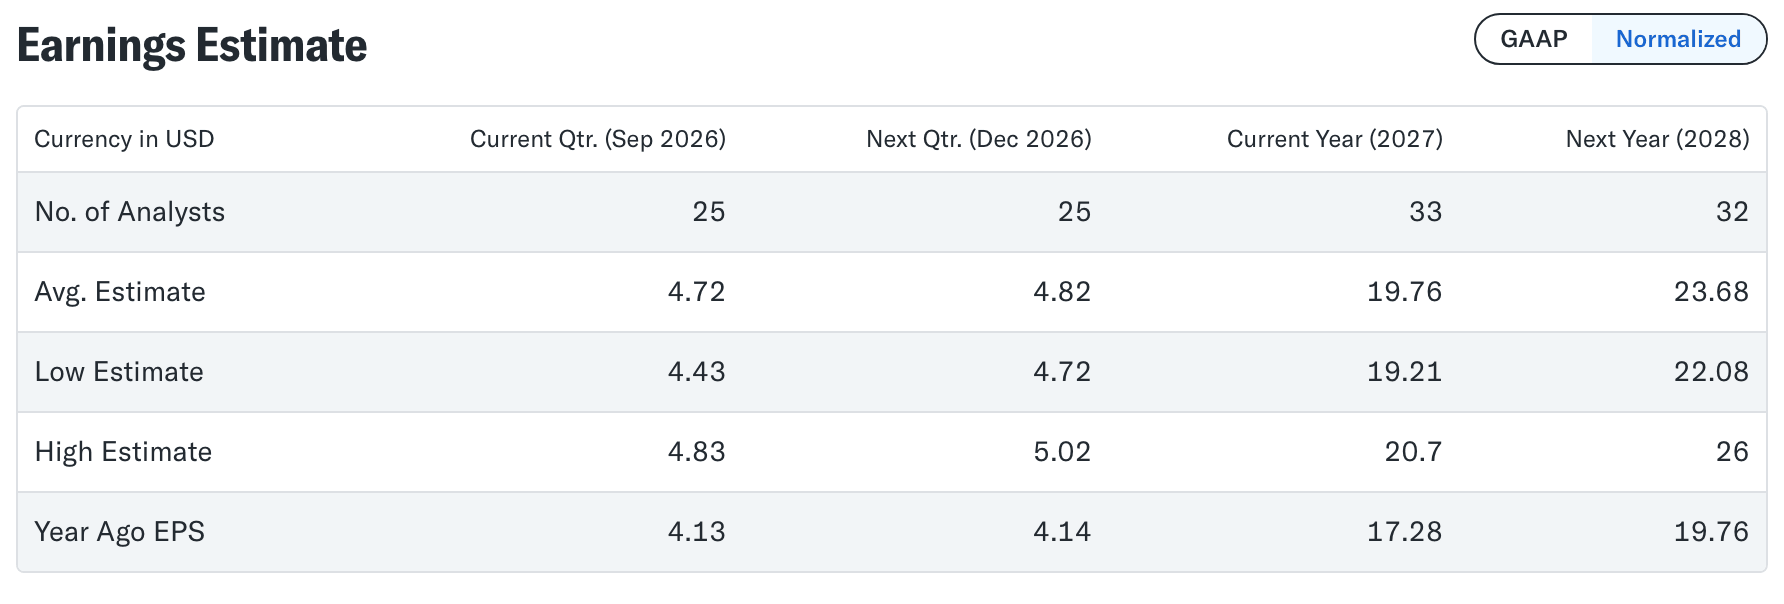
The table’s Normalized view shows the same numbers that earningsTrend contains.
The same request also returns epsTrend and epsRevisions for each period, and earningsHistory with the last 4 reported quarters and their surprise percentages.
Scrape Yahoo Finance for hundreds of tickers
Many production ticker lists include old symbols, indices, and foreign listings, so your batch script has to report problems and continue. Save the next script as batch.py. It runs 8 threads by default, collects missing and failed symbols separately, and converts minor currency units:
from concurrent.futures import ThreadPoolExecutor

import pandas as pd

from quote_summary import quote_summary
from yahoo_embedded import SymbolNotFound, fetch_page

# Yahoo quotes many London, Johannesburg, and Tel Aviv prices in minor units.
# Market cap stays in major units.
MINOR_UNITS = {"GBp": ("GBP", 100), "ZAc": ("ZAR", 100), "ILA": ("ILS", 100)}
PRICE_FIELDS = ("price", "week52_low", "week52_high", "target_mean")


def to_major_units(row: dict) -> dict:
    unit = MINOR_UNITS.get(row["currency"])
    if unit is None:
        return row
    currency, divisor = unit
    prices = {key: row[key] / divisor for key in PRICE_FIELDS if row[key] is not None}
    return {**row, **prices, "currency": currency}


def collect(symbols: list[str], fetch=fetch_page, workers: int = 8):
    """Quote rows for many symbols, plus the symbols that were missing or failed."""
    # " msft" and "MSFT" are the same ticker
    symbols = list(dict.fromkeys(s.strip().upper() for s in symbols))
    missing, failed = [], {}

    def one(symbol: str) -> dict | None:
        try:
            return to_major_units(quote_summary(symbol, fetch=fetch))
        except SymbolNotFound:
            missing.append(symbol)
        except Exception as error:  # keep the batch running, report at the end
            failed[symbol] = repr(error)
        return None

    with ThreadPoolExecutor(max_workers=workers) as pool:
        rows = [row for row in pool.map(one, symbols) if row]
    return pd.DataFrame(rows), missing, failed


if __name__ == "__main__":
    tickers = "AAPL MSFT SQ ^GSPC SPY BTC-USD 7203.T SAP.DE VOD.L NPN.JO".split()
    table, missing, failed = collect(tickers)
    cols = "symbol price currency market_cap delay_minutes reporting_currency".split()
    print(table[cols].to_string(index=False))
    print("missing:", missing, "| failed:", failed)
A mixed list of 10 symbols finished in 2.5 seconds:
 symbol     price currency   market_cap  delay_minutes reporting_currency
   AAPL   341.070      USD 4.977637e+12              0                USD
   MSFT   516.170      USD 3.832844e+12              0                USD
  ^GSPC  7743.410      USD          NaN              0                NaN
    SPY   771.350      USD          NaN              0                NaN
BTC-USD 85011.320      USD 1.707212e+12              0                NaN
 7203.T  2989.500      JPY 3.540116e+13             20                JPY
 SAP.DE   185.920      EUR 2.145897e+11             15                EUR
  VOD.L     1.258      GBP 2.907280e+10             15                EUR
 NPN.JO   709.380      ZAR 5.307029e+11             15                USD
missing: ['SQ'] | failed: {}
The batch reported SQ as missing because Block, Inc. changed its symbol to XYZ. Yahoo redirects the old symbol to its lookup page, but a reused symbol fails silently. FB, Meta’s old symbol, returned a ProShares ETF with status 200, so compare each name with your ticker list. The FB quote page looks like any other quote page:
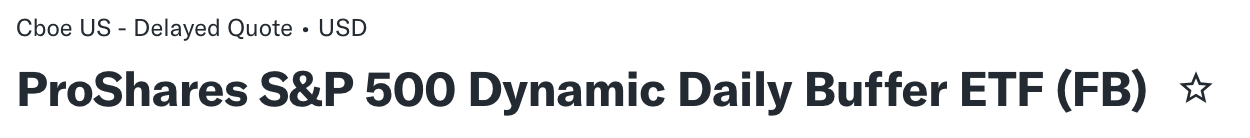
A reused symbol returns a normal quote page, so the name is the clearest sign of the change.
Check units, currencies, and delays
A status-code check won’t detect 3 more problems:
- Minor currency units. Yahoo reported VOD.L’s price as 125.8 in
GBp(pence) and its market cap as 29.07B in pounds. NPN.JO’s price was 70,938 inZAc(cents).to_major_units()divides only the price fields, so market cap keeps its major units. - Reporting currency. Statement values use the company’s reporting currency, and the time-series data points include that currency in a
currencyCodefield. Vodafone (VOD.L) trades in pence but reports in euros, and Naspers (NPN.JO) trades in rand but reports in US dollars. Ratios can mix the 2 currencies. TEVA.TA’s forward P/E was 43.5, while TEVA, its New York listing, had 12.9. Yahoo had divided TEVA.TA’s shekel price by a dollar EPS estimate. - Exchange delay.
delay_minuteswas 0 for the US listings and Bitcoin. The Xetra, London, and Johannesburg quotes had a 15-minute delay, and the Tokyo quote had a 20-minute delay. Keepdelay_minutesandmarket_timewith every row before you compare prices across exchanges.
Run larger batches
With its default 8 threads, collect() processed all 503 S&P 500 symbols in 74 seconds from the residential connection without a 429 or a retry. Only BRK.B and BF.B were missing, because Wikipedia’s S&P 500 list spells them with dots and Yahoo uses BRK-B and BF-B. With period1 set to 7 days ago, all 501 histories refreshed in 48 seconds. The median page was under 1 MB, compared with 4.9 MB for MSFT’s full history.
With exponential backoff, fetch_page() already retries timeouts, 429s, 5xx responses, and pages without quote data. Our guide to retrying failed requests in Python explains backoff with urllib3’s Retry and Tenacity.
If you move to asyncio, check your client’s limit on response-header size first. The response for the MSFT summary tab had about 37 KB of headers, including an 8,765-byte Content-Security-Policy and a 27,039-byte Link header. With default settings, aiohttp 3.14.3 raised a ClientResponseError on a page that Yahoo had served with status 200. Its message began 400, message='Got more than 8190 bytes when reading.
Passing max_field_size=65536 to aiohttp.ClientSession fixed the error. Both httpx and curl_cffi’s AsyncSession handled the page with default settings. Our comparison of requests, httpx, and aiohttp explains the other trade-offs between them.
Run the same parser from a server with Web Unlocker API
Our Web Unlocker API takes a URL and returns the page. It handles IP rotation, CAPTCHA solving, and automatic retries on our servers, so the same parser runs from your server while we maintain the unblocking. fetch_page_unlocker() takes the same symbol, tab, and params arguments as fetch_page(), so quote_summary(), price_history(), statement(), and estimates() all accept it through their fetch parameter. Save it as unlocker.py:
import os
from urllib.parse import urlencode

import requests

from yahoo_embedded import page_url

API_URL = "https://api.brightdata.com/request"


def fetch_page_unlocker(symbol: str, tab: str = "", params: dict | None = None) -> str:
    """Takes the same symbol, tab, and params as fetch_page(), via Web Unlocker API."""
    url = page_url(symbol, tab) + (f"?{urlencode(params)}" if params else "")
    response = requests.post(
        API_URL,
        headers={"Authorization": f"Bearer {os.environ['BRIGHTDATA_API_KEY']}"},
        json={
            "zone": os.environ["BRIGHTDATA_UNLOCKER_ZONE"],
            "url": url,
            "format": "json",  # Yahoo's status, headers, and HTML, wrapped in JSON
            "country": "us",
        },
        timeout=120,
    )
    response.raise_for_status()
    return response.json()["body"]
It reads your API key and your Web Unlocker API zone name from 2 environment variables. A zone is a named product configuration in your account. You’ll find the key on the account settings page and the steps to create a zone in the Web Unlocker API quickstart. Once the zone exists, its Overview tab shows both values:
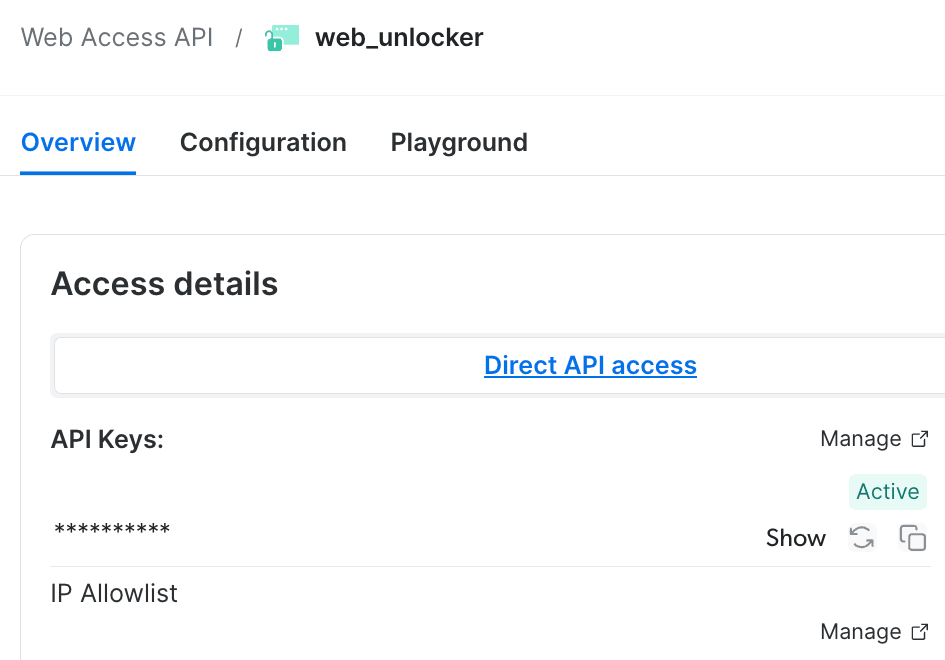
The zone name, here web_unlocker, is at the top, and the copy button under API Keys copies your key.
Set both in your shell before you run the next script:
export BRIGHTDATA_API_KEY="your-api-key"
export BRIGHTDATA_UNLOCKER_ZONE="your-zone-name"
To route quote_summary(), price_history(), statement(), or estimates() through Web Unlocker API, pass fetch_page_unlocker as the fetch argument. Save this script as unlocker_demo.py:
from price_history import price_history
from unlocker import fetch_page_unlocker

history, events = price_history("MSFT", fetch=fetch_page_unlocker)
print(
    f"{len(history):,} daily bars from {history.index[0]:%Y-%m-%d} "
    f"to {history.index[-1]:%Y-%m-%d}"
)
It printed the same history as price_history.py did:
10,213 daily bars from 1986-03-13 to 2026-09-25A single request returned the full historical data page, and the parser needed no changes to read it. The batch script accepts the same function through collect(tickers, fetch=fetch_page_unlocker).
Note these 3 details:
- Use
"format": "json". The response then contains Yahoo’s status code, headers, and full HTML in a single JSON object. The function returns the HTML from itsbodyfield. - Encode special characters.
page_url()already percent-encodes index symbols such as^GSPCas%5EGSPC, so every URL it builds is valid. - Or use our Python SDK. Install
brightdata-sdkwithpip install brightdata-sdk, and passresponse_format="json"toscrape_url()to get Yahoo’s status code with the page.
Each tab is a separate request, and you pay only for successful requests.
Get structured records from the Yahoo Finance Scraper API
Our Yahoo Finance Scraper API returns a structured record per ticker, and proxies, unblocking, and retries are built in. It’s a pre-built scraper in our Web Scraper API. A record combines the summary fields, company profile, key executives, annual financials, and analyst price targets, which the scraper’s product page lists field by field. The Control Panel shows the scraper’s synchronous and asynchronous modes and the endpoint that the code below calls:
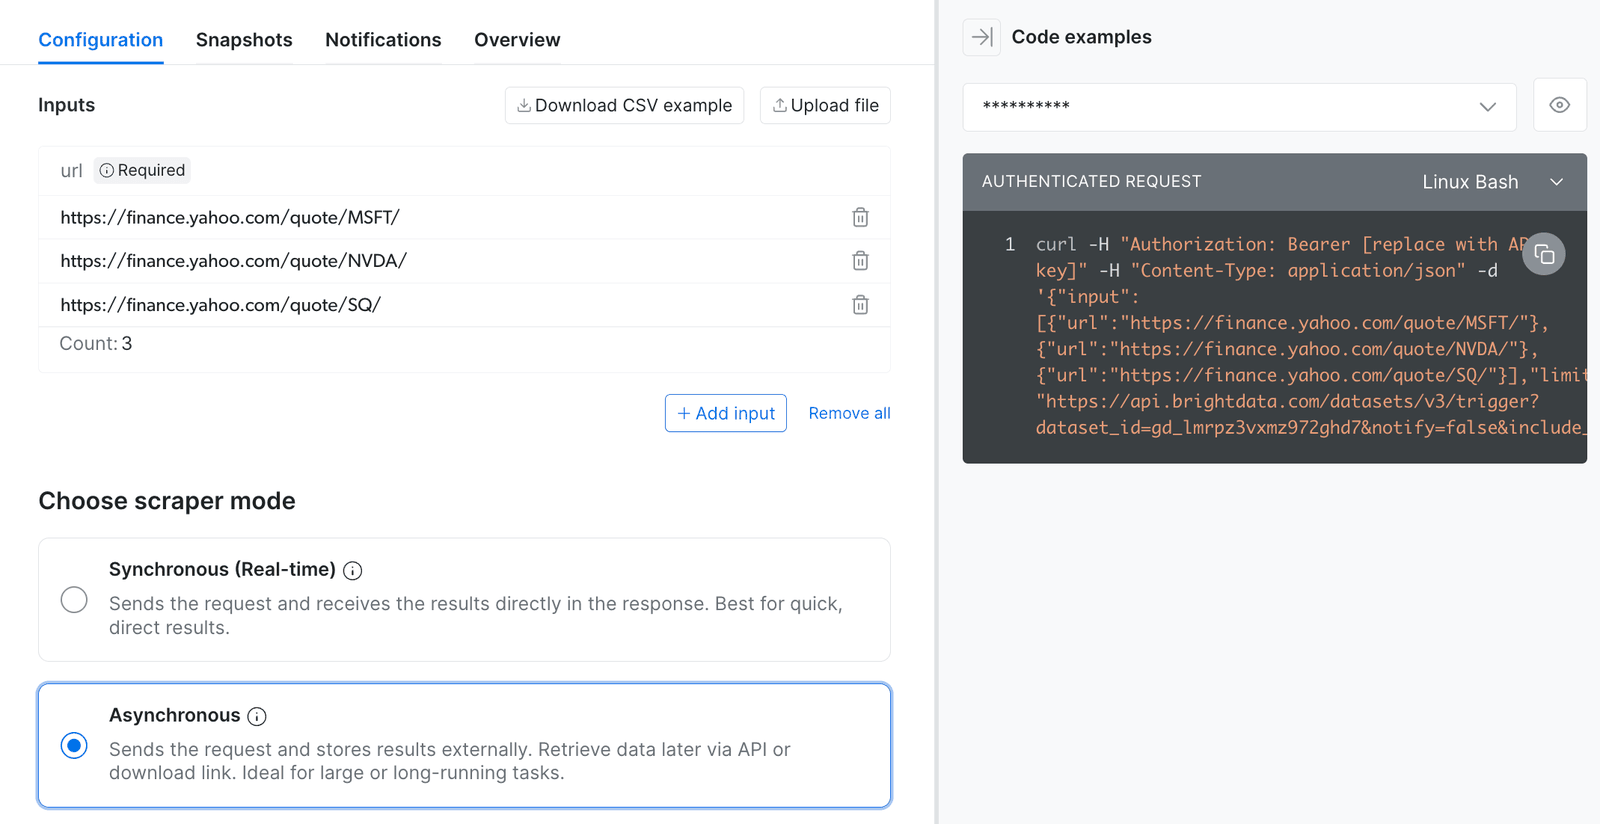
The panel’s curl example uses the same quote URLs, trigger endpoint, and dataset ID as scraper_api.py, and Asynchronous mode works best for scheduled batch jobs.
Trigger a job and download the records
Save the next script as scraper_api.py. It triggers a job for a list of URLs, polls its progress, downloads the records, and reports the symbols that Yahoo doesn’t list:
import os
import time

import requests

API = "https://api.brightdata.com/datasets/v3"
DATASET_ID = "gd_lmrpz3vxmz972ghd7"  # Yahoo Finance business information
HEADERS = {"Authorization": f"Bearer {os.environ['BRIGHTDATA_API_KEY']}"}
# The API returns only these fields, so the list keeps input, error, and error_code.
FIELDS = (
    "input|error|error_code|stock_ticker|closing_price|"
    "market_cap|pe_ratio|currency|timestamp"
)


def job_status(snapshot_id: str) -> str:
    progress = requests.get(
        f"{API}/progress/{snapshot_id}", headers=HEADERS, timeout=60
    )
    return progress.json()["status"]


def run_batch(urls: list[str], poll_seconds: int = 30) -> list[dict]:
    """Trigger one collection job, wait until it's ready, and return its records."""
    trigger = requests.post(
        f"{API}/trigger",
        params={
            "dataset_id": DATASET_ID,
            "include_errors": "true",
            "custom_output_fields": FIELDS,
        },
        headers=HEADERS,
        json={"input": [{"url": url} for url in urls]},
        timeout=60,
    )
    trigger.raise_for_status()
    snapshot_id = trigger.json()["snapshot_id"]

    while job_status(snapshot_id) != "ready":
        time.sleep(poll_seconds)

    records = requests.get(
        f"{API}/snapshot/{snapshot_id}",
        params={"format": "json"},
        headers=HEADERS,
        timeout=300,
    )
    records.raise_for_status()
    return records.json()


def collect_records(urls: list[str]) -> tuple[list[dict], dict[str, str]]:
    """Run one job and split its records into results and per-URL errors."""
    records = run_batch(list(dict.fromkeys(urls)))  # drop duplicate URLs
    done = [record for record in records if not record.get("error")]
    errors = {
        record["input"]["url"]: f'{record.get("error_code")}: {record["error"]}'
        for record in records
        if record.get("error")
    }
    return done, errors


if __name__ == "__main__":
    urls = [f"https://finance.yahoo.com/quote/{s}/" for s in ("MSFT", "NVDA", "SQ")]
    records, errors = collect_records(urls)
    for record in records:
        print(record)
    print("errors:", errors)
It printed 2 records and an error for SQ:
{'input': {'url': 'https://finance.yahoo.com/quote/MSFT/'}, 'stock_ticker': 'MSFT', 'closing_price': 516.17, 'market_cap': 3832843862016, 'pe_ratio': 28.739979, 'currency': 'USD', 'timestamp': '2026-09-27T16:15:44.789Z'}
{'input': {'url': 'https://finance.yahoo.com/quote/NVDA/'}, 'stock_ticker': 'NVDA', 'closing_price': 225.07, 'market_cap': 5434765213696, 'pe_ratio': 28.489874, 'currency': 'USD', 'timestamp': '2026-09-27T16:16:02.513Z'}
errors: {'https://finance.yahoo.com/quote/SQ/': 'dead_page: Target quote not found on lookup page'}
The scraper flagged SQ as dead_page because Yahoo redirects SQ to its lookup page, and fetch_page() raises SymbolNotFound in the same case.
Set up a scheduled pipeline
Run the Scraper API as a batch job. Send many tickers in each trigger call, then poll the progress endpoint or wait for a webhook.
The synchronous /scrape endpoint returns records directly in its response. For a longer job, the endpoint returns a snapshot_id to poll instead, as the synchronous API reference describes.
The trigger call accepts a few settings that matter for a scheduled pipeline. The asynchronous API reference lists them, and the Control Panel offers the same options under Scraper settings:
- Errors report.
include_errors=trueadds anerrorand anerror_codeto any input without a result, such as a symbol that Yahoo no longer lists.collect_records()reports those inputs by URL. - Output fields.
custom_output_fieldskeeps only the fields you list, separated by|, so addinput,error, anderror_codeto keep the error report. - Record limits.
limit_per_inputlimits the records per input, andlimit_multiple_resultslimits the records per job. Both limits control the cost of a Discover by keyword search. - Delivery and webhooks.
endpointdelivers the records to your webhook URL.notify=truesends a notification when the job completes, so a scheduler doesn’t have to poll/progress. Passuncompressed_webhook=trueto receive webhook payloads uncompressed. Delivery settings in the panel can also write results to Amazon S3, Google Cloud Storage, or Snowflake, as the data delivery docs describe. - Schedules. The Control Panel can run the same collection on a recurring schedule, such as a daily ticker refresh.
On a longer ticker list, the scraper also flagged MMC, BK, and FI as dead_page. Those companies had changed their symbols to MRSH, BNY, and FISV. You pay only for successfully delivered records.
Search by keyword or run it from the CLI
The Discover by keyword mode finds listings that match a keyword across exchanges and asset types. A WIX query found Wix.com, Wickes Group (WIX.L), and WIX option contracts, and an MSFT query also found Microsoft’s Toronto listing and single-stock ETFs. Filter on entity_type and stock_ticker to keep the listings you want.
The Yahoo Finance Scraper API also runs from a terminal as brightdata pipelines yahoo_finance_business <url> in the Bright Data CLI. Through the web_data_yahoo_finance_business tool, an AI agent can fetch the record for a quote URL you give it. The tool runs on our Yahoo Finance MCP Server, after you enable its finance tool group.
Choose the right approach for your pipeline
Start by reading the quote pages for free, and add Web Unlocker API for scheduled server jobs. For structured records, use the Scraper API or the Yahoo Finance Dataset:
| Option | Best for | You handle | Pricing |
|---|---|---|---|
| yfinance | Personal research, as its README says | Library updates, blocked IPs | Free |
| Quote pages with curl_cffi | Hundreds of tickers a day from home or a GitHub Actions runner | Parser, retries, blocked IPs | Free |
| Quote pages with Web Unlocker API | Scheduled server jobs that read any tab | Parser | Per successful request |
| Playwright with Browser API | Quarterly statements and other data that appears after you select a toggle | Browser script, parser | Per GB of traffic |
| Yahoo Finance Scraper API | Parsed records delivered on a schedule | Output field list | Per delivered record |
| Yahoo Finance Dataset | Ready-made files of companies, funds, and indices | Delivery settings | Per record |
To estimate a monthly budget, count 1 Web Unlocker API request per tab, per ticker, per refresh. The Yahoo Finance Scraper API needs 1 record per ticker per refresh. Multiply either volume by the current price on the Web Unlocker API pricing page or the Web Scraper API pricing page.
For quarterly statements, a Playwright or Puppeteer script can select the financials tab’s Quarterly toggle in our Browser API. It runs Chromium in the cloud, and CAPTCHA solving and JavaScript rendering are built in. Our guide to scraping dynamic websites with Python shows that workflow step by step.
Our Yahoo Finance Dataset packages the same kind of records as the Scraper API into ready-made JSON, NDJSON, CSV, or Parquet files. It includes equities, mutual funds, indices, ETFs, currencies, and money-market funds, so filter on entity_type to keep the asset classes you want.
You can buy a subset with only the data points you need and get updates on a daily, weekly, monthly, or custom schedule. Each delivery can contain only new or updated records and go directly to Amazon S3, Google Cloud, Azure, Snowflake, or SFTP. The dataset page shows the current record count and pricing, and you can download a sample file in JSON or CSV before you buy.
For other market-data sources, see our guides to scraping financial data and scraping Google Finance. Our other scrapers and datasets offer more stock data and other Yahoo results:
- Stock Market Scraper collects stock data from sites such as Yahoo Finance, Google Finance, and TradingView.
- Google Finance Scraper and TradingView Scraper collect stock prices and market trends from those 2 sites.
- Nasdaq Scraper collects Nasdaq data such as open price, close price, and share volume.
- Stocktwits Scraper collects Stocktwits posts, sentiment, and trending symbols.
- Financial Data Scraper API returns fields such as company name, stock ticker, exchange, and closing price.
- Stock Market Dataset, Stock Prices Dataset, and Financial Dataset deliver company profiles, stock tickers, and prices as ready-made files.
- Google Finance Datasets, Historical Financial Data, and Financial News Dataset deliver Google Finance data, historical financial data, and financial news as ready-made files.
- Yahoo News API and Yahoo Search API return Yahoo News and Yahoo search results.
Final thoughts
Yahoo Finance’s quote pages contain their own API responses as JSON, so 1 request per tab returns the data with no browser, cookie, or crumb. Fix the client before you add delays, because Yahoo’s 429s on first requests depended on the client’s TLS handshake and User-Agent. Parse the embedded responses, validate every page, compare each name with your ticker list, and convert minor currency units inside the parser.
For scheduled server jobs, route the same parser through Web Unlocker API, or let the Yahoo Finance Scraper API return structured records. Our monthly free credits apply to both, so you can try either with your own ticker list.
FAQ
Is there an official Yahoo Finance API?
No. Yahoo says it disabled API access to quote data because its data providers “do not currently authorize” redistribution in API form. The internal API hosts that yfinance uses are undocumented and disallowed in robots.txt. Yahoo’s quote pages embed the same data as JSON.
Is yfinance still usable?
Yes, from home and 3 GitHub Actions runners, yfinance fetched MSFT’s full daily history in under 1.5 seconds. It uses curl_cffi’s Chrome TLS handshake. Its README calls the Yahoo API “intended for personal use only.” Developers reported 401s and failed fetches from some cloud hosts, so test it from your own server.
Does Yahoo Finance block web scraping?
Yes, for some clients. Yahoo blocked Python’s default requests client on its first request. With Chrome’s TLS handshake, curl_cffi got no 429s on a residential connection or 3 GitHub Actions runners. For scheduled jobs, Bright Data’s Web Unlocker API fetches the same pages with IP rotation and automatic retries.
Can you download data from Yahoo Finance?
Yes, but Yahoo’s help page limits the CSV download to paid Yahoo Finance subscribers. In code, a single request to the historical data tab returned every daily MSFT bar since 1986. For bulk files, Bright Data’s Yahoo Finance Dataset delivers records for companies, funds, and indices on the schedule you choose.
Is the Yahoo Finance API free?
Not officially. Yahoo’s internal endpoints cost nothing to call, but they’re undocumented and disallowed for crawlers. Yahoo’s help page limits CSV downloads to paid subscribers. Bright Data’s Yahoo Finance Scraper API returns structured records, and new accounts get monthly free credits to test it.


Technical Writer
 5 years experience
Satyam Tripathi helps SaaS and data startups turn complex tech into actionable content, boosting developer adoption and user understanding.