TL;DR: Quick Comparison
✓ Bright Data dominates both enterprise and AI web scraping with 400M+ residential IPs, 99.99% uptime, and comprehensive AI infrastructure including MCP Server for RAG systems and AI agents, starting at free tier with 5,000 requests/month
✓ Firecrawl is best for AI developers seeking simple setup with native Markdown output and transparent $19-$399/month pricing
✓ Key difference: Firecrawl = simplified API for basic AI workflows | Bright Data = complete AI data platform with both speed AND scale, plus automatic unblocking of protected websites
✓ Choose Bright Data if you need production-grade AI infrastructure, automatic unblocking of protected sites, multi-modal data (text/video/audio), enterprise compliance (SOC 2), or RAG systems that won’t fail on difficult websites
✓ Choose Firecrawl if you need basic text scraping with minimal configuration and are processing under 100K pages/month
✓ Both offer MCP Server support, but Bright Data’s provides access to 60+ structured domain scrapers, 50PB+ Archive API, and proven reliability that Firecrawl’s simplified approach can’t match
What is Bright Data?
Bright Data has operated since 2014 as the world’s largest web data platform. The company serves 50,000+ customers including Fortune 500 enterprises, processing over 650 petabytes of data monthly.
Core Infrastructure & Network
Bright Data’s foundation is its massive ethical proxy infrastructure. The platform operates 150 million+ residential IPs across 195 countries, providing real-user IP addresses.
When you’re building AI agents or RAG systems that depend on live web data, blocking isn’t an option. Bright Data’s residential proxies get your AI applications the data they need, even from heavily protected sites that block simpler tools.
The network includes three proxy types:
- Residential proxies: 400M+ IPs from real devices
- Datacenter proxies: High-speed dedicated IPs
- ISP proxies: Static residential IPs combining speed and legitimacy
Key Features for AI Applications
Web Scraper API: Pre-built scrapers for 100+ popular domains including LinkedIn, Amazon, Instagram, Twitter (X), and TikTok. Instead of building custom scrapers, you call an API and receive structured, AI-ready data. These scrapers are optimized for feeding LLMs and RAG systems with clean, reliable data at scale.
Web Unlocker: Automatically bypasses anti-bot protections including Cloudflare, DataDome, and PerimeterX. This handles CAPTCHA solving, fingerprint rotation, and browser automation without manual configuration. This is critical for AI applications that cannot afford blocked requests.
Archive API: Access to 50+ petabytes of historical internet data including images, audio, and video files. This is invaluable for multi-modal AI training where you need diverse data types beyond what simple text scrapers can provide.
Browser API: Remote browser automation for JavaScript-heavy sites requiring complex interactions like scrolling, clicking, and form submission. Essential for AI agents that need to interact with dynamic websites.
Bright Data MCP Server for AI Agents
Bright Data’s Model Context Protocol (MCP) Server connects AI agents directly to web data infrastructure with enterprise-grade reliability. Your LLM can search, extract, and navigate the web autonomously without getting blocked.
The MCP Server runs on Bright Data’s free tier: 5,000 free requests every month, with no credit card. The same pool covers Web Scraper API, SERP API, and Web Unlocker. This is perfect for prototyping AI agents and RAG systems before scaling to production. It provides AI developers with Bright Data’s proven infrastructure at no cost, eliminating the “simplicity vs. capability” trade-off.
MCP Server capabilities for AI applications:
- Structured data from 100+ popular domains (not just generic scraping)
- Advanced search and intelligent crawling
- Browser automation for complex AI agent workflows
- Automatic bypass of anti-bot protections, including CAPTCHAs and fingerprinting
- Real-time data extraction for RAG knowledge retrieval
- Works with Claude, ChatGPT, and custom AI agents
- Scales from prototype to production without switching tools
Why this matters for AI agents and RAG systems: When your AI agent encounters a protected site, session management, or complex JavaScript, you need infrastructure that handles it automatically. Bright Data’s MCP Server gives AI applications the same enterprise-grade access that Fortune 500 companies rely on, but through a developer-friendly interface.
What is Firecrawl?
Firecrawl launched in 2024 from Y Combinator as a web scraping API built for simplicity. The platform has gained 81.3K+ GitHub stars and serves 80,000+ companies building web scraping applications.
AI-Native Design Philosophy
Firecrawl focuses on converting web pages into clean Markdown and JSON formats. For straightforward scraping needs on unprotected websites, this simplified approach reduces development time.
The platform automatically converts web pages into LLM-optimized formats without manual transformation. This eliminates basic data cleaning pipelines for simple use cases.
LLM-Ready Data Outputs
Automatic Markdown conversion: Pages get transformed into clean Markdown that preserves document structure while removing navigation, ads, and boilerplate content.
Structured JSON extraction: The /extract endpoint accepts natural language prompts to pull specific data fields. Instead of writing CSS selectors, you describe what you want and receive structured JSON.
Interactive scraping: The platform handles basic JavaScript rendering and dynamic content loading for unprotected sites.
Agent mode: The autonomous Agent endpoint uses AI to navigate websites and gather data without explicit instructions for simpler scraping scenarios.
Developer Experience
Firecrawl prioritizes ease of setup. Integration is straightforward:
from firecrawl import Firecrawl

firecrawl = Firecrawl(api_key="fc-YOUR-API-KEY")

# Scrape a single URL
scrape_result = firecrawl.scrape('https://example.com', formats=['markdown', 'html'])
print(scrape_result)
The platform offers:
- Native LangChain integration for basic RAG pipelines
- SDKs for Python, Node.js, Go, and Rust
- Open-source core with community contributions
- No-code integrations with n8n, Zapier, Make, and Lovable
- 500 free credits for testing
The trade-off: This simplicity comes with limitations. Firecrawl achieves 96% web coverage, which means 4% of sites (often the most valuable, protected ones) are inaccessible. For AI applications requiring reliable access to all sites, this gap becomes critical.
Head-to-Head Comparison
Architecture & Technical Approach
Firecrawl uses an API-first, single-purpose design. You send a URL, receive clean data from sites without sophisticated protection. The platform abstracts complexity behind simple endpoints, which works well for basic scraping needs.
Bright Data operates as a comprehensive AI data platform. You get both simplicity (through MCP Server and pre-built APIs) AND enterprise infrastructure when you need it. This isn’t complexity for its own sake. It’s the difference between “works on most sites” and “works on protected sites too.”
For AI applications, this architectural difference is crucial. When your RAG system needs data from a Cloudflare-protected documentation site, or your AI agent must access geo-restricted content, Bright Data’s infrastructure handles those blocks automatically.
AI & LLM Integration
Both platforms support AI applications, but with different reliability profiles. Check out Bright Data’s demos now.
Firecrawl returns fast responses on sites without protection. This works well for basic use cases where speed matters more than access to protected sites.
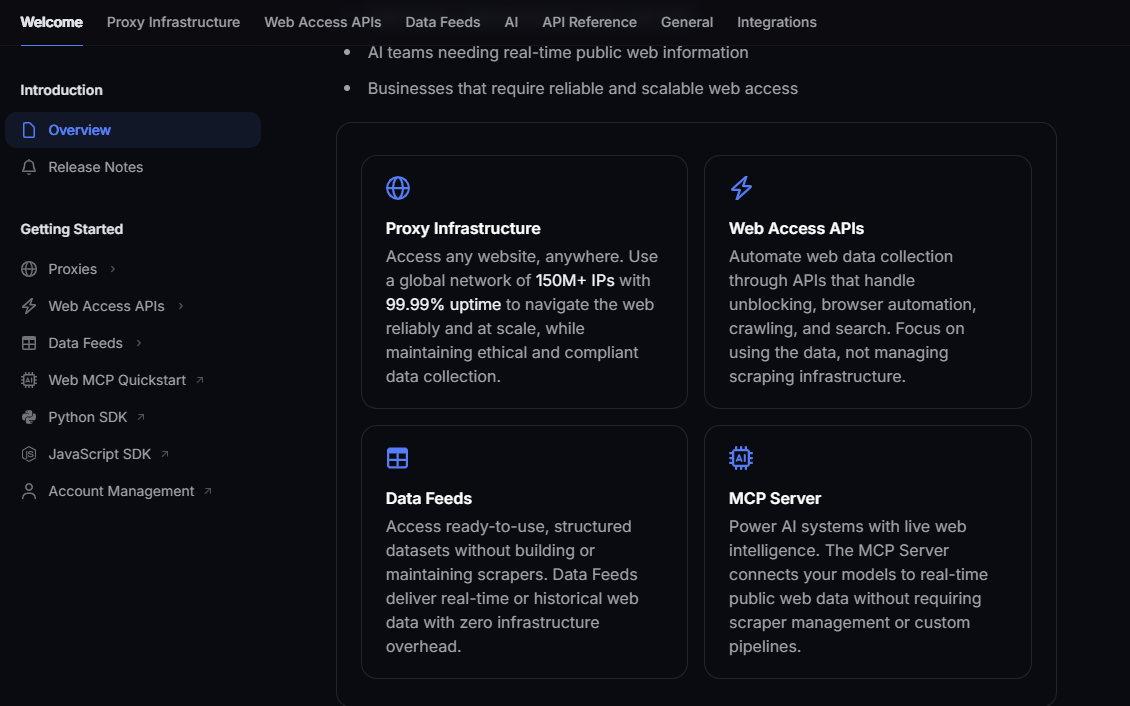
Bright Data provides enterprise-grade AI infrastructure through its MCP Server that combines speed AND reliability:
- 99.99% network uptime for always-on AI workflows
- Automatic unblocking of protected sites that block simpler tools
- 100+ pre-built scrapers delivering structured data from major platforms
- 50PB+ Archive API for multi-modal AI training beyond text
- Real-time and batch modes optimized for different AI workflows
Bright Data is built for:
- Production RAG systems that need data from protected sources
- AI agents accessing protected sites automatically
- Multi-source data aggregation for comprehensive AI knowledge bases
- Enterprise AI applications where failures aren’t acceptable
- Real-time AI agents needing both speed AND reliability
For RAG systems specifically: Both platforms can deliver clean data, but Bright Data ensures your RAG system doesn’t fail when users query information from protected sources. When your AI needs to retrieve knowledge from LinkedIn, major e-commerce sites, or enterprise platforms, Bright Data’s Web Unlocker handles the blocks automatically.
The MCP Server bridges the simplicity gap. You get Firecrawl-style ease of use with enterprise-grade capabilities underneath.
Performance & Speed
The critical insight: Speed on easy targets is only half the picture. For AI applications, the question isn’t just “how fast?” but “will it work when I need it?”
Firecrawl achieves 96% web coverage. This is significantly better than Puppeteer’s 79% or cURL’s 75%, but that 4% gap often includes the most valuable data sources: LinkedIn profiles, e-commerce pricing, financial data, enterprise SaaS platforms.
Bright Data fills that gap with its residential proxy network and Web Unlocker. The platform handles the protected sites where simpler tools fail, making it essential for production AI applications.
For AI agents and RAG systems: When building a chatbot that answers questions about competitor products, you can’t tell users “sorry, I can’t access that site.” Bright Data ensures your AI applications work reliably across all data sources.
Anti-Bot & Scraping Success Rates
Modern websites deploy multiple protection layers:
- Cloudflare’s Bot Management
- DataDome behavioral analysis
- PerimeterX device fingerprinting
- Custom CAPTCHA implementations
- Rate limiting and IP blocking
Firecrawl handles common protections through built-in stealth mode. The platform works reliably on most websites without additional configuration. When it encounters advanced protection, it fails, leaving a coverage gap.
For basic AI projects scraping unprotected content, this may suffice. For production AI applications, the protected sites it misses often include your most critical data sources.
Bright Data’s Web Unlocker unblocks protected sites through:
- Automatic CAPTCHA solving
- Browser fingerprint rotation
- TLS fingerprinting randomization
- Behavioral pattern mimicking that defeats advanced detection
- Residential IP rotation from 400M+ addresses appearing as real users
For AI applications, this is the difference between a demo and production. When building RAG systems, your users don’t care about your average coverage. They care that their specific query failed. Bright Data’s infrastructure ensures your AI applications deliver reliable answers from any source.
The platform has defeated sophisticated anti-scraping techniques for over a decade. This is battle-tested infrastructure that AI developers can depend on.
Developer Experience & Integration
Firecrawl’s integration time: Under 5 minutes for basic setup. The API documentation is clear, examples are abundant, and the community provides support through GitHub Discussions and Discord.
Bright Data offers multiple integration paths:
- Simple path (MCP Server): 5-10 minutes to connect AI agents through Model Context Protocol. As easy as Firecrawl but with enterprise capabilities
- Pre-built APIs: 15-30 minutes to integrate specific domain scrapers (LinkedIn, Amazon, etc.)
- Custom configuration: 30-60 minutes for organizations requiring precise control
The key difference: Bright Data scales with your needs. Start simple with MCP Server, then customize when requirements grow. Firecrawl’s simplicity becomes a limitation when you need more.
For AI developers building RAG systems: Bright Data’s MCP Server provides the same ease-of-use as Firecrawl with none of the coverage gaps. Your AI agents get clean, structured data through a simple interface, backed by infrastructure that won’t fail on protected sites.
For enterprise teams: Bright Data’s documentation is comprehensive, and customers receive dedicated support teams and solution architects. You’re not troubleshooting alone when production AI systems need help.
Pricing & Cost Structure
Pricing models reveal different philosophies: Firecrawl optimizes for small projects, Bright Data provides value at all scales.
Firecrawl uses transparent credit-based pricing:
| Plan | Price | Credits | Best For |
|---|---|---|---|
| Free | $0 | 500 (one-time) | Testing & evaluation |
| Hobby | $19/month | 3,000 | Individual developers |
| Standard | $99/month | 100,000 | Startups & small teams |
| Growth | $399/month | 500,000 | Growing companies |
| Enterprise | Custom | Custom | Large-scale operations |
Bright Data provides flexible pricing across use cases:
- MCP Server: Free on the shared monthly pool of 5,000 free requests, no credit card
- Residential Proxies: Starting at $5.04/GB (50% off promotion: $2.52/GB)
- Web Scraper API: Starting at $0.001/record (25% off: $0.00075/record)
- Web Unlocker: Starting at $1/1K requests
- Browser API: Starting at $5/GB
For AI applications specifically: Bright Data’s free tier gives 5,000 requests every month, shared across the MCP Server and its APIs, while Firecrawl’s 500 free credits are one-time. You can build and test production RAG systems without paying anything.
For production AI systems: Bright Data bills Web Scraper API and Web Unlocker on successful results, so failed requests on protected sites cost nothing.
Use Case Analysis
Best for Production RAG Systems: Bright Data
Building RAG (Retrieval Augmented Generation) systems for production requires reliable data access, not just clean formatting. When users query your AI assistant, they expect answers regardless of whether the source website uses Cloudflare protection.
Why Bright Data wins for production RAG:
Access to protected knowledge sources: RAG systems are only as good as their knowledge retrieval. Web Unlocker handles CAPTCHAs, fingerprints, and retries automatically, so your AI can answer questions from sources that block simpler tools. This includes LinkedIn, major e-commerce platforms, enterprise SaaS documentation, and financial data sources.
Enterprise-grade reliability: 99.99% uptime with SLAs means your RAG system delivers consistent answers. When building AI assistants for customer-facing applications, you can’t have “sorry, I can’t access that information right now” as an acceptable response.
MCP Server for rapid integration: Bright Data’s Model Context Protocol Server provides the same developer-friendly integration as Firecrawl but backed by infrastructure that won’t fail. Start prototyping with the free 5,000 requests/month, then scale seamlessly to production.
Multi-source knowledge aggregation: Pre-built scrapers for 100+ major platforms deliver structured, AI-ready data from diverse sources. Your RAG system can pull information from LinkedIn profiles, Amazon reviews, Twitter discussions, and documentation sites all through unified APIs.
The entire pipeline delivers clean, structured data for RAG systems with enterprise reliability.
Best for Enterprise AI Operations: Bright Data
Fortune 500 companies have requirements that extend beyond technical capabilities: compliance certifications, audit trails, SLAs, and proven reliability at massive scale.
Why Bright Data is essential for enterprise AI:
Compliance infrastructure: SOC 2 Type II certification, GDPR compliance, CCPA adherence, and ISO certifications satisfy even the most stringent procurement requirements. Financial services, healthcare, and government AI applications require this documentation.
Scale proven at Fortune 500: Processing 650+ petabytes monthly across 50,000+ customers demonstrates operational excellence. When your AI systems monitor millions of data points, process competitor intelligence, or power customer-facing chatbots, you need infrastructure that won’t fail.
99.99% uptime guarantee with SLA agreements ensures reliability for mission-critical AI operations. When business decisions depend on AI-powered insights, downtime isn’t acceptable.
White-glove support includes dedicated account managers, solution architects, and 24/7 technical support. Enterprise AI teams get hands-on assistance with implementation, optimization, and troubleshooting.
Geographic precision: 195 countries with targeting down to city or ZIP code level enables AI applications to access region-specific data. Bright Data’s 400M+ residential proxies provide the global coverage enterprise AI operations require.
Best for Multi-Modal AI Training: Bright Data
Training modern AI models requires diverse data types beyond text: images, video, audio, and historical context.
Bright Data’s Archive API provides access to 50+ petabytes of historical internet data including:
- Images and graphics from billions of web pages
- Video content for computer vision training
- Audio files for speech recognition models
- Historical versions of websites showing change over time
Firecrawl optimizes only for text extraction, making it unsuitable for projects requiring visual or audio training data.
Annotation services further enhance training data quality. Bright Data can label and categorize data using either AI assistance or human annotators, producing high-quality datasets for supervised learning.
For AI model developers: You can’t train sophisticated multi-modal models with text-only tools. Bright Data provides the complete data infrastructure for next-generation AI development.
Best for AI Agents Requiring Reliable Access: Bright Data
Conversational AI and autonomous agents need instant access to current web information with reliable success on protected sites, not just speed on easy targets.
Bright Data’s infrastructure for AI agents enables:
- Real-time knowledge retrieval from any website (including protected ones)
- AI agents that don’t fail when encountering Cloudflare protection
- Autonomous navigation across complex, multi-step workflows
- Geographic-specific data access for location-aware AI assistants
- Concurrent multi-source data gathering at scale
The MCP Server provides AI agents with browser automation, CAPTCHA solving, and residential proxy rotation automatically. Your agent describes what it needs, Bright Data’s infrastructure ensures it gets it.
The agent handles navigation, pagination, and anti-bot challenges automatically with infrastructure that won’t fail.
The competitive advantage: AI agents built on Bright Data deliver reliable answers from any source. Agents built on simpler tools tell users “I couldn’t access that information” on the protected sites that often matter most.
When to Choose Firecrawl
Choose Firecrawl when your project prioritizes:
Minimal setup over comprehensive capabilities. If you need basic scraping for straightforward, unprotected websites, Firecrawl’s simplified API reduces configuration time.
Small-scale experimentation over production reliability. For personal projects, learning exercises, or basic prototypes processing under 100K pages monthly from unprotected sites.
Text-only extraction over multi-modal data. When you don’t need images, video, audio, or historical data for AI training.
Basic AI applications over enterprise requirements. Projects that don’t need compliance certifications, dedicated support, or guaranteed SLAs.
Acceptable failure rate. If your sources are mostly unprotected and occasional blocks are acceptable.
Ideal Firecrawl use cases:
- Personal AI experiments and learning projects
- Basic web monitoring of unprotected sites
- Content aggregation from simple blogs and news sites
- Proof-of-concept prototypes before production development
- Non-critical applications where occasional failures are acceptable
When to Choose Bright Data
Choose Bright Data when your project requires:
Production-grade AI infrastructure. When building RAG systems, AI agents, or LLM applications that users depend on, you need reliable access to protected sources as well as open ones.
Reliable access to protected sites. When your AI needs data from LinkedIn, major e-commerce platforms, enterprise SaaS sites, or any source using Cloudflare, DataDome, or PerimeterX protection.
Enterprise reliability for AI applications. 99.99% uptime SLA ensures your AI-powered chatbots, research tools, and automated systems work consistently.
Multi-modal AI training. Archive API with 50+ petabytes including video, audio, and images supports training sophisticated AI models beyond text-based applications.
Scale from prototype to production. Start on the free tier (5,000 requests every month, shared with the MCP Server), scale seamlessly to millions of requests without switching platforms or rebuilding infrastructure.
Compliance for regulated industries. Organizations in financial services, healthcare, or government requiring SOC 2 Type II, GDPR, and industry-specific certifications.
Geographic precision. AI applications needing region-specific data across 195 countries with city-level targeting.
Ideal Bright Data use cases:
- Production RAG systems that need reliable retrieval from protected sources
- Enterprise AI agents accessing protected websites automatically
- Multi-modal AI training with text, image, video, and audio data
- Customer-facing AI applications where failures aren’t acceptable
- Competitive intelligence AI monitoring protected competitor sites
- Financial AI systems requiring compliance and data accuracy
- Research AI tools aggregating data from diverse protected sources
- E-commerce AI accessing real-time pricing from major platforms
Alternative Solutions to Consider
While Bright Data provides comprehensive AI infrastructure and Firecrawl offers simplified basic scraping, other platforms fill specific niches:
For no-code users: Octoparse offers visual scraping workflows without programming. Business analysts can set up basic scrapers through point-and-click interfaces. Trade-off: fails on protected sites and lacks AI optimization.
For open-source control: Crawl4AI provides free, self-hosted scraping with LLM integration. Ideal for developers prioritizing cost over reliability. Trade-off: you handle all infrastructure, maintenance, anti-bot challenges, and failures.
For managed complexity: Zyte API combines developer-friendly APIs with automatic anti-bot handling. Positioned between Firecrawl’s simplicity and Bright Data’s comprehensive capabilities.
For marketplace approach: Apify offers thousands of pre-built actors plus cloud execution infrastructure. Middle ground for teams wanting some customization without comprehensive infrastructure.
For compliance-first: Oxylabs emphasizes ethical scraping and enterprise compliance similar to Bright Data but with smaller proxy networks and less comprehensive capabilities.
Learn more in our guide: Top 7 Firecrawl Alternatives for AI Web Scraping
The Bottom Line
The choice between Firecrawl and Bright Data isn’t about “simple vs. complex.” It’s about demo vs. production.
Firecrawl works for basic prototypes on unprotected websites. The simplified API reduces initial setup time for learning projects and personal experiments on open sites.
Bright Data powers production AI applications that users depend on. The platform’s 400M+ residential proxies, 99.99% uptime, MCP Server for AI agents, and automatic unblocking of protected sites make it essential for RAG systems, AI agents, and enterprise applications where failures aren’t acceptable.
For AI developers specifically: Prototype and test production RAG systems on the free tier, backed by infrastructure that won’t fail when you scale.
The web scraping market has evolved: simplicity alone isn’t enough for production AI applications. You need reliable access to protected data sources, not just open ones.
Ready to get started?
Try Bright Data’s MCP Server for free on the free tier’s 5,000 monthly requests. Perfect for building and testing RAG systems and AI agents without cost.
Explore our comprehensive AI data platform with Web Scraper API, Web Unlocker, Archive API, and Browser API to see why leading AI companies choose Bright Data for production applications.
Early-stage startups can begin prototyping with our free tier. As projects grow, Bright Data scales seamlessly from prototype to production. No platform switching, no rebuild required, no coverage gaps.
Building production AI applications? Sign up for personalized recommendations and architecture guidance for your specific RAG system or AI agent requirements.
Frequently Asked Questions
What is the main difference between Firecrawl and Bright Data?
Firecrawl is a simplified scraping API that delivers clean Markdown from unprotected websites (96% coverage). Bright Data is a comprehensive AI data platform with 400M+ proxies, 99.99% network uptime, and MCP Server integration designed for production RAG systems and AI agents that need reliable access to protected websites.
The critical difference: Firecrawl works until it encounters protection. Bright Data’s Web Unlocker is built for the protected sites that block simpler tools.
Which is better for AI and RAG systems?
Bright Data is superior for production AI and RAG systems due to automatic unblocking of protected sites, 99.99% network uptime, MCP Server for AI agents, and free tier (5,000 requests/month) for prototyping. Bright Data ensures your RAG system can retrieve knowledge from any source, including LinkedIn, e-commerce platforms, and enterprise sites that block simpler tools.
Firecrawl works for basic RAG prototypes on unprotected sites but leaves a 4% coverage gap that often includes the most valuable data sources. For production AI applications where users depend on reliable answers, Bright Data’s infrastructure is essential.
Which is cheaper, Firecrawl or Bright Data?
Bright Data gives you more free usage and bills only for success:
- Free tier: Bright Data gives 5,000 free requests every month, shared across the MCP Server and its APIs, vs Firecrawl’s 500 one-time credits
- Protected sites: Web Unlocker handles CAPTCHAs and anti-bot systems, and you pay only for successful requests
For paid usage, compare Firecrawl’s monthly plans with Bright Data’s per-result rates against your own monthly volume.
Can beginners build AI applications with Bright Data?
Yes. Bright Data’s MCP Server provides the same ease-of-use as Firecrawl. Connect in 5-10 minutes with free tier (5,000 requests/month). The difference: you get enterprise-grade capabilities without complexity.
Start simple, scale when needed. Beginners can use pre-built scrapers and MCP integration without configuration. Advanced users can customize when requirements grow.
Which has better success rates on protected websites?
Bright Data unblocks protected websites using Web Unlocker and 400M+ residential IPs. The platform handles Cloudflare, DataDome, PerimeterX, and custom anti-bot systems that block simpler tools.
Firecrawl achieves 96% coverage but fails on protected sites, which often include the most valuable data sources for AI applications: LinkedIn, major e-commerce platforms, enterprise documentation, financial data.
For production AI systems, every blocked source is a question your AI can’t answer. Bright Data ensures your AI delivers reliable answers from protected sources too.
Do both platforms support JavaScript rendering?
Yes, but with different reliability. Both handle JavaScript-heavy websites with dynamic content loading.
Firecrawl renders JavaScript automatically for unprotected sites.
Bright Data provides Browser API with full browser automation plus residential proxies ensuring JavaScript rendering works even on protected sites with sophisticated detection.
Can I use both platforms together?
While possible, most organizations find Bright Data’s MCP Server provides everything they need: the simplicity of Firecrawl’s API plus enterprise capabilities. Starting with Bright Data’s free tier (5,000 requests/month) eliminates the need to switch platforms later when you encounter protected sites.
If already using Firecrawl, you can augment with Bright Data for protected sites. However, most teams consolidate on Bright Data’s unified platform to avoid managing multiple services.
Related Resources:


Web Data & AI Expert
 6 years experience
Daniel Shashko is a Senior SEO/GEO at Bright Data, specializing in B2B marketing, international SEO, and building AI-powered agents, apps, and web tools.