For price monitoring, scraping Target products at scale means reading store prices and stock from internal JSON APIs rather than page HTML.
In our tests, a pack of 31 Tide pods cost $9.99 in Cedar Rapids and $12.69 in Chicago at the same time. Some responses looked valid but contained an online price or a parent product’s price range. From US IPs, only 1 of 112 product API calls from curl and Python clients with default settings succeeded.
This guide shows you how to collect those prices, detect bad responses, and decide whether to build a scraper or use a Target Price Scraper.
TL;DR
- Request prices by store ID. Map ZIP codes to store IDs, then call Target’s product API with its public API key.
- Check each price’s location and variant. Location 3991 marks an online price, and a parent product can return a range, so save 1 row per variant.
- Find blocks in response bodies. Blocked calls returned HTTP 435, sometimes as valid JSON.
- Pick the tool by how you track locations. For ZIP codes, Bright Data’s Target Scraper API matched our scraper in 20 of 20 checks. For store IDs or per-channel stock, run your code on the Web Unlocker API.
How Target serves product data
In our tests, a scraper could read prices, stock, and product details from 3 Target hosts. The product page HTML was the only source without a price. Target identifies each product by a TCIN (Target.com Item Number), the number after A- in a product URL.
All 3 hosts were behind Target’s Fastly CDN. On the www and redsky hosts, HUMAN Security’s bot check could block a request and return a block response instead of data:
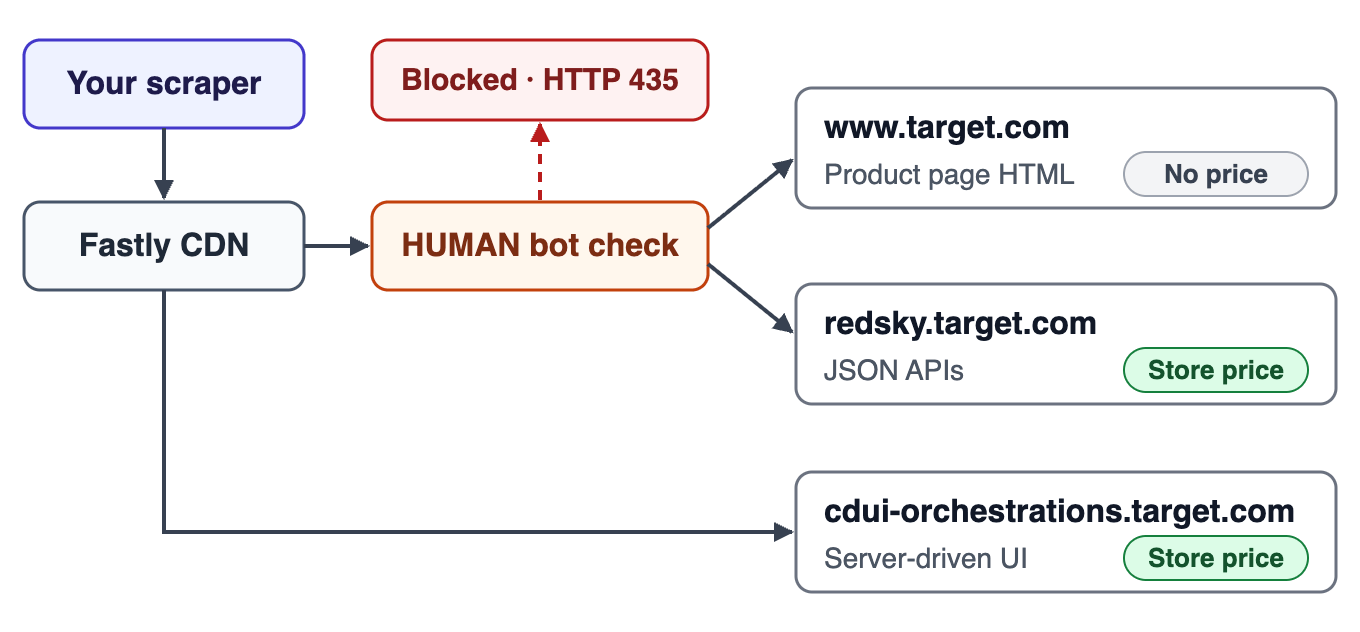
In our tests, the page HTML had no price, while the JSON APIs and server-driven UI modules had the store price.
The page HTML had no price
The product page was a Next.js application. Its __NEXT_DATA__ script had the title, description, images, and a review summary, but no price. The page props contained isProductDetailServerSideRenderPriceEnabled: false in every page we fetched with curl, whether the user agent was curl, python-requests, Chrome, or HeadlessChrome. If that flag becomes true, the HTML may include prices, so check the flag before you parse the HTML.
The same props labeled each visitor with isBot, isAiAgent, and isSeoPhantom flags. Requests that claimed to be a search-engine crawler, such as Googlebot, got a different, cached page with schema.org JSON-LD and a rendered price.
That price belonged to a single default location. Search engines publish how to verify their crawlers with reverse DNS, so a site can detect a spoofed crawler. For store prices, use the JSON APIs below instead of that page.
Prices and stock came from JSON APIs
Target’s aggregation API on redsky.target.com returns prices per store. Every endpoint we called required a key parameter. Without the key, the API returned 401 with "no API key found in request".
The key is a public API key, not a secret. It appeared 28 times in each product page we saved, except the cached page that crawlers got. Read it from a Target page, such as the home page, instead of hardcoding it.
When we checked, the API host’s robots.txt disallowed every crawler, while the main site’s robots.txt allowed product pages.
These 4 endpoints were enough for every product-data job we tested:
| Endpoint | What it returns | Limits and errors in our tests |
|---|---|---|
pdp_client_v1 |
Product, price at 1 store_id, and every variant in the family |
404 for a TCIN that no longer exists |
plp_search_v2 |
Search results for a keyword or a UPC barcode number | count up to 28, offset up to 1,199 |
nearby_stores_v1 |
Store IDs near a ZIP code | None |
product_fulfillment_v1 |
Shipping, pickup, and in-store stock at the requested store, sometimes with a nearby store | None |
This request gets the price of a carton of Parmalat UHT milk at the Chelsea store in New York, store 3412, with curl and jq:
KEY=$(curl -s https://www.target.com/ \
  | grep -oE '[0-9a-f]{40}' | sort | uniq -c | sort -rn \
  | head -1 | awk '{print $2}')

REDSKY=https://redsky.target.com/redsky_aggregations/v1/web
Q="key=$KEY&tcin=15078349"
Q="$Q&store_id=3412&pricing_store_id=3412"
Q="$Q&channel=WEB&page=%2Fp%2FA-15078349"
curl -s "$REDSKY/pdp_client_v1?$Q" \
  | jq '.data.product.children[]
        | select(.tcin=="15078349") | .price'
The location_id field in the response shows which store the price belongs to:
{
  "current_retail": 3.89,
  "display_was_now": false,
  "formatted_current_price": "$3.89",
  "formatted_current_price_type": "reg",
  "formatted_unit_price": "$0.12",
  "formatted_unit_price_suffix": "/fluid ounce",
  "reg_retail": 3.89,
  "location_id": 3412,
  "external_system_id": "15078349-3412-3.89-2025080815"
}
The price is under children because this TCIN is a variant of a parent product. Both curl commands above worked from our connection in India. From US IPs, Target’s bot check blocked nearly all such requests in our tests. In that case, jq printed a parse error, because the response was an HTML block page, not JSON.
The Web Unlocker API sends the same requests through its unblocking layer and returns Target’s JSON. Set the BRIGHTDATA_API_KEY and UNLOCKER_ZONE environment variables first, as the Web Unlocker API quickstart shows:
unlock() {
  curl -s https://api.brightdata.com/request \
    -H "Authorization: Bearer $BRIGHTDATA_API_KEY" \
    -H "Content-Type: application/json" \
    -d "{\"zone\": \"$UNLOCKER_ZONE\",
         \"url\": \"$1\", \"format\": \"raw\"}"
}

KEY=$(unlock https://www.target.com/ \
  | grep -oE '[0-9a-f]{40}' | sort | uniq -c | sort -rn \
  | head -1 | awk '{print $2}')

REDSKY=https://redsky.target.com/redsky_aggregations/v1/web
Q="key=$KEY&tcin=15078349"
Q="$Q&store_id=3412&pricing_store_id=3412"
Q="$Q&channel=WEB&page=%2Fp%2FA-15078349"
unlock "$REDSKY/pdp_client_v1?$Q" \
  | jq '.data.product.children[]
        | select(.tcin=="15078349") | .price'
The unlock function accepts any Target URL, including the stock request below.
The live page loaded server-driven UI modules
In our browser network captures, the product page didn’t call pdp_client_v1. Its layout came from server-driven UI modules, page sections that the server sends as data, either inside __NEXT_DATA__ or from cdui-orchestrations.target.com. A deferred_enrichment call on www.target.com added the location-specific modules.
The cdui-orchestrations.target.com response and the deferred_enrichment modules both contained prices. With include_data_source_modules=true, a request to cdui-orchestrations.target.com for the Chelsea store returned the same price and location ID as pdp_client_v1 for 16 of 16 test products. An endpoint that the product page didn’t call, like pdp_client_v1, can disappear without notice, and the matching cdui prices give you a tested fallback.
Why Target scrapers break at scale
Some failures happen on the first request, and others appear only when a job includes many stores and products.
Blocks depended on the IP and the client
In our tests, Target used HUMAN Security, a bot-detection service that merged with PerimeterX in 2022. Every product page we fetched with a browser or HTTP-client user agent loaded HUMAN’s sensor script from client.px-cloud.net.
In our IP and client test, we sent the same 16 pdp_client_v1 URLs from each IP source and client, in runs spread over 3 hours. A call passed if it returned 200 or 206 with no HUMAN block in the body:
| IP source | Client | Calls that passed |
|---|---|---|
| IPs in India | curl | 63 of 64 |
| IPs in the US | curl or Python requests, default user agent |
1 of 112 |
| Web Unlocker API with US exit IPs | Selected by Web Unlocker API | 32 of 32 |
From India, even curl passed. From US IPs, the result depended on the client, and browser-like headers let more calls pass. The Web Unlocker API selects the headers and browser fingerprint for you, and it passed every call in this test.
The cdui-orchestrations.target.com host behaved differently when we alternated calls to it and to pdp_client_v1 with Python’s default user agent from US IPs. The cdui host responded to all 8 calls, while the bot check blocked all 8 calls to pdp_client_v1. From our connection in India, cdui responses with prices had a median transfer size of 80 KB, and pdp_client_v1 responses had 9 KB. The cdui host avoided the block in our tests, but its data format follows the page layout and can change with any page release.
In our tests, changing a single header made a passing setup fail, and HUMAN’s block response gave no reason. Change one variable at a time. Before you trust a fix, alternate it with the old setup and run enough calls to see a clear difference. When you compare TLS fingerprints with a fingerprint echo service, use JA4 and the HTTP/2 fingerprint, because Chrome-style handshakes change JA3 between connections.
HUMAN also sets its own cookies. When we checked, its cookie documentation listed a lifetime of 5.5 minutes for _px3 and 1 year for _pxvid. The same page said these cookies maintain a session and help distinguish real users from bots. For the whole session, use each cookie jar with the IP and client that received it, or let the Web Unlocker API manage cookies.
Blocked calls returned HTTP 435 in 2 formats
When we checked, HUMAN’s enforcer documentation listed 403 and 429 as block statuses and said each site could customize the response. On Target, blocked API calls returned HTTP 435 instead, and the block response had 2 formats.
Our curl calls didn’t request JSON and got an HTML challenge page. Rendered in a browser, that page asked the visitor to press and hold a button:
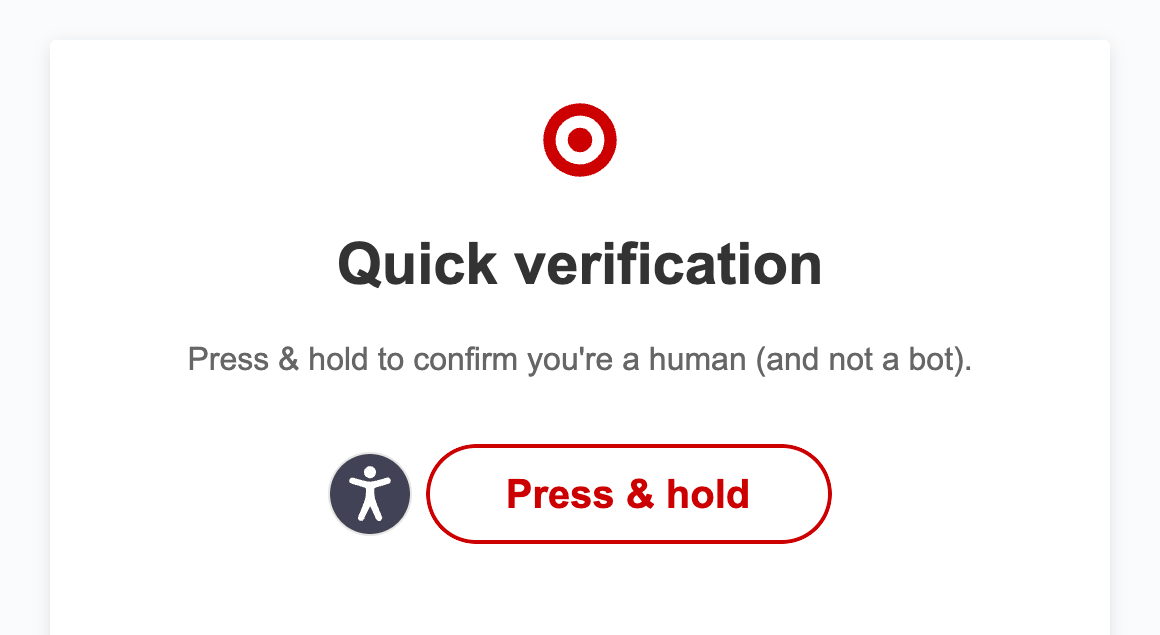
The challenge page our curl calls received with HTTP 435 instead of data.
Our Python requests calls requested JSON and got a 343-byte JSON object that starts with {"appId". If you only check for valid JSON, this block looks like valid data. Both formats contained the URL of HUMAN’s captcha script, and no normal response in our samples contained it:
def is_human_block(body):
    """HUMAN sends a block as an HTML page or a small JSON object.

    Both formats contain the URL of its captcha script. Normal Target
    pages do not.
    """
    return "captcha.px-" in body
On a set of 21 Target responses, the check flagged all 4 blocks in both formats and passed all 17 normal ones. A simpler check on the string px-captcha would have flagged a rendered product page and missed the JSON block.
Prices differed by store
Across 8 stores, 12 of the 16 products we checked had more than one price. Target reported more than 2,000 stores. The nearby_stores_v1 endpoint maps a ZIP code to the nearest store IDs. For each of 8 ZIP codes, we collected prices for the 16 products at the nearest store in a single 2-minute run.
A subset of 6 products at 5 of the 8 stores shows the price differences in US dollars. These 5 stores include each product’s lowest and highest price:
| Product | New York | Chicago | Cedar Rapids | Anchorage | Honolulu |
|---|---|---|---|---|---|
| Parmalat UHT whole milk, 32 fl oz | 3.89 | 3.49 | 3.59 | 4.49 | 3.89 |
| Tide Original pods, 31 count | 11.19 | 12.69 | 9.99 | 10.59 | 10.59 |
| Cheerios, Family Size 18 oz | 5.99 | 5.69 | 5.29 | 6.79 | 5.69 |
| Market Pantry Classic Roast, 25.9 oz | 14.69 | 14.19 | 12.89 | 16.99 | 17.59 |
| Starbucks Fall Blend, 10 oz | 14.39 | 13.59 | 12.79 | 14.29 | 13.59 |
| LEGO Creator Space Shuttle 31134 | 7.99 | 7.99 | 7.99 | 7.99 | 7.99 |
The Market Pantry coffee had the widest range: $17.59 in Honolulu was 36% higher than $12.89 in Cedar Rapids. Even without Anchorage and Honolulu, 11 of the 16 products had more than one price, and the Tide pods varied most, by 27%.
Prices can also change within a day. Between 2 of our runs on the same day, the Chicago store lowered the milk price from $3.49 to $2.97, and pdp_client_v1 labeled it sale. Set the refresh rate by how often prices change in your categories. Keep the price type, such as sale or regular, with each row.
The 4 products with the same price at every store were 2 LEGO sets and 2 AirPods models. For all 4, the API returned a price from location 3991, whichever store we requested. Location 3991 marks an online price, not a store price.
Passing 3991 as a store ID returned 206 with "Parameter store_id cannot be digital store 3991." in the errors array. For our connection in India, Target’s product page also set the store to 3991 and the ZIP code to 52404.
You can use location 3991 to save requests. First, request each product at 2 stores. If both responses show location 3991, collect the product once per refresh instead of once per store. For 4 of our 16 test products, this rule reduced the requests from 8 to 1 per refresh.
To collect store prices, send the product request with a store ID through the Web Unlocker API. The Target Scraper API returns prices for the ZIP code you send.
Parent products returned price ranges
Target lists each variant, such as a pack size, as a child TCIN under a parent product. Search results returned the child TCIN, but the product endpoint returned the parent. Tide pods TCIN 87767249 returned parent 79394303 with the price "$11.19 - $30.99", and its children array listed the 31, 42, 76, and 112 packs. If a scraper saves only the top-level price, it records a range or its lowest value for a product that has 4 prices.
The range can also hide store differences. At the parent level, Pampers Swaddlers showed "$9.99 - $59.99" at all 8 stores in an earlier run. At the variant level, the 164-count size 1 pack cost $47.99 in New York and $44.99 at the other 7 stores.
One request returns every variant of the family at the requested store. If you send 1 TCIN per family, you pay for 1 request per family at each store.
Search stopped at an offset of 1,199
The search endpoint rejected any count above 28 with "Parameter 'count' cannot be requested with more than 28". It also rejected any offset above 1,199, so 1 query could return about 1,227 results. A search for “shirts” reported 131,690 results in our test, so a single keyword could return about 1% of them.
When we checked, the robots.txt for www.target.com disallowed search pages for all user agents and listed 6 sitemap indexes. The product sitemap index pointed to 110 files, which listed 2,504,600 product URLs when we downloaded them. Discover products from sitemaps and category pages, and use the search API for occasional lookups such as UPC-to-TCIN resolution. With the UPC as the keyword, both UPCs we tried returned exactly 1 product with its TCIN.
Some status codes were misleading
Target returns 3 kinds of responses that need their own handling, and 2 of them have a misleading status code:
| Response | What it meant | What to do |
|---|---|---|
206 with an errors array |
Part of the query failed, and product data was still present | Parse the data, log the error |
404 with "No product found with tcin" |
The product no longer exists | Mark the URL dead, skip retries |
435 with an HTML or JSON body |
A HUMAN block | Detect it from the body, pause that client, and wait before retrying |
Removed products can appear in any input list, so plan for them. One product in our test list returned "No product found with tcin 1002219928".
Stock had 3 channels per store
In our tests, the product_fulfillment_v1 endpoint reported shipping, store pickup, and in-store availability separately and gave a quantity per store. This request reuses KEY and REDSKY from the product API request above and checks the milk at the Chelsea store:
Q="key=$KEY&tcin=15078349&store_id=3412"
Q="$Q&channel=WEB&page=%2Fp%2FA-15078349"
curl -s "$REDSKY/product_fulfillment_v1?$Q" \
  | jq '.data.product.fulfillment | {
      shipping: .shipping_options.availability_status,
      stores: [.store_options[] | {
        store: .location_id,
        units: .location_available_to_promise_quantity,
        pickup: .order_pickup.availability_status,
        in_store: .in_store_only.availability_status
      }]
    }'
The Chelsea store had no units and no pickup, but shipping showed the milk in stock, and a nearby store listed 6 units:
{
  "shipping": "IN_STOCK",
  "stores": [
    {
      "store": "3412",
      "units": 0.0,
      "pickup": "UNAVAILABLE",
      "in_store": "OUT_OF_STOCK"
    },
    {
      "store": "1886",
      "units": 6.0,
      "pickup": "IN_STOCK",
      "in_store": "IN_STOCK"
    }
  ]
}
In another request, the Anchorage store listed 2 units of the same milk. Save the shipping, pickup, and in-store status for each store, because a single is_available flag can’t contain 3 separate values. For stock, use read endpoints like product_fulfillment_v1, which already return quantities per store, rather than cart requests. Engineers who reverse-engineer retail APIs also report that write endpoints are better protected.
Scrape Target store prices with the Web Unlocker API
The Web Unlocker API routes each request through IPs and browser fingerprints that it selects for each site. It also handles headers, cookies, CAPTCHAs, and retries, and returns the site’s response. Bot-detection vendors update their checks often, and the Web Unlocker API adapts to those updates for you. You keep full control of your parser and endpoint logic.
To start, create a Bright Data account with an API key and a Web Unlocker API zone, a named configuration for requests and their billing. You also need Python and the requests library, and the script runs on Python 3.13. The Web Unlocker API is self-serve and bills only successful requests. The Web Unlocker API pricing page lists current rates, and the free tier includes 5,000 requests a month with no credit card required.
The script reads Target’s API key from its home page and maps each ZIP code to a store. It then gets every variant’s price and separates valid rows from rejected ones:
"""Collect Target prices per store through Bright Data's Web Unlocker API.

Usage:
    export BRIGHTDATA_API_KEY=...        # account API key
    export UNLOCKER_ZONE=web_unlocker    # your Web Unlocker API zone
    python target_store_prices.py 15078349,87767249 10001,99501
"""
import collections
import html
import json
import os
import re
import sys
import time
from concurrent.futures import ThreadPoolExecutor
from datetime import datetime, timezone
from urllib.parse import urlencode

import requests

API_KEY = os.environ["BRIGHTDATA_API_KEY"]
ZONE = os.environ.get("UNLOCKER_ZONE", "web_unlocker")
REDSKY = "https://redsky.target.com/redsky_aggregations/v1/web/"
ONLINE_STORE = "3991"  # the location Target's API calls a digital store


def is_human_block(body):
    """HUMAN sends a block as an HTML page or a small JSON object.

    Both formats contain the URL of its captcha script. Normal Target
    pages do not.
    """
    return "captcha.px-" in body


def unlock(url, attempts=3):
    """Fetch a URL through Web Unlocker API and return Target's response."""
    status = None
    for attempt in range(attempts):
        try:
            r = requests.post(
                "https://api.brightdata.com/request",
                headers={"Authorization": f"Bearer {API_KEY}"},
                json={"zone": ZONE, "url": url, "format": "raw"},
                timeout=120,
            )
        except requests.RequestException as error:
            status = type(error).__name__
            time.sleep(2 ** attempt)
            continue
        # Web Unlocker API reports Target's own result in the
        # x-brd-status-code and x-brd-error headers.
        status = int(r.headers.get("x-brd-status-code", r.status_code))
        if is_human_block(r.text):
            status = "blocked"  # a block can arrive with any status code
        elif status in (200, 206):
            return status, r.text
        elif "404" in r.headers.get("x-brd-error", ""):
            return 404, ""  # dead product page: do not retry
        time.sleep(2 ** attempt)
    return status, ""


def web_api_key():
    """Read the web API key that Target embeds in its own pages."""
    status, page = unlock("https://www.target.com/")
    keys = re.findall(r'apiKey\\?"\s*:\s*\\?"([0-9a-f]{40})', page)
    if not keys:
        raise RuntimeError(f"no apiKey in the home page (status {status})")
    return collections.Counter(keys).most_common(1)[0][0]


def store_for_zip(key, zip_code):
    """Resolve a ZIP code to the nearest Target store ID."""
    query = urlencode({"key": key, "place": zip_code, "limit": 1,
                       "within": 100, "channel": "WEB", "page": "/s"})
    status, body = unlock(f"{REDSKY}nearby_stores_v1?{query}")
    try:
        store = json.loads(body)["data"]["nearby_stores"]["stores"][0]
    except (ValueError, KeyError, IndexError) as error:
        raise RuntimeError(f"no store for {zip_code} ({status})") from error
    return store["store_id"], store["location_name"]


def price_rows(key, tcin, store_id, zip_code):
    """Return one row per sellable variant (child TCIN) at one store."""
    query = urlencode({"key": key, "tcin": tcin, "store_id": store_id,
                       "pricing_store_id": store_id,
                       "has_pricing_store_id": "true", "channel": "WEB",
                       "page": f"/p/A-{tcin}"})
    status, body = unlock(f"{REDSKY}pdp_client_v1?{query}")
    error = {"tcin": tcin, "store_id": store_id, "zip": zip_code}
    try:
        product = json.loads(body)["data"]["product"]
    except (ValueError, KeyError, TypeError):
        return [{**error, "error": status or "no_response"}]
    # A child TCIN returns its parent. The parent price is a range, so
    # save each child's price on its own row.
    items = product.get("children") or [product]
    now = datetime.now(timezone.utc).isoformat(timespec="seconds")
    rows = []
    for item in items:
        price = item.get("price", {})
        priced_at = str(price.get("location_id"))
        rows.append({
            "tcin": item["tcin"],
            "parent_tcin": product["tcin"],
            "title": html.unescape(
                item["item"]["product_description"]["title"]),
            "zip": zip_code,
            "store_id": store_id,
            "priced_at": priced_at,
            "scope": "online" if priced_at == ONLINE_STORE else "store",
            "price": price.get("current_retail"),
            "regular_price": price.get("reg_retail"),
            "price_type": price.get("formatted_current_price_type"),
            "collected_at": now,
        })
    return rows


def valid(row):
    """Keep rows with a price from the requested or online store."""
    return (isinstance(row.get("price"), (int, float))
            and row["priced_at"] in (str(row["store_id"]), ONLINE_STORE))


if __name__ == "__main__":
    tcins = sys.argv[1].split(",")
    zips = sys.argv[2].split(",")
    key = web_api_key()
    stores = {z: store_for_zip(key, z) for z in zips}
    jobs = [(t, stores[z][0], z) for t in tcins for z in zips]
    with ThreadPoolExecutor(max_workers=8) as pool:
        results = list(pool.map(lambda job: price_rows(key, *job), jobs))
    # TCINs from one family return the same rows. Keep one row per
    # variant and store, and never let an error replace a row with a price.
    unique = {}
    for row in (r for batch in results for r in batch):
        slot = (row["tcin"], row["store_id"])
        if slot not in unique or "error" in unique[slot]:
            unique[slot] = row
    good = [r for r in unique.values() if valid(r)]
    bad = [r for r in unique.values() if not valid(r)]
    # Append, so every run adds to the price history.
    for name, batch in (("target_prices", good), ("target_rejects", bad)):
        with open(f"{name}.jsonl", "a") as out:
            out.writelines(json.dumps(row) + "\n" for row in batch)
    print(f"{len(good)} valid, {len(bad)} rejected, stores: {stores}")
With 2 input TCINs at 2 ZIP codes, the script produced 12 rows, because each request returned the whole variant family:
12 valid, 0 rejected, stores: {'10001': ('3412', 'Chelsea 23rd and 8th'), '99501': ('2371', 'Anchorage NE')}The first rows of target_prices.jsonl show the milk family at the Chelsea store:
{"tcin": "15078348", "parent_tcin": "94758333", "title": "Parmalat UHT 2% Reduced Fat Milk - 32 fl oz", "zip": "10001", "store_id": "3412", "priced_at": "3412", "scope": "store", "price": 3.89, "regular_price": 3.89, "price_type": "reg", "collected_at": "2026-09-27T05:34:07+00:00"}
{"tcin": "15078349", "parent_tcin": "94758333", "title": "Parmalat UHT Whole Milk - 32 fl oz", "zip": "10001", "store_id": "3412", "priced_at": "3412", "scope": "store", "price": 3.89, "regular_price": 3.89, "price_type": "reg", "collected_at": "2026-09-27T05:34:07+00:00"}
The run that produced the price table included 128 product and store pairs, 16 products at 8 stores, and wrote 800 rows with no rejections. This script repeated the run the next day in 97 seconds with 8 workers, and all 800 prices matched the first run. The script also keeps a target_rejects.jsonl file for any pair that needs a retry.
The Web Unlocker API reports Target’s own result in the x-brd-status-code and x-brd-error headers, so the script reads both. For a removed product, x-brd-error shows Target’s 404, and the script records it without retrying.
Each design choice handles a failure that can happen in a Target scraper:
- Key from the page: the scraper keeps working after a key rotation, as long as the page still embeds the key as
apiKey. - One row per child: your table never stores a parent range.
scopecolumn: an online price is labeledonline, so it can’t be mistaken for a store price.- Block check: a HUMAN block in HTML or JSON is logged as
blocked, whatever the status code. - No overwrites: an error for one variant never replaces another variant’s row that has a price.
- Rejects file: rows without a valid store price or online price are saved for a retry pass, and removed products keep their
404.
The code depends on pdp_client_v1 and nearby_stores_v1, so send a daily canary request to both and alert when the response schema changes. Our guide to retrying failed Python requests explains backoff in more depth.
To run the same code on residential proxies, send a proxied requests.get() in unlock() and treat a plain 404 as a removed product. The rest of the script stays the same. With residential proxies, you control the client and user agent, so test them and each endpoint against Target before you scale.
Collect Target products with the Target Scraper API
The Target Scraper API is the Web Scraper API‘s scraper for Target. You send product URLs and ZIP codes, and it returns structured records with fields such as price, variants, ratings, specifications, and seller. Bright Data maintains the parsing and the endpoints, so your code only normalizes the records. Bright Data also offers a Target Price Scraper, a Target Reviews Scraper, and a Target Image Scraper for narrower jobs.
The console shows the scraper’s input fields above its synchronous and asynchronous modes. The fields are a URL, an all_variations flag, and a ZIP code:
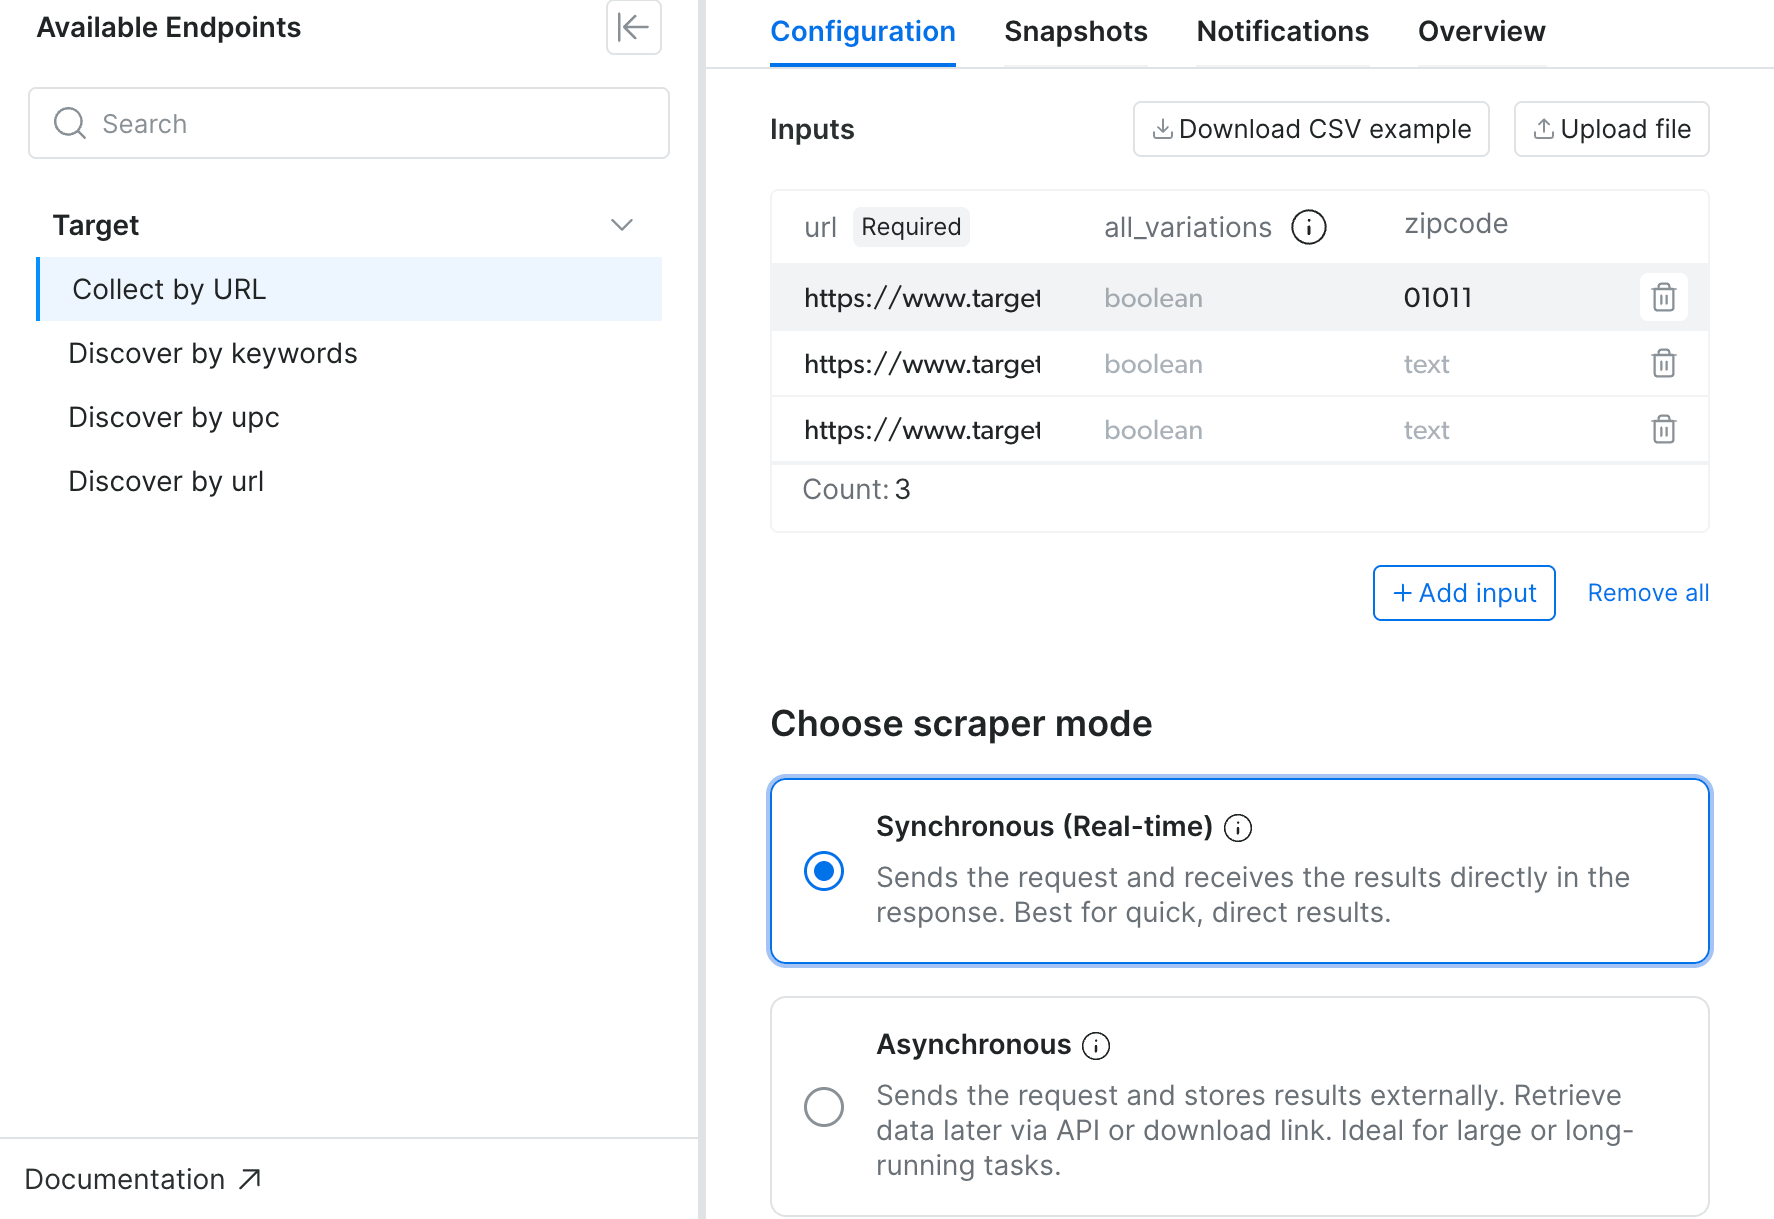
Each input row lists a single product and can add a ZIP code, which sets the location for the record’s price.
The Web Scraper API bills only for delivered records. The Web Scraper API pricing page lists current rates, and the free tier includes 5,000 requests a month with no credit card required. For a client library, install the Bright Data Python SDK with pip install brightdata-sdk.
The script below starts an asynchronous job, waits for it, downloads the records, and normalizes them:
"""Collect Target product records by URL and ZIP code with the Web Scraper API.

Usage:
    export BRIGHTDATA_API_KEY=...
    python target_scraper_api.py inputs.csv   # columns: url,zipcode
"""
import csv
import json
import os
import re
import sys
import time

import requests

API = "https://api.brightdata.com/datasets/v3"
DATASET_ID = "gd_ltppk5mx2lp0v1k0vo"  # Target products scraper
HEADERS = {"Authorization": f"Bearer {os.environ['BRIGHTDATA_API_KEY']}"}


def trigger(inputs):
    """Start an asynchronous collection and return its snapshot ID."""
    r = requests.post(
        f"{API}/trigger",
        headers=HEADERS,
        params={"dataset_id": DATASET_ID, "include_errors": "true"},
        json=inputs,
        timeout=60,
    )
    r.raise_for_status()
    return r.json()["snapshot_id"]


def wait(snapshot_id, poll_seconds=15, max_minutes=60):
    """Poll the snapshot until it is ready and return its progress record."""
    deadline = time.time() + max_minutes * 60
    while time.time() < deadline:
        progress = requests.get(f"{API}/progress/{snapshot_id}",
                                headers=HEADERS, timeout=30).json()
        if progress["status"] in ("ready", "failed"):
            return progress
        time.sleep(poll_seconds)
    raise TimeoutError(snapshot_id)


def download(snapshot_id):
    """Download all records, including error records, as a list."""
    r = requests.get(f"{API}/snapshot/{snapshot_id}",
                     headers=HEADERS, params={"format": "json"}, timeout=300)
    r.raise_for_status()
    return r.json()


def normalize(record):
    """Map one record to a flat row, or return None for an error record."""
    if record.get("error_code"):
        return None
    price = record.get("final_price")
    if price is None and record.get("price_range"):
        # A record can have its price in price_range, like "$24.99".
        match = re.fullmatch(r"\$([\d,]+\.\d{2})", record["price_range"])
        price = float(match.group(1).replace(",", "")) if match else None
    origin = record.get("discovery_input") or record.get("input") or {}
    reviewed = bool(record.get("reviews_count"))  # rating 0 means unrated
    url_tcin = re.search(r"/A-(\d+)", record.get("url") or "")
    return {
        "tcin": url_tcin.group(1) if url_tcin else record.get("tcin_id"),
        "parent_tcin": record.get("group_id"),
        "title": record.get("title"),
        "zipcode": origin.get("zipcode") or None,
        "price": price,
        "initial_price": record.get("initial_price"),
        "available": record.get("is_available"),
        "rating": record.get("rating") if reviewed else None,
        "reviews_count": record.get("reviews_count"),
        "collected_at": record.get("timestamp"),
    }


if __name__ == "__main__":
    with open(sys.argv[1], newline="") as f:
        inputs = [{"url": row["url"], "zipcode": row["zipcode"]}
                  for row in csv.DictReader(f)]
    snapshot_id = trigger(inputs)
    progress = wait(snapshot_id)
    records = download(snapshot_id)
    rows = [row for row in map(normalize, records) if row]
    with open("target_records.jsonl", "w") as out:
        out.writelines(json.dumps(row) + "\n" for row in rows)
    print(f"snapshot {snapshot_id}: {len(rows)} rows, "
          f"errors: {progress.get('error_codes', {})}")
The input file has the milk at 2 ZIP codes, plus a nationally priced LEGO set and a 112-count Tide pack, both in Anchorage. The last row is a product that Target has removed:
url,zipcode
https://www.target.com/p/-/A-15078349,10001
https://www.target.com/p/-/A-15078349,60601
https://www.target.com/p/-/A-86216189,99501
https://www.target.com/p/-/A-84114518,99501
https://www.target.com/p/petal-and-pup-skarlett-top/-/A-1002219928,10001
The job returned 4 records and flagged the removed product as dead_page:
snapshot sd_muifuppi1d0g830zfd: 4 rows, errors: {'dead_page': 1}All 4 prices matched our scraper. The Market Pantry coffee and the Tide 31-count pack varied in price by location. We compared them with our scraper at all 8 ZIP codes, at the same time:
| Product | Product and ZIP code pairs | Distinct prices | Matched our scraper |
|---|---|---|---|
| Market Pantry Classic Roast, 25.9 oz | 8 | 7 | 8 of 8 |
| Tide Original pods, 31 count | 8 | 5 | 8 of 8 |
| Milk, LEGO set, and Tide 112 count (input file above) | 4 | Not applicable | 4 of 4 |
All 20 product and ZIP code pairs matched our scraper’s price at the nearest store. A day later, a rerun of the input file returned Chicago’s new $2.97 sale price, which our scraper confirmed.
Each record includes the ZIP code used for its price and an availability flag for that ZIP code. The normalizer maps these fields:
- Parent ID:
group_idhas the parent TCIN. - Origin:
inputhas a collected record’s URL and ZIP code.discovery_inputhas the keyword or category URL, and any ZIP code, when the Target Scraper API found the product itself. - Price: the normalizer takes the price from
final_priceorprice_range. - Unrated products: a
ratingof 0 with 0 reviews means the product has no rating.
Choose synchronous or asynchronous mode
The synchronous /scrape endpoint returns results in the response for quick jobs and returns a snapshot_id to poll for longer jobs. The synchronous requests docs give the current time limit. Use /trigger for scheduled batches. You poll a snapshot_id from either endpoint the same way.
For recurring jobs, set the API to deliver the results. The delivery options include webhooks and cloud storage such as Amazon S3, Google Cloud Storage, and Microsoft Azure. On /scrape, set limit_per_input in the request body to limit the records per input, as the documentation shows.
Discover products by keyword or category
The Target Scraper API can also find products for you:
- Keyword: “dog treats” and “shirts” with
limit_per_inputset to 20 returned 40 records with no errors. - Category URL: 2 category pages, each with a ZIP code, returned 40 records.
The normalizer above already reads discovery_input, so the same code processes discovered records.
Use the Browser API for sessions and debugging
The Browser API runs a remote Chrome that you drive with Playwright or Puppeteer over the Chrome DevTools Protocol (CDP), or with Selenium over WebDriver. On Target, it loaded the product page as a full browser session, including HUMAN’s script. Because it loads the whole page, the Browser API works well for capturing the network traffic after Target changes its front end.
The Bright Data MCP Server serves tools to AI agents over the Model Context Protocol (MCP). Its browser tools give agents the same remote browser for workflows that click or type on a page.
The Browser API bills per GB, as the Browser API pricing page shows. Blocking images and trackers helps keep each session small. Once a capture shows the requests you need, the Web Unlocker API can send them directly, without loading the page.
Without a stored location cookie, Target assigned each of our US browser sessions a store near the exit IP. The Browser API’s Proxy.setLocation command, sent over CDP, selects an exit IP near coordinates that you choose. To run the script, install playwright and set a Browser API zone’s connection string in the BROWSER_API_WSS environment variable, as the Browser API quickstart shows:
import asyncio
import os

from playwright.async_api import async_playwright

# wss://brd-customer-<id>-zone-<zone>:<password>@brd.superproxy.io:9222
WSS = os.environ["BROWSER_API_WSS"]


async def main():
    async with async_playwright() as pw:
        browser = await pw.chromium.connect_over_cdp(WSS)
        page = await browser.contexts[0].new_page()
        cdp = await page.context.new_cdp_session(page)
        # Exit near Manhattan, so Target geolocates the session there.
        await cdp.send("Proxy.setLocation", {
            "lat": 40.7506, "lon": -73.9972, "distance": 10, "strict": True,
        })
        await page.goto("https://www.target.com/p/-/A-15078349",
                        wait_until="domcontentloaded", timeout=120_000)
        # The page renders the price twice, and one copy stays hidden.
        price = page.locator('[data-test="product-price"]').first
        await price.wait_for(state="attached", timeout=60_000)
        cookies = await page.context.cookies("https://www.target.com")
        store = {c["name"]: c["value"] for c in cookies}.get("fiatsCookie")
        print(store, await price.text_content())
        await browser.close()

asyncio.run(main())
Across 3 runs with the same coordinates, Target assigned 3 different New York stores near those coordinates. The fiatsCookie value listed the store ID (DSI), name (DSN), and ZIP code (DSZ):
DSI_2475|DSN_Bronx%20Terminal|DSZ_10451 $3.59
DSI_3284|DSN_Lower%20East%20Side%20Grand%20and%20Clinton|DSZ_10002 $3.99
DSI_3394|DSN_Upper%20West%20Side%2098th%20and%20Columbus|DSZ_10025 $3.99
Because each session got a nearby store, this setup is useful for sampling prices across a metropolitan area.
Buy the Target Dataset for catalog backfill
The Target Dataset offers pre-collected Target product records that you can filter and buy without running a scraper. It works well for a catalog backfill that needs many rows at once.
The dataset page lists the current record count, fields, and pricing. In the Dataset Marketplace, you can filter records and preview a sample before you buy:
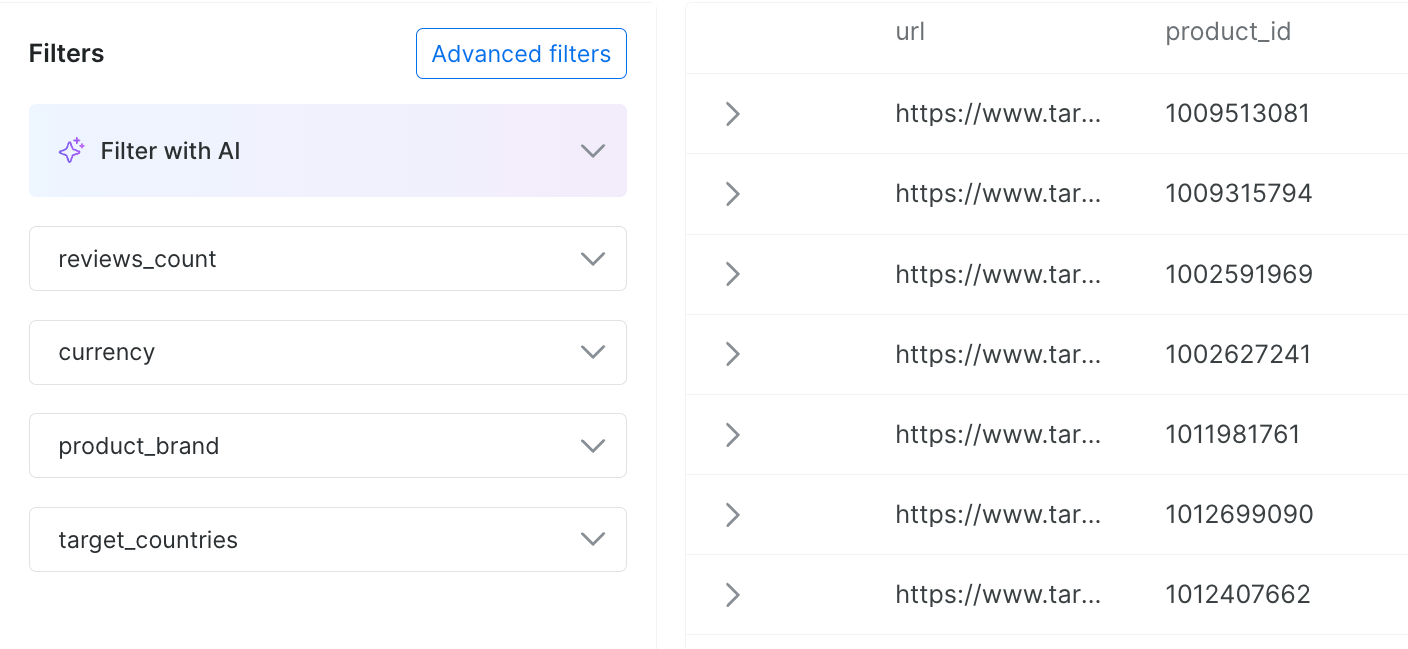
The Target dataset’s field filters and a sample of its records.
Before loading, map the records to your own schema:
- Product IDs: use the TCIN in each record’s URL as your table key, the same ID the scrapers above use.
- Ratings: a
ratingof 0 with 0 reviews means the product has no rating yet.
Choose the approach by location, volume, and refresh rate
Options with more control need more maintenance, which grows with how often Target changes its pages and endpoints. Teams that want ready-made Target dashboards can use the Target Price Tracker or Target Inventory Tracker. For other retailers, see our guide to ecommerce web scraping. Each approach bills by its own unit, and each product’s pricing page lists current rates:
| Approach | Billed by | Scope of 1 call or record | Best fit |
|---|---|---|---|
| Your code with Web Unlocker API | Successful request | 1 variant family at 1 store ID | Store IDs and per-channel stock |
| Your code with residential proxies | GB of traffic | 1 variant family at 1 store ID, about 15 KB compressed in our tests | Low cost per call, with full control of the client |
| Target Scraper API | Delivered record | 1 product at 1 ZIP code | Recurring collection with parsing and maintenance handled for you |
| Browser API | GB of traffic | 1 full browser session | Sessions and debugging |
| Target Dataset | Record | 1 pre-collected product record | Backfill and catalog research |
Pick by how you track locations. If you track by ZIP code, the Target Scraper API matched the nearest store’s price in our tests, and Bright Data maintains it for you. If you track store IDs and per-channel stock, run your own code on the Web Unlocker API or residential proxies. For a backfill, choose the dataset, as our comparison of datasets and web scraping APIs explains.
Before you pick, estimate the monthly volume by multiplying products by stores, by refreshes per day, and by 30. Tracking 5K products at 50 stores once a day means 7.5M requests or records a month. Per-channel stock adds 1 product_fulfillment_v1 request per TCIN and store. Multiply the total by the per-unit rate on the pricing page, where monthly plans lower the rate.
Your own code can send fewer requests than this estimate, in 2 ways. Of our 16 test products, 4 had the same price at every store and needed only 1 request per refresh. One product API request also returns a whole variant family, so 128 product and store pairs produced 800 rows in our run.
On residential proxies, 7.5M gzip-compressed pdp_client_v1 calls would transfer about 110 GB. As the residential proxy pricing page notes, billing counts headers and bodies, which averaged 15 KB per call for us. The billing FAQ explains how traffic is measured. Request compressed responses, because the same pdp_client_v1 bodies averaged 134 KB without compression and 14 KB with gzip.
The Web Unlocker API handles the unblocking for you and bills only successful requests. In our IP and client test, it passed every call on US exit IPs without client tuning. You can also use both the Web Unlocker API and residential proxies. Send each endpoint’s requests through the option that fits their volume, and move an endpoint to the Web Unlocker API when Target’s bot check changes.
Validate and monitor Target collection
A block that is_human_block() detects appears as an error. A wrong-store price that looks valid appears as data, so no error flags it. The checks below help detect failures that can look like valid data or waste requests:
| Check | Where to look | Detects |
|---|---|---|
| Price is a number above zero | price |
Missing prices and ranges |
| Price came from the store you requested, or is labeled online | location_id, scope |
Wrong-store prices |
| Row is a child TCIN | tcin, children |
Parent-level ranges |
| Body has the expected JSON schema and no HUMAN block | Response body | HTML and JSON block responses (HTTP 435) |
| Product still exists | 404, dead_page |
Dead URLs retried on every run |
| Price change since the last run is within your threshold | Price history | Misparsed or wrong prices |
Run the checks on every batch, and save each row with its TCIN, store ID, and collection time, so the history grows. Count failures by reason, such as a block, a wrong store, a removed product, or a timeout. One overall failure rate can hide a rise in failures for one reason, so alert when the rate for any reason rises above normal. Track cost per successful record as well, so you can compare approaches with the same measure.
Final thoughts
Target shows its product data publicly, but a price can depend on the store, the variant, and the time you collect it. In our tests, online prices from location 3991, parent price ranges, and JSON block responses all looked like valid data. Keep the store ID, the variant, and the request status with each row, and run a daily canary against every endpoint you depend on.
The Web Unlocker API handles the unblocking and your code controls stores and channels, while the Target Scraper API also handles parsing and maintenance. To choose, run a sample of your products and ZIP codes on both through the free tier, which includes 5,000 requests a month with no credit card required, and compare the prices.
FAQ
Does Target have a public product API?
No, Target’s developer portal is only for Target employees, Target Plus sellers, and partners. The website calls internal JSON APIs on redsky.target.com with an API key from its pages, and those endpoints can change without notice. Bright Data’s Target Scraper API returns product records from a URL and a ZIP code.
How do you get Target product prices by store?
Call Target’s product API with a store ID and its public API key to get every variant’s price at that store. Another endpoint maps a ZIP code to the nearest store ID. A location ID of 3991 marks Target’s online price, not a store price. Bright Data’s Target Scraper API returns prices for the ZIP code you send.
Can you track Target inventory by store?
Yes, in our tests, Target’s product_fulfillment_v1 endpoint returned a unit count and the shipping, pickup, and in-store status for the requested store. A New York store had 0 units and a nearby store had 6, while shipping showed the item in stock. Save stock per store and per channel.
How much does it cost to scrape Target data?
Cost grows with the number of products, stores, and daily refreshes. Tracking 5K products at 50 stores daily means 7.5M requests or records a month. Bright Data bills Web Scraper API records on delivery, Web Unlocker API requests on success, and residential proxies per GB. Each pricing page lists current rates.
How do you scrape Target products for free?
Bright Data’s free tier includes 5,000 requests a month with no credit card required, and it covers both the Target Scraper API and the Web Unlocker API, so you can test prices on your own products. Plain HTTP requests are free, but Target’s bot check blocked clients with default settings from US IPs in our tests.


Technical Writer
 5 years experience
Satyam Tripathi helps SaaS and data startups turn complex tech into actionable content, boosting developer adoption and user understanding.