Scraping ZoomInfo, a B2B data platform, means collecting the company profiles it shows without a login. Sales and data teams use ZoomInfo company data to enrich CRM accounts with industry, headcount, revenue, and technology fields.
Without a referrer from another site, all 32 first requests we sent from new residential IPs got ZoomInfo’s “Press & Hold” challenge page. In our tests, IPs that got a first page were blocked after a median of 3 pages.
This guide shows you how to get company pages at scale, match accounts to profiles, extract data, and decide when to buy a ZoomInfo scraper.
TL;DR
- We measured about 3 pages per IP, so collecting 100K ZoomInfo pages would need more than 33K sessions. By the 5th request, 12 of 14 sessions got a Cloudflare 429.
- ZoomInfo held duplicate company profiles. A search for one domain returned 3 company IDs, and a duplicate listed a different headcount and revenue.
- ZoomInfo’s embedded JSON held unrounded numbers. Web Unlocker returned Aviagen’s page with 6,776 employees in its JSON, while the profile showed 5K to 10K.
- Bright Data’s ZoomInfo Scraper API handles unblocking for you. From 1 directory URL, it returned 45 structured company records.
What ZoomInfo shows without a login
ZoomInfo’s public pages gave detailed company data and basic data about people. Emails, direct phone numbers, full contact lists, and the full list of technologies required an account. Our logged-out scraper collected firmographics such as industry and headcount. The public site had these main page types:
| Page type | URL pattern | What it can show |
|---|---|---|
| Company profile | /c/{slug}/{id} |
Industry, headcount, revenue estimate, headquarters, phone, website, SIC and NAICS codes, some technologies, funding, and employee counts by management level |
| Company directory | /companies-search/{filters} |
9 companies per page, filtered by location and industry |
| Person profile | /p/{name}/{id} |
A name, a job title, and an employer |
| Other pages | /pic/, /hq/, /tech/, /executives/, /competitors/ |
Employee directories, headquarters details, companies that use a technology, executives, and competitors |
Person pages, employee directories, and the lists of people on company pages contain personal data, which GDPR can cover. Logged-in pages are subject to ZoomInfo’s terms of service, which account holders accept. Our scripts collect public company records only and drop person fields.
Why your first request to ZoomInfo gets blocked
ZoomInfo ran 2 anti-bot systems in front of its pages, and each blocked response showed which system sent it. A proxy between your scraper and ZoomInfo can also change the TLS fingerprint that those systems see. In our tests, the first request of a session needed an external referrer, but later requests that carried the session’s cookies didn’t need one.
Each anti-bot system has its own signature
Requests to zoominfo.com pages, including directory pages, were routed through Cloudflare and checked by HUMAN Security, which merged with PerimeterX in 2022. Both systems marked their blocked responses with distinct signatures, and a real company page had a signature too:
| Response from | Status and page | Signal to branch on |
|---|---|---|
| HUMAN Security | 403, “Access to this page has been denied” with a “Press & Hold” button | The 403 status and px-captcha in the body |
| Cloudflare | 429, “Just a moment…” | The cf-mitigated: challenge response header |
| ZoomInfo’s origin | 200, the company page | <script id="ng-state"> with company data |
Branch on these signals, not on page titles. Company pages also contained _pxAppId, so its presence doesn’t mean that HUMAN blocked the request. The Cloudflare docs say that every type of challenge page carries the cf-mitigated: challenge header.
The embedded JSON in the ng-state script marked real company pages most reliably. Treat a response as successful only when it carries this JSON.
What your proxy does to your TLS fingerprint
We used a Bright Data residential proxy zone, a named proxy configuration. The zone opened its own TLS connection to the site. We sent requests from 3 clients to tls.peet.ws, a TLS fingerprint checker, first without a proxy and then through that zone:
| Client | JA4 without a proxy | JA4 through the proxy |
|---|---|---|
| curl_cffi impersonating Chrome 150 | t13d1516h2_8daaf6152771_806a8c22fdea |
t13d1516h2_8daaf6152771_d8a2da3f94cd |
| curl_cffi impersonating Firefox 147 | t13d1717h2_5b57614c22b0_3cbfd9057e0d |
t13d1516h2_8daaf6152771_02713d6af862 |
| System curl 8.7.1 (LibreSSL) | t13d497h2_0d8feac7bc37_7395dae3b2f3 |
t13d1516h2_8daaf6152771_02713d6af862 |
Through the proxy, all 3 JA4 fingerprints started with t13d1516h2_8daaf6152771, the same first 2 parts as curl_cffi impersonating Chrome. Those parts encode TLS 1.3, 15 cipher suites, 16 extensions, and HTTP/2. So the proxy presented a Chrome-like TLS fingerprint for all 3 clients. Chrome impersonation also kept its HTTP/2 fingerprint through the proxy, so use it to make both the TLS and HTTP/2 fingerprints look like Chrome’s.
Check which hop terminates TLS before you spend time on TLS impersonation. If the proxy only tunnels your connection, the site sees your client’s own handshake. In both cases, the TCP connection starts at the exit node, whose SYN packet carries its own TTL, window size, and option order. A macOS User-Agent can arrive over a Windows TCP stack, and an anti-bot system that reads TCP fingerprints can flag that mismatch.
How ZoomInfo judges the first request
HUMAN’s challenge page ran a sensor script in the browser, and the script set risk cookies such as _px3. A scraper’s first request carries none of those cookies, so the site can judge only the request and the connection it arrives on.
We sent 32 cookieless company-page requests with no referrer from new US residential IPs, and each of 4 clients sent 8. The clients were system curl, curl with a full set of Chrome headers, curl_cffi impersonating Chrome, and httpx over HTTP/2. All 32 got HUMAN’s 403 and this “Press & Hold” page:
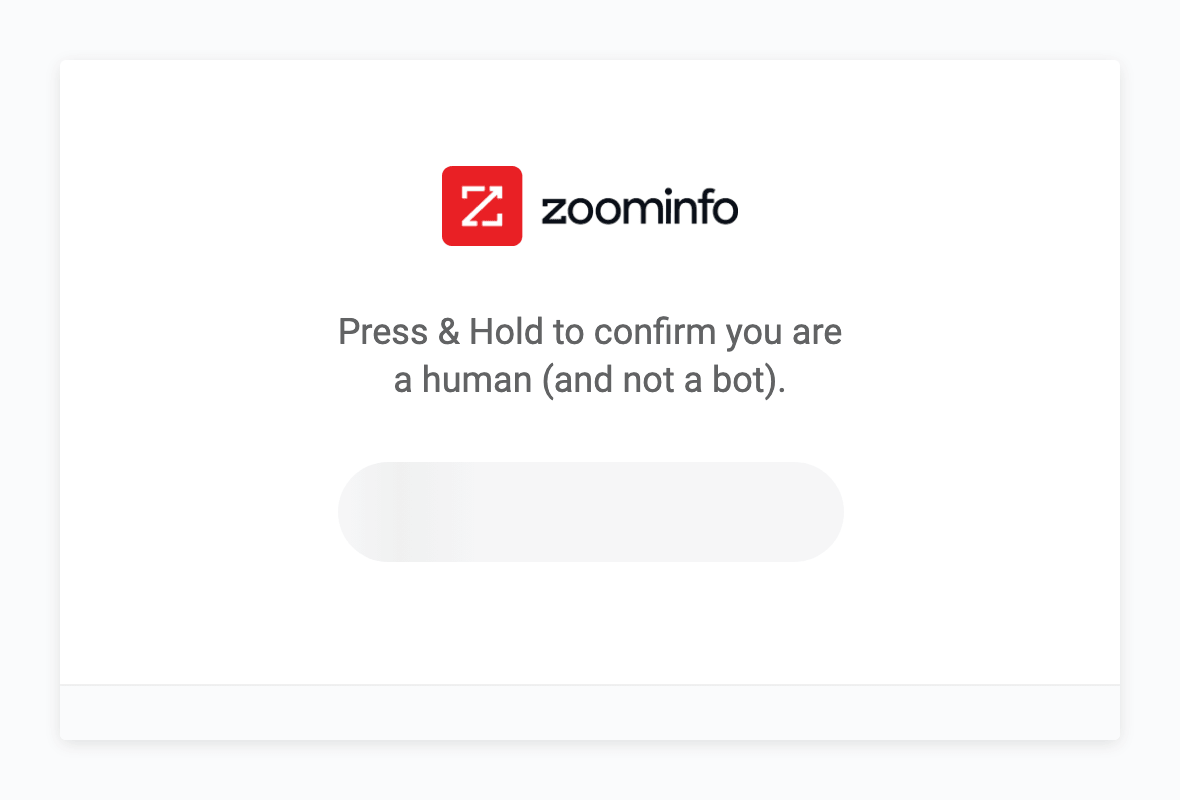
ZoomInfo returned this challenge page to a cookieless request with no referrer.
Through the proxy zone, Cloudflare saw the proxy’s TLS handshake for all 4 clients. From a home connection, Cloudflare saw each client’s own handshake. The first requests from all 6 clients we tried on that connection got the same 403. So for our first requests with no referrer, the TLS handshake didn’t change the result.
An external referrer changed the result. Cookieless requests from curl_cffi impersonating Chrome succeeded 16 of 18 times when their Referer header named another site. The referrers were Google, Bing, DuckDuckGo, LinkedIn, and example.com. Of the 2 failed requests, 1 got an HTTP 502.
Cookieless requests with a sec-fetch-site: cross-site header but no Referer header were blocked 3 of 3 times. Cookieless requests with a same-origin referrer were also blocked 3 of 3 times. In our tests, a first request needed to look like a click from another site, such as a search result.
With a Google referrer, the success rate also changed with concurrency and with the User-Agent:
- At 6 concurrent requests through rotating IPs, 14 of 45 curl_cffi requests succeeded.
- With 1 request at a time and a 6-second pause after each, 13 of 20 requests succeeded, and 3 got a redirect.
- Requests with a
curlorpython-requestsUser-Agent were blocked 29 of 29 times. - At 6 concurrent requests, 4 of 15 system curl requests with a Chrome User-Agent succeeded.
Even with 1 request at a time, 7 of 20 requests failed, so a do-it-yourself scraper still needs retries, new sessions, and monitoring.
How many ZoomInfo pages each IP gets
Once a session got its first page, ZoomInfo served only a few more pages to the same IP. Each session kept 1 residential IP through the proxy’s sticky-session setting and sent a Google referrer on the first request. Then we counted company pages until the first blocked request.
Across 14 sessions that got a first page, the median session loaded 3 company pages before its first blocked request. By the 5th request, 12 of the 14 had received a Cloudflare 429. After the first 429, every later request in that session received a 429 too. None of the 429s we inspected carried a Retry-After header.
In the sessions below, a delay of 2 or 15 seconds between pages didn’t change the count:
| Client | Delay between pages | Result by request |
|---|---|---|
| HTTP client | 15 seconds | OK, OK, then 429 on the next 8 |
| HTTP client | 15 seconds | OK, OK, OK, then 429 on the next 7 |
| HTTP client | 2 seconds | OK, OK, OK, then 429 on the next 7 |
| Real Chrome | Page load time | OK, OK, OK, then “Just a moment…” on the next 5 |
In the Chrome session, headful Chrome ran with navigator.webdriver hidden, through a separate sticky session. It loaded the first 3 pages in 6 to 9 seconds each. On each of the next 5 pages, Cloudflare’s challenge was still showing after about 15 seconds, although the browser had a clearance cookie, cf_clearance.
In sessions that kept the first response’s cookies, later requests didn’t need an external referrer. A later request could name the previous ZoomInfo page as its referrer, as a browser does.
Clearing the cookies didn’t reset the count. Of 4 sessions that cleared them before every request and sent a Google referrer each time, 3 got a 429 after 3 pages. So the limit was tied to the IP, not to the cookies.
Forum threads say anti-bot cookies are bound to the exit IP, but we couldn’t reproduce that with the cookies our HTTP client received. We moved a cookie jar with _pxhd, _cfuvid, and contextual_signup_test from one IP to a new one, and 4 of 5 requests succeeded. Cookieless requests from other new IPs at the same time succeeded 2 of 5 times. Both groups sent a Google referrer.
This diagram shows the path from a scraper to a company page and the response from each anti-bot system:
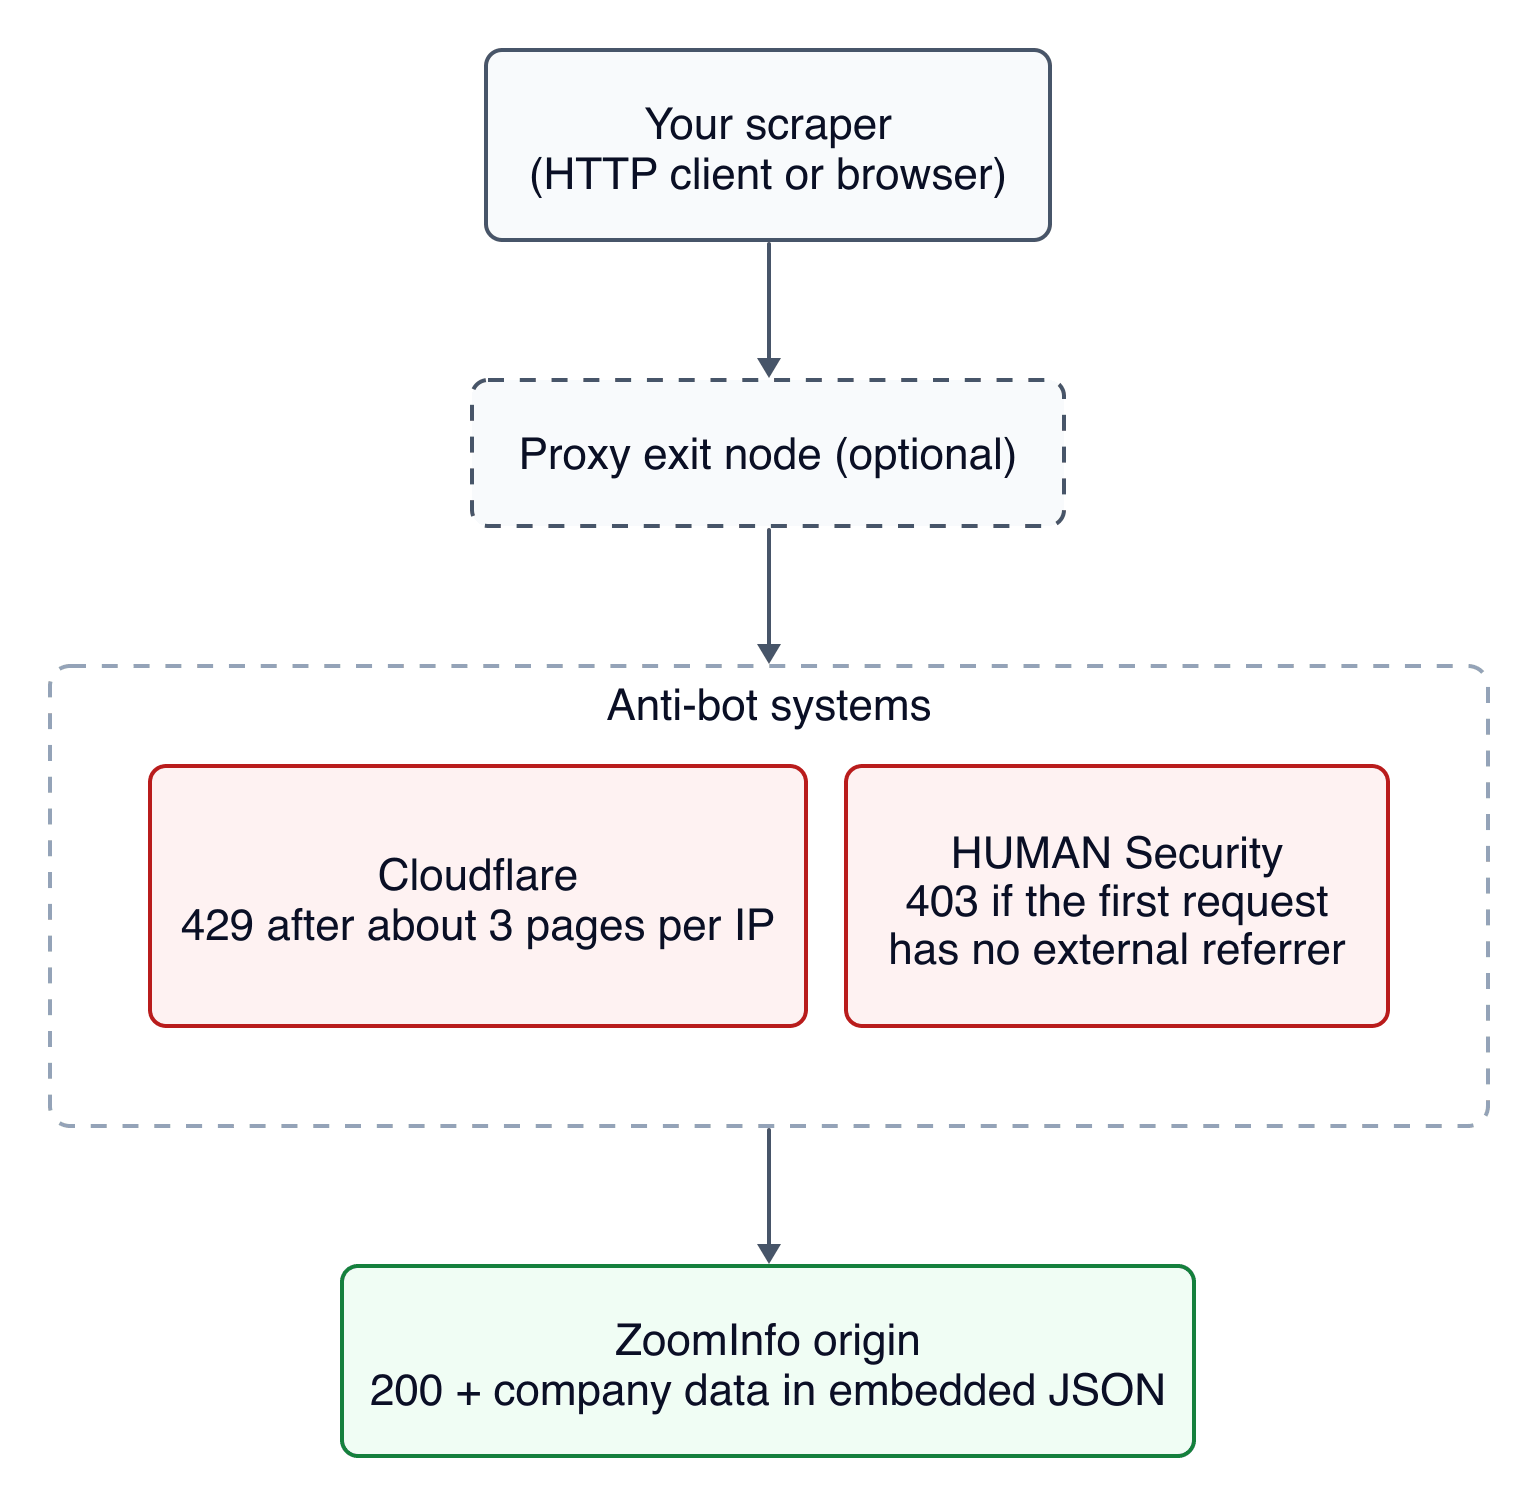
A blocked request returns no company data, so a higher block rate means more requests per record.
At about 3 pages per IP, collecting 100K company pages a month would need more than 33K sessions that get a first page. Every blocked first request means one more session to start. Bright Data’s Web Unlocker handles these sessions for you.
Extract the company data from a ZoomInfo page
ZoomInfo’s company pages were server-rendered Angular applications. The server wrote the page’s data into <script id="ng-state" type="application/json">. That script comes from Angular’s TransferState API, which lets the browser reuse the data without fetching it again. For Walmart, the script held 84 KB of JSON, and its pageData object had 42 keys.
The embedded JSON held more precise numbers than the visible page. Aviagen’s profile showed its headcount as a range and its revenue rounded to 1 decimal place:
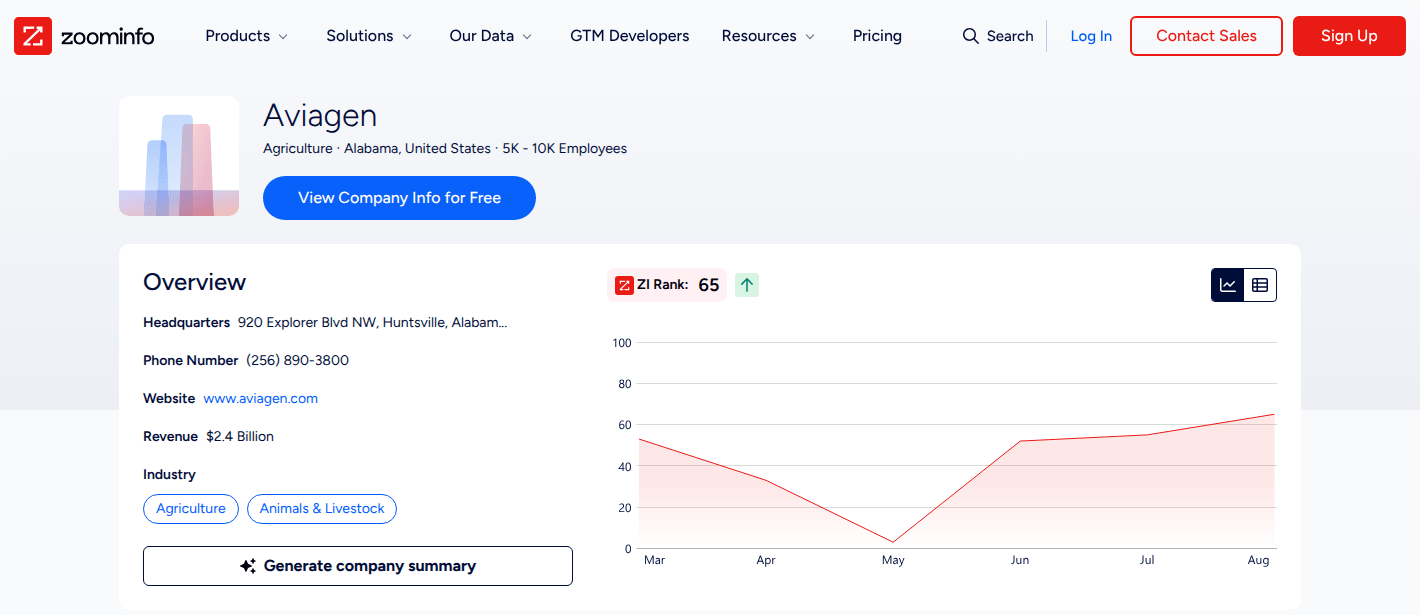
Aviagen’s visible profile showed “5K – 10K” employees and “$2.4 Billion” in revenue.
The same page’s JSON held the unrounded numbers:
<script id="ng-state" type="application/json">
{"pageData": {
  "companyId": 9047889,
  "name": "Aviagen",
  "numberOfEmployees": "6776",
  "about": {"revenue": "2413885", ...},
  ...
}}
</script>
ZoomInfo stored revenue in thousands of dollars, so Aviagen’s 2413885 means $2,413,885,000. Compare one company’s embedded JSON with its visible profile to confirm the multiplier.
Other company pages also showed ranges, while their embedded JSON held unrounded numbers. The FAQ block on the Walmart page said “10K+” employees, while the JSON held 2,100,000. For 5 small companies shown as “<$5 Million” in revenue, the JSON estimates ranged from $366,000 to $4,474,000.
Some fields changed between fetches even when the company data stayed the same. Across 2 fetches of the Walmart page, minutes apart, exactly 3 pageData keys differed:
picheld a partly different set of 9 employees.copilotContentheld the same 10 marketing templates in a new order.intentsheld 5 entries, 2 of which carried arandomLocationvalue, and both values changed.
With these fields in the page, hashing whole pages can make unchanged companies look changed on every crawl. This parser, saved as parse_zoominfo.py, reads the embedded JSON, converts the units, keeps IDs as strings, and hashes only company fields:
import hashlib
import json
import re
from urllib.parse import urljoin

STATE = re.compile(r'<script[^>]*id="ng-state"[^>]*>(.*?)</script>', re.S)
LD_JSON = re.compile(
    r'<script[^>]*type="application/ld\+json"[^>]*>(.*?)</script>', re.S
)


def _state(html: str) -> dict | None:
    match = STATE.search(html)
    return json.loads(match.group(1)) if match else None


def _int(value) -> int | None:
    return int(value) if value and str(value).isdigit() else None


def _zi_rank(html: str) -> int | None:
    for block in LD_JSON.findall(html):
        data = json.loads(block)
        if isinstance(data, dict) and data.get("@type") == "Organization":
            for prop in data.get("additionalProperty", []):
                if prop.get("name") == "ZI Rank":
                    return prop.get("value")
    return None


def parse_company(html: str) -> dict | None:
    state = _state(html)
    page = (state or {}).get("pageData") or {}
    if not page.get("companyId"):
        return None  # a challenge page, an empty shell, or another template
    about = page.get("about") or {}
    overview = page.get("overview") or {}
    revenue_k = _int(about.get("revenue"))  # stored in thousands of USD
    domain = (page.get("url") or "").lower().removeprefix("www.")
    return {
        "id": str(page["companyId"]),  # strings: person IDs overflow int32
        "name": page.get("name"),
        "domain": domain or None,
        "employees": _int(page.get("numberOfEmployees")),  # unrounded count
        "revenue_usd": revenue_k * 1000 if revenue_k is not None else None,
        "founded": _int(page.get("foundingYear")),
        "ticker": overview.get("ticker"),
        "sic": overview.get("sic") or [],
        "naics": overview.get("naics") or [],
        "industries": [i["name"] for i in about.get("industries") or []],
        "hq": page.get("address"),
        "phone": about.get("phone"),
        "tech_used": sorted(t["name"] for t in page.get("techUsed") or []),
        "management_levels": {
            m["title"]: m["value"] for m in page.get("mgtl") or []
        },
        "zi_rank": _zi_rank(html),
        # Person fields (executives, pic, hierarchyOrgChart) are excluded.
    }


# intents, pic, and copilotContent changed between 2 fetches of the
# same page, so the hash excludes them.
STABLE = ("name", "domain", "employees", "revenue_usd", "industries",
          "hq", "phone", "sic", "naics", "ticker", "tech_used")


def content_hash(record: dict) -> str:
    stable = json.dumps({k: record.get(k) for k in STABLE}, sort_keys=True)
    return hashlib.sha256(stable.encode()).hexdigest()[:16]
parse_company returns None for any page without company data, such as a challenge page or an empty page. On the 2 Walmart fetches, content_hash returned the same value, b4ffe1810bbb1c8c, while the SHA-256 of their raw HTML differed.
Find ZoomInfo company URLs at scale
ZoomInfo’s robots.txt listed 1 sitemap, which included marketing pages only. We found no sitemap for company or person pages, so you can build the URL list from 3 other sources.
Directory pages
Each /companies-search/ URL listed the companies that matched its location and industry filters, and a pageNum query parameter selected the page. The Alabama agriculture listing showed a total of 1,962 companies. Pages 1 to 5 each returned the page we requested. Requests for pages 6 and 10 returned HTTP 200 with page 1’s companies and pageNum: 1 in the embedded JSON.
Here’s the first page of that listing:
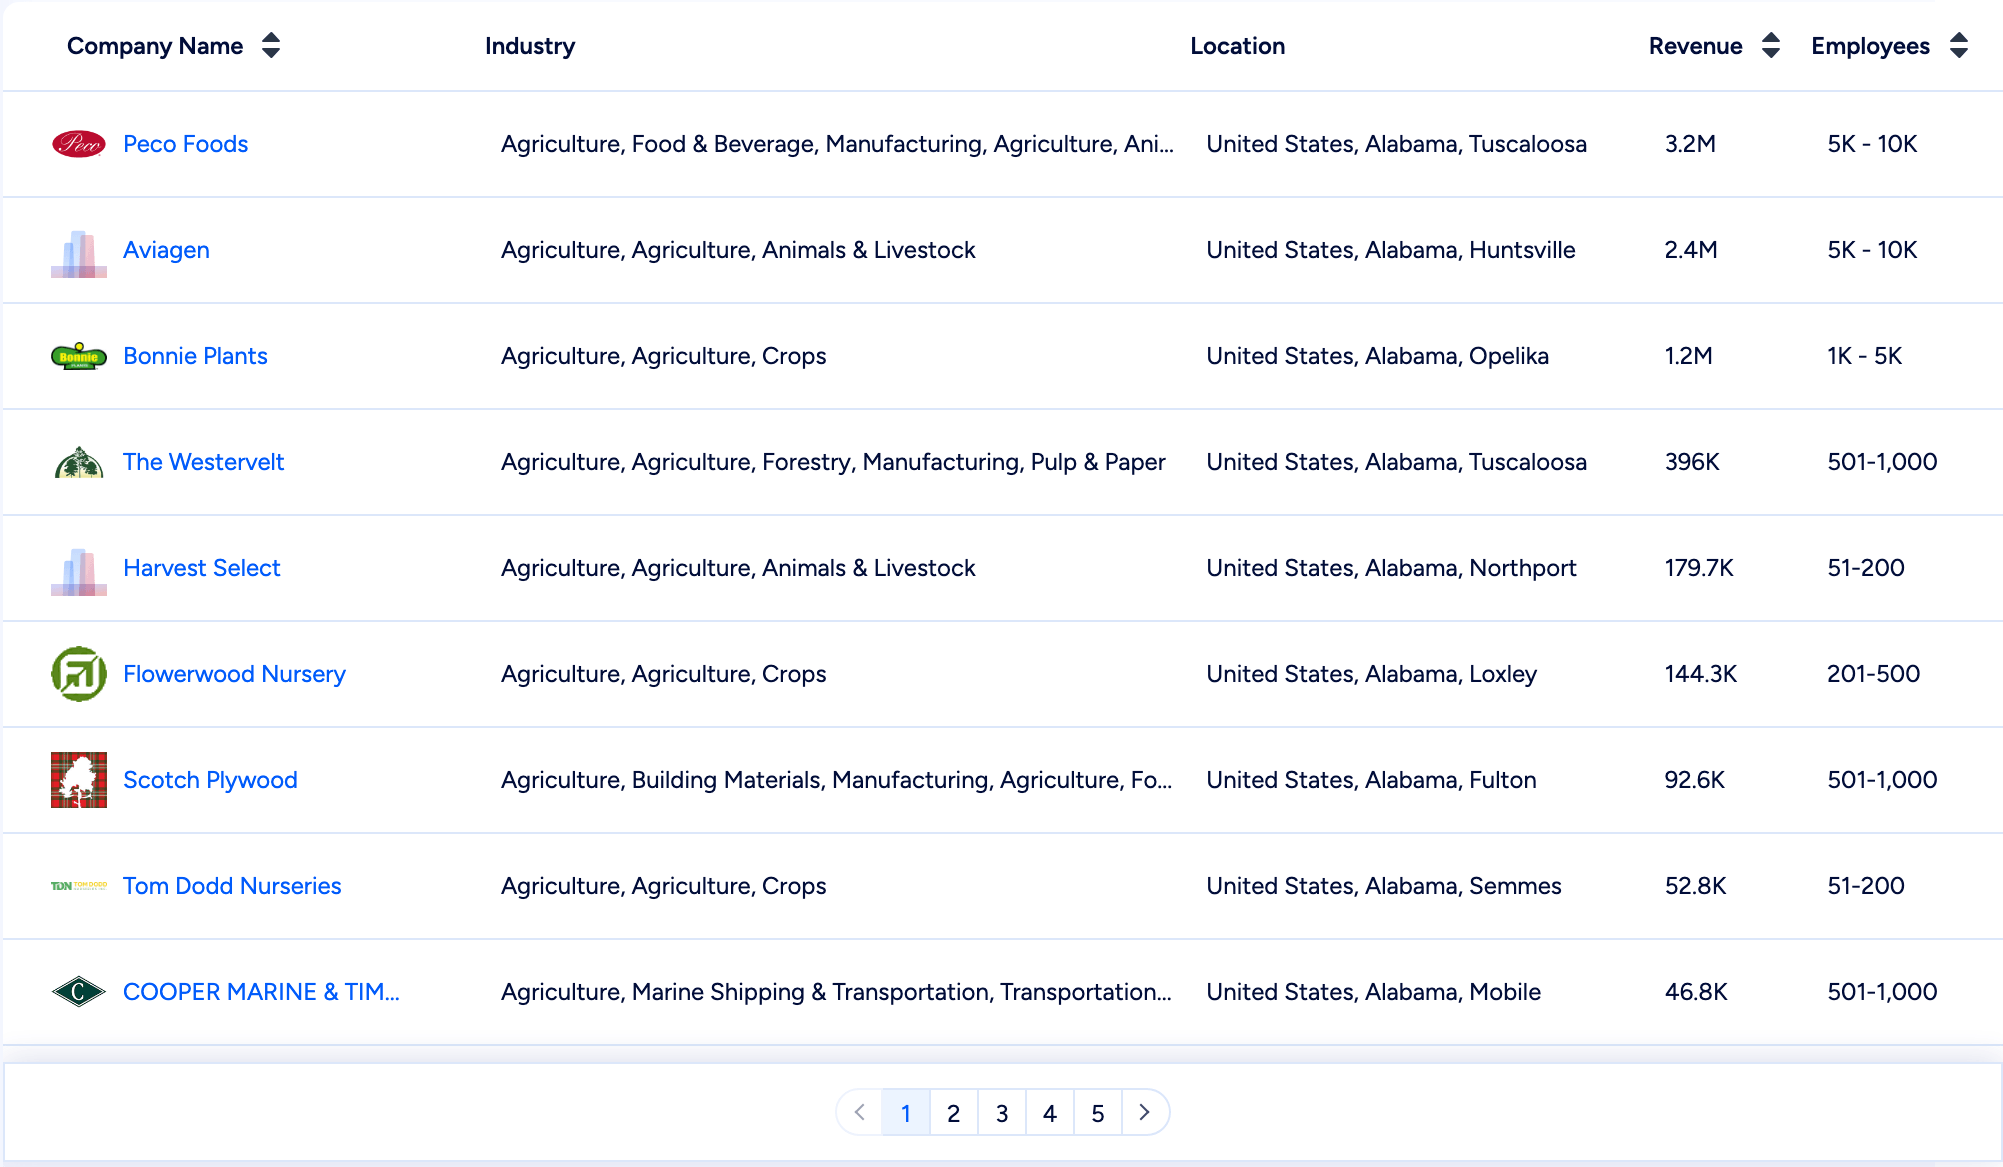
The pagination showed 5 pages. The revenue column was in thousands of dollars, so Aviagen’s 2.4M matches the $2.4 Billion on its profile.
A paginator that checks only status codes would collect page 1’s companies again as new results. Add this guard to parse_zoominfo.py. It compares the page number in the embedded JSON with the one you requested:
def directory_page(html: str, requested: int) -> list[str] | None:
    state = _state(html) or {}
    if state.get("pageNum") != requested:
        return None  # past the reachable pages, ZoomInfo serves page 1 again
    rows = (state.get("aiSearchResults") or {}).get("data") or []
    return [urljoin("https://www.zoominfo.com", row["companyUrl"])
            for row in rows]
directory_page returned 9 company URLs per page, and it returned None for page 6. So only 5 pages of this filter were reachable, and they held about 45 of its 1,962 companies. To reach more companies, split a large filter by US state or sub-industry until each smaller filter has 45 companies or fewer. Bright Data’s ZoomInfo Scraper API can also crawl ZoomInfo directory pages and return the companies they list as structured records.
Search results for companies you already know
A query such as site:zoominfo.com/c example.com, sent through Bright Data’s SERP API, can find candidate profiles for a domain. For brightdata.com, the query returned 3 different company IDs. Keep the candidate whose website matches the domain you searched.
Links between company pages
Many profiles listed similar companies, and Bright Data’s ZoomInfo Scraper API returned them in a similar_companies field. A crawler can start from a list of seed URLs and follow these links to find more companies.
Duplicate profiles and stable IDs
Duplicates existed in ZoomInfo’s own data, so any of the 3 sources could return them. For brightdata.com, one extra profile listed the main profile’s street address but a different website domain. Its headcount and revenue estimates also differed from the main profile’s.
A join on domain misses that duplicate, and a join on name can also match unrelated companies. A search for minimax.com returned 9 profiles with Minimax in the name, and several were unrelated businesses. Match entities on domain or headquarters street address, and review only the profiles that match on one but not the other. Keep ZoomInfo’s numeric ID as the primary key.
In a company URL, the slug could change, but the redirect we traced kept the numeric ID. In one sample, 3 of 20 company URLs returned a 301 redirect, so each needed one more request through the same anti-bot systems. For the input /c/walmart-inc/155353090, the Scraper API returned the canonical URL, /c/walmart/155353090, which kept the same ID. Web Unlocker followed the same redirect and returned Walmart’s page.
3 ways to collect ZoomInfo data at scale
At 100K company pages a month and about 3 pages per IP, a do-it-yourself pipeline would need more than 33K sessions and ongoing engineering work. Bright Data’s ZoomInfo data extraction options handle different amounts of that work, from unblocked pages to ready-made records:
| Web Unlocker | ZoomInfo Scraper API | ZoomInfo dataset | |
|---|---|---|---|
| You send | A page URL | Company or directory URLs | A filter |
| You get | The full page HTML | Structured JSON records | Ready-made records in a file |
| In our tests | Company pages arrived with the embedded JSON intact | Company records arrived, and directory URLs were paginated for us | The sample file showed the full schema |
| Delivery | Synchronous or asynchronous requests | Snapshots through the API, cloud storage, or a webhook | Files on a scheduled refresh |
| Parsing | Yours | Included | Included |
The right option depends on the output you need:
- Structured records for your own URL list. Use the Scraper API.
- Unrounded headcount and revenue. Use Web Unlocker with
parse_company. - Wide coverage, already collected. Use the dataset.
For pages that need clicks and scrolling, Bright Data’s Browser API runs a hosted Chrome that you drive with Playwright or Puppeteer. For company pages, which need no clicks, Web Unlocker is the simpler option, because it returns the HTML directly, with no browser to drive. For AI agents, Bright Data’s ZoomInfo MCP server lets clients such as Claude Desktop and Cursor collect the same public company profiles.
To start, create a Bright Data account and an API key. For Web Unlocker, also create a zone, a named Web Unlocker configuration, in the control panel. New accounts get free credits to test Bright Data’s APIs.
The scripts need Python 3.10 or later. The complete files are in Bright Data’s zoominfo-scraper repository on GitHub. Set the key and zone once:
pip install httpx
export BRIGHTDATA_API_KEY="your_api_key"
export BRIGHTDATA_UNLOCKER_ZONE="your_web_unlocker_zone"
Each script reads the key when it starts, so a script with a missing key stops before it sends any request.
Web Unlocker returns pages you parse
Web Unlocker is Bright Data’s unblocking API. You send a URL, and Web Unlocker handles proxies, browser rendering, and challenges before it returns the page. In our tests, it unblocked ZoomInfo company pages and returned the HTML with the embedded JSON intact. So parse_company works on that HTML without changes.
Web Unlocker reports the target’s own status in the x-brd-status-code response header and details in x-brd-error, so a pipeline can branch on the result. By default, it bills only successful requests, and the docs list the settings that change this default.
This fetcher, saved as fetch_pages.py, handles 5 URLs at a time, tries each one up to 3 times, and saves the records to companies.jsonl:
import json
import os
import sys
import time
from concurrent.futures import ThreadPoolExecutor
from datetime import datetime, timezone

import httpx

from parse_zoominfo import content_hash, parse_company

API = "https://api.brightdata.com/request"
KEY = os.environ["BRIGHTDATA_API_KEY"]
ZONE = os.environ["BRIGHTDATA_UNLOCKER_ZONE"]


def fetch(url: str, attempts: int = 3) -> dict:
    error = None
    for attempt in range(1, attempts + 1):
        try:
            resp = httpx.post(
                API,
                headers={"Authorization": f"Bearer {KEY}"},
                json={"zone": ZONE, "url": url, "format": "raw"},
                timeout=180,
            )
            # The API reports the target's own result in these 2 headers.
            target = resp.headers.get("x-brd-status-code")
            record = parse_company(resp.text) if target == "200" else None
        except (httpx.HTTPError, ValueError) as exc:  # timeout or bad JSON
            error = f"{type(exc).__name__}: {exc}"
        else:
            if record:
                record["fetched_at"] = datetime.now(timezone.utc).isoformat()
                record["hash"] = content_hash(record)
                return {"url": url, "ok": True, "attempts": attempt,
                        "record": record}
            error = resp.headers.get("x-brd-error") or f"target {target}"
        if attempt < attempts:
            time.sleep(2 ** attempt)
    return {"url": url, "ok": False, "attempts": attempts, "error": error}


if __name__ == "__main__":
    urls = [line.strip() for line in open(sys.argv[1]) if line.strip()]
    with ThreadPoolExecutor(max_workers=5) as pool, \
            open("companies.jsonl", "a") as good, \
            open("failures.jsonl", "a") as bad:
        for result in pool.map(fetch, urls):
            (good if result["ok"] else bad).write(json.dumps(result) + "\n")
            print("saved" if result["ok"] else "not saved", result["url"])
With 3 company URLs listed one per line in urls.txt, python fetch_pages.py urls.txt printed:
saved https://www.zoominfo.com/c/bright-data/430599389
saved https://www.zoominfo.com/c/peco-foods-inc/82428957
saved https://www.zoominfo.com/c/aviagen-group/9047889
All 3 companies were saved. Here are the company fields from the Aviagen entry in companies.jsonl:
{
  "id": "9047889",
  "name": "Aviagen",
  "domain": "aviagen.com",
  "employees": 6776,
  "revenue_usd": 2413885000,
  "founded": 1923,
  "ticker": null,
  "sic": ["02", "025"],
  "naics": ["11", "112"],
  "industries": ["Agriculture", "Animals & Livestock"],
  "hq": {
    "street": "920 Explorer Blvd NW",
    "city": "Huntsville",
    "state": "Alabama",
    "country": "United States",
    "zip": "35806"
  },
  "phone": "(256) 890-3800",
  "tech_used": ["ClickDimensions", "Freshservice", "PHP", "Zingfit"],
  "management_levels": {
    "C-Level": 14,
    "VP-Level": 28,
    "Director": 108,
    "Manager": 998,
    "Non-Manager": 1229,
    "Top Contacts": 1316
  },
  "zi_rank": 65
}
Aviagen’s profile showed these employees and revenue_usd values as “5K – 10K” and “$2.4 Billion” in its header and overview.
The ZoomInfo Scraper API returns records
Bright Data’s ZoomInfo Scraper API handles both unblocking and parsing. Its Collect by URL endpoint takes company URLs, and Discover by search_url takes directory URLs and collects the companies listed on their pages. The control panel listed both endpoints and offered synchronous and asynchronous modes:
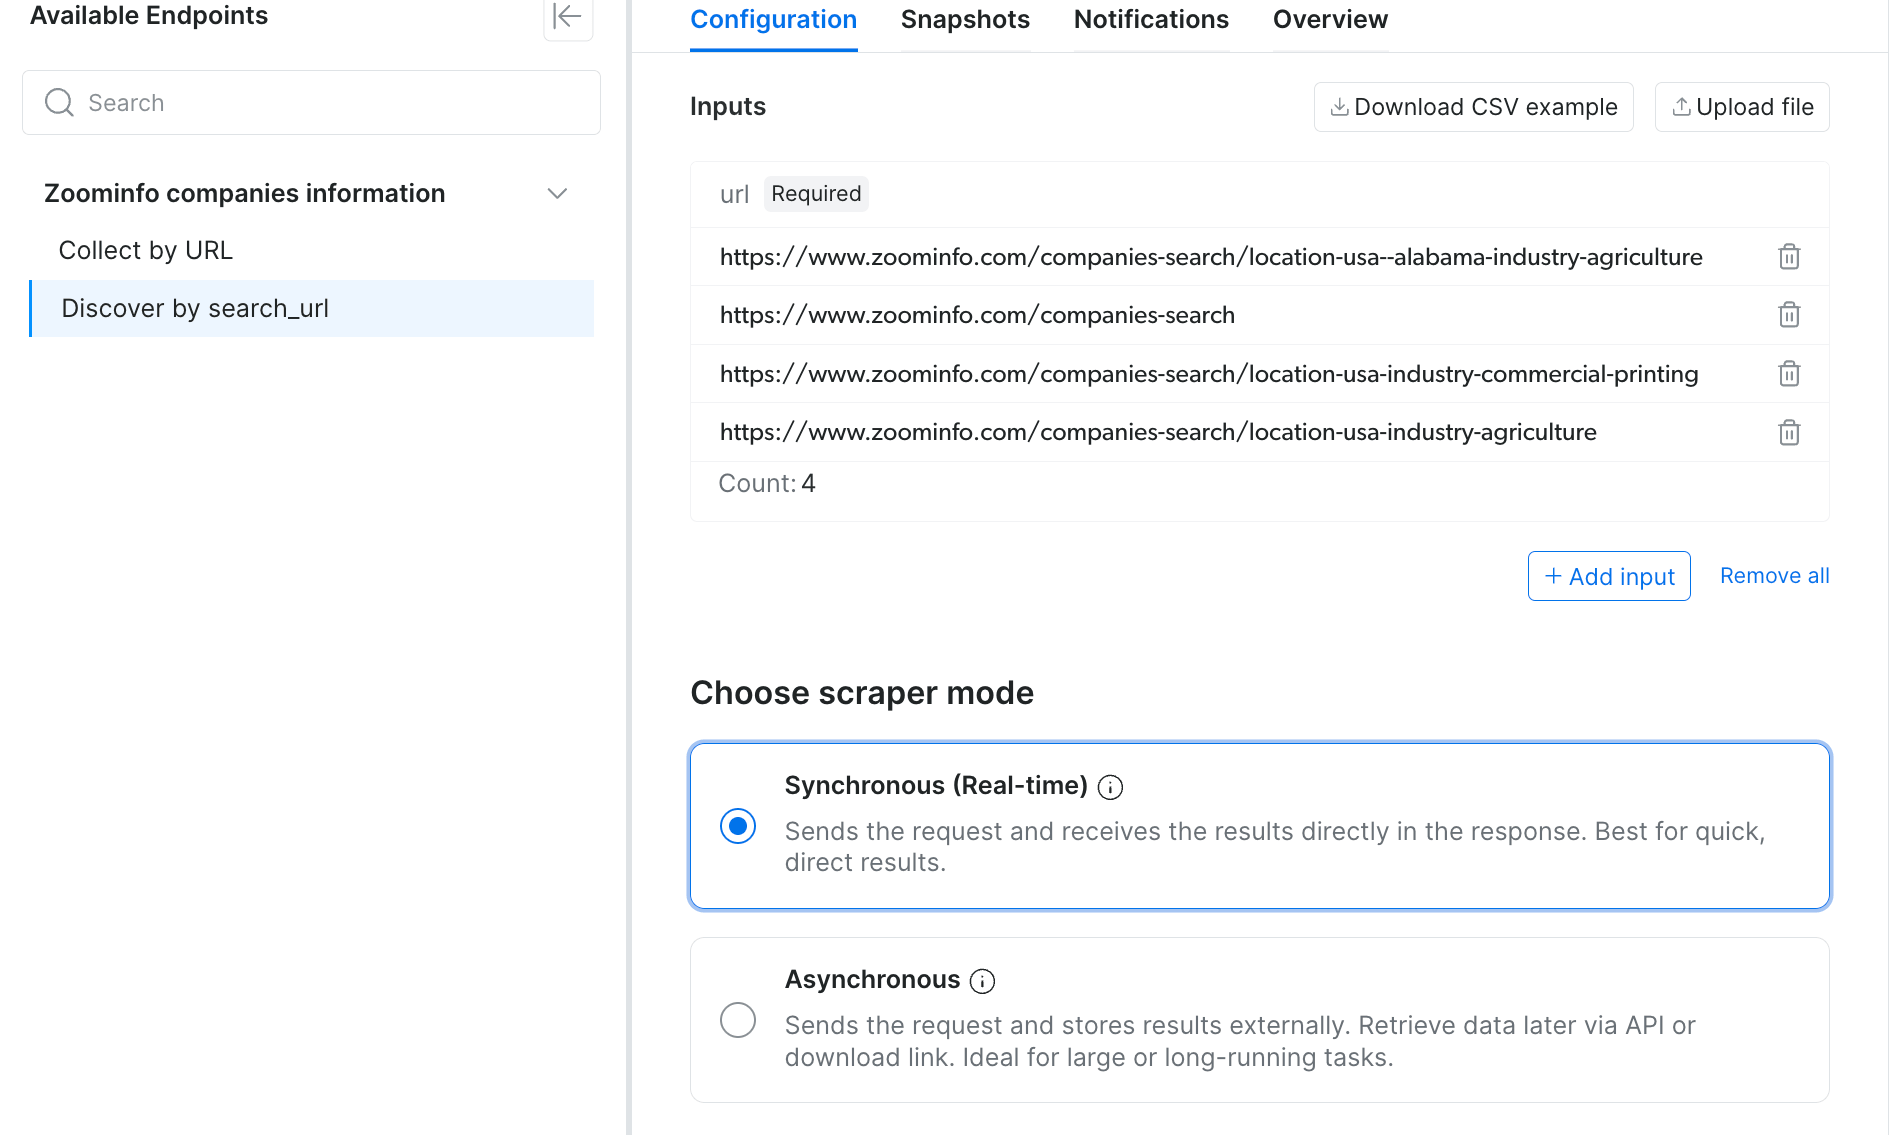
Discover by search_url takes directory URLs like these and returns the companies listed on their pages.
For batches, use the asynchronous /trigger endpoint, which runs the job in the background and returns a snapshot ID. The synchronous /scrape endpoint returns records directly for small tests, and it moves longer jobs to a snapshot after its response time limit.
In our 40-URL batch, the first records arrived within a minute. For large batches, let the API deliver results to cloud storage or a webhook. It sends each snapshot when the last input finishes, so you don’t poll the API.
Discover by search_url handles pagination for you. From the Alabama directory URL alone, it returned 45 company records. Each record carried the directory URL it came from. For a larger filter, send a directory URL for each US state or sub-industry.
The scraper_api.py client triggers a job and polls until the snapshot is ready, then downloads it. Its clean function converts the employee range into employees_min and employees_max and flags revenue ranges such as “<$5 Million”. It also drops the leadership, org chart, and CEO fields, which hold data about people. With --discover, the client sends directory URLs to Discover by search_url:
import json
import os
import re
import sys
import time

import httpx

BASE = "https://api.brightdata.com/datasets/v3"
DATASET_ID = "gd_m0ci4a4ivx3j5l6nx"  # Zoominfo companies information
HEADERS = {"Authorization": f"Bearer {os.environ['BRIGHTDATA_API_KEY']}"}


def trigger(urls: list[str], discover: bool = False, limit: int = 50) -> str:
    params = {"dataset_id": DATASET_ID, "include_errors": "true"}
    if discover:  # directory URLs: the job handles their pagination
        params |= {"type": "discover_new", "discover_by": "search_url",
                   "limit_per_input": limit}
    resp = httpx.post(f"{BASE}/trigger", params=params, headers=HEADERS,
                      json=[{"url": u} for u in urls], timeout=60)
    resp.raise_for_status()
    return resp.json()["snapshot_id"]


def wait(snapshot_id: str, every: int = 30) -> dict:
    while True:
        try:
            progress = httpx.get(f"{BASE}/progress/{snapshot_id}",
                                 headers=HEADERS, timeout=60).json()
        except (httpx.HTTPError, ValueError):  # retry after a network error
            progress = {}
        if progress.get("status") in ("ready", "failed"):
            return progress
        time.sleep(every)


def download(snapshot_id: str, tries: int = 30) -> list[dict]:
    for _ in range(tries):
        try:
            resp = httpx.get(f"{BASE}/snapshot/{snapshot_id}",
                             params={"format": "json"}, headers=HEADERS,
                             timeout=300)
            if resp.status_code == 200 and resp.content.strip():
                return resp.json()
        except (httpx.HTTPError, ValueError):  # timeout or a partial file
            pass
        time.sleep(10)  # wait until the snapshot file is available
    raise RuntimeError(f"snapshot {snapshot_id} is not available yet")


def employee_range(text: str | None) -> tuple[int | None, int | None]:
    # "11-50" -> (11, 50), "1K - 5K" -> (1000, 5000), "10K+" -> (10000, None)
    if not text:
        return None, None
    nums = [int(float(n) * (1000 if k else 1)) for n, k
            in re.findall(r"([\d.]+)\s*(K?)", text.replace(",", ""))]
    if not nums:
        return None, None
    if len(nums) == 1:
        return nums[0], None if "+" in text else nums[0]
    return nums[0], nums[1]


def clean(row: dict) -> dict:
    row["employees_min"], row["employees_max"] = employee_range(
        row.get("employees_text"))
    # Headcount comes from the employees_text range.
    row["employees"] = row["total_employees"] = None
    row["revenue_is_range"] = (row.get("revenue_text") or "").startswith("<")
    row["stock_symbol"] = (row.get("stock_symbol") or "").strip() or None
    row["id"] = str(row["id"])
    for field in ("leadership", "org_chart", "ceo"):  # data about people
        row.pop(field, None)
    return row


if __name__ == "__main__":
    urls = [a for a in sys.argv[1:] if a.startswith("http")]
    snapshot = trigger(urls, discover="--discover" in sys.argv)
    progress = wait(snapshot)
    summary = {k: progress.get(k) for k in ("status", "records", "errors")}
    print(json.dumps(summary))
    rows = download(snapshot)
    # Keep rows that carry an id and no error.
    good = [clean(r) for r in rows if r.get("id") and not r.get("error")]
    bad = [r for r in rows if r.get("error") or not r.get("id")]
    json.dump(good, open("records.json", "w"), indent=2)
    json.dump(bad, open("errors.json", "w"), indent=2)
    print(f"{len(good)} records saved to records.json")
With the 3 company URLs from urls.txt as arguments, the client printed:
{"status": "ready", "records": 3, "errors": 0}
3 records saved to records.json
The snapshot held all 3 records, and the client saved them to records.json. Each record carried company fields such as revenue, industry, technologies, website, headquarters, and phone number.
The ZoomInfo dataset delivers records already collected
The ZoomInfo dataset delivers records with the same fields, already collected and refreshed on a schedule. Check the dataset page for the current record count, refresh frequency, and pricing, and inspect its sample before you buy. To decide between it and a ZoomInfo subscription, read our comparison of Bright Data and ZoomInfo.
Filter before you buy. The dataset’s filters let you select only the records you need, such as company pages with URLs that include /c/. Drop the leadership and org chart columns, which hold data about people, unless you have a lawful basis for them.
A dataset holds records as they were at collection time, and each refresh updates them. To pick a refresh frequency, collect the same sample of companies twice, a month apart, and count the records that changed.
Match CRM domains to ZoomInfo profiles
A CRM holds domains rather than ZoomInfo URLs. This script, saved as find_profiles.py, searches Google for each domain through Bright Data. It fetches the top 3 profiles with fetch from fetch_pages.py and keeps the first record whose domain matches the CRM domain. If the search without quotes finds no match, the script searches again with the domain in quotes:
import json
import os
import re
import sys
from concurrent.futures import ThreadPoolExecutor
from urllib.parse import quote_plus

import httpx

from fetch_pages import fetch

API = "https://api.brightdata.com/request"
KEY = os.environ["BRIGHTDATA_API_KEY"]
# A SERP API zone if you have one, otherwise the Web Unlocker zone.
ZONE = (os.environ.get("BRIGHTDATA_SERP_ZONE")
        or os.environ["BRIGHTDATA_UNLOCKER_ZONE"])
PROFILE = re.compile(r"https://www\.zoominfo\.com/c/[^/?#]+/\d+")
# Each query found profiles that the other missed, so try both.
QUERIES = ("site:zoominfo.com/c {}", 'site:zoominfo.com/c "{}"')


def candidates(query: str, top: int = 3) -> list[str]:
    url = f"https://www.google.com/search?q={quote_plus(query)}&brd_json=1"
    for _ in range(3):
        try:
            resp = httpx.post(
                API,
                headers={"Authorization": f"Bearer {KEY}"},
                json={"zone": ZONE, "url": url, "format": "raw"},
                timeout=120,
            )
            results = resp.json().get("organic", [])  # parsed results
        except (httpx.HTTPError, ValueError):  # timeout or an empty body
            continue
        links = [row.get("link", "") for row in results]
        found = (PROFILE.match(link) for link in links)
        return list(dict.fromkeys(m.group(0) for m in found if m))[:top]
    return []


def find_profile(domain: str) -> dict | None:
    for query in QUERIES:
        for url in candidates(query.format(domain)):
            result = fetch(url)
            # Keep a profile only when its website is the CRM domain.
            if result["ok"] and result["record"]["domain"] == domain:
                return result["record"]
    return None


if __name__ == "__main__":
    domains = [d.strip().lower().removeprefix("www.") for d in sys.argv[1:]]
    with ThreadPoolExecutor(max_workers=5) as pool, \
            open("matches.jsonl", "a") as out:
        records = pool.map(find_profile, domains)
        for domain, record in zip(domains, records, strict=True):
            out.write(json.dumps({"domain": domain, "record": record}) + "\n")
            print(domain, record["id"] if record else "no match")
For 4 CRM domains, python find_profiles.py aviagen.com pecofoods.com brightdata.com walmart.com printed:
aviagen.com 9047889
pecofoods.com 82428957
brightdata.com 430599389
walmart.com no match
For each match, the script returned a full company record. The search without quotes found Aviagen and Bright Data, and the search with quotes found Peco Foods. Walmart’s profile didn’t appear in either search’s results, so the script returned no match instead of a wrong company. Send unmatched domains to a name search or a review queue.
Validate every record before it reaches your CRM
Each response we saw from ZoomInfo and from Bright Data’s APIs needs its own action:
| Response | Meaning | Action |
|---|---|---|
200 with company data in ng-state |
A real company page | Parse and store |
| 301 redirect | The URL changed | Store the new URL, and use the ID as the key |
403 with px-captcha in the body |
HUMAN blocked the request | Retry on a new session |
429 with cf-mitigated: challenge |
Cloudflare’s per-IP request limit was reached | Rotate the IP, and stop retrying on it |
| 429 with no Cloudflare headers | Bright Data’s auto-throttle, triggered by a low success rate | Lower the request rate, and fix the requests that fail |
| 502 with no anti-bot signature | A temporary upstream error | Retry with backoff |
Web Unlocker x-brd-status-code header |
The target site’s own status | Store 200 results, and retry the others a limited number of times |
Scraper API 202 from /scrape |
The job moved to a snapshot | Poll the snapshot ID |
Directory page whose pageNum is lower than requested |
Past the last reachable page | Stop paginating, and narrow the filter |
Status checks catch failed pages, and field checks catch bad records:
- Keep IDs as strings. ZoomInfo person IDs in the data we inspected ranged from -2,135,143,530 to 17,773,369,573, so they fit neither a signed nor an unsigned 32-bit integer.
- Read headcount from ranges or the embedded JSON. Use
employees_minandemployees_maxfromclean, ornumberOfEmployeesfrom the JSON. - Mark revenue ranges. A value like “<$5 Million” is a range, and the JSON held the estimate.
- Split industry codes. Values like “54,541” carried a sector code and a subsector code.
- Expect empty CEO fields. ZoomInfo left the CEO field empty on every public page we checked.
- Track fill rates per batch. A sudden drop in one field’s fill rate can mean ZoomInfo changed a template.
Our guide to fixing inaccurate web scraping data explains data cleaning in more depth.
What ZoomInfo scraping costs at scale
The options have different billing units, and each pricing page lists the current rates:
| Option | Billed on | Other costs |
|---|---|---|
| Web Unlocker and your parser | Successful requests, with default settings | URL discovery, parsing, deduplication, and hosting |
| ZoomInfo Scraper API | Records delivered | Deduplication and storage |
| ZoomInfo dataset | Records in the file | Deduplication and storage |
| Residential proxies and your own stack | Bandwidth | Sessions, retries, parsing, deduplication, and the engineering to run them |
The company pages we measured were 42 to 55 KB compressed, so 100K pages use about 4 to 6 GB of bandwidth. At higher volumes, check each pricing page for volume plans.
Residential proxies give you the most control. For pages this size, their bandwidth bill is small compared with the engineering cost. With a do-it-yourself stack, you also pay for blocked first requests, retries, and the extra sessions at about 3 pages per IP. You also need an engineer who maintains the stack when ZoomInfo changes its anti-bot rules or page structure.
In an IsraelTech podcast interview, Bright Data CEO Or Lenchner said, “You need us when you need scale repeatedly all the time.” For small amounts of data, Lenchner advised teams to collect it themselves. Our comparison of managed and DIY scraping lists the costs of each approach.
Final thoughts
ZoomInfo’s pages held unrounded firmographics as embedded JSON, but in our tests, anti-bot systems checked each first request and blocked IPs after about 3 pages. The JSON made extraction the smaller job, so at scale, sessions, URL discovery, and deduplication need the most work. Our scripts collect only public company data, because contact details needed an account and data about people can require a lawful basis.
Bright Data’s Web Unlocker and ZoomInfo Scraper API handle the sessions, and the ZoomInfo dataset delivers records that Bright Data already collected. Test the ZoomInfo Scraper API on a sample of your own accounts, and compare the records with your CRM.
FAQ
Can you scrape ZoomInfo?
Yes, for the company pages that load without a login. Contact details needed an account. The public company pages carried their data as embedded JSON. In our tests, ZoomInfo blocked all 32 first requests without a referrer from another site, so start every new session with one.
How to scrape data from ZoomInfo?
Find each company’s profile URL, fetch the public page, and read the data from its embedded JSON. IPs in our tests got a median of 3 pages, so plan for many sessions. Bright Data’s ZoomInfo Scraper API handles the sessions and parsing for you.
Is there a ZoomInfo API?
Yes. ZoomInfo sells access to its own database through an API. For public company profiles, Bright Data’s ZoomInfo Scraper API collects those pages and returns structured records. Bright Data’s ZoomInfo dataset delivers records with the same fields, already collected and refreshed on a schedule.
Is ZoomInfo outdated?
Some of its records can be outdated, so check them before they reach a CRM. Our search for one domain returned 3 ZoomInfo IDs, and one was a duplicate with a different headcount. Deduplicate, compare fill rates, and refresh as often as your fields change.
Can I use ZoomInfo for free?
Partly. Company profile pages on zoominfo.com loaded without an account, though their HTML marked contact details and some sections as paywalled. ZoomInfo also offered a free Lite plan with limited monthly credits. New Bright Data accounts get free credits to test the ZoomInfo Scraper API on those pages.
Is there a free ZoomInfo scraper?
Yes. Bright Data’s open-source zoominfo-scraper repository on GitHub has Python scripts that use Bright Data’s APIs. In our tests, requests with a curl or python-requests User-Agent were blocked 29 of 29 times, even with a Google referrer. Bright Data’s APIs handle unblocking for these scripts.


Technical Writer
 5 years experience
Satyam Tripathi helps SaaS and data startups turn complex tech into actionable content, boosting developer adoption and user understanding.