Scraping Zillow means collecting listing, price, and property records from Zillow’s public pages for pricing models, investment analysis tools, and market dashboards. Each page embeds its main data as JSON.
Zillow blocks default Python requests, but that’s the easier problem. The harder one is data your scraper misses without telling you. Most listing pages don’t include price history in their HTML, and one search stops at 984 listings, only 6% of Houston’s homes for sale.
This guide shows you how to scrape Zillow with Python, get every listing with its price history, and decide when a managed scraper costs less.
TL;DR
- Use a browser’s TLS fingerprint. Zillow blocks Python’s default TLS fingerprint, even with Chrome headers.
curl_cffiimpersonating Chrome got 429 of 430 pages. - Read the page’s embedded JSON, and fetch price history separately. Most listing pages load it with a second request that HTML-only scrapers never make.
- One search stops at 984 listings, so split large searches. Or use the Bright Data Zillow Scraper API, which found all 1,295 Fort Wayne listings from one URL.
- Check completeness, not only status codes. Compare your row count with Zillow’s reported total, retry failed rows, and flag previously sold homes without price history.
What Zillow data you can scrape and where to find it
Your scraper can get Zillow data from 4 main sources, and Zillow’s robots.txt treated each of them differently:
| Data | Source on Zillow | What robots.txt said |
|---|---|---|
| Listing fields: price, beds, Zestimate, photos, listing agent | __NEXT_DATA__ JSON inside the listing page HTML |
Allowed for /homedetails/ pages |
| Price history, tax history, schools | Usually a /graphql/ request that the page sent after it loaded |
Disallowed for /graphql/ |
| Search results, 41 listings per page | City pages such as /fort-wayne-in/2_p/, or the internal async-create-search-page-state endpoint |
Allowed for city pages, disallowed for the endpoint and ?searchQueryState= URLs |
| Changed listings | Sitemaps linked from robots.txt, such as latest.xml.gz |
Published for crawlers |
Zillow’s pages were built with Next.js, and each page embedded its main data as JSON in a __NEXT_DATA__ script tag. You can read that JSON without rendering the page. Our guide to scraping Next.js sites explains how this embedded data works.
Your requests for one listing and one search follow this path:
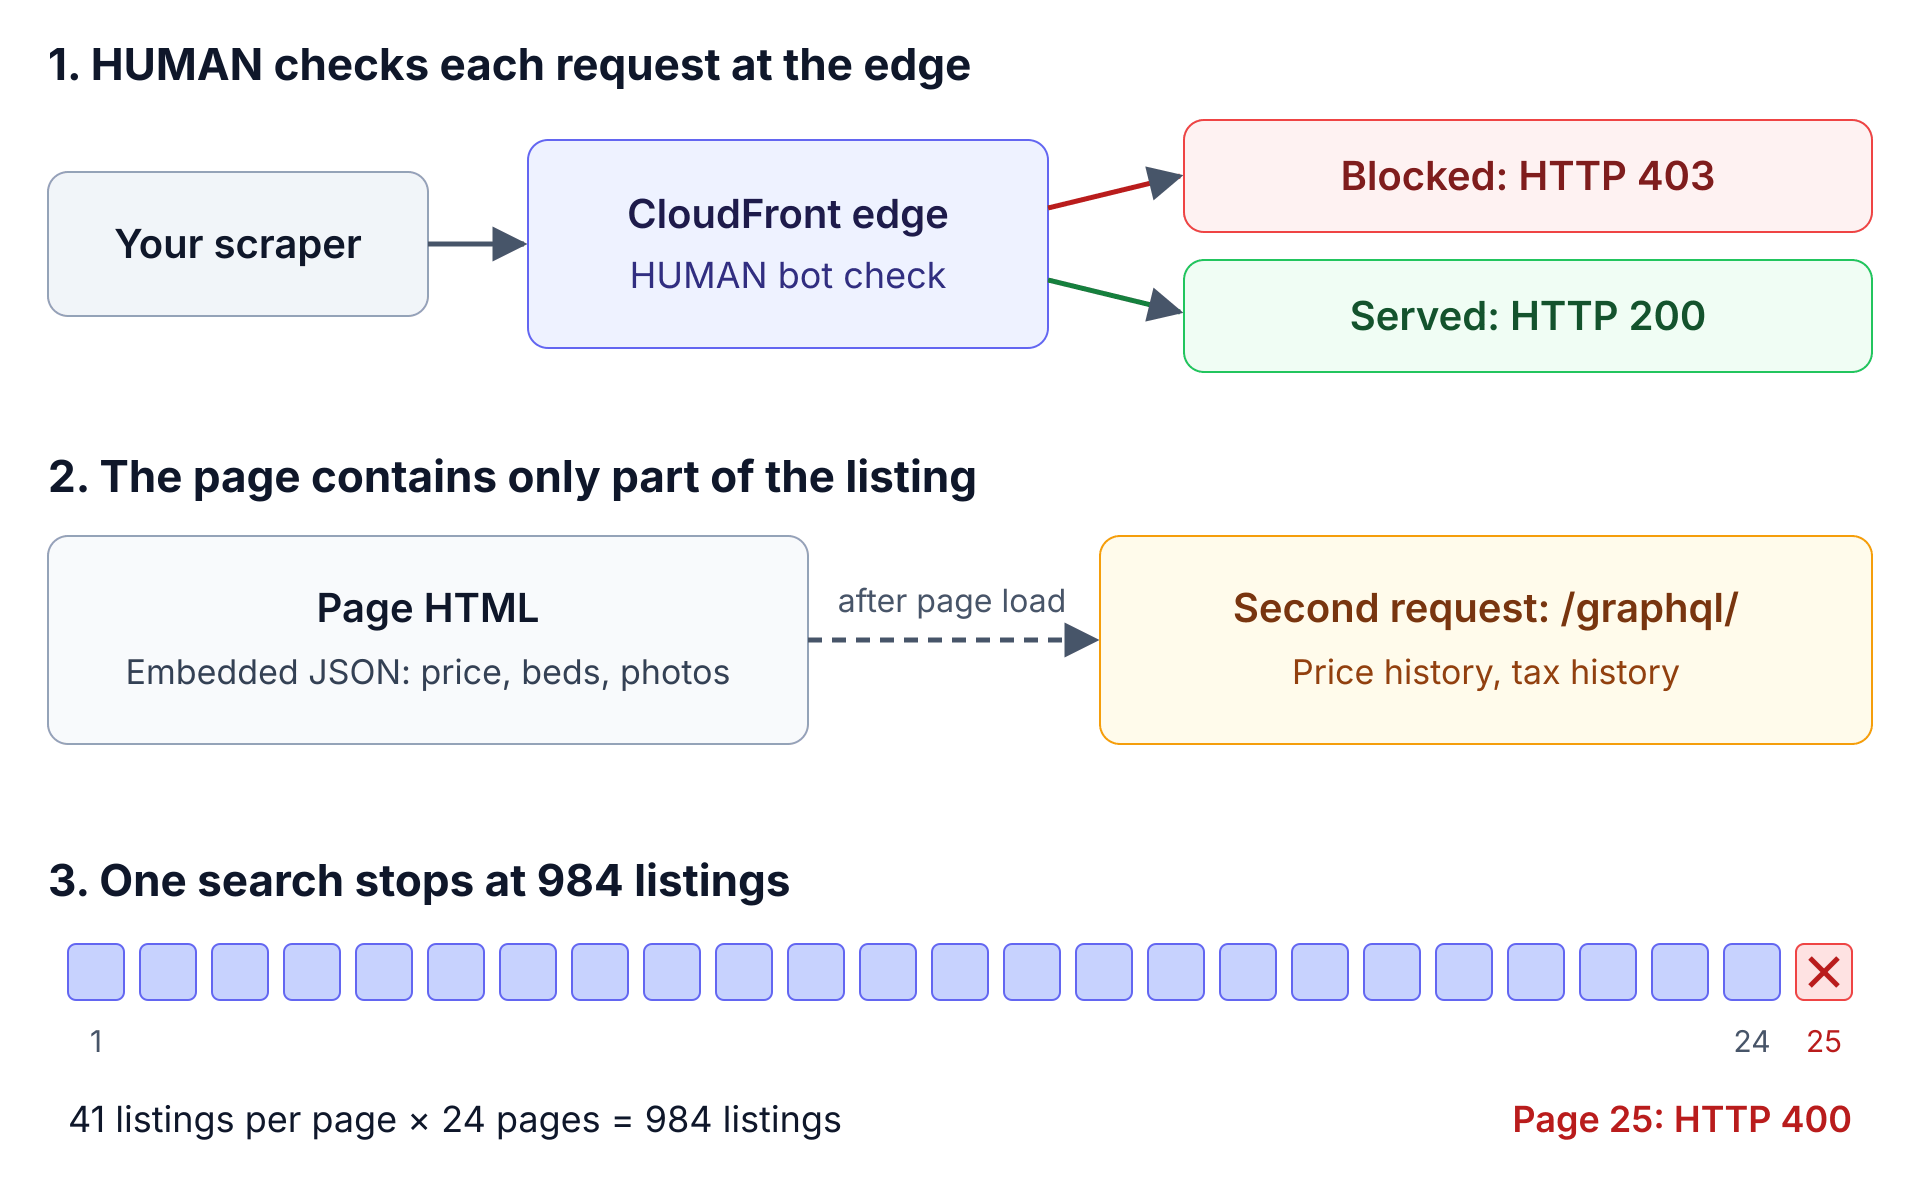
HUMAN’s bot check runs at the edge before any HTML exists, and the price history loads after the page does. If your parser reads only the HTML, it can mistake a block for an empty page, and it misses the price history on most listings.
Listing pages and price history
You need to parse the listing JSON twice, because it was double-encoded. The field props.pageProps.componentProps.gdpClientCache had a string value, and that string was itself a JSON object. Its keys were the names of Zillow’s internal GraphQL queries.
For-sale, off-market, and Zillow Showcase listings each used their own GraphQL operation name. ForSalePriorityQuery had 101 fields, NotForSalePriorityQuery had 122, and ViewShowcasePriorityQuery had 78. If your parser expects one operation name, it fails on the others. Merge every entry in the cache instead, and one parser handles all 3 listing types.
Price and tax history were missing from that JSON on most listings. For 20 for-sale listings, the Bright Data Zillow Scraper API returned 1 to 18 price history events each. The HTML of the same pages contained none of those events. If your scraper reads only the HTML, it records these homes as having no price history and raises no error.
The browser requested the history after the page loaded. For a home for sale, that request (ForSaleNonPriorityQuery) returned 145 property fields, including 21 years of tax history. An off-market page used a different request, a persisted GraphQL query that the page called by its hash.
Search pages and the 984-listing limit
A full page of search results contained 41 listings in its __NEXT_DATA__ block, but only 9 of them rendered as HTML cards. If you parse the cards with CSS selectors, you miss the other 32. The card selectors from older Zillow tutorials, such as article.list-card, matched no elements.
Zillow also limited each search. Its own pagination stopped at page 20, even for a search that reported more than 1K results:
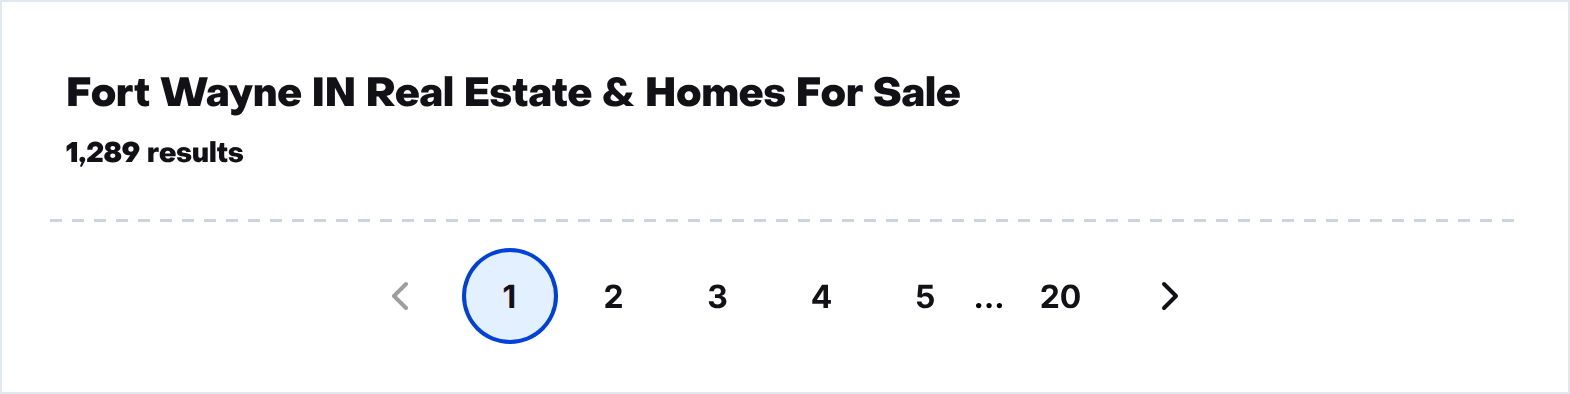
The top and bottom of Zillow’s Fort Wayne results list. The total (1,289 here) changes as listings are added and removed, but the page numbers still stopped at 20.
Twenty pages of 41 listings make 820, the limit that some scraping tools document. But pages 21 to 24 still returned 41 more listings each when requested by URL, and page 25 returned an HTTP 400 error. One search therefore reached 984 listings, which was 76% of Fort Wayne’s 1,295 for-sale listings and 6% of the 15,410 in the city of Houston. Every response still reported the full total, so compare that number with what you collect.
Parse the JSON rather than the markup, and you get all 41 listings per page instead of 9.
Why Zillow blocks default Python requests
Zillow’s bot protection came from HUMAN Security, formerly PerimeterX. Two details showed it: the block page named the PerimeterX app ID PXHYx10rg3, and robots.txt disallowed /captchaPerimeterX/ and /HYx10rg3/.
The refusal came from CloudFront, the content delivery network (CDN) in front of Zillow, not from Zillow’s own servers. Each blocked response was an HTTP 403 with x-cache: LambdaGeneratedResponse and x-px-blocked: 1. It also lacked the x-envoy-upstream-service-time header that normal pages included. Your scraper can check that x-px-blocked header to detect a block without parsing the page.
What a blocked request looks like
A curl request with a Chrome User-Agent was refused:
curl -s -o /dev/null -D - \
  -A "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/140.0.0.0 Safari/537.36" \
  "https://www.zillow.com/homedetails/25875-Fox-Tail-Trl-South-Bend-IN-46628/77039629_zpid/"
The edge responded in 0.32 seconds with the 5,952-byte “Press & Hold” page:
HTTP/2 403
server: CloudFront
content-length: 5952
x-px-blocked: 1
x-cache: LambdaGeneratedResponse from cloudfront
A headless Chromium launched from Playwright got the same block, HTTP 403 with x-px-blocked: 1, and rendered HUMAN’s challenge:
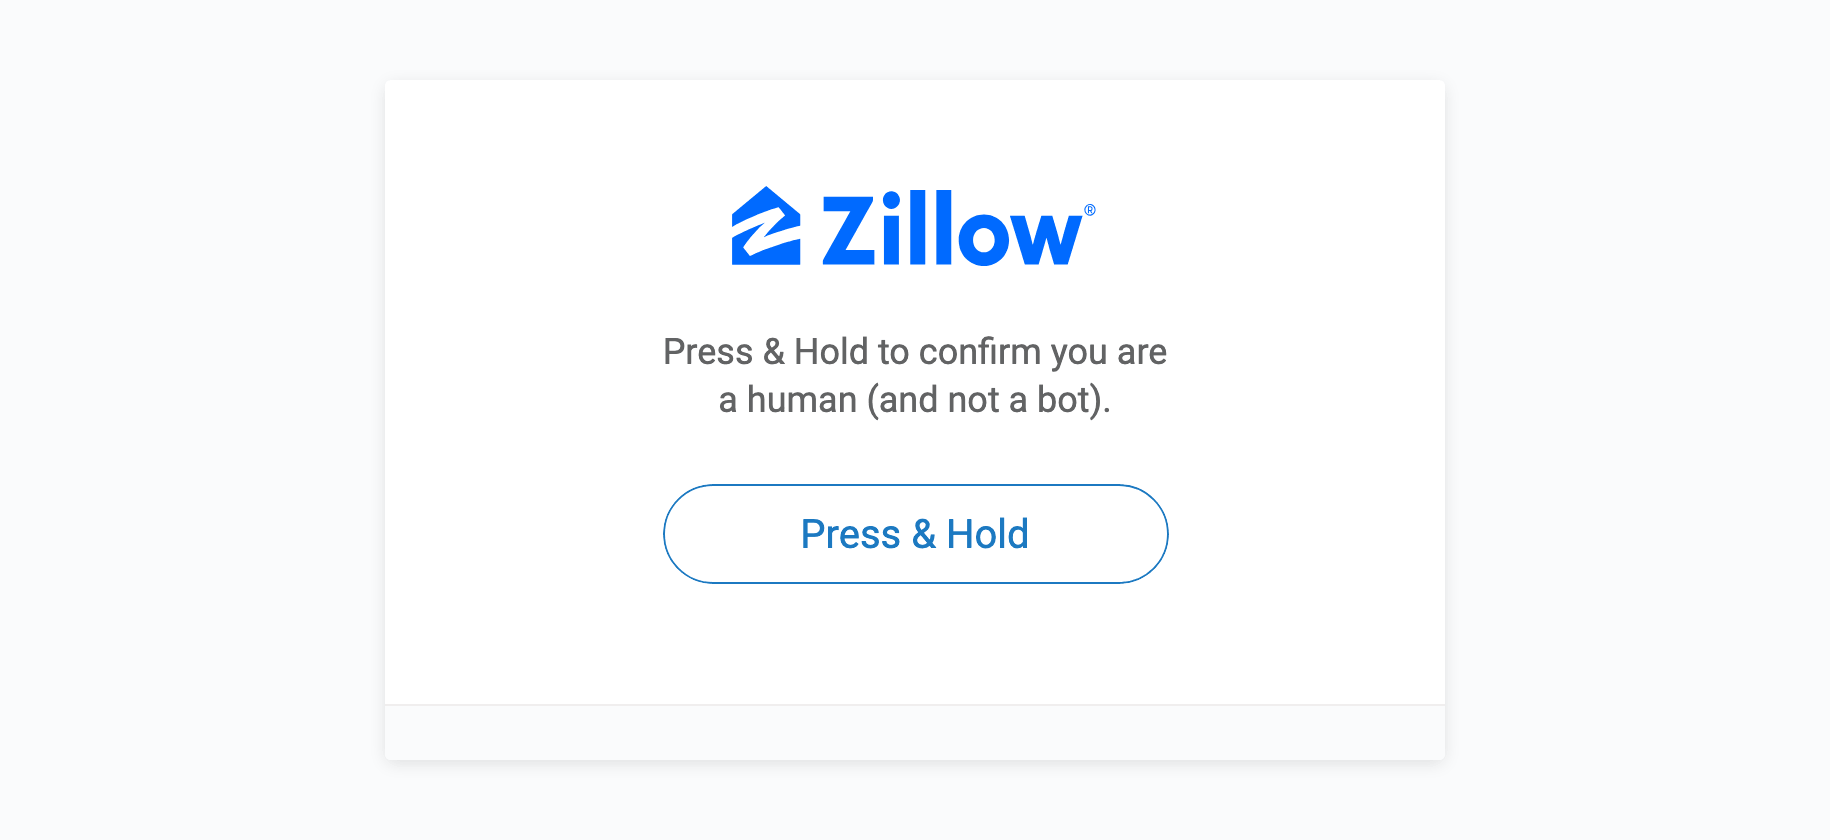
If your scraper receives this page, it has been refused at the edge, and the page contains no listing data.
To handle this page without your own bypass code, use the Bright Data Zillow CAPTCHA solver.
Which Python clients pass Zillow’s bot check
From the same IP, seconds after curl was refused, curl_cffi fetched the same listing. That library impersonates Chrome’s TLS handshake and headers:
python - <<'EOF'
from curl_cffi import requests

url = "https://www.zillow.com/homedetails/25875-Fox-Tail-Trl-South-Bend-IN-46628/77039629_zpid/"
r = requests.get(url, impersonate="chrome")
print(r.status_code, len(r.content))
EOF
It printed an HTTP 200 and 730,803 bytes of HTML:
200 730803Those 2 requests differed in their headers and in their TLS fingerprint. A TLS fingerprint is the pattern of cipher suites and extensions that a client offers when it opens a connection. Our guide to TLS fingerprinting explains how sites use these fingerprints to detect bots.
From one residential IP that Zillow hadn’t blocked, 6 clients fetched a listing page and a search page each, with the same result on both:
| Client | TLS fingerprint | Result |
|---|---|---|
Python requests, default headers |
Python (OpenSSL) | 403 |
Python requests, Chrome User-Agent and browser headers |
Python (OpenSSL) | 403 |
httpx, browser headers |
Python (OpenSSL) | 403 |
curl_cffi, impersonate="chrome" |
Chrome | 200 |
curl_cffi, impersonate="firefox" |
Firefox | 200 |
curl_cffi, impersonate="safari" |
Safari | 403 |
If your client uses Python’s TLS fingerprint, browser headers don’t help. The Safari profile was refused on both pages as well, so test each impersonation profile against Zillow before you rely on it. The Chrome profile also passed when HTTP/1.1 was forced, so the HTTP/2 settings weren’t the deciding factor.
Why headers and IP reputation still matter
Zillow also checks whether your request’s HTTP headers look like a real browser’s. When a proxy used Chrome’s TLS fingerprint and a new US IP for every request, the headers alone decided the result.
Python’s default User-Agent was refused 5 of 5 times, and a Chrome User-Agent alone passed 5 of 5. Chrome’s full set of headers without its sec-ch-ua client hints was refused 4 of 10 times. That suggests Zillow gives each request a risk score instead of applying a fixed rule.
Your IP’s reputation also matters. About 20 requests were sent from one residential IP, and most came from clients that Zillow refused. After that, Zillow refused even the Chrome profile that had passed minutes earlier, and the block ended within 6 minutes.
Sessions with Chrome’s TLS fingerprint and reused cookies behaved differently. Across 5 such sessions, 429 of 430 listing requests returned the page. The one failure was an HTTP 502, not a block. HUMAN refused none of the 430, including 250 requests from one IP in 12 minutes.
So treat a refusal as a signal to pause that IP, not to retry immediately. Measure the block rate per IP before you decide how many proxy IPs you need. For IP rotation and other ways to keep the block rate low, see our guide to web scraping without getting blocked.
Scrape Zillow with Python and curl_cffi
The scraper below reads the same JSON the page uses. It needs Python 3.10 or newer and curl_cffi, which our guide to web scraping with curl_cffi introduces. Install the library in a virtual environment:
python3 -m venv .venv
source .venv/bin/activate  # on Windows: .venv\Scripts\activate
pip install curl_cffi
This script, zillow_diy.py, fetches a Fort Wayne search page, then reads 3 listings from it:
"""Scrape Zillow with a browser's TLS fingerprint and the page's embedded JSON."""
import json
import re
import time

from curl_cffi import requests

NEXT_DATA = re.compile(
    r'<script id="__NEXT_DATA__" type="application/json">(.*?)</script>', re.S
)
# Chrome TLS + matching headers; keep one session per IP
session = requests.Session(impersonate="chrome")


def next_data(url: str) -> dict:
    resp = session.get(url, timeout=30)
    match = NEXT_DATA.search(resp.text)
    # A block can be a 403 or a 200 captcha page,
    # so test for the data, not the status
    if resp.headers.get("x-px-blocked") or not match:
        raise RuntimeError(f"no page data for {url} (HTTP {resp.status_code})")
    resp.raise_for_status()  # Zillow's 404 page also contains __NEXT_DATA__
    return json.loads(match.group(1))


def search_page(city: str, page: int) -> tuple[list[dict], int]:
    """One server-rendered page of results, plus the total that Zillow reports."""
    url = f"https://www.zillow.com/{city}/{page}_p/"
    cat1 = next_data(url)["props"]["pageProps"]["searchPageState"]["cat1"]
    return cat1["searchResults"]["listResults"], cat1["searchList"]["totalResultCount"]


def listing(url: str) -> dict:
    """The server-rendered part of a listing: gdpClientCache is double-encoded JSON."""
    props = next_data(url)["props"]["pageProps"]["componentProps"]
    cache = json.loads(props["gdpClientCache"])
    record = {}
    for query_result in cache.values():  # e.g. ForSalePriorityQuery{...}
        record.update(query_result.get("property") or {})
    return record


if __name__ == "__main__":
    cards, total = search_page("fort-wayne-in", 1)
    print(f"page 1: {len(cards)} listings of {total} reported")
    for card in cards[:3]:
        time.sleep(2)
        home = listing(card["detailUrl"])
        history = home.get("priceHistory") or []
        print(home["zpid"], home["homeStatus"], home["price"], home["bedrooms"], "bd",
              home["livingArea"], "sqft | priceHistory:", len(history))
When run with python zillow_diy.py, it found 41 listings on page 1, and 2 of the 3 listings it opened had no price history:
page 1: 41 listings of 1295 reported
73145681 FOR_SALE 649900 4 bd 5124 sqft | priceHistory: 3
73159210 FOR_SALE 699900 4 bd 4132 sqft | priceHistory: 0
73110917 FOR_SALE 239900 3 bd 1468 sqft | priceHistory: 0
The first listing was a Showcase listing, which included its price history in the HTML. For the other 2, the Zillow Scraper API returned 2 and 3 price history events, and the HTML had 0. The whole run took about 11 seconds, including the 2-second pauses.
This approach had 2 limits. First, page 24 of the Fort Wayne city pages still returned 41 listings, but page 25 returned an HTTP 400 error. If your city has more listings than one search can reach, you need smaller searches. Second, the missing price history came only from /graphql/.
Splitting a city usually means zip-code or filtered searches, which use /homes/ and ?searchQueryState= URLs, and the missing price history needs the /graphql/ request. Zillow’s robots.txt disallowed all three, so calling them is a compliance decision for your team. Our guide to robots.txt for web scraping explains how to read and respect those rules.
To run this scraper from many IPs, pass a Bright Data residential proxy to the session. For end-to-end encrypted connections, load the Bright Data certificate for port 44445 with verify="brightdata_root_ca_44445.crt".
Residential IPs come from real people who opted in, so Bright Data residential proxies need an approved company KYC (know your customer) review first. The review approves specific use cases, so describe your Zillow pipeline when you apply. Without KYC, the Web Unlocker API handles unblocking for you, and the Zillow Scraper API in the next section returns listing records with price history.
Scrape Zillow with the Zillow Scraper API
The Zillow Scraper API runs the collection on Bright Data infrastructure, handles unblocking and parsing for you, and returns JSON records. You pay per delivered record, and new accounts get 5K free credits that renew every month. It includes these Zillow scrapers, which the sections below call the listing, price history, search page, and Full Properties scrapers:
| Scraper | Dataset ID | Input | Output |
|---|---|---|---|
| Zillow properties listing information | gd_lfqkr8wm13ixtbd8f5 |
Listing URL, search URL, or location filters | 1 record per listing, up to 139 fields |
| Zillow price history | gd_lxu1cz9r88uiqsosl |
Listing URL | 1 row per price history event |
| Zillow properties search page | gd_m71oxpvxwr113ehqg |
Search URL with searchQueryState |
1 row per search result, 26 fields |
| Zillow Full Properties Information | gd_m794g571225l6vm7gh |
Listing URL or search URL | 1 record per listing, with snake_case field names such as price_history |
All 4 collect by URL through the same API request, so you only change the dataset ID. Bright Data also offers a Zillow Image Scraper API and scrapers for other property sites in its Real Estate Scraper API range. In the Control Panel, the listing scraper shows its 3 input methods and the synchronous and asynchronous modes:
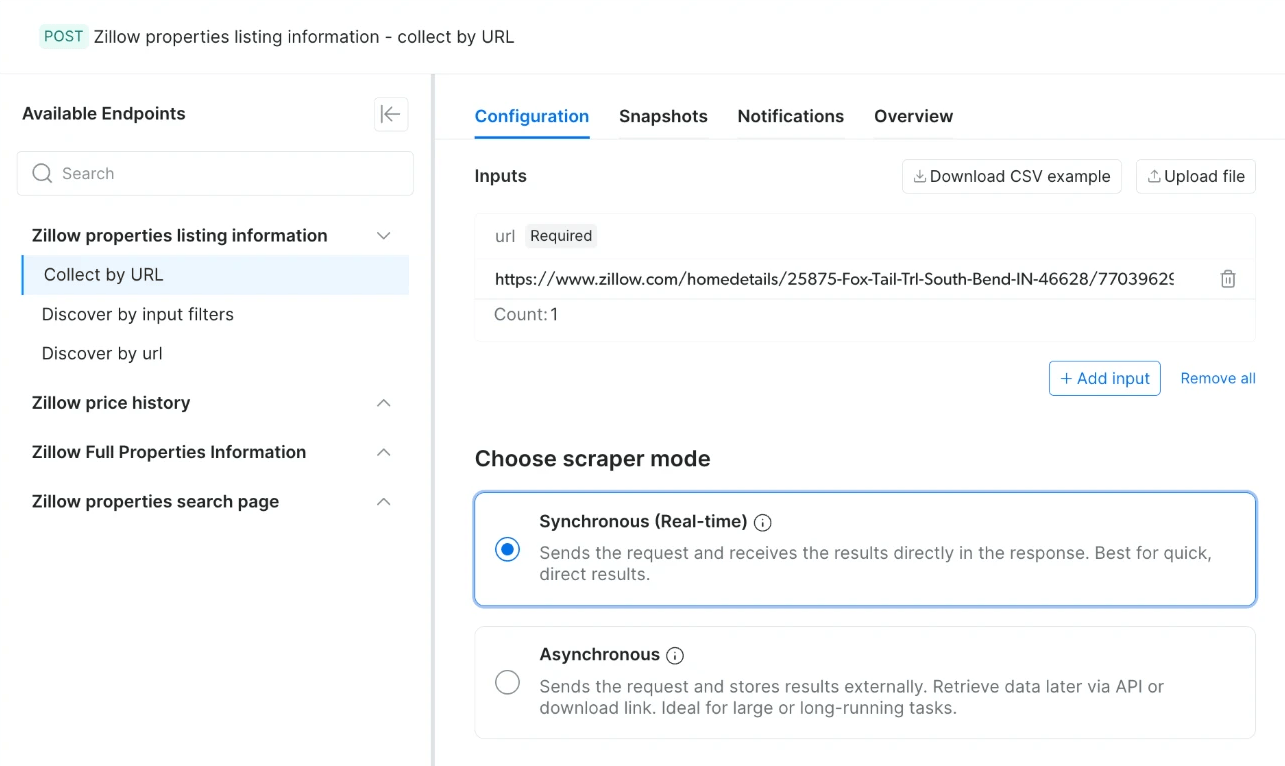
The left panel lists the same 4 scrapers as the table above.
Collect listings and price history
To run the script below, zillow_api.py, you need the requests package (pip install requests) and an API token from the Control Panel. Its collect() function calls the synchronous endpoint and switches to polling when a job takes longer than 1 minute:
"""Listings, price history and discovery with Bright Data's Zillow Scraper API."""
import os
import time

import requests

API = "https://api.brightdata.com/datasets/v3"
HEADERS = {"Authorization": f"Bearer {os.environ['BRIGHTDATA_API_TOKEN']}"}
LISTINGS = "gd_lfqkr8wm13ixtbd8f5"       # Zillow properties listing information
PRICE_HISTORY = "gd_lxu1cz9r88uiqsosl"   # Zillow price history, one row per event


def collect(dataset_id: str, urls: list[str]) -> list[dict]:
    """Up to 20 URLs per synchronous call; a job past 1 minute returns 202."""
    params = {"dataset_id": dataset_id, "include_errors": "true", "format": "json"}
    resp = requests.post(f"{API}/scrape", headers=HEADERS, params=params, timeout=120,
                         json={"input": [{"url": u} for u in urls]})
    if resp.status_code == 202:
        return wait_and_download(resp.json()["snapshot_id"])
    resp.raise_for_status()
    return resp.json()


def discover(search_url: str) -> list[dict]:
    """Every listing in one Zillow search, collected as full records (async)."""
    resp = requests.post(f"{API}/trigger", headers=HEADERS, timeout=60,
                         params={"dataset_id": LISTINGS, "include_errors": "true",
                                 "type": "discover_new", "discover_by": "url"},
                         json={"input": [{"url": search_url}]})
    resp.raise_for_status()
    return wait_and_download(resp.json()["snapshot_id"])


def wait_and_download(snapshot_id: str, poll_s: int = 15) -> list[dict]:
    while True:
        resp = requests.get(f"{API}/progress/{snapshot_id}", headers=HEADERS,
                            timeout=60)
        resp.raise_for_status()
        status = resp.json()["status"]
        if status == "ready":
            break
        if status in ("failed", "canceled"):
            raise RuntimeError(f"snapshot {snapshot_id} ended as {status}")
        time.sleep(poll_s)
    while True:  # the download returns 202 while the file is still being prepared
        resp = requests.get(f"{API}/snapshot/{snapshot_id}", headers=HEADERS,
                            params={"format": "json"}, timeout=300)
        if resp.status_code != 202:
            resp.raise_for_status()
            return resp.json()
        time.sleep(10)


if __name__ == "__main__":
    homes = collect(LISTINGS, [
        "https://www.zillow.com/homedetails/25875-Fox-Tail-Trl-South-Bend-IN-46628/77039629_zpid/",
    ])
    for h in homes:
        print(h["zpid"], h["homeStatus"], h["price"], "| zestimate", h.get("zestimate"),
              "| priceHistory", len(h.get("priceHistory") or []),
              "| taxHistory", len(h.get("taxHistory") or []),
              "| collected", h.get("timestamp"))
    events = collect(PRICE_HISTORY, [
        "https://www.zillow.com/homedetails/2506-Gordon-Cir-South-Bend-IN-46635/77050198_zpid/",
    ])
    for e in events:
        print(e["zpid"], e["date"][:10], e["event"], e["price"], e["source"])
With BRIGHTDATA_API_TOKEN exported, the two calls took 35 to 65 seconds together:
77039629 FOR_SALE 359000 | zestimate 351600 | priceHistory 1 | taxHistory 21 | collected 2026-09-27T11:30:53.846Z
77050198 2023-03-03 Sold 265000 IRMLS
77050198 2023-02-03 Pending sale 264900 IRMLS
77050198 2023-02-01 Listed for sale 264900 IRMLS
The listing record matched what Zillow’s own page loaded, with 1 price history event and 21 years of tax history. Its timestamp showed that Bright Data collected it live, during the request.
The 3 events for the second home, 2506 Gordon Cir, match the price history table on its Zillow page:
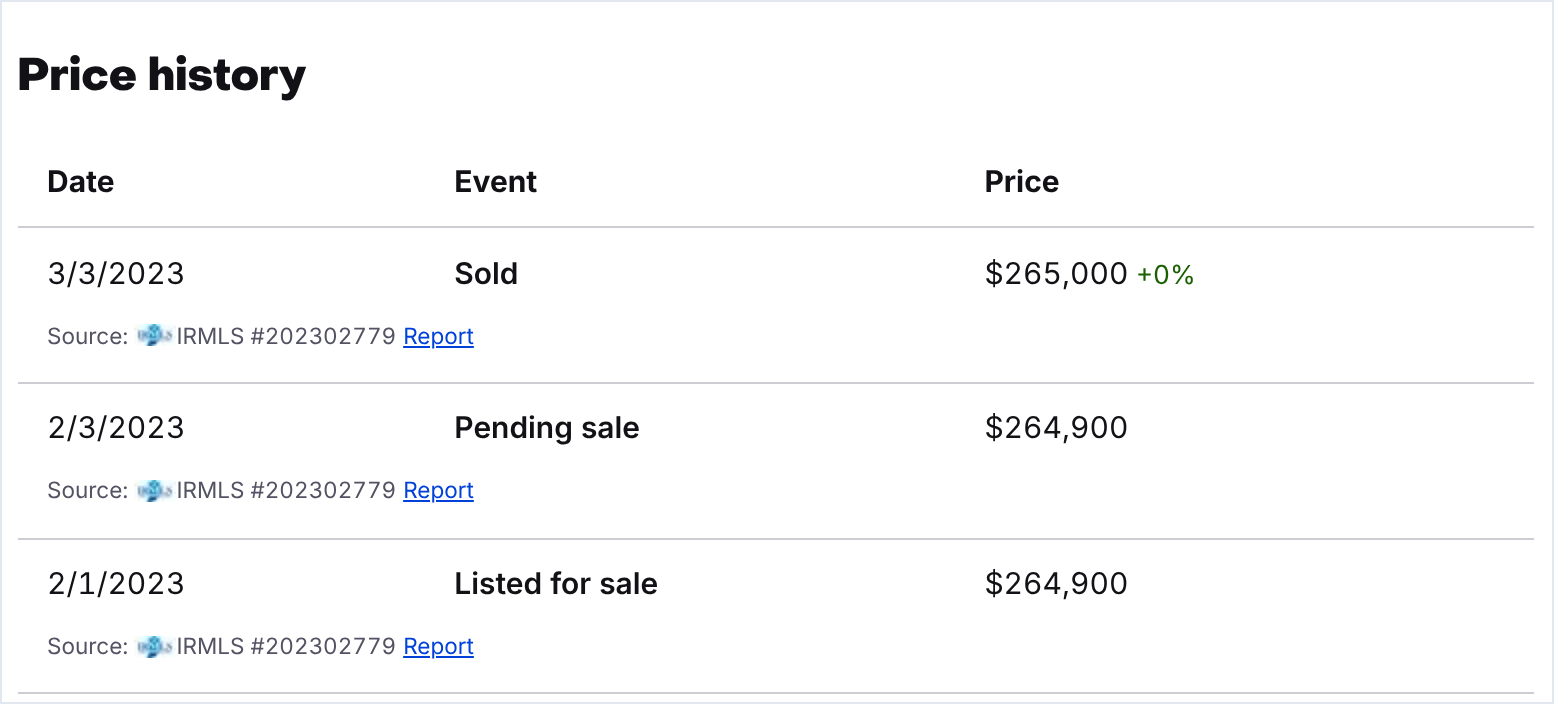
Each row names its source, a local multiple listing service (MLS), which the API output keeps in the source field.
The synchronous /scrape endpoint takes up to 20 URLs and returns the data directly if the job finishes within 1 minute. For a longer job, it responds with HTTP 202 and a snapshot ID instead. A batch of 20 Fort Wayne listings took about 4 minutes, so expect a few minutes of polling before your script prints anything. For larger batches, use the asynchronous /trigger endpoint, which the next section uses for discovery.
Discover every listing in a search
Discovery collects full listing records from one search URL and can exceed the 984-listing limit that stopped the do-it-yourself (DIY) scraper. The discover() function above sends the Fort Wayne city URL, https://www.zillow.com/fort-wayne-in/, to the listing scraper’s Discover by URL input method in an asynchronous /trigger request. In 13 to 17 minutes, it returned 1,295 rows, one for each listing Zillow reported. For a small sample instead, pass up to 20 listing URLs from search_page() in zillow_diy.py to collect().
To limit how many records each search URL returns, for example on a test run, send {"input": [...], "limit_per_input": 50} as the JSON body. Instead of polling, you can have /trigger deliver the results to a webhook or S3, and each snapshot stays downloadable for 30 days.
When you only need search result fields, such as price, beds, and address, the search page scraper is faster. From a Fort Wayne search URL with searchQueryState, it returned 1,154 unique listings in 65 seconds. Use discovery when you need every listing.
Get price history for off-market homes
For homes for sale, the listing scraper’s priceHistory matched Zillow’s own page on 4 of 4 listings. For off-market homes, use the Full Properties scraper. On 6 of 6 off-market homes, it returned the price history in a snake_case price_history array, 1 record per home.
For the same 6 homes, the price history scraper returned 1 row per event: 28 rows in 37 seconds. The two outputs matched exactly.
Billing is per delivered record, so a home with 5 events costs you 5 records from the price history scraper and 1 from Full Properties. Fort Wayne listings averaged 5 events, with a maximum of 29. So send off-market URLs to the Full Properties scraper, and read price_history rather than priceHistory. Use the price history scraper when you want 1 row per event.
Run the same scraper from a terminal or an AI agent
The Bright Data CLI runs the listing scraper as a pipeline command, which suits one-time jobs and coding agents. After you install it with npm install -g @brightdata/cli and run bdata login once, one command returns a listing:
bdata pipelines zillow_properties_listing \
  "https://www.zillow.com/homedetails/25875-Fox-Tail-Trl-South-Bend-IN-46628/77039629_zpid/"
Within 3 minutes, it printed the same record as the API, in one line of JSON that starts:
[{"zpid":77039629,"city":"South Bend","state":"IN","homeStatus":"FOR_SALE","address":{"city":"South Bend","streetAddress":"25875 Fox Tail Trl","zipcode":"46628","state":"IN"},"bedrooms":3,"bathrooms":2,"price":359000,"yearBuilt":1996,If your AI assistant uses the Model Context Protocol (MCP), the Bright Data MCP server exposes the same scraper as the web_data_zillow_properties_listing tool. To use the tool, enable the server’s business tool group. Each record includes a timestamp, so your agent can confirm how current a price is before it quotes one.
For a complete agent built on the same server, see our guide to building a real estate AI agent with CrewAI.
Keep Zillow data complete and current
Before the records reach your data warehouse, check each run against Zillow’s reported total. The checks below also flag error rows, duplicate listings, and missing price history. A sitemap of changed listings then keeps your repeat runs small.
Validate every record
A 200 response confirms that the request succeeded, not that the data is complete. This validator, saved as validate.py, separates error rows, removes duplicate listings, and flags homes that sold before but have no price history. It also counts records collected more than 24 hours ago as stale and compares your record count with Zillow’s reported total:
"""Checks to run on Zillow records before they reach the warehouse."""
from datetime import datetime, timedelta, timezone


def validate(rows: list[dict], reported_total: int | None = None,
             max_age_h: int = 24) -> dict:
    errors = [r for r in rows if r.get("error_code") or r.get("error")]
    records, seen = [], set()
    for r in rows:
        if r in errors or r.get("zpid") in seen:
            continue
        seen.add(r.get("zpid"))
        records.append(r)
    # A home that sold before has price history, so missing history is a gap, not a fact.
    history_gaps = [r["url"] for r in records
                    if (r.get("lastSoldPrice") or r.get("dateSoldString"))
                    and not r.get("priceHistory")]
    cutoff = datetime.now(timezone.utc) - timedelta(hours=max_age_h)
    stale = [r["url"] for r in records
             if datetime.fromisoformat(r["timestamp"].replace("Z", "+00:00")) < cutoff]
    report = {"records": len(records), "error_rows": len(errors),
              "duplicates": len(rows) - len(errors) - len(records),
              "history_gaps": history_gaps, "stale": len(stale),
              "retry": [e.get("input", {}).get("url") for e in errors]}
    if reported_total:
        report["coverage"] = round(len(records) / reported_total, 3)
    return report
The run_pipeline.py script runs discovery for Fort Wayne and then validates the rows:
"""Discover every listing in one Zillow search, then validate the result."""
import json
import time

from validate import validate
from zillow_api import discover

start = time.time()
rows = discover("https://www.zillow.com/fort-wayne-in/")
report = validate(rows, reported_total=1295)  # Zillow's total, e.g. from search_page()
print(f"{len(rows)} rows in {round((time.time() - start) / 60, 1)} min")
counts = {k: (len(v) if isinstance(v, list) else v) for k, v in report.items()}
print(json.dumps(counts))
json.dump(rows, open("fort_wayne.json", "w"))
Discovery returned 1,295 rows, and the validator kept 1,270 of them as records:
1295 rows in 12.9 min
{"records": 1270, "error_rows": 25, "duplicates": 0, "history_gaps": 0, "stale": 0, "retry": 25, "coverage": 0.981}
Coverage was 98.1% of the 1,295 listings that Zillow reported. The run had no duplicates, and no record failed the price history check. The check only flags homes that sold before, so it ignores homes that never had any price history, such as new construction plans.
A missing Sold price in your data isn’t always a scraping error. In 8 Houston listings, neither of the 2 Sold events had a price, as expected in Texas, where sale prices aren’t public record.
Send any URLs that the price history check flags to the Full Properties scraper, and resubmit the retry URLs. For any listing that still lacks a full record, the search page scraper’s results include price, beds, and address.
Refresh only the listings that changed
Zillow’s robots.txt listed a sitemap index for each listing status. The for-sale-by-agent index included a latest.xml.gz sitemap. This script, changed_listings.py, reads it through the Web Unlocker API and keeps the Indiana listings. Before you run it, create a Web Unlocker zone in the Control Panel and put its name in the script:
"""List recently changed Zillow listings in one state, from a sitemap linked from robots.txt."""
import gzip
import os
import re

import requests

SITEMAP = "https://www.zillow.com/xml/sitemaps/us/hdp/for-sale-by-agent/latest.xml.gz"
HEADERS = {"Authorization": f"Bearer {os.environ['BRIGHTDATA_API_TOKEN']}"}


def unlock(url: str, attempts: int = 2) -> bytes:
    # replace "web_unlocker" with the name of your Web Unlocker zone
    payload = {"zone": "web_unlocker", "url": url, "format": "raw", "country": "us"}
    for _ in range(attempts):  # retry once on a transient error
        resp = requests.post("https://api.brightdata.com/request", headers=HEADERS,
                             json=payload, timeout=180)
        # Web Unlocker returns the target's own status code in this header
        if resp.headers.get("x-brd-status-code") == "200":
            return resp.content
    raise RuntimeError(f"{url}: {resp.headers.get('x-brd-status-code')} "
                       f"{resp.headers.get('x-brd-error')}")


body = unlock(SITEMAP)
# the file may arrive already decoded
xml = (gzip.decompress(body) if body[:2] == b"\x1f\x8b" else body).decode()
entries = re.findall(r"<loc>([^<]+)</loc>\s*<lastmod>([^<]+)</lastmod>", xml)
indiana = [(url, mod) for url, mod in entries if re.search(r"-IN-\d{5}/", url)]
dates = [mod for _, mod in entries]
print(f"{len(entries)} changed listings nationwide, {len(indiana)} in Indiana")
print("oldest change:", min(dates), "| newest:", max(dates))
print(indiana[0][0])
The file listed 50K changed listings nationwide, 1,014 of them in Indiana:
50000 changed listings nationwide, 1014 in Indiana
oldest change: 2026-09-24T14:08:00Z | newest: 2026-09-27T07:51:00Z
https://www.zillow.com/homedetails/600-W-Cyprus-Cir-Bloomington-IN-47403/94517948_zpid/
A sitemap file can list at most 50K URLs, and these 50K changes spanned about 3 days. So a daily run can re-collect only the listings in your area that changed since the last run, which keeps its cost low. Send them to collect() 20 URLs at a time, or in one /trigger job. The file lists what changed, not every home on Zillow.
The sitemaps in the 4 for-sale indexes listed 749 of the 1,154 Fort Wayne listings that the search page scraper found, or 65%. None of the 217 new construction listings appeared. Use sitemaps to decide what to re-collect, and use discovery to find what exists.
What each approach costs at scale
The cheapest way to fetch a page often isn’t the cheapest way to get a complete dataset. Each approach below returned Zillow data, but they differ in how complete it is and how much work you still have. Prices are list rates at publication, and our pricing page has current rates:
| Approach | What you pay | Result | Work left for you |
|---|---|---|---|
curl_cffi on your own IPs |
Your servers and proxy traffic | 429 of 430 pages served; searches limited to 984 listings; usually no price history in the HTML | Fingerprint updates, IP reputation, search splitting, price history |
| Web Unlocker API | $1.50 per 1K successful requests | 10 of 10 listing pages, median 4.5 s | Parsing, search splitting, price history |
| Browser API | $8 per GB | 3.97 MB per listing, about $0.03; price history rendered | Browser scripts, parsing |
| Zillow Scraper API | $1.50 per 1K records | All 1,295 Fort Wayne listings found from one URL; price history for homes both for sale and off-market | Validation |
| Zillow datasets | Up to $2.50 per 1K records, $250 minimum order | 137.42M property records in the marketplace, mostly off-market homes | Choosing an update schedule |
Web Unlocker charges only for successful requests and returns the target site’s status code in the x-brd-status-code header, so check that header in your code. A request for a missing listing, for example, returned x-brd-status-code: 404. The Browser API rendered the price history table without extra code, which suits pages that need a full browser session.
The DIY approach also has a maintenance cost that no price in the table shows. One developer who runs a daily Zillow scraper for clients reported that it breaks every quarter when Zillow pushes updates. Zillow’s pages show why. Each listing type used its own GraphQL operation name in the JSON, and card selectors from old tutorials, such as article.list-card, matched nothing.
The datasets have a different purpose: the Bright Data Zillow listing dataset contains more than 137M property records. Most of those records are off-market homes, which suits valuation models and research that needs every property, not only homes for sale. Buyers can get updates daily, weekly, monthly, or on a custom schedule, and the Scraper API collects current listings on demand.
Compare the cost of the whole pipeline, including discovery, listing details, price history, and retries, not the cost of a single page fetch. Our guide to managed vs. DIY web scraping estimates the full cost of running scrapers in-house.
Final thoughts
To fetch a Zillow page, you need a client with a browser’s TLS fingerprint. Getting complete data is harder, because each search stops at 984 listings and most listing pages load price history in a second request. For a one-time job on a small area without price history, the curl_cffi scraper is enough. For every listing with its price history on a schedule, the Bright Data Zillow Scraper API handles both for you.
Create a free Bright Data account, run discovery on one search URL from your market, and compare the row count with Zillow’s reported total.
FAQ
Can you scrape data from Zillow?
Yes, if your client uses a browser’s TLS fingerprint. The Python requests library gets an HTTP 403, while curl_cffi impersonating Chrome gets the page. Listing fields are in JSON embedded in each page, so a parser can read them without depending on the HTML layout.
Why is Zillow not showing all listings?
Zillow limits each search. Its pagination shows 20 pages, but the site serves 24 pages of 41 listings each, so one search reaches 984 listings at most. Split large areas into smaller searches, or use the Bright Data Zillow Scraper API, which found all 1,295 Fort Wayne listings from one URL.
How do I get Zillow price history data?
Use the Bright Data Zillow Scraper API. Its for-sale listing records include price history, and its Full Properties scraper returns it for off-market homes. Most listing pages load price history in a second request, so HTML-only scrapers miss it. For market trends by zip code, Zillow Research publishes free CSVs.
Does Zillow have an open API?
No. Zillow Group’s APIs for MLS listings, public records, and Zestimates require approval, limit daily calls, and restrict data storage. Zillow Research offers free CSVs of market-level data only. For listing-level data, the Bright Data Zillow Scraper API returns listings and price history as structured JSON.
How can you scrape Zillow for free?
Use curl_cffi, a free Python HTTP client that impersonates Chrome, to fetch listing pages slowly, and parse the embedded JSON. That method stops at 984 listings per search and misses most price history. New Bright Data accounts get 5K free credits a month with no credit card, enough for 5K Zillow Scraper API records.
How can you scrape Zillow without coding?
Use a managed scraper’s no-code dashboard. In the Bright Data Control Panel, open the Zillow Scraper API, paste listing or search URLs, and start the run. Then download the records as JSON or CSV. For a whole market, you can buy a ready-made Zillow dataset instead of scraping.
Can ChatGPT do web scraping?
ChatGPT can write scraper code, but it isn’t built to collect Zillow data at scale without other tools. An AI agent gets structured listings by calling the Zillow listing tool in the Bright Data MCP server, then works with the returned JSON. Check each record’s timestamp before your agent quotes a price.


Technical Writer
 5 years experience
Satyam Tripathi helps SaaS and data startups turn complex tech into actionable content, boosting developer adoption and user understanding.