Scraping Walmart at scale gives pricing teams the prices, stock, and reviews that shoppers see, collected from thousands of pages on a schedule.
Walmart’s bot check is only the first problem. When I fetched product pages from rotating IPs, Walmart priced each page for a different store. If your scraper doesn’t set a zip code or store, Walmart picks a store based on the IP address. Your price table then mixes stores, and no error warns you.
This guide explains Walmart’s defenses and listing limits, which method to choose, and how to collect store-level prices in Python.
TL;DR
- The store can change the price. Across 8 zip codes, the same gallon of milk ranged from $2.42 to $6.28.
- Setting the store per request worked. With a store ID, Bright Data’s Walmart Scraper API returned the exact prices the browser showed at both stores I compared.
- A Walmart category listing stopped near 390 unique products. It claimed about 2,450 items but showed 389, and splitting it into 9 price ranges found 2,069.
- A 200 status didn’t mean success. Walmart served its “Robot or human?” challenge with HTTP 200, so check the content and store ID of every record.
How Walmart detects scrapers
Walmart’s product pages were protected by Akamai, HUMAN, and an F5 web application firewall (WAF). The headers, cookies, and runtime config of a single product page response showed all 3:
| Layer | How I recognized it | What scripts received |
|---|---|---|
| Akamai edge | x-ak-protocol and server-timing: ak_p headers, the akavpau_p2 cookie, and the Bot Manager cookies ak_bmsc and bm_sv in browser sessions |
418 Access Denied for GraphQL calls without Walmart’s client headers |
| HUMAN, formerly PerimeterX | A first-party sensor at /px/PXu6b0qd2S/init.js and the _pxhd, _px3, and _pxvid cookies |
A 307 redirect to /blocked, then a “Robot or human?” press-and-hold page with status 200 |
| F5 WAF | 6 TS-prefixed cookies in a browser session, such as TS012768cf |
No blocking response traced to it |
Plain headless Chrome, launched with Playwright, got HUMAN’s press-and-hold CAPTCHA both times I tried. The challenge page looked like a normal Walmart page and returned status 200:
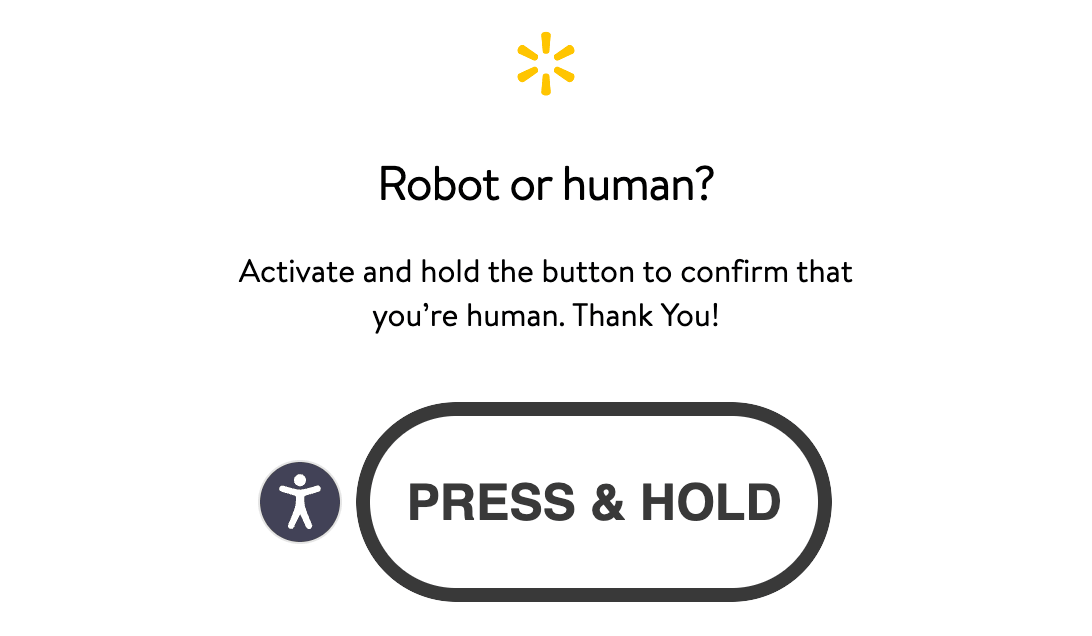
A scraper that checks only the status code would save this page as a success.
The same runtime config enabled ThreatMetrix, a device-profiling service, only on account pages such as cart, orders, wallet, and subscriptions. That list didn’t include product, category, or review pages, the ones price tracking needs.
Walmart’s own bot flag didn’t show whether a request passed. Each product page embedded a psych object with fields such as isAkamaiBot. That field was "1" even on pages that Walmart served in full, so judge a response by its content and its store ID.
Which HTTP clients got challenged
On the same IP, whether Walmart showed a challenge depended on the HTTP client. I requested the same 5 Walmart product URLs with 6 HTTP clients from a non-US home broadband IP, 1 URL per round. In each round, the clients requested that URL one at a time, 2 seconds apart, and each kept its own cookie jar.
Of the 5 URLs, 3 were dead, and they still gave a clear signal. A client that passed got Walmart’s 404 page, while a challenged client got the challenge page:
| Client | Challenge pages in 5 requests |
|---|---|
| curl with LibreSSL | 4 |
Python requests |
2 |
httpx with HTTP/2 |
1 |
curl_cffi impersonating Firefox |
2 |
curl_cffi impersonating Chrome |
0 |
curl_cffi impersonating Safari |
0 |
In the 2 rounds with live product URLs, curl, requests, and the Firefox profile got the challenge. In the same rounds, seconds apart, the Chrome and Safari profiles got the product page.
Our curl_cffi guide covers the impersonation setup, and our TLS fingerprinting article covers what the handshake exposes.
Through a US session on Bright Data’s residential proxies, the same 6 clients made 30 requests without a single challenge page. Each client got a US residential IP. Results depend on each client and proxy combination, so test yours against Walmart at the concurrency you plan to run.
Where Walmart pages keep their data
Walmart rendered product, search, category, and review pages with the Next.js pages router. Each page embedded its data model as JSON in a __NEXT_DATA__ script tag. On a candy product page, that JSON was 401 KB of the 592 KB of HTML. These JSON paths held the fields that matter:
- Product pages:
props.pageProps.initialData.data.product, including price, availability, seller, and alocationobject - Search and category pages:
props.pageProps.initialData.searchResult.itemStacks[].items, with the reported total insearchResult.aggregatedCount - Review pages:
props.pageProps.initialData.data.reviews, with its own pagination block
The tag had a nonce attribute, so match it by id with a pattern that allows extra attributes.
In the browser, Walmart’s GraphQL API served data that the page didn’t embed, such as item details further down the page. The API used persisted queries, which are saved queries that the client calls by a SHA-256 hash in the URL:
/orchestra/pdp/graphql/ItemByIdBtf/<sha256-hash>/ip/<item-id>Walmart blocked scripted replays of these GraphQL calls. Without Walmart’s x-o-* client headers, a scripted call to /orchestra/home/graphql got Akamai’s 418. With the headers, it got a HUMAN block as JSON with status 412.
Those headers also included the web app version, which changes with Walmart’s releases, so values hard-coded in older open-source scrapers become outdated.
The script below fetches a product page through Bright Data’s Web Unlocker API, then reads the product data and the store it was priced for. It needs Python 3.9 or later and requests, your API key in BRIGHTDATA_API_TOKEN, and your Web Unlocker zone name in BRIGHTDATA_UNLOCKER_ZONE:
import json
import os
import re

import requests

API_KEY = os.environ["BRIGHTDATA_API_TOKEN"]
ZONE = os.environ["BRIGHTDATA_UNLOCKER_ZONE"]  # your Web Unlocker zone name
NEXT_DATA = re.compile(r'<script id="__NEXT_DATA__"[^>]*>(.*?)</script>', re.S)


def fetch(url: str) -> tuple[str, str]:
    """Return the page's status code and HTML."""
    r = requests.post(
        "https://api.brightdata.com/request",
        headers={"Authorization": f"Bearer {API_KEY}"},
        json={"zone": ZONE, "url": url, "format": "raw", "country": "us"},
        timeout=180,
    )
    r.raise_for_status()
    # Web Unlocker reports the target page's status code in this header.
    return r.headers.get("x-brd-status-code", ""), r.text


def parse_product(html: str) -> dict:
    if "Robot or human" in html:
        raise RuntimeError("challenge page, not a product page")
    match = NEXT_DATA.search(html)
    if match is None:
        raise RuntimeError("no __NEXT_DATA__ block in the page")
    data = json.loads(match.group(1))["props"]["pageProps"]["initialData"]
    product = data["data"]["product"]
    location = product.get("location") or {}
    price = (product.get("priceInfo") or {}).get("currentPrice") or {}
    return {
        "us_item_id": product.get("usItemId"),
        "name": product.get("name"),
        "price": price.get("price"),
        "availability": product.get("availabilityStatus"),
        "seller": product.get("sellerName"),
        "store_id": (location.get("storeIds") or [None])[0],
        "zip": location.get("postalCode"),
    }


status, html = fetch("https://www.walmart.com/ip/10450114")
if status != "200":
    raise RuntimeError(f"page status {status}, not 200")
print(status, json.dumps(parse_product(html), indent=2))
A run returned a live product priced for a store that the script never requested. Your run will likely show another store:
200 {
  "us_item_id": "10450114",
  "name": "Great Value Whole Vitamin D Milk, Gallon",
  "price": 3.32,
  "availability": "IN_STOCK",
  "seller": "Walmart.com",
  "store_id": "3081",
  "zip": "95829"
}
The Web Unlocker API reports Walmart’s own status code in the x-brd-status-code header, as its error codes page describes. The script checks that header before it parses the page.
Parse the embedded JSON first. For data the page doesn’t embed, call GraphQL from a browser session, because scripted calls were blocked.
Why a Walmart price depends on the store
Walmart’s Affiliate Marketing API documentation said an item’s price and availability depend on the zip code and store ID of the request. On in-store prices, a Walmart spokesperson told CNBC that “the price you see is the same for everyone in any given store.” Each product page was priced for a specific store.
The page named that store in its “Pickup from” text, and the price varied by store. The same gallon of milk cost $3.32 at the Sacramento store Walmart assigned and $3.03 at an Atlanta store I chose manually:
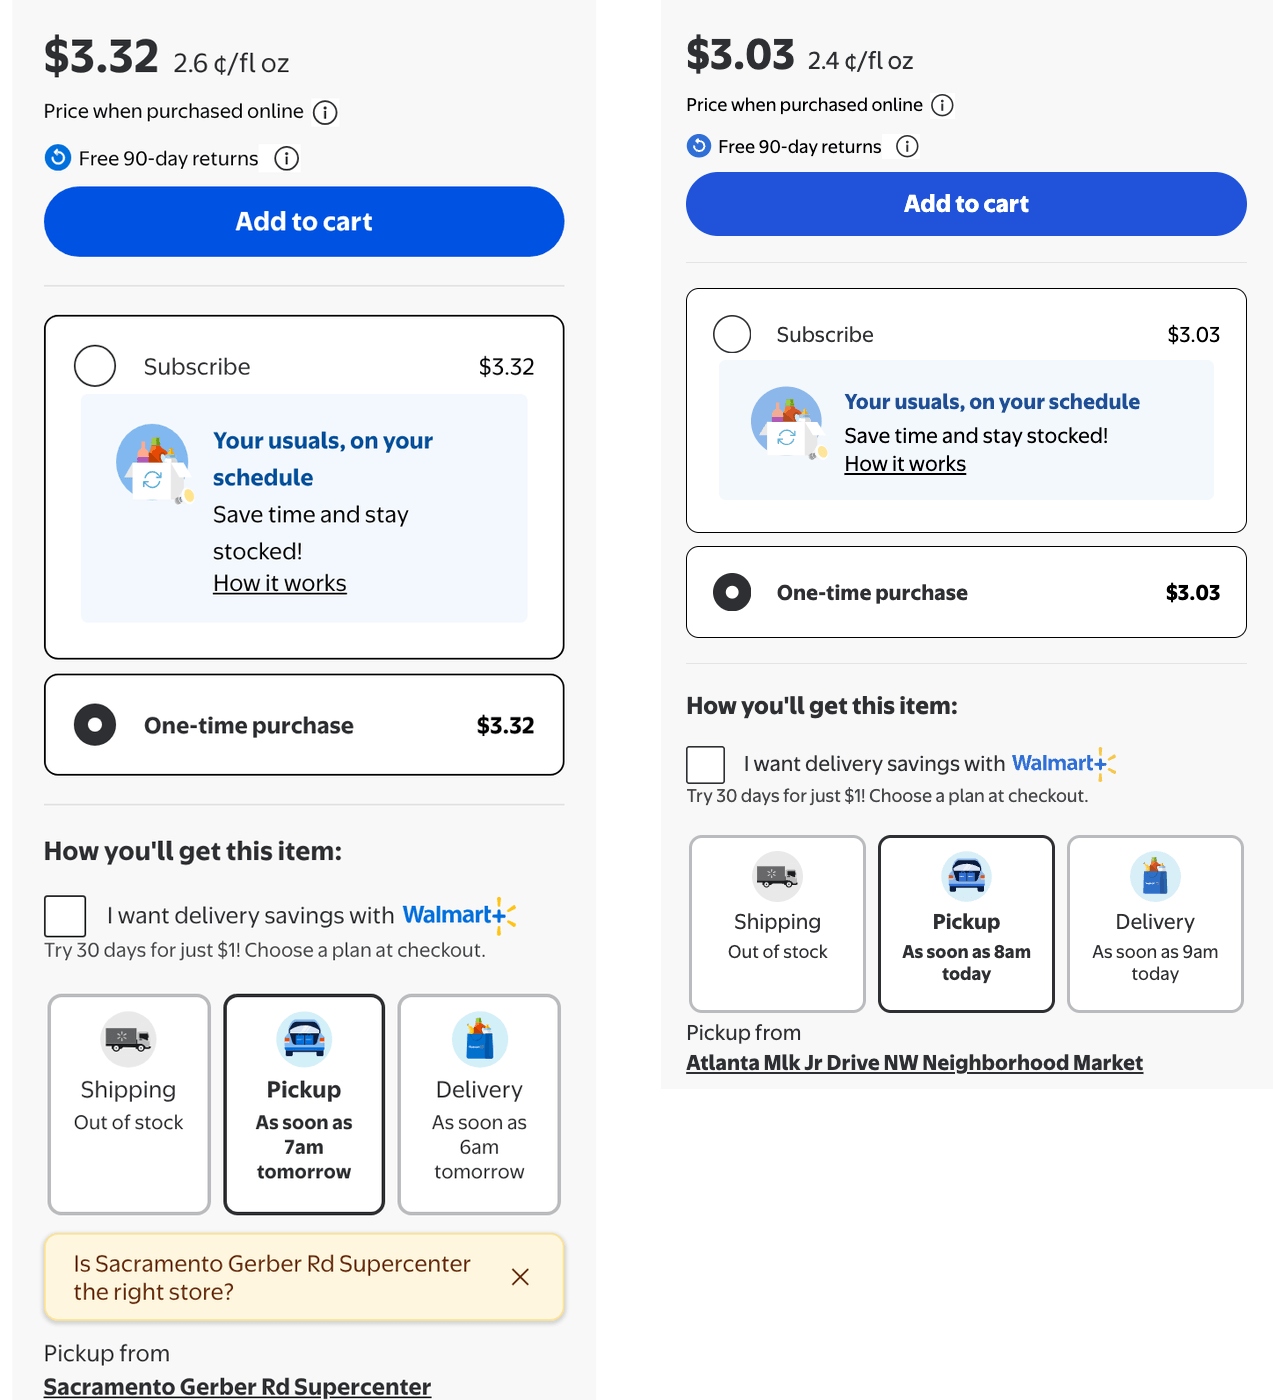
Without the store in each record, these 2 prices for the same milk would look like a price change.
When a request included no location, Walmart chose a store, recorded it in the page’s location object, and marked the choice as IMPLICIT. Some connections got a default store, store 3081 in Sacramento, zip 95829, which is the store in the script’s output. Walmart based the store on the exit IP, so rotating IPs also changed the store:
- Rotating IPs: each of 48 product pages was priced for a different store.
- Other connections: a non-US broadband IP and a satellite IP both got the default store. Walmart located another session in Big Water, Utah, zip 84741, and gave it the default store too.
Why setting the store from a script was unreliable
I tried 2 ways, and both left the choice of store to Walmart:
- Location cookies: I set
assortmentStoreIdand a hand-builtlocGuestDatacookie. Of 9 requests with the cookies, 6 got the challenge page, while 0 of 3 requests without them did. The 3 that passed kept the IP’s store. - Choosing the exit IP: Walmart used its own IP geolocation. That geolocation matched a standard IP lookup’s zip code on only 5 of 11 pages, so an IP’s zip code didn’t predict the store.
How a zip code or store ID sets the store
The zipcode input of Bright Data’s Walmart Scraper API sets the location for each request. I collected 4 grocery items in each of 8 zip codes, and the same gallon of Great Value whole milk showed 8 different prices:
| Zip code | Store ID in the record | Price |
|---|---|---|
| 60614, Chicago, IL | 5402 | $2.42 |
| 75201, Dallas, TX | 5823 | $2.46 |
| 72712, Bentonville, AR | 100 | $2.72 |
| 33177, Miami area, FL | 6397 | $2.92 |
| 94103, San Francisco, CA | 2648 | $3.32 |
| 10001, New York, NY | 3520, Secaucus Supercenter, NJ | $4.07 |
| 99504, Anchorage, AK | 4359 | $4.98 |
| 96813, Honolulu, HI | 3478 | $6.28 |
Bananas ranged from $0.13 in Bentonville to $0.42 in Honolulu. Eggs cost $1.67 in all 8 zip codes, but pickup was unavailable in 3 of them. Record availability per store, the same way as price.
Setting the store still mattered for protein powder, which varied less than milk. I collected 387 of its products twice, first without a zip code and then with Bentonville’s zip code. The first run’s records came from 170 different stores, and 24 products changed price between the 2 runs.
A zip code isn’t a store. Zip 10001 in Manhattan resolved to the Secaucus Supercenter in New Jersey, store 3520. Walmart’s store picker listed several stores for zip 30303 in Atlanta:
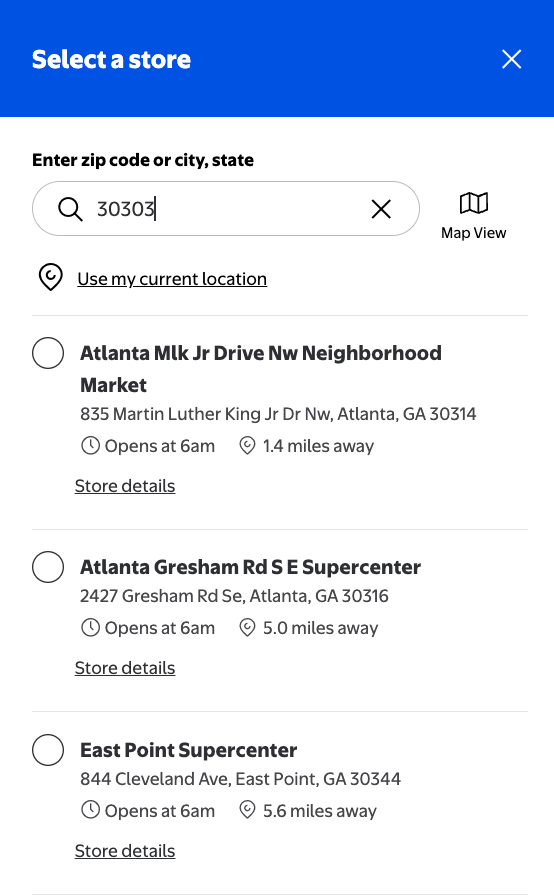
The first 3 stores listed for zip 30303. A zip code points to an area, and a store ID points to a store.
When you need a specific store, the Walmart Scraper API also takes a store_id. Each store’s page URL on walmart.com contained its ID, such as 100 in walmart.com/store/100-bentonville-ar. Walmart’s store sitemap, walmart.com/sitemap_store_main.xml, listed these URLs by store type, including pages for 3,582 Supercenters and 675 Neighborhood Markets. When I set the 2 stores from the milk screenshots, the API returned the prices the browser showed, $3.32 in Sacramento and $3.03 in Atlanta.
Repeat runs for the same zip code returned the same prices. Chicago milk cost $2.42 again in 2 later runs within 90 minutes. In Bentonville, 2 jobs that ran at the same time returned the same prices for all 39 products that both jobs collected. A day later, zip 72712 still resolved to store 100, and the milk there still cost $2.72.
What to record with each price
Both milk prices in the screenshots had Walmart’s label “Price when purchased online,” so treat scraped prices as each store’s online prices.
Availability also depends on the fulfillment method. On the milk page, shipping showed out of stock while pickup and delivery from the same store showed in stock. Walmart Scraper API records had separate pickup and delivery flags for this. Their Fulfillment_type field named who fulfilled the order, such as the seller or Walmart Fulfillment Services.
Walmart’s unit prices also used different units. The same gallon showed a unit_price of 0.023 per fluid ounce in Miami and 1.02 per quart in New York. Recompute unit prices from pack size. For the milk, the complete record listed pack size under specifications as 128 fluid ounces.
Prices also change over time. Walmart reported more than 11,000 rollbacks, its term for temporary price cuts, in a single quarter.
Key every price by store ID, zip code, and timestamp, and record availability for each fulfillment method. Reject any record priced for a location you didn’t request.
How to work within Walmart’s listing and review limits
Walmart’s protein powder category page reported about 2,450 items and a maxPage of 25. Pages 1 to 10 held about 50 product slots each, of which about 10 were sponsored. Pages after page 11 had no products:
| Category page | Product slots returned |
|---|---|
| 1 to 10 | 47 to 50 per page |
| 11 | 13 in one run, 0 in another |
| 12 to 25 | 0 |
Pages 1 to 11 had 501 slots in total, and they held 389 unique products. This pagination limit came from Walmart’s listing itself, so it appeared the same way in every session I ran.
In a desktop browser, the page numbers still reached 25, and page 12 returned Walmart’s not-found page:
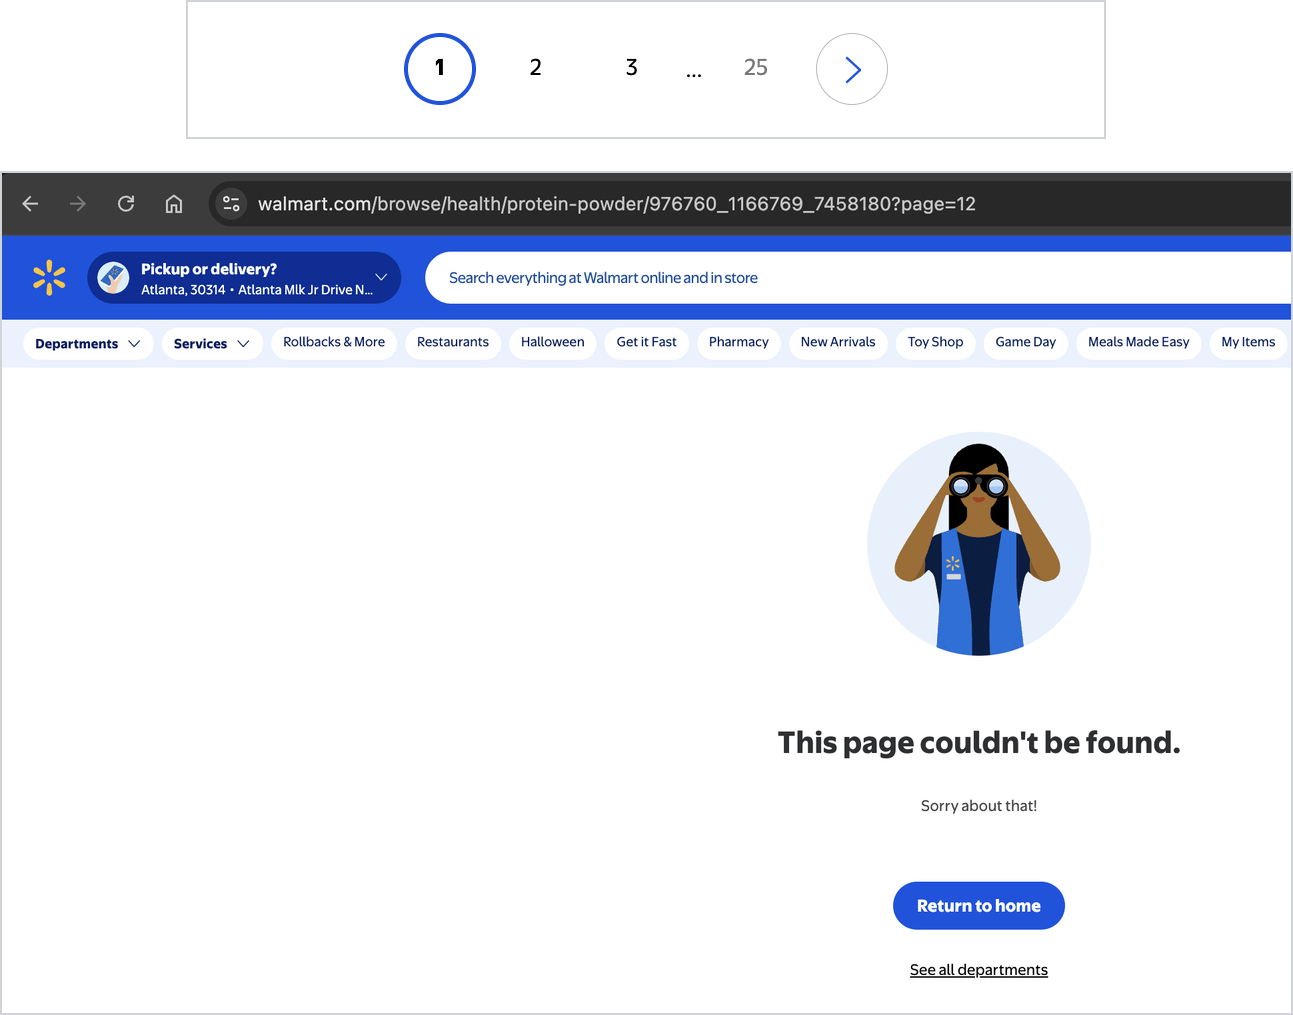
A scraper that followed the page numbers to 25 got nothing past page 11.
How to split a category into price ranges
The Walmart Scraper API’s category discovery accepts category URLs with Walmart’s price filters, so you can collect a category range by range. As a baseline, the unfiltered category URL returned 393 unique products, close to the 389 the listing showed.
Walmart’s min_price and max_price URL parameters split the category into price ranges, and each range reported its own count. I first split the category at $15, $25, $35, $50, and $75. I then split the 3 ranges that reported more than 500 products, at $42, $62, and $100, and ran discovery on all 9 ranges:
| Price range | Products Walmart reported | Unique products discovered |
|---|---|---|
| $0 to $15 | 75 | 60 |
| $15 to $25 | 230 | 189 |
| $25 to $35 | 429 | 330 |
| $35 to $50, as 2 ranges | 718 | 569 |
| $50 to $75, as 2 ranges | 592 | 484 |
| $75 and up, as 2 ranges | 519 | 444 |
The 9 ranges returned 2,069 unique products, which was about 5 times the baseline. The column sums to 2,076 because a few products appeared in 2 ranges. No range returned more than 330 unique products, so each stayed under the pagination limit.
Walmart’s reported counts were 17% to 30% higher than the unique products each row returned. In the $0 to $15 range, the 2 listing pages showed only 62 unique products, not the 75 Walmart reported. Discovery returned 60, close to the 62 on the pages. Treat Walmart’s reported count as an upper bound.
Split each category into price ranges until each range returns fewer unique products than its pagination limit, which was about 390 for protein powder.
Walmart’s product sitemaps listed far more products than a category listing. Through the Web Unlocker API, I fetched a product sitemap index that pointed to 5,916 sitemap files. The first file alone held 50,000 product URLs from mixed categories, and each URL had only a last-modified date. Use sitemaps for catalog-wide URL lists, and use price ranges for the categories you track.
Where search results and reviews stop
Search had its own page limit. A search for “laptop” reported 20,251 results but a maxPage of 14, at 40 results per page, so at most 560 results were reachable. Where you can, discover products through categories or sitemaps.
When you need the search results themselves, as in share-of-shelf tracking, use the Walmart products search scraper, whose records flagged sponsored results. A search for “protein powder” returned 568 records, including 164 sponsored ones. Among those records, 55 item IDs appeared more than once, and 52 of them were both sponsored and organic results. Keep both placements for share-of-shelf, and deduplicate by item ID for a product list.
Reviews had their own pagination limit. The milk page showed 399,133 ratings, of which 27,412 had written text. Under the default sort, its pagination showed 10 reviews per page and stopped at 10,000. Page 1001 didn’t fail but returned page 1 again, so stop at the page count Walmart reports instead of waiting for an empty page.
The Walmart reviews scraper takes a sort_by input for review order. For a candy product with 127 ratings, it returned all 41 written reviews.
Why your URL list needs regular updates
About 1 in 7 old product URLs were dead. Of 150 product URLs about 2 years old, 22 returned 404 or 410, and another 37 live pages had no price.
Run discovery again often enough to keep your URL list current, so each job collects live products.
How to choose a method to scrape Walmart
Each method below does a different amount of the work for you, from raw page access to finished records. Each product’s pricing page lists its current prices:
| Method | What it handles for you | Billing basis | Store selection | Current pricing |
|---|---|---|---|---|
| Rotating residential proxies with your own parser | Rotating residential IPs for your own client and parser | Per GB of traffic | Set by Walmart from the exit IP | Residential proxies pricing |
| Web Unlocker API with your own parser | Unblocking, with Walmart’s status code in a response header | Per successful request | Set by Walmart from the exit IP | Web Unlocker pricing |
| Walmart Scraper API | Discovery, collection, and parsed records with store fields | Per delivered record | Set per request with zipcode and store_id |
Web Scraper API pricing |
| Browser API | A full browser with a built-in CAPTCHA solver, for interactive flows | Per GB of traffic | Set by choosing a store on the page | Browser API pricing |
| Walmart datasets | Ready-made Walmart product, review, and seller data | Per record | Set at collection time | Datasets pricing |
Residential proxies and the Web Unlocker API deliver the raw page, so your team runs the parsing and the store validation. The Walmart Scraper API returns parsed records you can validate directly.
Residential proxies give you full control of each request. You choose the client, headers, and parser, which suits teams that already run their own stack.
The Web Unlocker API handles access so you can focus on parsing. It also fetched Walmart’s product sitemaps for catalog-wide URL lists.
The Walmart Scraper API fits store-level work at volume. Its zipcode and store_id inputs set the location, and its records report the store they were priced for, so your pipeline can verify every record.
Use the Browser API for interactive flows. It runs a full browser, which suits exploring a page and capturing new endpoints. For catalog-scale volume, combine it with the Walmart Scraper API or the Web Unlocker API.
Datasets fit backfills and catalog-wide analysis. The Walmart datasets offer a choice of refresh schedules.
Agents can run single-product lookups. The Bright Data CLI has a walmart_product pipeline, and the Bright Data MCP server has a web_data_walmart_product tool. From a product URL, the CLI pipeline returned a record with the same schema as Walmart Scraper API records.
Compare every method by cost per valid record, because a page priced for the wrong store isn’t a usable store-level record.
How to build a store-level price pipeline with the Walmart Scraper API
To scrape Walmart at scale, discover URLs by price range, set a zip code or store ID on each, and check each record’s store ID. The Walmart Scraper API has separate scrapers for products, reviews, sellers, and search, all available through the same REST API. New accounts can start on the free tier. Each scraper has its own dataset ID and inputs:
| Scraper | Dataset ID | Main inputs | Use it for |
|---|---|---|---|
| Walmart products | gd_l95fol7l1ru6rlo116 |
url with zipcode and optional store_id, or discovery by category_url, keyword, or sku |
Store-level prices, product details, and images |
| Walmart products zipcodes | gd_m693oc1r1gebnayxq |
url with zip_code and optional store_id, or discovery by category or keyword |
Pickup store, stock quantity, and delivery ETA |
| Walmart reviews | gd_mpql1v8g2o8o6l1wzd |
url with optional sort_by |
Written reviews |
| Walmart sellers info | gd_m7ke48w81ocyu4hhz0 |
Seller page url |
Seller profiles |
| Walmart products search | gd_m7khey0wb7wviejgj |
Search page url |
Search results with sponsored flags |
In the control panel, the Walmart products scraper took a zipcode and a store_id with each URL:
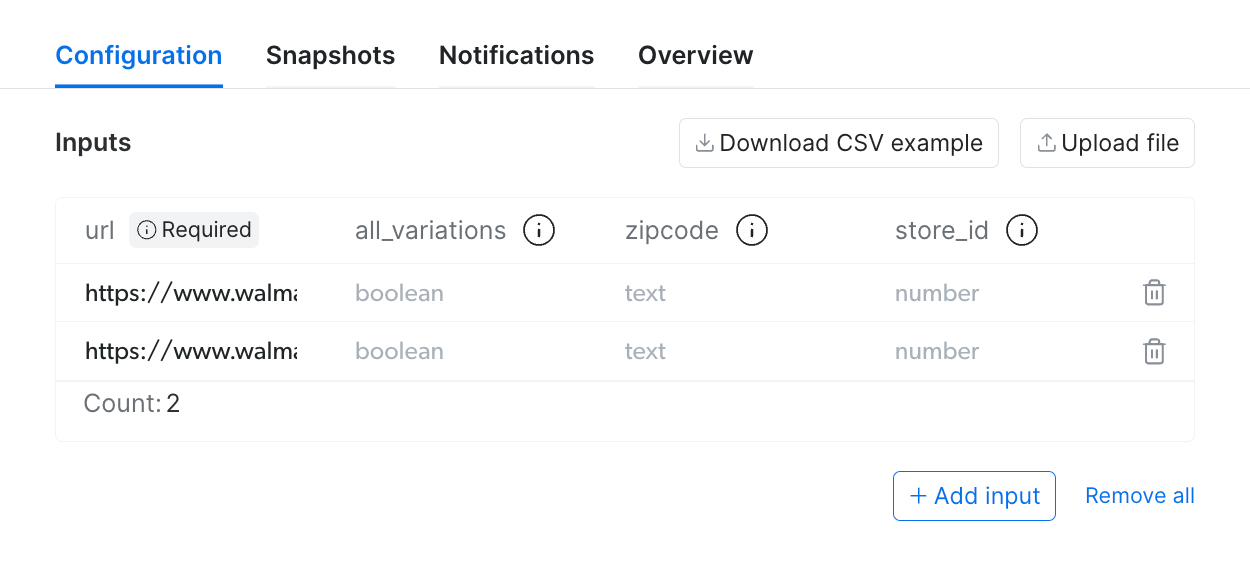
The zipcode and store_id columns request a store for each record.
Create the shared helpers
These helpers need an API key in BRIGHTDATA_API_TOKEN. The post function honors Retry-After, so your client waits and retries when it reaches the async request limits:
import os
import time

import requests

API = "https://api.brightdata.com/datasets/v3"
HEADERS = {"Authorization": f"Bearer {os.environ['BRIGHTDATA_API_TOKEN']}"}
WALMART_PRODUCTS = "gd_l95fol7l1ru6rlo116"


def post(url, **kwargs):
    """POST that honors Retry-After to stay within the rate limits."""
    for attempt in range(6):
        r = requests.post(url, headers=HEADERS, timeout=120, **kwargs)
        if r.status_code != 429:
            r.raise_for_status()
            return r
        time.sleep(int(r.headers.get("Retry-After") or 2 ** (attempt + 1)))
    r.raise_for_status()


def wait_and_download(snapshot_id, every=30):
    while True:
        r = requests.get(f"{API}/progress/{snapshot_id}", headers=HEADERS,
                         timeout=60)
        r.raise_for_status()
        status = r.json()["status"]
        if status == "ready":
            break
        if status in ("failed", "canceled"):
            raise RuntimeError(f"{snapshot_id} ended as {status}")
        time.sleep(every)
    while True:  # 202 means the file is still being assembled
        r = requests.get(f"{API}/snapshot/{snapshot_id}", headers=HEADERS,
                         params={"format": "json"}, timeout=300)
        if r.status_code == 200:
            return r.json()
        r.raise_for_status()
        time.sleep(10)
The discovery and collection blocks below reuse post, wait_and_download, API, and HEADERS, so keep all 3 blocks in the same file.
Discover product URLs by price range
These functions split a category into price ranges and return a sorted list of unique URLs:
def price_ranges(category_url, edges):
    """One discovery input per price range.

    Pick edges that keep each range under the pagination limit.
    """
    sep = "&" if "?" in category_url else "?"
    urls = [f"{category_url}{sep}min_price={lo}&max_price={hi}"
            for lo, hi in zip(edges, edges[1:])]
    return [{"category_url": u, "all_variations": False} for u in urls]


def discover(category_url, edges, per_range=600):
    body = {"input": price_ranges(category_url, edges),
            "limit_per_input": per_range}
    params = {"dataset_id": WALMART_PRODUCTS, "type": "discover_new",
              "discover_by": "category_url", "include_errors": "true"}
    job = post(f"{API}/trigger", params=params, json=body)
    records = wait_and_download(job.json()["snapshot_id"])
    urls = {r["url"].split("?")[0] for r in records if r.get("url")}
    return sorted(urls)
With per_range=600, a single discovery job across the 9 protein powder price ranges returned 2,069 unique product URLs.
Error records had a descriptive error message alongside their error_code, such as the 410 Gone status Walmart returned for removed products. discover keeps only records with a url, so read error records from the raw snapshot when you check a run.
Collect and validate store-level records
Then collect each URL with a zip code, and validate every record before it reaches your data warehouse. Include input, error, and error_code in the field list, so each record keeps its input and any error details. Add specifications if you recompute unit prices from pack size:
FIELDS = "|".join([
    "product_id", "product_name", "final_price", "currency", "unit_price",
    "available_for_pickup", "available_for_delivery", "store_id",
    "store_name", "store_location", "seller", "timestamp",
    "input", "error", "error_code",  # keep input and error details
])


def collect(urls, zipcode, store_id=None, webhook=None):
    """Start one async job for a zip code. Returns the snapshot ID."""
    params = {"dataset_id": WALMART_PRODUCTS, "include_errors": "true",
              "format": "json", "custom_output_fields": FIELDS}
    if webhook:  # Bright Data POSTs the finished records to this URL
        params |= {"endpoint": webhook, "uncompressed_webhook": "true",
                   "auth_header": os.environ["WEBHOOK_AUTH_HEADER"]}
    row = {"zipcode": zipcode} | ({"store_id": store_id} if store_id else {})
    body = {"input": [{"url": u, **row} for u in urls]}
    job = post(f"{API}/trigger", params=params, json=body)
    return job.json()["snapshot_id"]


def validate(records, zipcode, store_id=None):
    """Keep records priced for the requested store. Route the rest by reason."""
    valid, rejected, seen = [], [], set()
    for rec in records:
        url = rec["input"]["url"]
        if rec.get("error_code"):
            rejected.append((url, rec["error_code"]))
            continue
        where = rec.get("store_location") or ""
        if store_id:  # store_location then shows the store's own zip
            matched = bool(where) and str(rec.get("store_id")) == str(store_id)
        else:  # store_location should show the requested zip
            matched = where.endswith(", " + zipcode)
        if not matched:
            rejected.append((url, f"priced for {where or 'no store'}"))
            continue
        try:
            price = float(rec["final_price"])
        except (KeyError, TypeError, ValueError):
            rejected.append((url, "no price, check availability"))
            continue
        key = (rec["product_id"], rec["store_id"])
        if key not in seen:
            seen.add(key)
            valid.append(rec | {"final_price": price})
    return valid, rejected


if __name__ == "__main__":
    category = ("https://www.walmart.com/browse/health/protein-powder/"
                "976760_1166769_7458180")
    edges = [0, 15, 25, 35, 42, 50, 62, 75, 100, 100000]
    urls = discover(category, edges, per_range=5)
    print(len(urls), "product URLs discovered")
    records = wait_and_download(collect(urls, zipcode="72712"))
    valid, rejected = validate(records, "72712")
    print(len(valid), "valid records,", len(rejected), "rejected")
A run with 5 products per range and Bentonville’s zip code, 72712, printed the counts below. While the discovery and collection jobs run, the script polls for their results. Your counts will differ, because they depend on Walmart’s listings on the day you run the pipeline:
42 product URLs discovered
41 valid records, 1 rejected
All 41 valid records were priced for store 100 in Bentonville. Walmart listed the remaining product without a price. The rejected list records why each record was rejected.
With a zip code alone, store_location showed the requested zip, so validate confirms each record against that zip. For a specific store, send its store_id with a zip code where that store is available, such as the store’s own zip. The record then showed the store’s own zip, so pass the same store_id to validate, which compares store IDs. The API checked the pairing, so store 3520 in Secaucus, sent with Bentonville’s 72712, produced an error record that named the mismatch.
At catalog scale, a single job with zip code 72712 ran all 2,069 discovered URLs, and validate checked every record’s reported location.
Run the pipeline at volume
At volume, 4 practices make the pipeline more predictable.
Batch URLs into jobs. Jobs run asynchronously, so let wait_and_download poll for the result. Use the async trigger for every job. When a job needs more time, the synchronous endpoint returns a snapshot ID to poll, so starting async keeps a single code path.
Count unique inputs. The API deduplicated repeated inputs, so a job of 34 inputs with 2 repeats returned 32 records. The same URL sent with 3 zip codes counted as 3 inputs, and each was priced for its own store.
Check error records before you retry. Error records named their cause, so remove dead product URLs from your list and resend the rest.
Deliver to your storage. Call collect(urls, zipcode, webhook=URL), and put the full header value, such as Bearer <secret>, in WEBHOOK_AUTH_HEADER. Bright Data POSTs the finished records to the webhook URL with that value as the Authorization header. The delivery guide covers the acknowledgment your endpoint sends, the source IPs to allowlist, and destinations such as Amazon S3, Google Cloud Storage, and Snowflake.
Keep store validation in your pipeline, so every record in your warehouse has a verified location.
Final thoughts
Scraping Walmart at scale is a store-location problem as much as an access problem. Each price belongs to the store it was priced for, and a success status doesn’t tell you which store that was. Set a zip code or store ID on every collection request, and split discovery into price ranges that each stay under the pagination limit.
When you need a backfill instead of daily store prices, start from a Walmart dataset. Otherwise, run a few price ranges and zip codes through the Walmart Scraper API on the free tier, then scale up once store validation passes.
FAQ
How do you scrape Walmart prices by zip code?
Send a zip code with each product URL instead of relying on the exit IP, which Walmart otherwise uses to pick a store. A zip code can resolve to a store in another state, so add a store ID when you need a specific store. Bright Data’s Walmart Scraper API takes both and reports the store for each record.
Does Walmart have a public API?
When I checked, Walmart’s APIs were for partners. The Affiliate Marketing API returned price and availability by zip code for apps that earn referral fees. Store lookups needed extra approval. The Marketplace APIs covered only sellers’ own catalogs, so store-level price trackers collect public product pages.
Can you scrape Walmart reviews?
Yes. On a milk product page, Walmart’s review pagination showed 10 reviews per page and stopped at 10,000 under the default sort. Page 1001 returned page 1 again, so stop at the page count Walmart reports. Bright Data’s Walmart reviews scraper collects written reviews and takes a sort_by input for review order.
Is there a Walmart product dataset?
Yes. Bright Data offers ready-made Walmart datasets for products, reviews, and sellers on a refresh schedule you choose. They suit backfills and catalog-wide analysis. For daily store-level prices, collect current records for a zip code or store ID with the Walmart Scraper API.


Technical Writer
 5 years experience
Satyam Tripathi helps SaaS and data startups turn complex tech into actionable content, boosting developer adoption and user understanding.