Scraping Yelp means collecting business listings, ratings, and reviews for sentiment analysis, market research, or sales leads. Yelp’s self-serve API plans included at most 7 review excerpts per business, while yelp.com shows the full text.
Yelp’s bot protection returned a challenge page to every Python HTTP request we sent. A local Chromium browser received a slider CAPTCHA. Even when a business page loaded, its HTML had no full review text.
This guide shows where Yelp stores its data and how to collect business details and full reviews in Python. It also explains when to use Bright Data’s Yelp Scraper API.
TL;DR
- DataDome, Yelp’s bot protection, stopped Python HTTP clients with a JavaScript challenge, even with TLS impersonation and US residential IPs. Bright Data’s Web Unlocker API loaded all 30 test business pages.
- Full reviews came from Yelp’s GraphQL API, up to 49 per call. A restaurant’s 582 recommended reviews took 12 calls.
- The persisted query ID can change when Yelp deploys, and a Browser API script captures the new one. An open-source scraper published an outdated ID.
- Bright Data’s Yelp Scraper API handles parser and query-ID maintenance for you, at a higher per-review price. It also collects reviews Yelp doesn’t recommend.
What blocks a Yelp scraper
In our tests, Yelp’s pages were protected by DataDome, a commercial bot-protection service. The blocked responses included its headers (server: DataDome and x-datadome: protected) and set a datadome cookie.
We sent requests for Yelp business pages from several client setups. The clients included curl_cffi, a Python HTTP client that impersonates a browser’s TLS handshake.
On home broadband, every setup requested the same page. Through US residential proxies, each client requested 12 different pages. None of the setups passed the challenge:
| Client | Network | What Yelp returned |
|---|---|---|
requests and httpx (HTTP/2) |
Home broadband outside the US | 403 CAPTCHA page, 5 of 5 each |
curl_cffi with a Chrome, Safari, or Firefox TLS profile |
Home broadband outside the US | 403 device-check page, 5 of 5 each |
curl_cffi with a Chrome TLS profile and a Python User-Agent |
Home broadband outside the US | 403 CAPTCHA page, 5 of 5 |
requests and curl_cffi |
US residential proxies, new IP per request | 403 device-check page, 12 of 12 each |
| Playwright with headless Chromium | Home broadband outside the US | 403 CAPTCHA page |
| Playwright with headed Chromium | Home broadband outside the US | Device check first, then a slider CAPTCHA within 8 seconds |
Every 403 body from these setups was DataDome’s challenge page. The page embedded a var dd={...} object, and the object’s rt field showed the challenge type. The value c loaded the CAPTCHA script, and i loaded a device-check page.
On the home connection, requests and httpx got c. With a browser TLS profile, curl_cffi got i, and with a Python User-Agent it got c again. Through US residential IPs, the requests library got i as well. Forcing HTTP/1.1 in curl_cffi returned the same device-check page.
The device check ran JavaScript, and an HTTP client can’t execute it. A headed browser ran the device check and then received this slider:
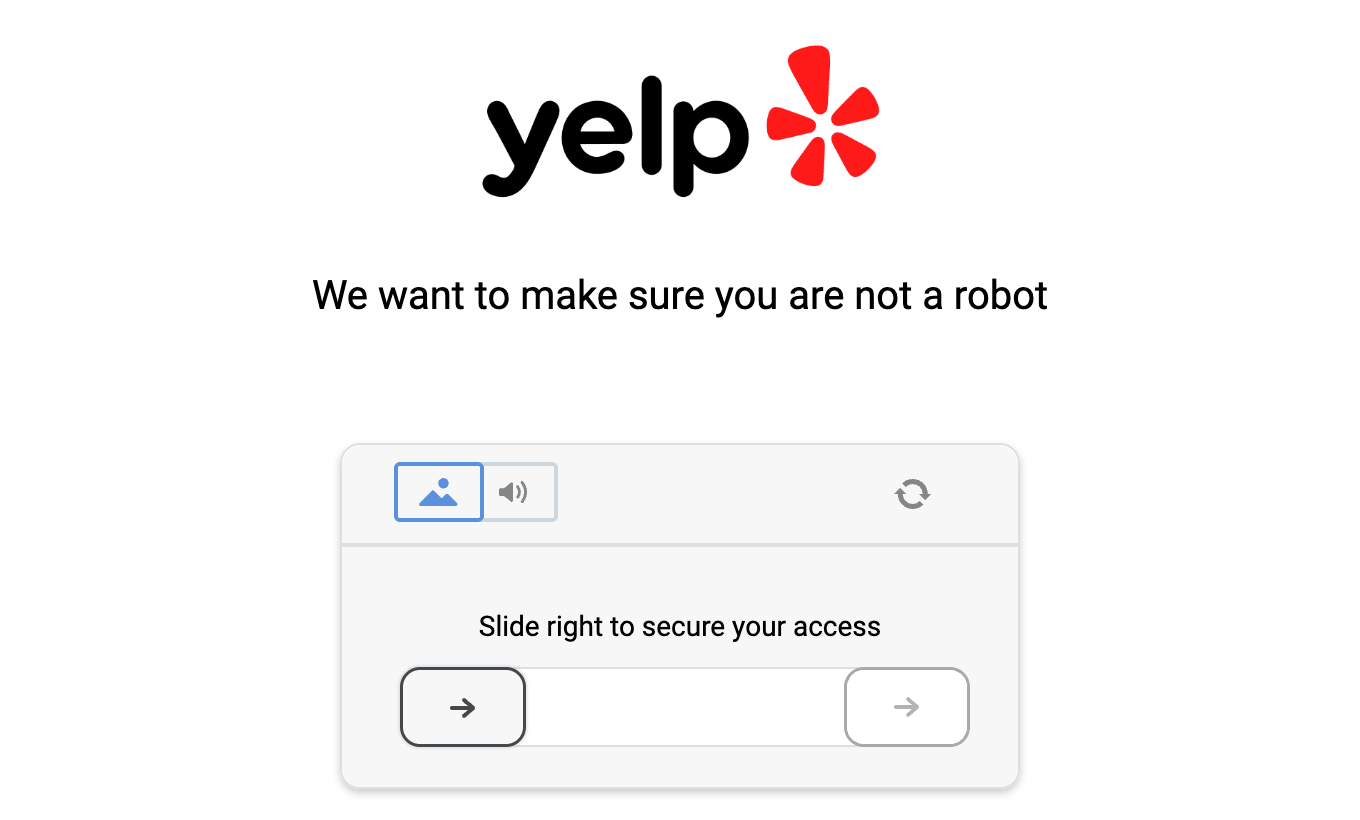
A headed Chromium session on a home connection showed this slider within 8 seconds of loading the page. If a person must drag the slider, a scraper can’t run automatically.
The HTTP clients stopped at a JavaScript challenge they can’t run, even through US residential IPs. The browsers could run JavaScript but used a single home IP, and Yelp returned CAPTCHA pages to that IP. Bright Data’s Web Unlocker API handles the browser environment, the IP, and DataDome challenges for you, including the CAPTCHAs on Yelp. Every Yelp request in the Python scraper uses it.
Where Yelp stores business and review data
Bright Data’s Browser API, a cloud browser you control with Playwright, shows how a Yelp business page loads its data. One logged page load sent 12 XHR and fetch requests to www.yelp.com, and 7 of the 12 were POST requests to /gql/batch. The data was in 3 places:
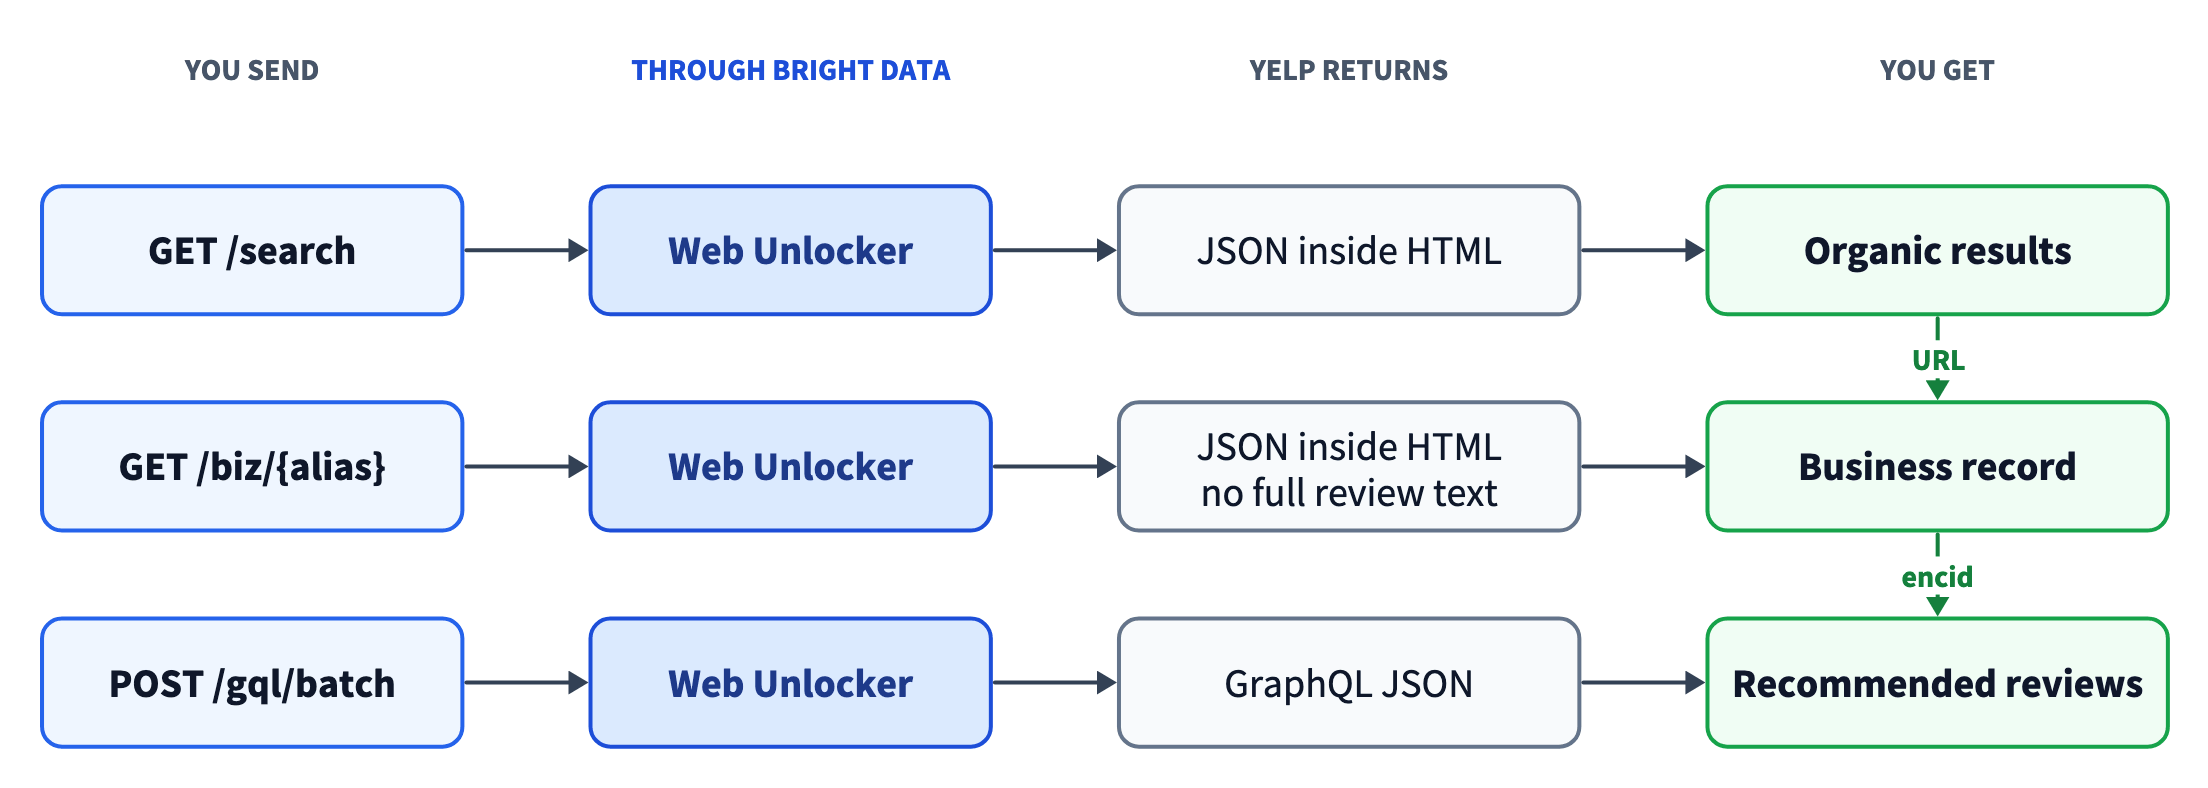
Search and business pages contained their data as JSON inside the HTML. Reviews needed a separate GraphQL call that used the business ID from the page.
Search pages
Yelp rendered search results on the server with Hypernova, which embedded 2 JSON objects in the HTML. A <script data-hypernova-key> tag contained the page props, including the list of result cards. A <script data-apollo-state> tag contained an Apollo Client cache. Both JSON objects were wrapped in an HTML comment, and the Apollo cache was also HTML-escaped (").
The 2 objects split each result between them. An organic card included only its bizId, rank, and URL, while the name, rating, and review count were in the Apollo cache under Business:<bizId>. Sponsored cards were the reverse, with their details inline and links through /adredir. A parser that read only the cards would get full details for sponsored results and no name, rating, or review count for organic ones.
On the rendered search page, the 2 kinds of card looked like this:
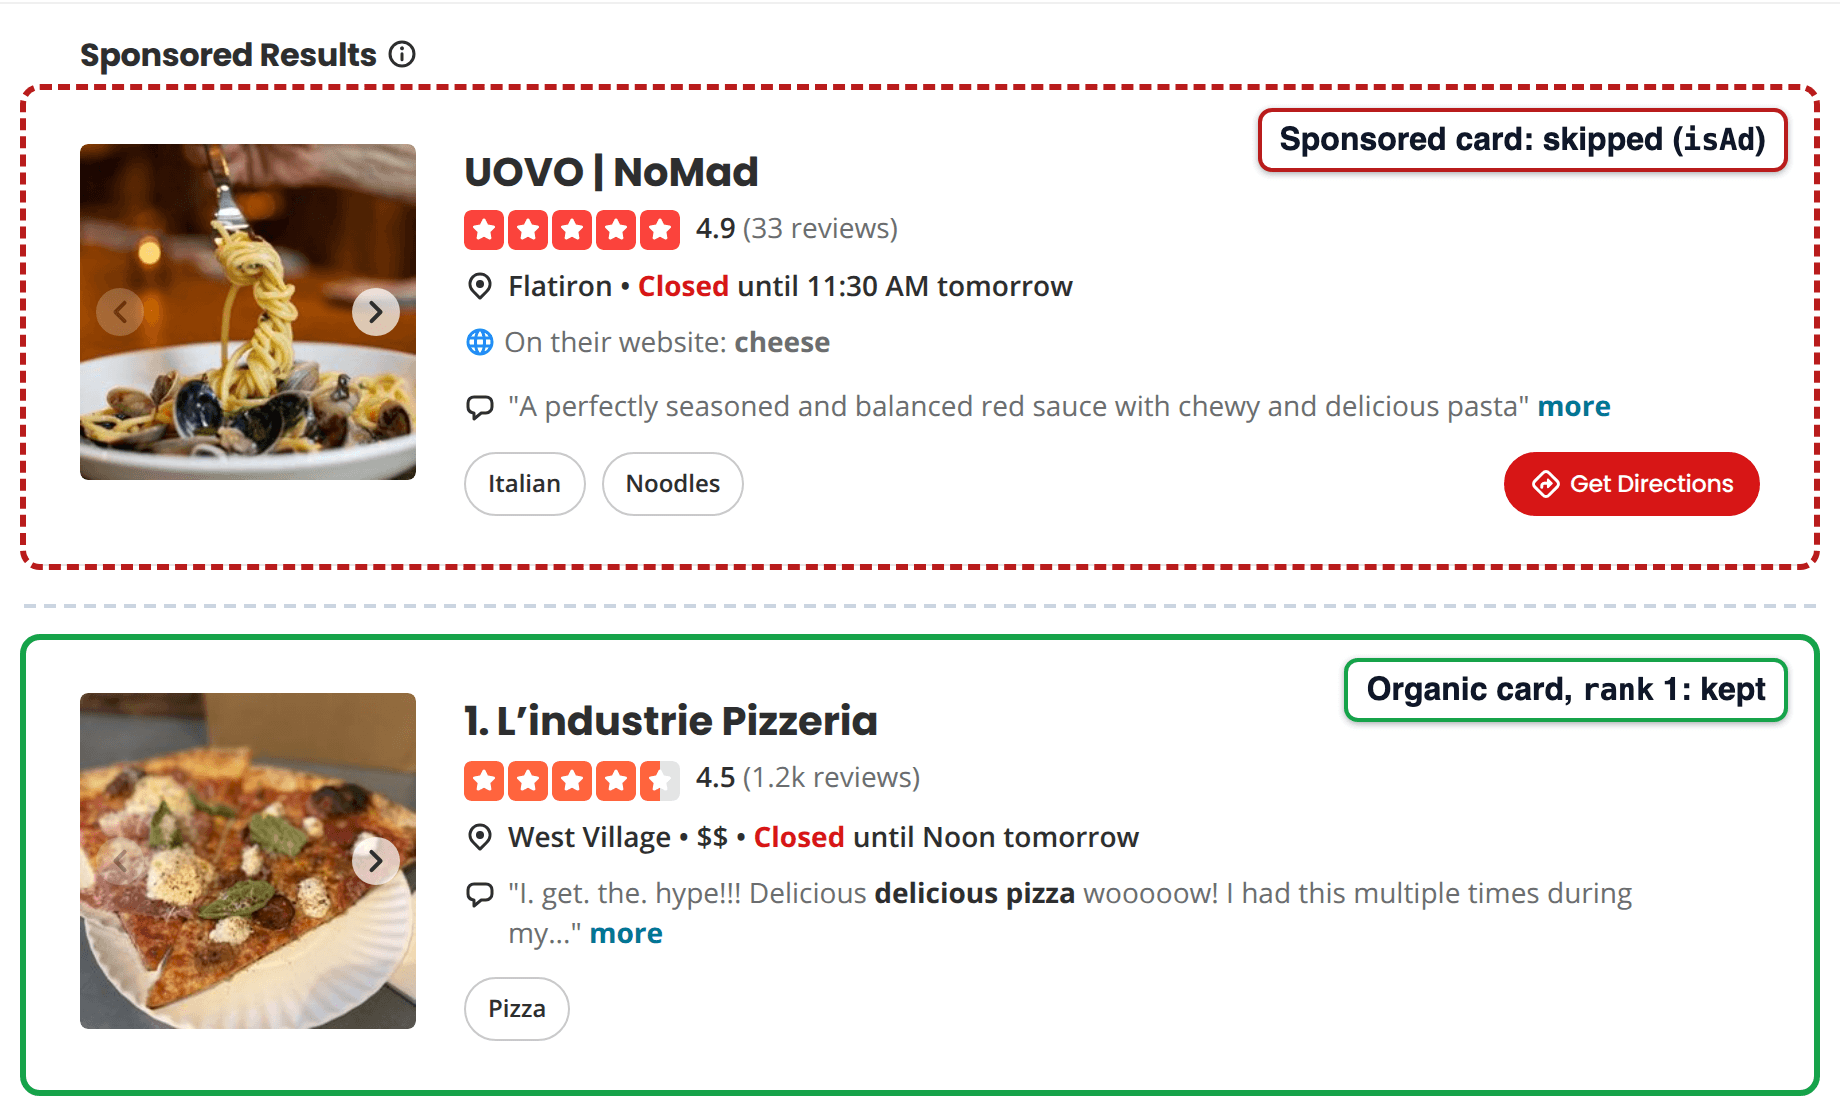
Yelp listed sponsored results before the numbered organic results. parse_search() keeps each organic card’s rank and skips any card marked isAd.
Yelp search also limited the number of results. The pagination block reported totalResults: 240 for all 4 queries we checked, including “Restaurants” in Dallas, and each page showed 10 results. To collect results for a whole city, split the query by neighborhood, category, or map area.
Business pages
A business page contained the same Apollo cache, and that cache had most business fields. It included the business ID (encid), rating, review count, address, phone, price range, categories, claim status, and website. The <meta name="yelp-biz-id"> tag also contained the encid. Search cards call the same ID bizId, and the GraphQL request calls it encBizId.
On L’industrie Pizzeria’s page, those fields appeared in the header and the sidebar:
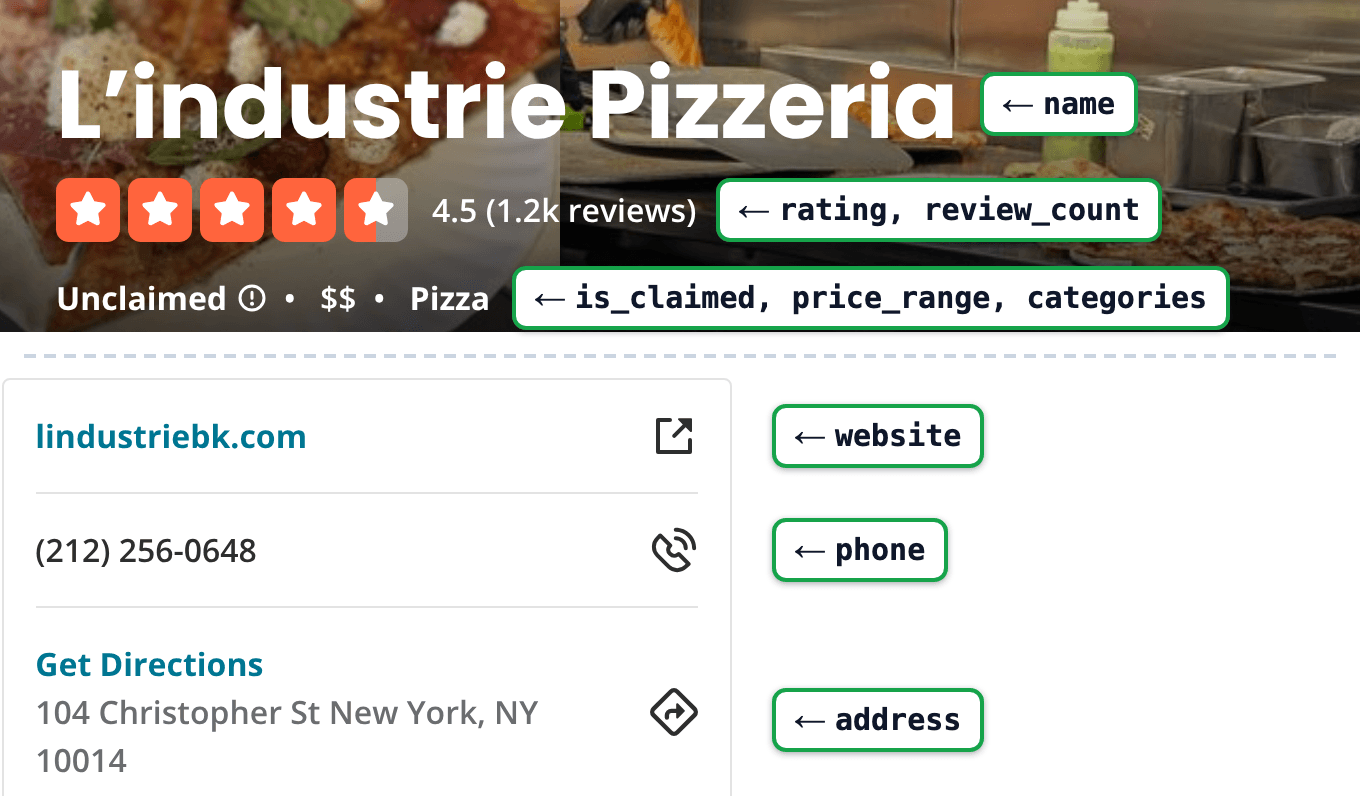
The labels are the keys that parse_business() returns, and every value came from the Apollo cache in the page’s HTML. The page rounded the review count to 1.2k, while the cache had the exact number.
Older guides read the rating from JSON-LD and read the reviews from the page itself. On all 19 business pages we saved, the JSON-LD blocks contained only photo lists and breadcrumbs, with no business rating. The Apollo cache contained no full review text on any of the 19 pages.
On 14 of those pages, the cache had review IDs and short highlight snippets, and the other 5 had no review references. The full review list loaded later, through a GraphQL request from the browser.
Reviews in the GraphQL API
Reviews came from Yelp’s GraphQL endpoint. The page sent a POST to /gql/batch with a JSON array of operations, and the GetBusinessReviewFeed operation returned the review list. Yelp used persisted queries, so the request contained a 64-character persisted query ID (documentId) instead of the query text. The server rejected IDs it didn’t recognize.
Opening page 2 of the reviews sent this request, shown here in Chrome DevTools:
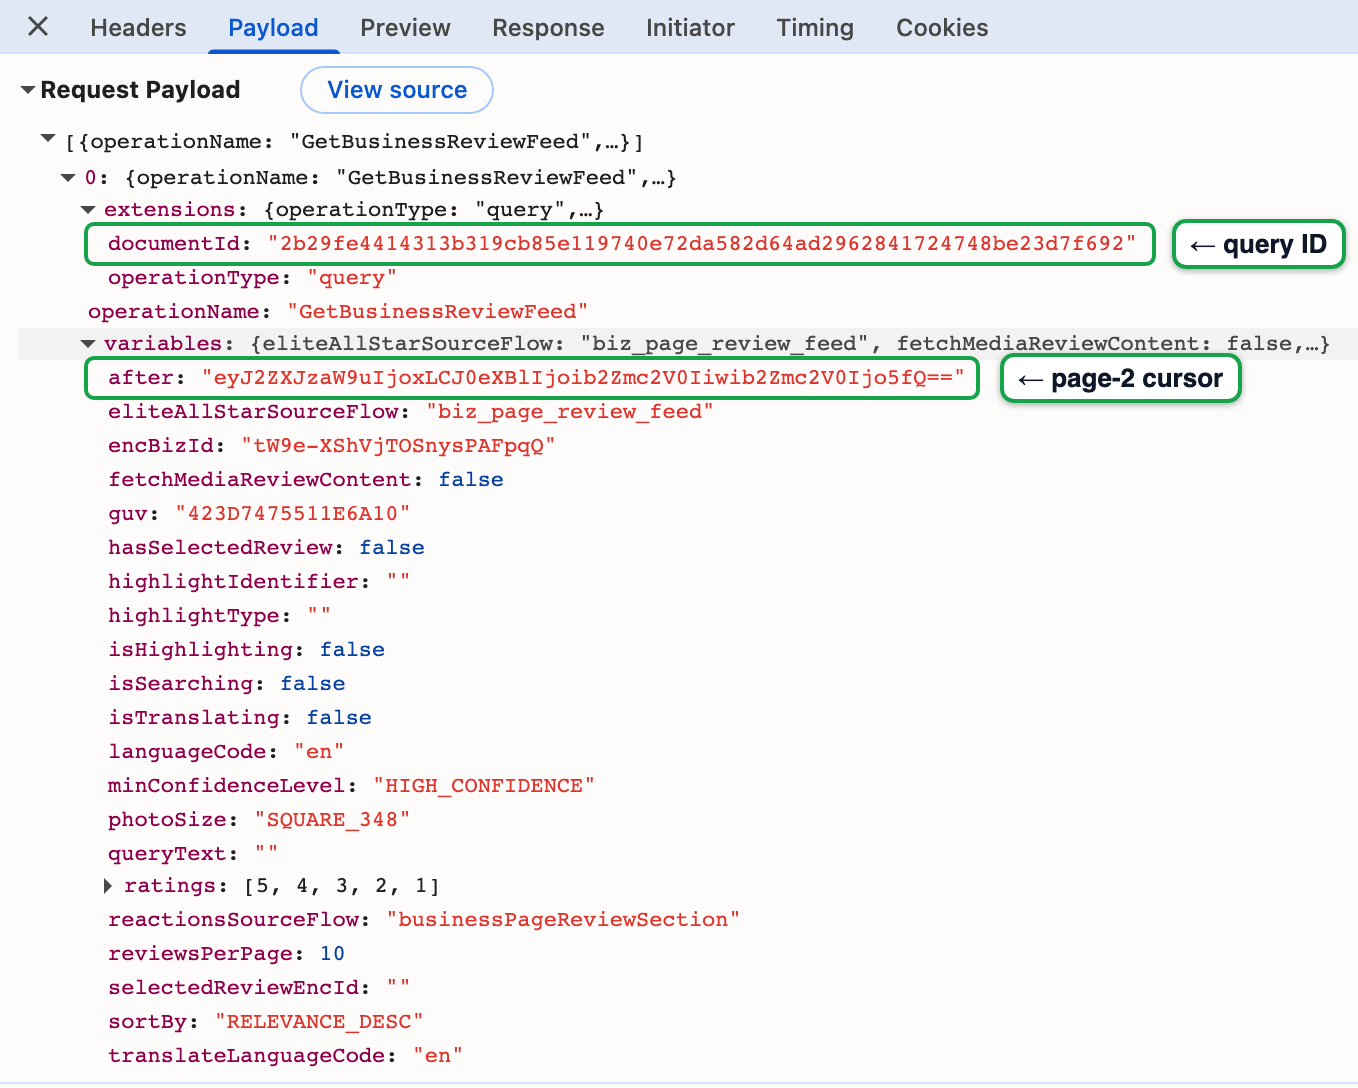
The page’s own request for review page 2. The scraper sends the same documentId and builds the after cursor itself.
The GraphQL API behaved like this in our tests:
- Page size:
reviewsPerPageaccepted 49. A value of 50 returned aBAD_USER_INPUTerror. - Pagination: the
aftercursor was base64-encoded JSON. The browser requested 10 reviews per page, and its page-2 cursor decoded to{"version":1,"type":"offset","offset":9}. That format lets you build each page’s cursor yourself and fetch the pages in parallel. - Sorting and filters:
sortByacceptedRELEVANCE_DESC,DATE_DESC,DATE_ASC,RATING_ASC, andELITES_DESC. Aratingsvalue of[1]reducedtotalCountto 35. That’s the count of 1-star reviews at Ziziki’s in Dallas, the restaurant we used for the GraphQL tests. - Errors: validation errors were returned in an HTTP 200 response and listed each missing variable. An unknown
documentIdgot an HTTP 403Forbiddenresponse in the browser. Through Web Unlocker, the same request returned502with error codehttp_status, which means Yelp returned an error status. Neither response contained DataDome’s challenge page, so an outdated ID doesn’t look like a block. - Scope:
GetBusinessReviewFeedreturned Yelp’s recommended reviews, the set the business page lists. According to Yelp, its software moves reviews it flags as unreliable, solicited, or unfairly biased to a separate not-recommended list. For Ziziki’s,totalCountwas 582, the business header showed 583, and the page’s collapsed section showed 39 not-recommended reviews.
Yelp’s page showed the same split. Under the review pagination, a collapsed section showed the number of reviews it didn’t recommend:
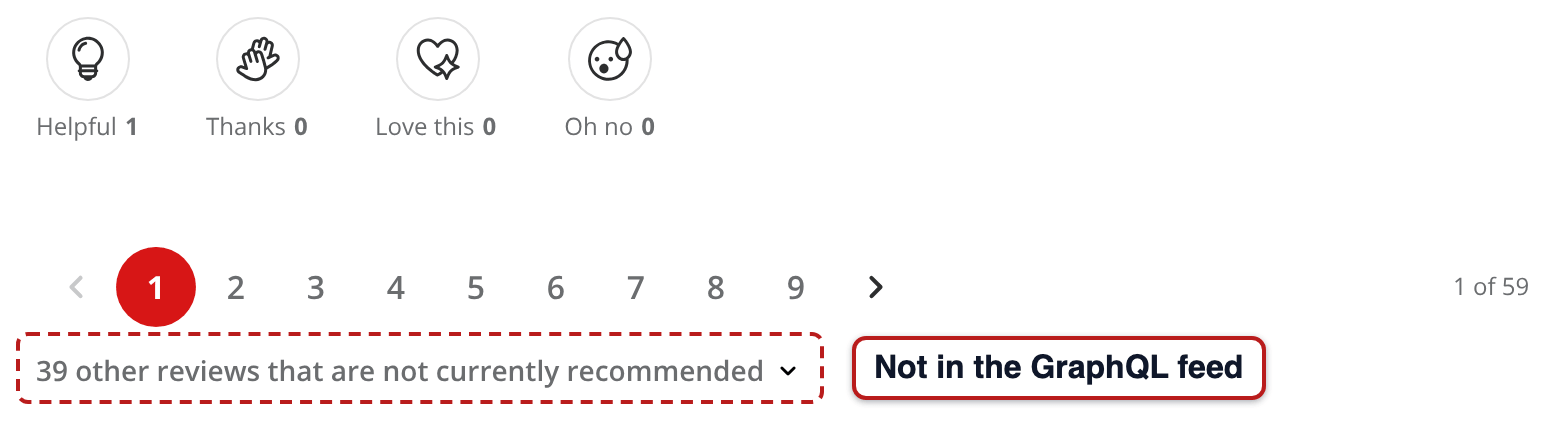
Ziziki’s page listed 59 pages of recommended reviews, 10 per page, and showed 39 more in the collapsed section.
The documentId can change when Yelp releases new frontend code. A popular open-source Yelp scraper published a documentId, but that ID no longer matched the one the live page sent. A short Browser API script, refresh_doc_id.py, captures the current ID from a live page, so you can update the scraper after Yelp releases new code.
Build a Yelp scraper in Python
The scraper requests search and business pages through Web Unlocker with GET. It sends the GraphQL request for reviews as a POST with a JSON body.
The code raises an error when a JSON object or a required key is missing. It also raises one when the persisted query ID is outdated or Yelp rejects a GraphQL variable. Other changes appear as empty fields or a row count below totalCount, so check both after each run.
If you’re new to scraping with Python, start with our Python web scraping guide, which covers the basics. You need Python 3.10 or later, the requests package, and a Bright Data account. Create a Web Unlocker zone, the named configuration that each request references, by following Bright Data’s Web Unlocker quickstart. Then generate an API key.
The free tier includes 5K credits a month, shared across Bright Data’s scraping APIs. Each Web Unlocker request or delivered Yelp Scraper API record uses 1 credit. Web Unlocker bills only for successful requests. Install the dependency and export your API key and zone name:
pip install requests
export BRIGHTDATA_API_KEY="your_api_key"
export BRIGHTDATA_UNLOCKER_ZONE="web_unlocker"
Web Unlocker and Browser API requests to Yelp need an account with full access. Accounts in immediate access mode, which doesn’t require Know Your Customer (KYC) verification, follow robots.txt. Yelp’s robots.txt disallowed crawlers it didn’t name when we read it.
You get full access after KYC verification or through your account manager. Until then, Web Unlocker returns a ub_bad_endpoint_robots error for Yelp URLs, and the Browser API returns a brob error.
Fetch pages through Web Unlocker
The helper posts each URL to Web Unlocker’s /request endpoint and returns the target’s response body, with up to 3 attempts per URL. Save it as the first part of yelp_scraper.py:
import base64
import html
import json
import os
import re
import time
import urllib.parse
from concurrent.futures import ThreadPoolExecutor

import requests

API_KEY = os.environ["BRIGHTDATA_API_KEY"]
ZONE = os.environ.get("BRIGHTDATA_UNLOCKER_ZONE", "web_unlocker")

# Persisted query ID of Yelp's GetBusinessReviewFeed operation.
# It can change when Yelp deploys. refresh_doc_id.py captures it.
REVIEW_FEED_DOC_ID = os.environ.get(
    "YELP_REVIEW_FEED_DOC_ID",
    "2b29fe4414313b319cb85e119740e72da582d64ad2962841724748be23d7f692",
)
PAGE_SIZE = 49  # Yelp's GraphQL API rejected 50 with BAD_USER_INPUT


class FetchError(Exception):
    pass


def unlock(url, method="GET", body=None, attempts=3):
    """Fetch a URL through Web Unlocker; return the target's response body."""
    payload = {"zone": ZONE, "url": url, "format": "raw",
               "country": "us", "method": method}
    if body is not None:
        payload["body"] = json.dumps(body)
        payload["headers"] = {"content-type": "application/json"}
    last_error = None
    for attempt in range(attempts):
        try:
            r = requests.post(
                "https://api.brightdata.com/request",
                headers={"Authorization": f"Bearer {API_KEY}"},
                json=payload,
                timeout=180,
            )
            # r.status_code reports on the API call itself.
            # The target's own status is in x-brd-status-code.
            status = r.headers.get("x-brd-status-code", str(r.status_code))
            if status == "200" and r.text:
                return r.text
            last_error = f"{status} {r.headers.get('x-brd-error-code')}"
        except requests.RequestException as exc:
            last_error = type(exc).__name__
        if attempt < attempts - 1:
            time.sleep(2 ** attempt)
    raise FetchError(f"{url}: {last_error}")
In a separate test of 30 Yelp business pages, unlock() loaded every page.
Parse business details from the Apollo cache
Add this parser to yelp_scraper.py. It extracts the Apollo cache, finds the business the page is about, and flattens its fields into a single record:
def embedded_json(page, marker, escaped):
"""Return the JSON that Yelp wraps in <!-- --> inside a <script> tag."""
m = re.search(
r"<script[^>]*" + marker + r"[^>]*>\s*<!--(.*?)-->\s*</script>",
page,
re.S,
)
if not m:
raise FetchError(f"{marker} missing: soft block or markup change")
raw = html.unescape(m.group(1)) if escaped else m.group(1)
return json.loads(raw)
def apollo_state(page):
# The Apollo cache was HTML-escaped (") inside an HTML comment.
return embedded_json(page, "data-apollo-state", escaped=True)
def parse_business(page):
state = apollo_state(page)
ref = next(v["__ref"] for k, v in state["ROOT_QUERY"].items()
if k.startswith("business("))
biz = state[ref]
loc = state[biz["location"]["__ref"]]
claim = next((v for k, v in biz.items()
if k.startswith("claimability(")), None) or {}
website = (biz.get("externalResources") or {}).get("website") or {}
return {
"encid": biz["encid"],
"alias": biz["alias"],
"name": biz["name"],
"rating": biz["rating"],
"review_count": biz["reviewCount"],
"price_range": (biz.get("priceRange") or {}).get("display"),
"phone": (biz.get("phoneNumber") or {}).get("formatted"),
"address": loc["address"]["formatted"].replace("\n", ", "),
"neighborhoods": loc.get("neighborhoods"),
"categories": [state[c["__ref"]]["title"] for c in biz["categories"]],
"is_claimed": claim.get("isClaimed"),
"is_closed": biz.get("isClosed"),
"website": website.get("url"),
}
def get_business(url):
return parse_business(unlock(url))Apollo stores related objects once and points to them with __ref keys, so the parser follows location and categories to their own entries. Some keys included their query arguments, such as claimability({"useConsumerClaimability":true}), so the code matches those keys by prefix. The parser read all 19 saved business pages without an error.
Scrape Yelp reviews from the GraphQL API
To scrape Yelp reviews, send a request with the business encid, the persisted documentId, and the variables that the query expects. The next part of yelp_scraper.py builds the offset cursor itself, so every page after the first runs in parallel. Yelp’s cursor contained the offset of the previous page’s last review, so review_page() passes start - 1:
def review_cursor(offset):
    # Yelp's "after" cursor is base64 JSON with a numeric offset inside.
    raw = json.dumps({"version": 1, "type": "offset", "offset": offset},
                     separators=(",", ":"))
    return base64.b64encode(raw.encode()).decode()


def review_page(encid, start, sort_by="DATE_DESC"):
    variables = {
        "encBizId": encid,
        "reviewsPerPage": PAGE_SIZE,
        "after": review_cursor(start - 1) if start else None,
        "sortBy": sort_by,  # RELEVANCE_DESC, DATE_DESC, DATE_ASC, ...
        "ratings": [5, 4, 3, 2, 1],
        "queryText": "",
        "isSearching": False,
        "selectedReviewEncId": "",
        "hasSelectedReview": False,
        "isTranslating": False,
        "translateLanguageCode": "en",
        "isHighlighting": False,
        "highlightType": "",
        "highlightIdentifier": "",
        "photoSize": "SQUARE_348",
        "fetchMediaReviewContent": False,
        "eliteAllStarSourceFlow": "biz_page_review_feed",
        "reactionsSourceFlow": "businessPageReviewSection",
        "minConfidenceLevel": "HIGH_CONFIDENCE",
    }
    body = [{
        "operationName": "GetBusinessReviewFeed",
        "variables": variables,
        "extensions": {"operationType": "query",
                       "documentId": REVIEW_FEED_DOC_ID},
    }]
    try:
        raw = unlock("https://www.yelp.com/gql/batch", method="POST",
                     body=body)
    except FetchError as exc:
        # Through Web Unlocker, an unknown documentId was returned as
        # 502 http_status, so the message suggests refreshing the ID.
        raise FetchError(f"{exc} (outdated documentId? run refresh_doc_id.py)")
    result = json.loads(raw)[0]
    # GraphQL errors can be returned in an HTTP 200 response.
    if result.get("errors"):
        raise FetchError(result["errors"][0]["message"])
    return result["data"]["business"]["reviews"]


def flatten_review(node):
    author = node.get("author") or {}
    # Author fields are personal data, so drop them if you only need sentiment.
    return {
        "review_id": node["encid"],
        "rating": node["rating"],
        "created_at": node["createdAt"]["localDateTimeForBusiness"],
        "text": (node.get("text") or {}).get("full"),
        "language": (node.get("text") or {}).get("language"),
        "author": author.get("displayName"),
        "author_location": author.get("displayLocation"),
        "author_review_count": author.get("reviewCount"),
    }


def get_reviews(encid, max_reviews=None, workers=4):
    first = review_page(encid, 0)
    total = first["totalCount"]
    if max_reviews:
        total = min(total, max_reviews)
    reviews = [e["node"] for e in first["edges"]]
    # Offsets are known in advance, so the remaining pages run in parallel.
    starts = range(PAGE_SIZE, total, PAGE_SIZE)
    with ThreadPoolExecutor(workers) as pool:
        for page in pool.map(lambda s: review_page(encid, s), starts):
            reviews += [e["node"] for e in page["edges"]]
    unique = {r["encid"]: flatten_review(r) for r in reviews}
    return list(unique.values())[:total], first["totalCount"]
get_reviews() collected all 582 recommended reviews of Ziziki’s in 12 GraphQL calls, and the review dates covered about 20 years.
The browser also sent a guv visitor ID and a languageCode value. The GraphQL API didn’t require either in our tests, so the code doesn’t send them.
The created_at value is in the business’s local time zone, with an offset such as -05:00 or -06:00 for Dallas, depending on daylight saving time. Before you compare review dates across cities, keep the offset when you store each value, or convert it to UTC.
Discover businesses from search results
The functions so far start from a business URL you already have. Search pages give you the business URLs for get_business() and the encid values for get_reviews(). Add the search functions to yelp_scraper.py too. The parser joins each organic card to its Apollo record and skips sponsored cards:
def parse_search(page):
    props = embedded_json(page, "data-hypernova-key", escaped=False)
    comps = (props["legacyProps"]["searchAppProps"]["searchPageProps"]
             ["mainContentComponentsListProps"])
    state = apollo_state(page)
    hits = []
    for comp in comps:
        section = comp.get("props") or {}
        if comp.get("type") != "searchResultSection":
            continue
        for item in section.get("searchResults", []):
            if item.get("isAd"):
                continue  # skip sponsored cards
            # Take details from the Apollo cache; organic cards may lack them.
            biz = state.get(f"Business:{item['bizId']}", {})
            hits.append({
                "rank": item.get("ranking"),
                "encid": item["bizId"],
                "name": biz.get("name"),
                "rating": biz.get("rating"),
                "review_count": biz.get("reviewCount"),
                "url": "https://www.yelp.com"
                       + item["businessUrl"].split("?")[0],
            })
    paging = next(c["props"] for c in comps if c.get("type") == "pagination")
    return hits, paging["totalResults"]


def search(term, location, pages=1):
    query = urllib.parse.urlencode({"find_desc": term, "find_loc": location})
    base = f"https://www.yelp.com/search?{query}"
    hits = []
    for n in range(pages):
        # Page 1 has no start parameter, the way a browser loads it.
        url = f"{base}&start={n * 10}" if n else base
        batch, total = parse_search(unlock(url))
        hits += batch
        if (n + 1) * 10 >= total:
            break
    return hits
search() sends page 1 without start, the way a browser first loads a search. It stops at the last page that totalResults allows, so a query that reaches Yelp’s 240-result limit needs 24 pages.
Run the Yelp scraper
The last block of yelp_scraper.py runs the steps in order. It fetches 2 search pages, 1 business page, and that business’s 150 newest reviews, and it writes the reviews to a JSON Lines file:
if __name__ == "__main__":
    hits = search("Pizza", "Lower Manhattan, New York, NY", pages=2)
    print(f"{len(hits)} organic results")
    for hit in hits[:3]:
        print(hit["rank"], hit["name"], hit["rating"], hit["review_count"])

    business = get_business(hits[0]["url"])
    print(json.dumps(business, indent=2, ensure_ascii=False))

    reviews, reported = get_reviews(business["encid"], max_reviews=150)
    print(f"collected {len(reviews)} of {reported} reviews")
    for r in reviews[:2]:
        print(r["created_at"], r["rating"], r["text"][:60])

    with open("reviews.jsonl", "w") as f:
        for row in reviews:
            f.write(json.dumps({"business": business["alias"], **row}) + "\n")
Run the script from the directory where you saved it. The first line prints only after both search pages load:
python yelp_scraper.pyThe run printed the top search results, the business record, and the first 2 reviews:
20 organic results
1 L’industrie Pizzeria 4.5 1222
2 Prince Street Pizza 4.3 5720
3 Juliana's 4.4 2997
{
  "encid": "G9hV4H2iGpWD8RoUpjtokg",
  "alias": "l-industrie-pizzeria-new-york",
  "name": "L’industrie Pizzeria",
  "rating": 4.5,
  "review_count": 1222,
  "price_range": "$$",
  "phone": "(212) 256-0648",
  "address": "104 Christopher St, New York, NY 10014",
  "neighborhoods": [
    "West Village"
  ],
  "categories": [
    "Pizza"
  ],
  "is_claimed": false,
  "is_closed": false,
  "website": "http://lindustriebk.com"
}
collected 150 of 1220 reviews
2026-09-25T20:43:26-04:00 4 I arrived here on a Saturday afternoon and man what a line.
2026-09-25T20:37:09-04:00 4 The pizza was like 4.25/5, I came with locals and they said
The run used 7 billable requests (2 for search pages, 1 for the business page, and 4 for GraphQL calls). The business page reported 1,222 reviews, while the GraphQL API’s totalCount was 1,220. Compare your row count with totalCount, not with the number on the page, when you check that a run is complete.
Refresh the persisted query ID when Yelp deploys
When the review calls start failing with 502 http_status while business pages still load, the documentId has most likely changed. Save this script as refresh_doc_id.py. It opens a single business page in the Browser API and scrolls until the page sends the GraphQL request for reviews. It prints the ID from that request, or None after 30 scrolls without one:
import asyncio
import json
import os

from playwright.async_api import async_playwright

# Browser API endpoint from the zone's Overview tab, with -country-us added.
BROWSER_WSS = os.environ["BRIGHTDATA_BROWSER_WSS"]
BIZ_URL = "https://www.yelp.com/biz/zizikis-dallas-2"


async def capture_review_feed_doc_id():
    async with async_playwright() as p:
        browser = await p.chromium.connect_over_cdp(BROWSER_WSS)
        page = await browser.new_page()
        found = asyncio.get_running_loop().create_future()

        def on_request(request):
            if (request.url.endswith("/gql/batch")
                    and "GetBusinessReviewFeed" in (request.post_data or "")
                    and not found.done()):
                ops = json.loads(request.post_data)
                op = next(o for o in ops
                          if o["operationName"] == "GetBusinessReviewFeed")
                found.set_result(op["extensions"]["documentId"])

        page.on("request", on_request)
        await page.goto(BIZ_URL, wait_until="domcontentloaded",
                        timeout=120_000)
        # Scroll until the page sends the GraphQL request for reviews.
        for _ in range(30):
            if found.done():
                break
            await page.mouse.wheel(0, 1200)
            await page.wait_for_timeout(1500)
        await browser.close()
        return found.result() if found.done() else None


if __name__ == "__main__":
    print(asyncio.run(capture_review_feed_doc_id()))
Install Playwright with pip install playwright, and create a Browser API zone by following Bright Data’s Browser API quickstart. Then set BRIGHTDATA_BROWSER_WSS to the zone’s endpoint, and add -country-us to the username. The value has the form wss://brd-customer-<id>-zone-<zone>-country-us:<password>@brd.superproxy.io:9222. The run printed the ID the scraper already uses:
2b29fe4414313b319cb85e119740e72da582d64ad2962841724748be23d7f692When the printed ID differs, export it as YELP_REVIEW_FEED_DOC_ID and run yelp_scraper.py again.
The Browser API bills per GB of traffic, and 6 Yelp business-page loads averaged about 8 MB each. Web Unlocker bills per successful request. Use the Browser API only for the occasional documentId refresh, and send page and review requests through Web Unlocker.
Troubleshoot common errors
Match what you see to a likely cause:
| What you see | Likely cause | What to do |
|---|---|---|
FetchError with 401 None or 400 None |
A wrong API key (401) or zone name (400) | Check BRIGHTDATA_API_KEY, and set BRIGHTDATA_UNLOCKER_ZONE to the zone’s exact name |
FetchError with ub_bad_endpoint_robots, or brob from the Browser API |
The account is in immediate (no-KYC) access mode, which follows Yelp’s robots.txt | Complete KYC verification, or ask your account manager for full access |
FetchError with data-apollo-state missing or data-hypernova-key missing |
A soft block (a block page returned with HTTP 200) or a markup change | Save the HTML that unlock() returned and search it for the <script> tag named in the error |
Review calls fail with 502 http_status while business pages load |
A new documentId |
Run refresh_doc_id.py and export the ID it prints |
FetchError with a GraphQL validation message |
A missing or out-of-range variable | Compare your variables with the page’s payload in DevTools |
Any other FetchError from unlock() |
The request failed on all 3 attempts | Retry the URL later, or increase attempts in unlock() |
Empty fields, or a KeyError or StopIteration in a parser |
A renamed key in Yelp’s JSON | Compare the page’s JSON with the keys the parser reads |
Scale Yelp scraping with Bright Data’s Yelp Scraper API
When you write your own scraper, you also maintain it. The persisted query ID, the variable list, and the parsers all depend on Yelp’s frontend, so each can break when Yelp releases frontend changes.
The Yelp Scraper API, part of Bright Data’s Web Scraper API, takes Yelp URLs or search filters and returns parsed records. Bright Data maintains the parsers as Yelp’s frontend changes. Bright Data also offers a dedicated Yelp image scraper and a Yelp MCP server for AI agents.
The Yelp Scraper API can also collect not-recommended reviews, which the GetBusinessReviewFeed query didn’t return in our tests. Yelp’s software didn’t recommend 17% of the reviews posted in 2025, according to its 2025 Trust and Safety Report.
Run the Yelp Scraper API from Python
In the control panel, the scrapers library lists the Yelp endpoints. The business endpoints accept URLs, search filters, or a bounding box as input, and the review endpoints accept business URLs or search filters. Each endpoint accepts a list of inputs and runs in synchronous or asynchronous mode:
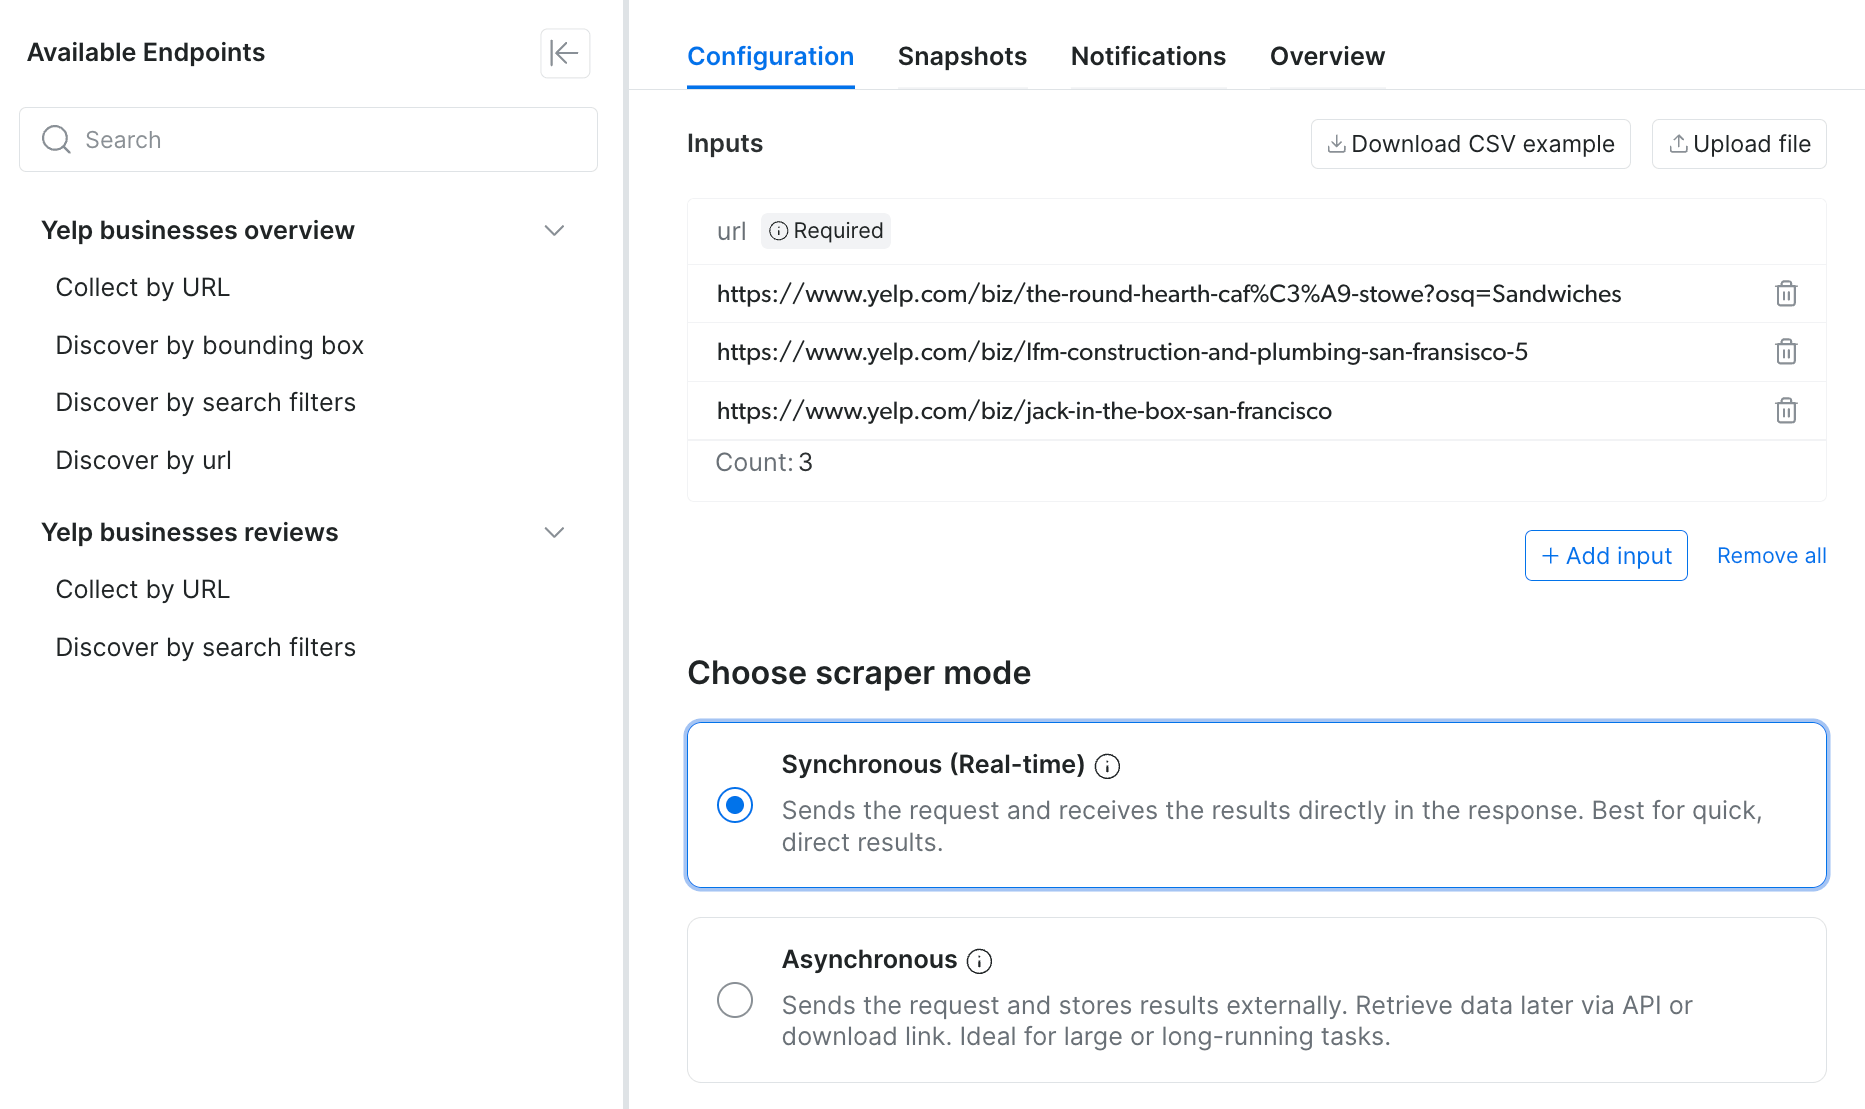
The Collect by URL endpoint for business records, with 3 example inputs and Synchronous mode selected. A synchronous call that takes longer than its 1-minute limit returns a snapshot ID instead of records, so scraper_api.py runs asynchronously.
You can run the same scrapers from Python through the asynchronous trigger endpoint. Save this script as scraper_api.py. It needs only BRIGHTDATA_API_KEY, because Scraper API calls don’t use a zone. It runs a discovery search for pizza in Brooklyn, NY, and then collects the 20 newest reviews of the first result:
import os
import time

import requests

API = "https://api.brightdata.com/datasets/v3"
HEADERS = {"Authorization": f"Bearer {os.environ['BRIGHTDATA_API_KEY']}"}

YELP_BUSINESSES = "gd_lgugwl0519h1p14rwk"
YELP_REVIEWS = "gd_lgzhlu9323u3k24jkv"


def collect(dataset_id, inputs, limit_per_input=None, poll_every=15,
            **params):
    """Trigger a Scraper API job, wait for it, and return its records."""
    body = {"input": inputs}
    if limit_per_input:
        body["limit_per_input"] = limit_per_input
    r = requests.post(
        f"{API}/trigger",
        headers=HEADERS,
        params={"dataset_id": dataset_id, "include_errors": "true",
                **params},
        json=body,
        timeout=60,
    )
    r.raise_for_status()
    snapshot_id = r.json()["snapshot_id"]

    while True:
        progress = requests.get(f"{API}/progress/{snapshot_id}",
                                headers=HEADERS, timeout=60).json()
        if progress["status"] == "ready":
            break
        if progress["status"] in ("failed", "canceled"):
            raise RuntimeError(f"{snapshot_id}: {progress}")
        time.sleep(poll_every)

    records = requests.get(f"{API}/snapshot/{snapshot_id}",
                           headers=HEADERS, params={"format": "json"},
                           timeout=120).json()
    # With include_errors=true, failed inputs are returned as error records.
    errors = [x for x in records if x.get("error")]
    rows = [x for x in records if not x.get("error")]
    return rows, errors


if __name__ == "__main__":
    rows, errors = collect(
        YELP_BUSINESSES,
        [{"country": "US", "category": "Pizza",
          "location": "Brooklyn, NY, United States"}],
        limit_per_input=5,
        type="discover_new",
        discover_by="search_filters",
    )
    for row in rows:
        print(row["name"], row["overall_rating"], row["reviews_count"],
              row["url"])
    print(f"{len(rows)} businesses, {len(errors)} errors")
    if not rows:
        raise SystemExit("discovery returned no businesses")

    reviews, errors = collect(
        YELP_REVIEWS,
        [{"url": rows[0]["url"], "unrecommended_reviews": False,
          "sort_by": "DATE_DESC"}],
        limit_per_input=20,
    )
    print(f"{len(reviews)} reviews, {len(errors)} errors")
    for r in reviews[:1]:
        print(r["date_iso_format"], r["Rating"], r["Content"][:120])
YELP_BUSINESSES and YELP_REVIEWS are the dataset IDs of Bright Data’s Yelp scrapers, shown in each scraper’s API examples in the control panel. collect() checks each job’s progress every 15 seconds and returns its records once the job is ready. For each discovered business, the script prints the name, rating, review count, and URL. It then prints the number of reviews and the first review’s date, rating, and first 120 characters of text.
The Yelp Scraper API bills only for successful deliveries. limit_per_input sets the maximum number of records per input. This script uses 5 for businesses and 20 for reviews, so a test run on a business with 5K reviews isn’t billed for 5K records. Inputs a job couldn’t collect are returned as error records that include their input, ready to resubmit.
Configure review jobs and map their fields
These 3 details affect which records a job returns and how you read them:
unrecommended_reviewsselected 1 of the 2 review sets. Withtrue, a job returned only not-recommended reviews (recommended_review: false). To collect both sets, send the business URL once with each value. Leave the date range empty on thetrueinput to collect not-recommended reviews from all dates.- Date filters on recommended reviews matched the GraphQL count. With
unrecommended_reviewsset tofalseand a date range fromstart_datetoend_date, the job returned 6 reviews. The GraphQL scraper found the same 6 for that range. - Yelp’s reaction labels changed over time. Recent records used
Helpful,Thanks,Love this, andOh no, while older Yelp reviews useduseful,funny, andcool. Map both sets before you compare reactions across years.
For recurring jobs, the Yelp Scraper API delivers to a webhook, Amazon S3, Google Cloud Storage, Google Pub/Sub, Microsoft Azure Storage, Snowflake, or SFTP.
Yelp API, scraper, or dataset: what 1K businesses cost
The right option depends on whether you need full review text and who maintains the data collection. This table shows the cost of a single workload, 1K businesses with 200 reviews each, at the list prices when we checked:
| Option | Full review text | Cost for 1K businesses and 200K reviews | Your ongoing work |
|---|---|---|---|
| Yelp Places API, Enhanced plan | No, 3 excerpts of about 160 characters | $299 per month, within the 30K included calls | Follow the display rules and the 24-hour caching limit |
| Yelp Insights API, Premium plan | Yes | Custom quote from Yelp’s sales team, from $0.08 per location on a rolling 12-month basis | Follow Yelp’s contract terms |
| Your own scraper on Web Unlocker | Yes, recommended reviews | $9 for 6K requests (1K business pages and 5K GraphQL calls) at $1.5 per 1K | Update the persisted query ID, variables, and parsers when Yelp’s frontend changes |
| Bright Data Yelp Scraper API | Yes, recommended and not recommended | $301.50 for 201K records at $1.5 per 1K | Manage input lists and delivery |
| Bright Data Yelp datasets | Yes, pre-collected | Up to $502.50 for 201K records at up to $0.0025 per record ($250 minimum order) | No collection work, monthly data refresh |
The Web Unlocker figure is low because each GraphQL call returned up to 49 reviews, and Web Unlocker bills only successful requests. The Yelp Scraper API bills per record, so jobs with many reviews cost more. For that price, you don’t spend engineering time on parsers or persisted query IDs.
Discovery adds cost with both options. On Web Unlocker, you pay for search pages, which showed 10 results each. On the Yelp Scraper API, you pay for discovery records.
Bright Data’s Yelp datasets work well for historical backfills. They include more than 200M review records and more than 9M business records. A separate Yelp restaurants dataset is also available.
Each dataset page in the control panel shows the fields, price, and a data sample before purchase:
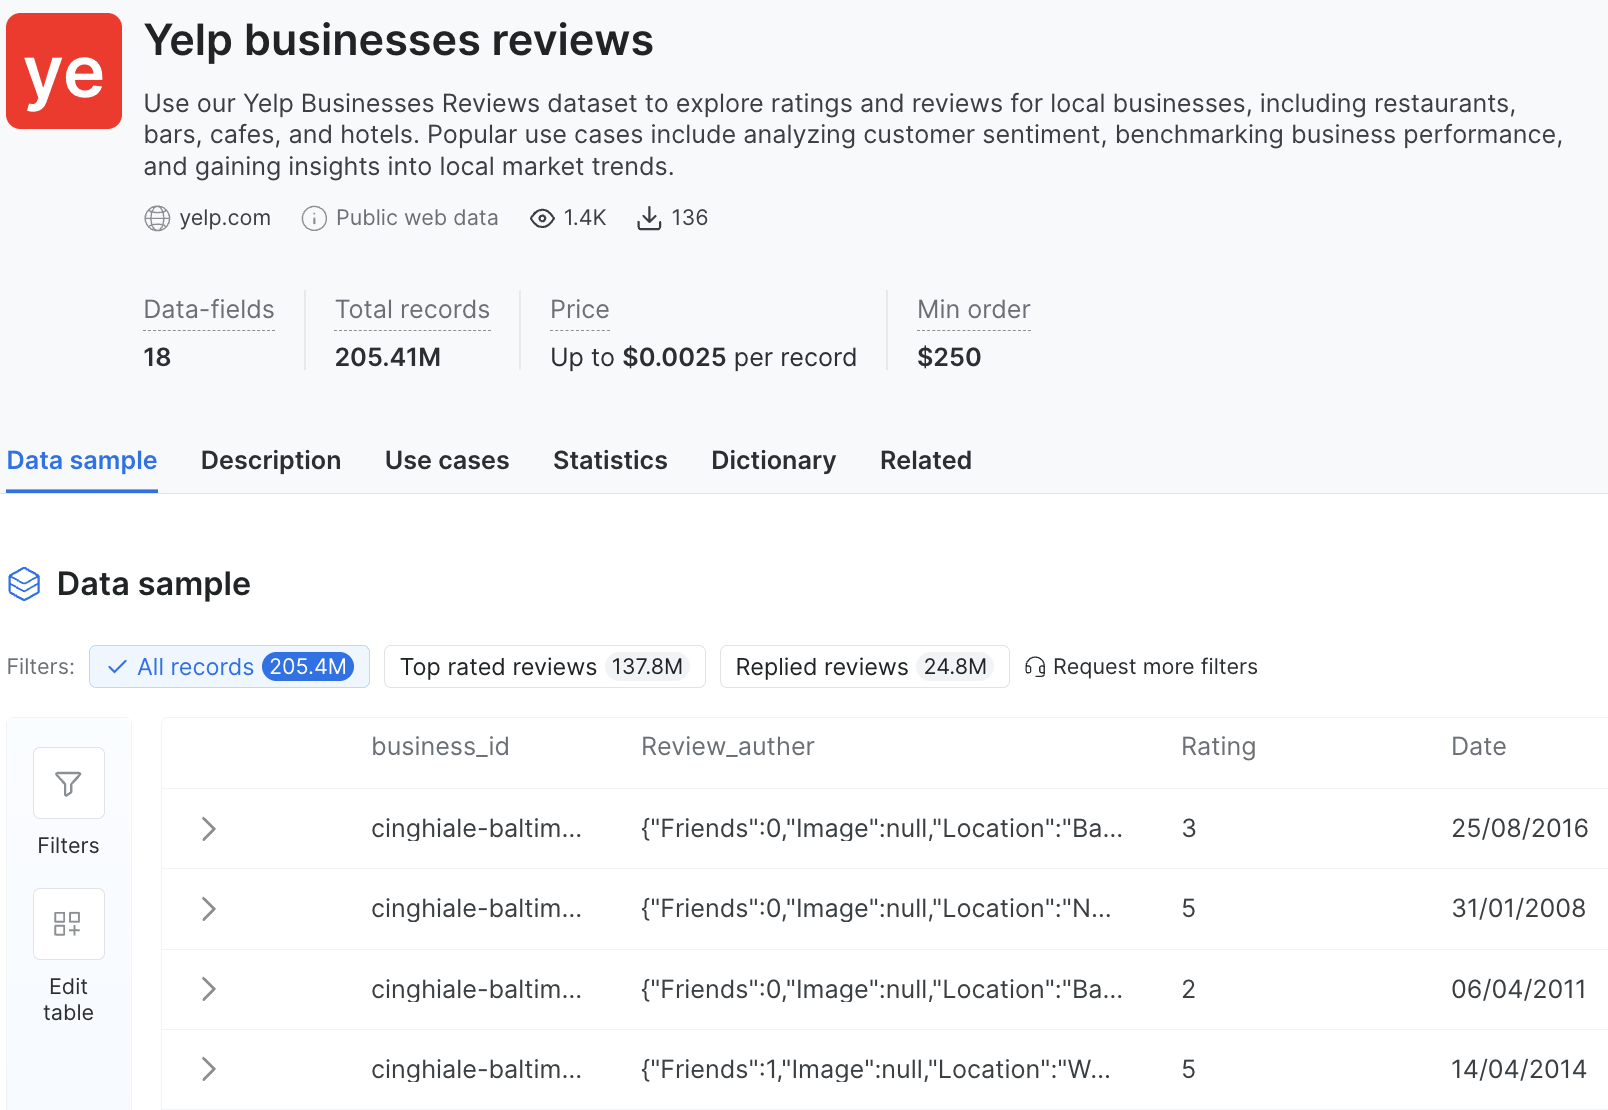
The Yelp businesses reviews dataset. At up to $0.0025 per record, the $250 minimum order buys at least 100K reviews.
Final thoughts
Scraping Yelp in Python worked in our tests once every request used Web Unlocker and reviews came from the GraphQL API, not the HTML. The persisted query ID can change when Yelp deploys, so if review calls start failing, run refresh_doc_id.py first. Bright Data’s Yelp Scraper API handles parser maintenance and adds not-recommended reviews, at a higher per-review price. Bright Data’s Yelp datasets provide historical data for backfills. Start on Bright Data’s free tier with a business you know, and compare yelp_scraper.py‘s row count with totalCount before you run it on more businesses.
FAQ
How do you scrape Yelp reviews?
Request them from Yelp’s GraphQL endpoint, /gql/batch, with the GetBusinessReviewFeed persisted query ID, because business-page HTML had no full review text in our tests. Each call returned up to 49 reviews. Route the calls through Bright Data’s Web Unlocker API, because DataDome, Yelp’s bot protection, blocked the Python HTTP clients we tested.
Does the Yelp API give all reviews?
No, not when we checked. Yelp’s docs listed 3 Places API review excerpts on Enhanced and up to 7 on Premium, each about 160 characters. Full text was available from Yelp’s Insights API Premium plan or from the GraphQL API that yelp.com uses, which returned recommended reviews. Bright Data’s Yelp Scraper API also returns full text, including not-recommended reviews.
Can I use the Yelp API for free?
Only for evaluation. Yelp’s docs listed 5K free Places API calls during a 30-day trial, and trial calls weren’t for commercial use. Paid plans started at $229 per month for the Base plan, which included no review excerpts or photos.
How much does the Yelp Fusion API cost?
Yelp’s pricing page listed the Places API (also called Fusion) at $229 per month for Base, $299 for Enhanced, and $643 for Premium. Each plan included 30K calls a month by default, and extra calls cost $5.91 to $14.13 per 1K, depending on the plan.
Is there a free Yelp scraper?
Yes, open-source Yelp scrapers are free, but in our tests, DataDome, Yelp’s bot protection, blocked Python HTTP clients. Bright Data’s free tier includes 5K credits a month, enough for 5K Yelp Scraper API records. Web Unlocker requests to Yelp need an account with full access.
Can websites detect scraping?
Yes. Bot-protection services can check TLS fingerprints, IPs, and JavaScript execution, and Yelp used DataDome in our tests. Python HTTP clients got 403 challenge pages on every test request, even with browser TLS fingerprints and US residential IPs. All 30 test business pages loaded through Bright Data’s Web Unlocker API.


Technical Writer
 5 years experience
Satyam Tripathi helps SaaS and data startups turn complex tech into actionable content, boosting developer adoption and user understanding.