


LinkedIn Crawler
Crawl LinkedIn at scale across profiles, posts, companies, and jobs. Collect public data such as ID, name, city, position, about, posts, current company, experience, company size, industry, employee profiles, corporate activities, and much more.

- Free tier - 5K records a month for free
- Scrape on demand via API or no-code scraper
- Pay only for successfully delivered results
- Bulk request handling, up to 5K URLs
Trusted by 50,000+ customers worldwide


Available LinkedIn crawlers
 131.9K+
 15.3K+
Just want LinkedIn data? Skip scraping.
Purchase a LinkedIn dataset
LinkedIn Crawler Pricing
Only pay for what’s successfully delivered. No hidden fees, no charges for failed deliveries.

- Pay only for success, no hidden fees
- Start free with 5,000 monthly credits
- No upfront commitment, cancel anytime
- 24/7 expert support and enterprise features

CODE EXAMPLES
Easily crawl LinkedIn data without worrying about being blocked.
curl -H "Authorization: Bearer API_TOKEN" -H "Content-Type: application/json" -d '[{"url":"https://www.linkedin.com/in/elad-moshe-05a90413/"},{"url":"https://www.linkedin.com/in/jonathan-myrvik-3baa01109"},{"url":"https://www.linkedin.com/in/aviv-tal-75b81/"},{"url":"https://www.linkedin.com/in/bulentakar/"},{"url":"https://www.linkedin.com/in/nnikolaev/"}]' "https://api.brightdata.com/datasets/v3/trigger?dataset_id=gd_l1viktl72bvl7bjuj0&format=json&uncompressed_webhook=true"[
{
"timestamp": "2026-10-22",
"id": "mar***la-***p-2*********",
"name": "Marcella R**p",
"city": "Coal, Pennsylvania, United States",
"country_code": "US",
"position": null,
"about": null,
"posts": null
},
{
"timestamp": "2026-10-22",
"id": "gar***ure***b11******",
"name": "Gary T***k",
"city": "Rock Hill, South Carolina, United States",
"country_code": "US",
"position": null,
"about": null,
"posts": null
},
{
"timestamp": "2026-10-22",
"id": "pau***erg***n-b*********",
"name": "Paul B******n",
"city": "Harrellsville, North Carolina, United States",
"country_code": "US",
"position": null,
"about": null,
"posts": null
},
{
"timestamp": "2026-10-22",
"id": "tod***ppe***8b1******",
"name": "Todd A***l",
"city": "Glenwood, Minnesota, United States",
"country_code": "US",
"position": null,
"about": null,
"posts": null
},
{
"timestamp": "2026-10-22",
"id": "jam***sco***615*********",
"name": "Jamie S***t",
"city": "United States",
"country_code": "US",
"position": null,
"about": "Jam***Sco*** BS*********N *********",
"posts": null
}
]curl -H "Authorization: Bearer API_TOKEN" -H "Content-Type: application/json" -d '[{"url":"https://www.linkedin.com/pulse/ab-test-optimisation-earlier-decisions-new-readout-de-b%C3%A9naz%C3%A9?trk=public_profile_article_view"},{"url":"https://www.linkedin.com/posts/orlenchner_scrapecon-activity-7180537307521769472-oSYN?trk=public_profile"},{"url":"https://www.linkedin.com/posts/karin-dodis_web-data-collection-for-businesses-bright-activity-7176601589682434049-Aakz?trk=public_profile"},{"url":"https://www.linkedin.com/pulse/getting-value-out-sunburst-guillaume-de-b%C3%A9naz%C3%A9?trk=public_profile_article_view"}]' "https://api.brightdata.com/datasets/v3/trigger?dataset_id=gd_lyy3tktm25m4avu764&format=json&uncompressed_webhook=true"[
{
"timestamp": "2026-09-29",
"url": "https:\/\/fr.linkedin.com\/posts\/tred-union-transport-international_laureatslabeltransportetlogistiqueresponsables-activity...",
"id": "7510636583109357569",
"user_id": "tre***nio***ran*********ern*********",
"use_url": "https:\/\/fr.linkedin.com\/company\/tred-union-transport-international?trk=public_post_feed-actor-image",
"title": "Lau***ts_***el_*********_et*********************les***************************************************",
"headline": "➡️ ***pal***ès *********abe*********************que*********************************************************************...",
"post_text": "➡️ Le palmarès 2026 du Label Transport \u0026 Logistique Responsables vient d’être dévoilé🎖️ Cette année, 68 entreprises du ..."
},
{
"timestamp": "2026-09-29",
"url": "https:\/\/www.linkedin.com\/posts\/santexgroup_wearesantex-santexculture-teamsantex-activity-7510438846224838657-QiYi",
"id": "7510438846224838657",
"user_id": "san***gro***",
"use_url": "https:\/\/www.linkedin.com\/company\/santexgroup?trk=public_post_feed-actor-image",
"title": "#we***san*** #s*********ure********************* | *********",
"headline": "Not***ery***am *********d b*********************",
"post_text": "Not every team is defined by a shared project. Sometimes, it’s defined by choosing to share the space💚\n\n👉 Our Santex t..."
},
{
"timestamp": "2026-09-29",
"url": "https:\/\/www.linkedin.com\/posts\/doctors-memorial-hospital-fl_doctors-memorial-hospital-is-pleased-to-activity-75081544545...",
"id": "7508154454555422720",
"user_id": "doc***s-m***ria*********l-f***",
"use_url": "https:\/\/www.linkedin.com\/company\/doctors-memorial-hospital-fl?trk=public_post_feed-actor-image",
"title": "Doc***s’ ***ori*********al ********************* Th*********************************************************************...",
"headline": "Doc***s’ ***ori*********al ********************* Th*********",
"post_text": "Doctors’ Memorial Hospital is pleased to welcome Thomas R. Eckler II, MD, FACEP, to our Emergency Medicine team.\n\nDr. Ec..."
},
{
"timestamp": "2026-09-29",
"url": "https:\/\/www.linkedin.com\/posts\/kaela-crampton_today-is-one-of-the-proudest-of-my-career-activity-7508191313939542016-_NS...",
"id": "7508191313939542016",
"user_id": "kae***cra***on",
"use_url": "https:\/\/www.linkedin.com\/in\/kaela-crampton",
"title": "Tod***is *** of*********des*********************rta*********************************************************************...",
"headline": "Tod***is *** of*********des*********************rta*********************************",
"post_text": "Today is one of the proudest of my career and certainly of my time at Swiftly, Inc. Today, Swiftly formally introduces t..."
},
{
"timestamp": "2026-09-29",
"url": "https:\/\/www.linkedin.com\/posts\/daniel-prevost28_took-the-week-off-last-week-to-hike-in-the-activity-7510313784536776704-...",
"id": "7510313784536776704",
"user_id": "dan***-pr***st2***",
"use_url": "https:\/\/es.linkedin.com\/in\/daniel-prevost28?trk=public_post_feed-actor-image",
"title": "Too***he ***k o*********eek*********************s d*********************************************************************...",
"headline": "Too***he ***k o*********eek*********************s d************",
"post_text": "Took the week off last week to hike in the \u0022Picos de Europa.\u0022\n\nCouldn´t believe how fortunate I was to run into Lionel M..."
}
]curl -H "Authorization: Bearer API_TOKEN" -H "Content-Type: application/json" -d '[{"url":"https://il.linkedin.com/company/ibm"},{"url":"https://www.linkedin.com/company/figueroa-real-estate/"},{"url":"https://www.linkedin.com/organization-guest/company/the-kraft-heinz-company"},{"url":"https://il.linkedin.com/company/bright-data"}]' "https://api.brightdata.com/datasets/v3/trigger?dataset_id=gd_l1vikfnt1wgvvqz95w&format=json&uncompressed_webhook=true"[
{
"timestamp": "2026-10-22",
"id": "searchnurture",
"name": "Search Nurture",
"country_code": "US",
"locations": [
"Oakland, CA 94609, US"
],
"followers": 1816,
"employees_in_linkedin": 3,
"about": "🧐Ever felt like eCommerce ads are a puzzling maze where achieving growth feels elusive? If this resonates with you, you..."
},
{
"timestamp": "2026-10-22",
"id": "mtservices",
"name": "MT SERVICES",
"country_code": "FR",
"locations": [
"130, Avenue Joseph Kessel Voisins-le-Bretonneux, Île-de-France 78960, FR"
],
"followers": 19,
"employees_in_linkedin": 36,
"about": "MT SERVICES intervient 24 h\/24 et 7J\/7 sous 4 heures dans toute l’Île-de-France et réalise, grâce à ses équipes de techn..."
},
{
"timestamp": "2026-10-22",
"id": "networkconseil",
"name": "Network Conseil",
"country_code": "FR",
"locations": [
"5 bis allée des Fontêtes Vertaizon , Auvergne Rhône-Alpes 63910, FR"
],
"followers": 342,
"employees_in_linkedin": 1,
"about": "Comment marketer quand l’environnement du cabinet comptable se digitalise ? « On compte en France près de 52 millions d’..."
},
{
"timestamp": "2026-10-22",
"id": "monumenta-real-estate",
"name": "Monumenta Real Estate",
"country_code": "FR",
"locations": [
"20, rue Cambron Paris, 75001, FR"
],
"followers": 19,
"employees_in_linkedin": 2,
"about": "MONUMENTA REAL ESTATE, une offre unique sur le marché : Le conseil via M2i, Monumenta Ingénierie Immobilière La commerci..."
},
{
"timestamp": "2026-10-22",
"id": "msehla-recrutement",
"name": "M\u0027SEHLA Solutions RH \u0026 Recrutement",
"country_code": "FR",
"locations": [
"Toulouse Métropole, FR"
],
"followers": 812,
"employees_in_linkedin": 1,
"about": "À Propos de Nous M’SEHLA – Recrutement ciblé sur les métiers en tension Nous accompagnons les entreprises françaises du ..."
}
]curl -H "Authorization: Bearer API_TOKEN" -H "Content-Type: application/json" -d '[{"url":"https://www.linkedin.com/jobs/view/software-engineer-at-epic-3986111804?_l=en"},{"url":"https://www.linkedin.com/jobs/view/software-engineer-at-pave-4310512612/"}]' "https://api.brightdata.com/datasets/v3/trigger?dataset_id=gd_lpfll7v5hcqtkxl6l&format=json&uncompressed_webhook=true"[
{
"timestamp": "2026-10-22",
"url": "https:\/\/www.linkedin.com\/jobs\/view\/sp%C3%A9cialiste-web-e-commerce-et-performance-num%C3%A9rique-at-luminaire-authentik-...",
"job_posting_id": "4480267421",
"job_title": "Spécialiste Web (e-commerce et performance numérique)",
"company_name": "Luminaire Authentik",
"company_id": "25075472",
"job_location": "Cowansville, Quebec, Canada",
"job_summary": "À propos de Luminaire Authentik Luminaire Authentik conçoit et fabrique, au Québec, des luminaires haut de gamme destiné..."
},
{
"timestamp": "2026-10-22",
"url": "https:\/\/www.linkedin.com\/jobs\/view\/shopify-practice-director-at-valtech-4440801850?_l=en",
"job_posting_id": "4440801850",
"job_title": "Shopify Practice Director",
"company_name": "Valtech",
"company_id": "5175",
"job_location": "Toronto, Ontario, Canada",
"job_summary": "Why Valtech? We’re the experience innovation company - a trusted partner to the world’s most recognized brands. To our p..."
},
{
"timestamp": "2026-10-22",
"url": "https:\/\/www.linkedin.com\/jobs\/view\/senior-system-analyst-at-ocs-ontario-cannabis-store-4479887515?_l=en",
"job_posting_id": "4479887515",
"job_title": "Senior System Analyst",
"company_name": "OCS Ontario Cannabis Store",
"company_id": "11686253",
"job_location": "Toronto, Ontario, Canada",
"job_summary": "About Us The Ontario Cannabis Store provides safe, responsible access to recreational cannabis for adults 19 and older. ..."
},
{
"timestamp": "2026-10-22",
"url": "https:\/\/www.linkedin.com\/jobs\/view\/software-development-manager-offers-platform-catalog-systems-ascs-at-amazon-448128787...",
"job_posting_id": "4481287871",
"job_title": "Software Development Manager, Offers Platform, Catalog Systems, ASCS",
"company_name": "Amazon",
"company_id": "1586",
"job_location": "Vancouver, British Columbia, Canada",
"job_summary": "Description Amazon Selection and Catalog Systems (ASCS) builds and operates the systems that host the world\u0027s largest e-..."
},
{
"timestamp": "2026-10-22",
"url": "https:\/\/www.linkedin.com\/jobs\/view\/manager-software-engineering-adobe-commerce-at-arc-teryx-equipment-4471661744?_l=en",
"job_posting_id": "4471661744",
"job_title": "Manager, Software Engineering (Adobe Commerce)",
"company_name": "Arc\u0027teryx Equipment",
"company_id": "137624",
"job_location": "North Vancouver, British Columbia, Canada",
"job_summary": "Your Opportunity at ARC’TERYX: As a Manager, Software Engineering, you’ll lead and manage a team of software developers ..."
}
]API for Seamless LinkedIn Data Access
Comprehensive, Scalable, and Compliant Web Data Extraction
API for Seamless LinkedIn Data Access
Tailored to your workflow
Get structured data in JSON, NDJSON, or CSV files through Webhook or API delivery.
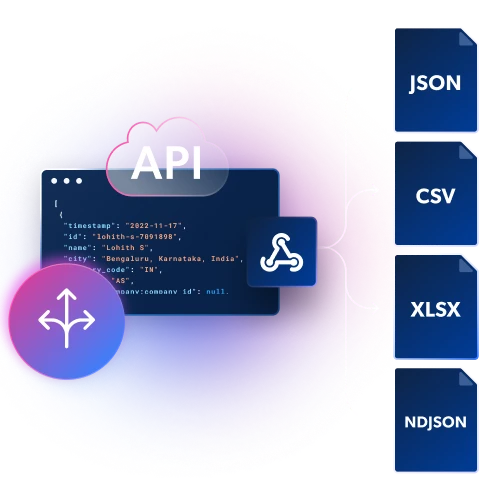
Built-in infrastructure and unblocking
Get maximum control and flexibility without maintaining proxy and unblocking infrastructure. Easily scrape data from any geo-location while avoiding CAPTCHAs and blocks.
Battle-proven infrastructure
Bright Data’s platform powers 50,000+ companies worldwide, offering peace of mind with 99.99% uptime, access to 400M+ real user IPs covering 195 countries.
Industry leading compliance
Our privacy practices comply with data protection laws, including the EU data protection regulatory framework, GDPR, and CCPA.
Simplified LinkedIn crawling


LinkedIn crawling use cases
Effective competitive analysis
Market trends & growth
B2B company data
Leading the way in ethical web data collection
We have set the gold standard for ethical and compliant web data practices. Our peer network is built on trust, with every member personally opting in and the guarantee of zero personal data collection. We champion the collection of only publicly available data, backed by an industry-leading Know Your Customer process and a transparent Acceptable Use Policy. Our global, multilingual Compliance & Ethics team, the first of its kind, ensures we stay ahead of regulatory changes and best practices.
Why 50,000+ Customers Choose Bright Data

100% Compliant

24/7 Global Support

Complete Data Coverage

Unmatched Data Quality

Powerful Infrastructure

Custom Solutions


LinkedIn Crawler FAQs
What is the LinkedIn crawler?
The LinkedIn crawler is an automated tool that discovers and collects public data from LinkedIn at scale. You don't need a full list of URLs. You can start from a keyword, a category, a search URL or a specific page. The crawler finds the matching records and sends the data back in a structured format.
What is the difference between crawling and scraping LinkedIn?
Crawling is about discovery: finding the pages. Scraping is about extraction: pulling specific fields from a page you already know about. A scraper needs you to tell it which URL to visit. A crawler finds the records for you and then extracts the data. Use the crawler when you don't have the full list of URLs, or when the list keeps changing, such as every item in a category or every result for a keyword. If you already have the exact URLs, collecting by URL is the more direct option.
How is the LinkedIn crawler different from a LinkedIn dataset?
A dataset is data that has already been collected, and you buy it as a ready-made file. The crawler collects fresh data when you run it, based on your own inputs. Pick a dataset if you want broad coverage right away with no setup. Pick the crawler if you need a specific scope, the latest data or collection on a schedule you control.
How is the LinkedIn crawler different from using proxies?
Proxies are infrastructure. They send your requests through different IP addresses, but you still have to build and maintain the crawler, the parser and the unblocking. The LinkedIn crawler includes all of it: proxy management, full browser rendering, CAPTCHA solving, data parsing and delivery. Choose proxies if you want to write and own the code. Choose the crawler if you just want the data.
Is the LinkedIn crawler the same as Bright Data's Crawl API?
No. The Crawl API works on any public website. You give it a root URL, and it returns the site's content as Markdown, Text, HTML or JSON. The LinkedIn crawler is built only for LinkedIn. It returns ready-to-use fields specific to LinkedIn, so you don't have to write your own parsing logic.
What inputs can I use to start a crawl?
It depends on the crawler you choose. Common starting points are a direct URL, a keyword, a category URL, a search URL, or a profile, seller or shop URL. You can send up to 5,000 URLs in a single bulk request.
Can I schedule recurring crawls of LinkedIn?
Yes. The crawler supports batch and scheduled collection, so you can rerun the same crawl at regular intervals. This is useful for tracking changes over time, such as prices, availability, rankings or engagement numbers, without starting each run by hand.
Do I need to deal with blocks, CAPTCHAs or JavaScript rendering?
No. Proxy management, CAPTCHA solving and full browser rendering are all built in. The crawler runs on Bright Data's network of over 400 million real user IPs in 195 countries, so you can crawl LinkedIn from any location without maintaining your own unblocking setup.
How is the LinkedIn crawler priced?
You pay only for records that are successfully delivered. Failed deliveries are never charged. You can start on the free tier with 5,000 records a month and no credit card, then move to pay as you go or a monthly plan as you scale. Plan details are in the pricing section above.
Is it legal to crawl LinkedIn?
The crawler only collects publicly available data. Bright Data's privacy practices follow data protection laws, including GDPR and CCPA. It also has a Know Your Customer process and a public Acceptable Use Policy. You are still responsible for making sure your own use of the data complies with the laws that apply to you.