


 854+
 38+
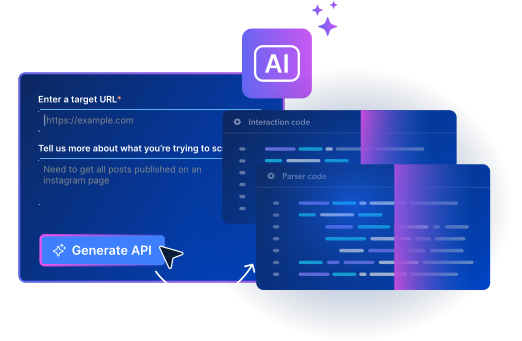


- Build requests in any language
- Automate with schedulers and webhooks
- JSON, NDJSON, or CSV delivery


Creative Commons Scraper API
Scrape Creative Commons images and 3D models. Collect Creative Commons data such as title, description, license type, creator details, image URLs, keywords, media type, and more.
5K free records/month · Credit card not required
Trusted by 50,000+ customers worldwide


Available Creative Commons scrapers
Pick a Creative Commons scraper and call it. Every Creative Commons scraper lists its output fields, delivery volume, and live success rate.
Explore thousands of production-ready scrapers
Pay only for successful results, no surprises – Proxies, unlocking, browsers and retries are built in.
Pricing
Web Scraper API Pricing
Only pay for what’s successfully delivered. No hidden fees, no charges for failed deliveries.
Records per month: 5K
$/mo
$
per 1,000 records
Your whole bill. Proxies, unblocking, parsing included.
Get started
- Pay only for success, no hidden fees
- Start free with 5,000 monthly credits
- No upfront commitment, cancel anytime
- 24/7 expert support and enterprise features
We accept these payment methods:

Just want data? Skip scraping.
Purchase a Creative Commons dataset
How it works
From zero to Creative Commons data in 3 steps
No proxies to configure, no infrastructure to manage. Pick, call, and receive.
-
Pick a scraper
Choose from the [current_scraper_name} scrapers above or create your own with AI in minutes.
-
Call the API
One API call with up to 5,000 target URLs. Python and Node.js SDKs, CLI, MCP server, or any HTTP client.
-
Get structured data
Receive clean, parsed [current_scrper_name] data in JSON, NDJSON, or CSV. Delivered via API, webhook, or cloud storage.
Scraper API Call
curl -H "Authorization: Bearer API_TOKEN" -H "Content-Type: application/json" -d '[{"url":"https://openverse.org/image/70ee48a3-6c6d-464c-9db7-75a507555979?q=beach","keyword":""},{"url":"https://openverse.org/image/62319cc3-12e4-43d4-b218-bee28f524e59?q=beach","keyword":""},{"url":"https://openverse.org/image/e7ae9471-7196-4767-bdf1-8a080d3a7134?q=beach","keyword":""},{"url":"https://openverse.org/image/ed2c0630-2837-400e-bfa1-c9333dd58331?q=beach","keyword":""}]' "https://api.brightdata.com/datasets/v3/trigger?dataset_id=gd_m23cxdw82ct6k022y3&format=json&uncompressed_webhook=true"
Response payload
[
  {
    "timestamp": "2026-06-15",
    "url": "https:\/\/www.google.com\/imgres?q=mural+art\u0026imgurl=https%3A%2F%2Fupload.wikimedia.org%2Fwikipedia%2Fcommons%2F5%2F5e%2FWal...",
    "title": "File:Wall painting - female painter - Pompeii (VI 1 10) - Napoli ...",
    "description": null,
    "image_url": "https:\/\/upload.wikimedia.org\/wikipedia\/commons\/5\/5e\/Wall_painting_-_female_painter_-_Pompeii_%28VI_1_10%29_-_Napoli_MAN_...",
    "creators": null,
    "license": null,
    "keyword": null
  },
  {
    "timestamp": "2026-06-15",
    "url": "https:\/\/www.google.com\/imgres?q=gymnastics\u0026imgurl=https%3A%2F%2Fupload.wikimedia.org%2Fwikipedia%2Fcommons%2F3%2F30%2F20...",
    "title": "File:2022-06-26 Budapest Cup Age-group III apparatus finals Vault ...",
    "description": null,
    "image_url": "https:\/\/upload.wikimedia.org\/wikipedia\/commons\/3\/30\/2022-06-26_Budapest_Cup_Age-group_III_apparatus_finals_Vault_%28Mart...",
    "creators": null,
    "license": null,
    "keyword": null
  },
  {
    "timestamp": "2026-06-16",
    "url": "https:\/\/www.google.com\/imgres?q=Aztec+pyramids\u0026imgurl=https%3A%2F%2Fupload.wikimedia.org%2Fwikipedia%2Fcommons%2Fc%2Fc8%...",
    "title": "File:Teotihuacan, Pyramid of the Moon, Cerro Gordo, and the Avenue ...",
    "description": null,
    "image_url": "https:\/\/live.staticflickr.com\/5758\/20660408766_5b6202a239_o.jpg",
    "creators": null,
    "license": null,
    "keyword": null
  },
  {
    "timestamp": "2026-06-16",
    "url": "https:\/\/www.google.com\/searchviewer\/7?hl=en\u0026svid=EpMBMg5oXy02WEltaDVRWlFCTToOZG5rWVZJUkRIaWYxU01KcWh0dHBzOi8vaW1hZ2VzLnB...",
    "title": "Close-up of a Carved Wall in an Ancient Temple · Free Stock Photo",
    "description": null,
    "image_url": "https:\/\/images.pexels.com\/photos\/15929091\/pexels-photo-15929091.jpeg?cs=srgb\u0026dl=pexels-sergk1-15929091.jpg\u0026fm=jpg",
    "creators": null,
    "license": null,
    "keyword": null
  },
  {
    "timestamp": "2026-06-16",
    "url": "https:\/\/www.google.com\/imgres?q=Buenos+Aires\u0026imgurl=https%3A%2F%2Fupload.wikimedia.org%2Fwikipedia%2Fcommons%2F8%2F8f%2F...",
    "title": "File:Palacio del Congreso in Buenos Aires (6370115601).jpg ...",
    "description": null,
    "image_url": "https:\/\/live.staticflickr.com\/6042\/6370115601_0c5ec4f945_o.jpg",
    "creators": null,
    "license": null,
    "keyword": null
  }
]
Scraper API Call
curl -H "Authorization: Bearer API_TOKEN" -H "Content-Type: application/json" -d '[{"url":"https://www.thingiverse.com/thing:6863579"},{"url":"https://www.thingiverse.com/thing:6854751"},{"url":"https://www.thingiverse.com/thing:6856939"},{"url":"https://www.thingiverse.com/thing:6855436"}]' "https://api.brightdata.com/datasets/v3/trigger?dataset_id=gd_m4jr2hyr2kfhtvba6e&format=json&uncompressed_webhook=true"
Response payload
[
  {
    "timestamp": "2024-12-19",
    "url": "https:\/\/www.thingiverse.com\/thing:6719448",
    "id": "6719448",
    "domain": "https:\/\/www.thingiverse.com\/",
    "title": "cap container box (fallout)",
    "description": "This object was made in Tinkercad. for the cap container lid",
    "license": "Creative Commons - Attribution - Share Alike",
    "images": [
      "https:\/\/cdn.thingiverse.com\/assets\/1b\/ff\/9d\/38\/82\/0ace2eef-aa0f-409e-88af-591c5df4c49c.png",
      "https:\/\/cdn.thingiverse.com\/assets\/1d\/d2\/02\/d6\/e9\/257948e0-f6c3-462c-83a9-97e0c1fc0f11.png",
      "https:\/\/cdn.thingiverse.com\/assets\/a2\/61\/22\/d7\/93\/ef59239a-ef44-4ac1-9af2-32bf50bc87bb.png",
      "https:\/\/cdn.thingiverse.com\/assets\/2d\/46\/20\/42\/27\/0ca0e1b0-0e44-4eb6-824d-08e3484ef248.png",
      "https:\/\/cdn.thingiverse.com\/assets\/fc\/f9\/c7\/c5\/ce\/f1bd7ab9-9384-4a08-b8eb-6b5010c70e15.png",
      "https:\/\/cdn.thingiverse.com\/assets\/50\/4b\/1e\/9e\/7c\/cb4fcb1e-375c-492b-a698-634753e1fc6e.png"
    ]
  },
  {
    "timestamp": "2024-12-19",
    "url": "https:\/\/www.thingiverse.com\/thing:6190826",
    "id": "6190826",
    "domain": "https:\/\/www.thingiverse.com\/",
    "title": "Oddish Planter",
    "description": "Oddish Planter\r\n\r\n4\u0022 high\r\n8.5\u0022 base\r\n5.5\u0022 top opening\r\n\r\nPrinted with PLA\r\n\r\nhttps:\/\/youtu.be\/qK1jMLIY4T0",
    "license": "Creative Commons - Attribution",
    "images": [
      "https:\/\/cdn.thingiverse.com\/assets\/8d\/0e\/75\/f9\/d8\/1e9aae24-1845-4dd5-b7b2-18d314cfd937.JPG",
      "https:\/\/cdn.thingiverse.com\/assets\/c4\/a4\/9b\/79\/1c\/7426c817-10b2-45f7-b1c5-b9c662a1bda2.png",
      "https:\/\/cdn.thingiverse.com\/assets\/3b\/6c\/f5\/1b\/6e\/f127f3f4-ac03-4860-a909-9e200224a9ca.png"
    ]
  },
  {
    "timestamp": "2024-12-19",
    "url": "https:\/\/www.thingiverse.com\/thing:6006827",
    "id": "6006827",
    "domain": "https:\/\/www.thingiverse.com\/",
    "title": "Berg Buddy Pushbar",
    "description": "This thing let you use Bergtoys Buzzy pushbar on your Berg Buddy. ",
    "license": "Creative Commons - Attribution",
    "images": [
      "https:\/\/cdn.thingiverse.com\/assets\/41\/1c\/0b\/2f\/32\/22f074e9-a77f-496b-a9cc-cf8278665535.png",
      "https:\/\/cdn.thingiverse.com\/assets\/6b\/13\/fc\/bd\/85\/7fb0aa80-4f1f-4b99-9255-4cbcd66485b6.jpeg"
    ]
  },
  {
    "timestamp": "2024-12-19",
    "url": "https:\/\/www.thingiverse.com\/thing:4908700",
    "id": "4908700",
    "domain": "https:\/\/www.thingiverse.com\/",
    "title": "Lanzador MM40",
    "description": null,
    "license": "Creative Commons - Public Domain Dedication",
    "images": [
      "https:\/\/cdn.thingiverse.com\/assets\/2b\/9f\/94\/d1\/f7\/contenedor.png",
      "https:\/\/cdn.thingiverse.com\/assets\/41\/d4\/2f\/5a\/88\/cajon.png"
    ]
  },
  {
    "timestamp": "2024-12-19",
    "url": "https:\/\/www.thingiverse.com\/thing:6782075",
    "id": "6782075",
    "domain": "https:\/\/www.thingiverse.com\/",
    "title": "Holder for IDEAL 45-163 Abmantelwerkzeug 3.2mm - 5.5mm",
    "description": "IDEAL 45-163 Abmantelwerkzeug 3.2mm - 5.5mm",
    "license": "Creative Commons - Attribution - Share Alike",
    "images": [
      "https:\/\/cdn.thingiverse.com\/assets\/e4\/74\/68\/ed\/bc\/Klamme_Halter.png",
      "https:\/\/cdn.thingiverse.com\/assets\/a3\/e7\/04\/1f\/c5\/gggg.jpg",
      "https:\/\/cdn.thingiverse.com\/assets\/be\/93\/cc\/03\/8a\/Klamme_Halter.png"
    ]
  }
]
TERMINAL
Tell your agent:
Read https://brightdata.com/SKILL.md and get structured JSON for this Creative Commons product via the Web Scraper API (gd_m23cxdw82ct6k022y3): https://openverse.org/image/70ee48a3-6c6d-464c-9db7-75a507555979?q=beachOr run it yourself:
curl -H "Authorization: Bearer YOUR_API_KEY" -H "Content-Type: application/json" -d '[{"url":"https://openverse.org/image/70ee48a3-6c6d-464c-9db7-75a507555979?q=beach"}]' "https://api.brightdata.com/datasets/v3/trigger?dataset_id=gd_m23cxdw82ct6k022y3&format=json"Or connect over MCP:
https://mcp.brightdata.com/mcp?token=YOUR_API_KEY
For coding Agents
Plug Creative Commons scrapers into your agent
Your agent picks from Creative Commons scrapers we already maintain. Let it run whenever you need, and every run delivers real-time web data straight to your storage. Works in Claude Code, Codex, Cursor and any other coding agent.
- Runs with npx, nothing to install
- bdata login opens browser auth, no key to paste
- Name a scraper, get JSON back
- Delivers to AWS · GCP · Azure · Snowflake · Webhook
World's #1 scraping platform
Everything you need, built in
You pay for results. Proxies, rendering, concurrency, and delivery are always included, on every plan.

Go straight to the source
Every request runs on Bright Data infrastructure. 400M+ IPs, unlocking and browsers are built in.

Scale to millions of pages instantly
Send unlimited concurrent requests - no infrastructure to manage, no configs to change.

Scrapers auto-fix when sites change
AI-powered self-healing detects site changes and repairs scrapers. Your pipelines keep running.

Thousands of verified scrapers
Every scraper is built, tested, and maintained by Bright Data. No community guesswork.

Pay per result, nothing extra
One price per record . Proxies, retries, rendering, unblocking - all included, no surprises.

Compliant and fully supported
GDPR & CCPA compliant. 24/7 human support on every plan, including free.
Choose your path
Start collecting Creative Commons data in minutes
Call the API from code, click through the control panel, or hand it to your AI agent.


Creative Commons data scraping use cases
Real-time Creative Commons intelligence for your business.
Licence-aware AI training data
Licences
Media
Attribution
Media asset discovery
Media
Formats
Categories
Creator and attribution tracking
Creators
Attribution
Licences
Collection composition analysis
Collections
Licences
Formats
Compare Bright Data to others
Web Scraper API vs other providers
Capability
Bright Data
Other scraping providers
Auto-scaling infrastructure
Unlimited
Partial
Anti-bot & CAPTCHA bypass
Built-in
Partial
Residential proxy network
400M+ IPs
Limited pool
Pre-built scrapers
1,400+
50–200
Auto-maintenance (site changes)
24/7
Depends on who built it
Pricing model
One all-in price per record
Compute, proxy, and storage metered separately
Failed requests
Free, pay only for success
Often billed
Custom sites (no pre-built scraper)
AI builds it in minutes, self-healing included
Community-built scrapers, no SLA
Compliance (GDPR, CCPA, SOC 2)
Full
Partial
Structured output (JSON/CSV)
Automatic
Support
24/7 experts, even on the free tier
Community forum
Free tier
5K records/mo
Varies
compliance
Leading the way in ethical web data collection
Only publicly available data. ISO 27001 certified, SOC 2 controls, GDPR & CCPA compliant. Every use case is reviewed by a dedicated Compliance & Ethics team, backed by a documented Know Your Customer process and Acceptable Use Policy.

Bright Data is used by world's top brands


Creative Commons Scraper API FAQs
What is the Creative Commons Scraper API?
The Creative Commons Scraper API is a powerful tool designed to automate data extraction from the Creative Commons website, allowing users to efficiently gather and process large volumes of data for various use cases.
How does the Creative Commons Scraper API work?
The Creative Commons Scraper API works by sending automated requests to targeted website, extracting the necessary data points, and delivering them in a structured format. This process ensures accurate and quick data collection.
Is the Creative Commons Scraper API compliant with data protection regulations?
Yes, the Creative Commons Scraper API is designed to comply with data protection regulations, including GDPR and CCPA. It ensures that all data collection activities are performed ethically and legally.
Can I use the Creative Commons Scraper API for competitive analysis?
Absolutely! The Creative Commons Scraper API is ideal for competitive analysis, allowing you to gather insights into your competitors' activities, trends, and strategies.
How can I integrate the Creative Commons Scraper API with my existing systems?
The Creative Commons Scraper API offers flawless integration with various platforms and tools. You can use it with your existing data pipelines, CRM systems, or analytics tools to improve your data processing capabilities.
Is there a free tier available for the Creative Commons Scraper API?
Yes! Every new Bright Data account automatically includes 5,000 free credits per month (approximately $7.50 in value) — no credit card required, no promo code, no commitment. These credits apply to Scrapers (including the Creative Commons Scraper API), as well as the Unlocker API and SERP API. Credits renew on the 1st of each month, and you can start making API calls immediately after signing up.
What happens when my free credits run out while using the Creative Commons Scraper API?
When your 5,000 free monthly credits are exhausted, behavior depends on your account balance. If you have pre-deposited funds, usage continues seamlessly at standard PAYG rates with no interruption. If you have no deposited funds, requests will return an error until you add funds or until your credits renew on the 1st of the following month. Note that unused free credits do not roll over.
To avoid interruptions, you can enable auto-recharge in your billing settings at brightdata.com/cp/billing/settings.
What are the usage limits for the Creative Commons Scraper API?
There are no specific usage limits for the Creative Commons Scraper API, offering you the flexibility to scale as needed.
Do you provide support for the Creative Commons Scraper API?
Yes, we offer dedicated support for the Creative Commons Scraper API. Our support team is available 24/7 to assist you with any questions or issues you may encounter while using the API.
What delivery methods are available?
Amazon S3, Google Cloud Storage, Google PubSub, Microsoft Azure Storage, Snowflake, and SFTP.
What file formats are available?
JSON, NDJSON, JSON lines, CSV, and .gz files (compressed).
Can AI agents use the Creative Commons Scraper API?
Yes. Connect any agent through the hosted MCP server, point a coding agent at brightdata.com/SKILL.md to set itself up, or use the CLI. Agents authenticate once with browser OAuth and can run any of the Creative Commons scrapers.