


- Approve the schema before the first run
- Refine with a follow-up prompt
- Add fields later without touching code


Medium Scraper API
Build a Medium scraper with AI and collect data such as: article title, author, publication, publish date, reading time, claps, responses, tags, subtitle, article text, and more.
5K page loads/month for free · Credit card not required
Trusted by 50,000+ customers worldwide


Build your Medium scraper in just a few clicks
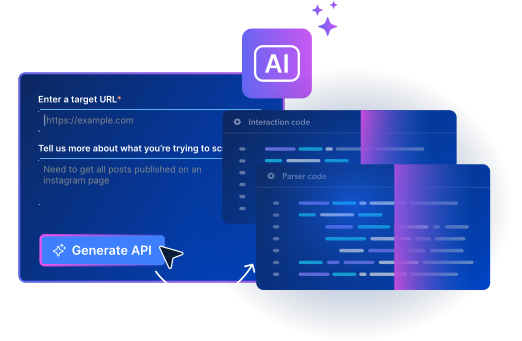
Choose the domain, outline your data requirements, and let our AI scraper builder automatically create the API.
- Describe data needs in plain English
- AI instantly generates the scraper API
- Run API requests for immediate results
- Edit the code in the built-in IDE, if needed
- Schedule runs daily, weekly, or at custom intervals
When Medium site changes, your scraper fixes itself
Self-Healing watches every run. When the success rate drops, it repairs the code. Healing jobs cost no credits.

Repairs itself before you notice
Success rate falls below your threshold, a repair job starts. No ticket, no hunting for the selector that broke.

You approve the fix, or let it ship
Review the code change before it goes live, or turn on auto save. Roll back to any earlier version, any time.

Repairs are free
You pay per delivered page. A scraper that stops working never burns your credits while it is being fixed.
Prompt it, code it, or hand it to your coding agent
Three ways for the same Medium scraper. Start in one, switch to another whenever you want.


Medium Scraper API Pricing
Only pay for what’s successfully delivered. No hidden fees, no charges for failed deliveries.

We accept these payment methods:

Looking for ready to use social media scrapers?
Pick a scraper and call it. Every scraper lists its output fields, delivery volume, and live success rate.
 25.1K+
 10K+
Explore thousands of production-ready scrapers
Pay only for successful results, no surprises – Proxies, unlocking, browsers and retries are built in.
Everything you need, built in
You pay for results. Proxies, rendering, concurrency, and delivery are always included, on every plan.

Go straight to the source
Every request runs on Bright Data infrastructure. 400M+ IPs, unlocking and browsers are built in.

Scale to millions of pages instantly
Send unlimited concurrent requests - no infrastructure to manage, no configs to change.

Scrapers auto-fix when sites change
AI-powered self-healing detects site changes and repairs scrapers. Your pipelines keep running.

Thousands of verified scrapers
Every scraper is built, tested, and maintained by Bright Data. No community guesswork.

Pay per result, nothing extra
One price per record . Proxies, retries, rendering, unblocking - all included, no surprises.

Compliant and fully supported
GDPR & CCPA compliant. 24/7 human support on every plan, including free.
Just want data? Skip scraping. Purchase a Medium dataset
Use cases
Medium data scraping use cases
Real-time Medium intelligence for your business.
Content and topic research
Articles
Tags
Topics
Author and publication analysis
Authors
Publications
Output
Engagement benchmarking
Claps
Responses
Reading time
Brand and trend monitoring
Mentions
Trends
Dates
Leading the way in ethical web data collection
Only publicly available data. ISO 27001 certified, SOC 2 controls, GDPR & CCPA compliant. Every use case is reviewed by a dedicated Compliance & Ethics team, backed by a documented Know Your Customer process and Acceptable Use Policy.

Bright Data is used by world's top brands


The easiest way to scrape Medium data at scale
Medium Scraper FAQs
What is the custom Medium Scraper?
The Medium scraper is a powerful tool designed to automate data extraction from Medium, enabling users to efficiently gather and process large volumes of prediction market data for various use cases.
Is there a free tier available for building and running a Medium scraper?
Yes! Every new Bright Data account automatically includes 5,000 free credits per month (approximately $7.50 in value) — no credit card required, no promo code, no commitment. These credits apply to scrapers built and run via the AI Scraper Studio, so you can generate, test, and run your Medium scraper right away. Credits renew on the 1st of each month.
What happens when my free credits run out while running my Medium scraper?
When your 5,000 free monthly credits are exhausted, what happens next depends on your account balance. If you have pre-deposited funds, your scraper jobs continue without interruption at standard PAYG rates. If you have no deposited funds, scraper jobs will return an error until you add funds or your credits renew on the 1st of the following month. Unused free credits do not roll over.
To ensure uninterrupted scraping, you can enable auto-recharge in your billing settings at brightdata.com/cp/billing/settings.
How do I create a Medium using an AI prompt?
Choose your website, describe the data in plain English, and the AI instantly generates a ready-to-run scraper; the finished scraper appears in your IDE workspace for testing, running, and edits as needed.
How does the Medium Scraper work?
The Medium Scraper works by sending automated requests to Medium, extracting the necessary data points, and delivering them in a structured format. This process ensures accurate and quick data collection.
Do I need my own servers or proxies to run the Medium scraper?
No. When you launch a job from the IDE, the scraper executes on Bright Data’s infrastructure - complete with built-in proxy rotation, geo-targeting, CAPTCHA/unblocking logic, and auto-scaling. You don’t maintain any servers or proxy pools; just run the scraper and the platform handles everything end-to-end.
Is the Medium Scraper compliant with data protection regulations?
Yes, the Medium Scraper is designed to comply with data protection regulations, including GDPR and CCPA. It ensures that all data collection activities are performed ethically and legally.
Is any coding required?
Coding is not required to generate the Medium scraper - the AI scraper Studio builds it from your prompt. You will still need a working knowledge of web-scraping concepts to configure and use the scraper, and you can optionally refine the auto-generated code in the built-in IDE.
Do you provide support for the Medium Scraper?
Yes, we offer dedicated support for the Medium Scraper. Our support team is available 24/7 to assist you with any questions or issues you may encounter while using the API.
What delivery methods are available?
JSON by default, with options for CSV, Parquet, or direct loads to S3, GCS, Azure Blob, BigQuery, and Snowflake.
What file formats are available?
JSON, NDJSON, JSON lines, CSV, and .gz files (compressed).